Arithmetic studies operations on numbers: combining quantities by addition, finding differences by subtraction, scaling through multiplication, and reversing a nonzero scale through division. Its usefulness goes beyond producing an answer. A calculation can express how resources are shared, how a measurement changes with scale, or why two different descriptions of a quantity agree.
The allowed numbers matter. Start with the natural numbers . Counting collections gives , but removing three from two calls for the integer . Sharing three units equally between two recipients gives the rational number . These operations motivate larger number systems: integers supply additive inverses, and rational numbers supply division by nonzero integers. A real number can also express lengths such as a diagonal of Euclidean norm , which is not a rational number.
The beauty is that bookkeeping, geometry, and algebra can check one another. The same product counts three groups of six, measures the area of a rectangle, and splits as by distributivity. A number line makes negative integers visible as positions; a fraction records an exact share even when its decimal representation does not terminate. An arithmetic rule becomes easier to remember when these interpretations fit together.
Linear arithmetic is the fragment of arithmetic built from equalities and inequalities between linear expressions , combined by logical operations and, in some versions, quantifiers. Coefficients are fixed numbers; multiplying two unknowns, as in , leaves this fragment. One must specify whether the unknowns range over the integers, rational numbers or real numbers.[ref]
For example, and are linear constraints. Substitution gives , hence . But has a real number solution and no integer solution, so a procedure for one number system cannot simply be reused for the other. This distinction makes linear arithmetic useful in automated reasoning about counts, schedules and bounds.
A numeral is a written expression representing a number. The number five can be written as the decimal numeral , the binary numeral , or the Roman numeral V. The expressions differ while the represented integer is the same.
This distinction matters when an algorithm examines numerical digits. A palindromic number, for example, is defined through its representation in a specified radix, rather than through the appearance of an abstract number. The integer five is a palindrome as the one-digit decimal numeral and as the binary numeral , whereas ten is written in decimal and in binary, neither of which is a palindrome.
A mathematical mean assigns a representative value to several quantities. A real mean of normally lies between their minimum and maximum and returns when every input equals . Different means preserve different operations: the arithmetic mean averages sums, while the geometric mean averages positive multiplicative factors.
For and , the arithmetic mean is and the geometric mean is . If equal distances are traveled at speeds and , the average speed is instead their harmonic mean, . The useful choice depends on which quantity is being added: distances, times, or logarithms of growth factors.
For distinct positive real numbers , their logarithmic mean isusing the natural logarithm. Set by continuity: the difference quotient of the natural logarithm tends to its derivative , so the reciprocal tends to . For example, .
An integral representation explains its name and its relation to multiplicative interpolation:For , integrate directly; for , the integrand is constant. Every interpolated value lies between and , so the logarithmic mean does too. It is symmetric in and homogeneous: for .
Numbers are mathematical objects used to express quantities and carry out operations. Familiar families include the natural numbers, integers, rational numbers, real numbers, and complex numbers; specifying the family determines which operations and solutions are available.
The surreal numbers form an ordered field built recursively from cuts , where every already constructed left option is smaller than every right option. The earliest examples are , , and . A cut names the simplest number between its options; different cuts can name the same number.
Allowing construction through arbitrary ordinals introduces both infinite numbers, such as , and positive infinitesimals, such as . All real numbers embed in the resulting ordered field, but its entire collection is a proper class. Unlike ordinal arithmetic, surreal multiplication and addition obey the usual commutative field laws.
For real numbers and , division asks for the unique number satisfying . Equivalently, uses the multiplicative inverse of . This description separates the role of the denominator from the result: the quotient undoes a specified multiplication.
For example, is the number whose double is three, so it is exactly . A second interpretation asks how many portions of size fit into an amount ; the answer is one and a half portions. Equal sharing and measuring with a specified portion size lead to the same quotient, although the units assigned to the result can differ.
In the natural numbers, exact division need not be possible. Euclidean division instead keeps a remainder: , with . Thus seventeen objects form three complete groups of five with two left over. As a rational number, the same quotient is . The remainder and the fractional part describe the same unfinished group in different ways.
Division by zero cannot retain the unique-solution rule. For , the equation has no solution; for , every real number solves , so there is no unique quotient. This explains both failures through multiplication, rather than assigning a value that would contradict ordinary arithmetic. [ref]
https://openstax.org/books/prealgebra-2e/pages/3-4-multiply-and-divide-integers. OpenStax, Prealgebra 2e, multiplication and division conventions
Division of integers that returns an integer quotient rather than an exact fraction. A rounding convention is required for negative operands. For and , the quotient is and the remainder is with .
For an -bit unsigned dividend and positive divisor , read the dividend bits from most to least significant. If the processed prefix is , maintain with . Appending bit gives trial remainder ; append quotient bit and replace the remainder by . This preserves the quotient–remainder identity.
The old dividend and new quotient can share one -bit processor register: after iterations its value is , where . The shifted dividend occupies the upper positions and the accumulated quotient occupies the lower positions, so no information is overwritten. The high processor register holds . For an -bit dividend the next trial remainder is no larger than the next prefix, hence fits in bits through the final iteration. This last bound is specific to the dividend width; it must not be assumed for unrestricted multiword dividends.
For signed two's complement integers, a conditional positive bias converts the rounding behaviour of an arithmetic right shift into C integer division. It can be formed without a conditional branch by turning the sign bit into either zero or a low--bit bit mask.
Proof. Nonnegative needs no adjustment. If , write , . Then , whose quotient rounded down is , exactly the quotient truncated towards zero. The bias fits safely for in an -bit signed word: it is added only to negative inputs, and the largest possible adjusted input is . The corresponding remainder is , where .
For representable integer quotients with nonzero divisor, C integer division discards the fractional part towards zero and defines the remainder by . Thus a nonzero remainder has the dividend's sign. For example, , so division by five returns quotient and remainder . This convention differs from division rounded down, which would return quotient and nonnegative remainder . Division by zero and an unrepresentable quotient are excluded.[ref]
The quotient of by a nonzero in a field is , the unique solution of . Thus is the rational quotient of by .
In Euclidean division of integers, the word instead denotes the integer in with a specified remainder range; for , . Here has quotient and remainder . Stating the ambient arithmetic prevents confusion between exact division and division with remainder.
A ratio compares two quantities , written and corresponding to division when . Equal ratios of corresponding lengths characterize the scaling of similar triangles.
For example, and specify the same ratio because . Multiplying both entries by the same nonzero scale preserves the quotient: . This is useful when comparing mixtures or scaling a recipe; doubling both ingredient amounts preserves their ratio, while adding the same amount to both generally does not. For quantities with the same physical units, their ratio is dimensionless, connecting this elementary calculation with dimensional analysis.
A percentage expresses a ratio in hundredths: as a fraction is . For example, . Comparing two percentages requires specifying whether the change is an absolute difference in percentage points or a relative change divided by the initial value.
A percentage point is one hundredth on a probability or proportion scale. A change from to is percentage points, while the relative increase is . These answer different questions and have different denominators.
An inequality compares mathematical quantities using an ordering, such as or for real numbers. A strict inequality excludes equality; a non-strict inequality allows it. For example, is strict, while is true because equality is allowed. Adding the same real number preserves either comparison; multiplying by a negative real number reverses its direction.
An ordered comparison such as , excluding equality. In a sorted search, strict comparisons distinguish regions that can be discarded from boundary positions that may contain an equal target.
A linear inequality compares a linear functional of a vector of unknowns with a constant, for example or over the real numbers. For , its solution set is a closed or open half-space, respectively. The inequality allows all points on one side of the line , including the line. Multiplication by a negative real number reverses the inequality, so is equivalently .
A system of linear inequalities requires several linear inequalities to hold simultaneously. The notation compares coordinates componentwise, giving one inequality per row of the matrix . Its solution set is the intersection of the corresponding half-spaces. For non-strict inequalities it is a linear polyhedron, which may be empty. For example, , , are inconsistent: adding their equivalent forms , , gives . A Farkas certificate for linear inequalities generalizes this cancellation.
A sum of squares adds the squares of numbers for specified real numbers . It is nonnegative and vanishes exactly when every term is zero. For the coordinates of a vector, it is the squared Euclidean norm; for regression residuals, it gives the residual sum of squares minimized by ordinary least squares.
A figurate number is an integer illustrated by a regular geometric arrangement of points. Triangular numbers and square numbers are basic examples: growing a prescribed shape turns a counting problem into a sequence of integers.
The th square pyramidal number counts a square-based stack with layers containing objects:For example, . To prove the formula, let . Direct algebra gives and , so mathematical induction identifies with the sum of squares.
Differences give sums over consecutive square numbers. The leading term shows cubic growth of the total, even though the largest layer has only objects.
For integers and , the th -gonal number isThese figurate numbers begin at one, and their successive increments form an arithmetic progression:Summing these increments proves the formula. For , it gives triangular numbers, square numbers, pentagonal numbers and hexagonal numbers. For example, the first three pentagonal numbers are , whose successive increments are four and seven. Increasing the number of polygon sides changes the step between increments while keeping this common quadratic structure.
The th hexagonal number is for a positive integer . Since , every hexagonal number is also a triangular number.
The th pentagonal number is for a positive integer , giving . A positive integer is pentagonal exactly when is a perfect square and is an integer, by the defining quadratic equation.
A value with any integer, including negative values and zero. For , positive values occur as pairs and . These are the indices in the Euler pentagonal identity.
A triangular number counts rows of objects, with a nonnegative integer:The first values are . The empty arrangement contributes zero, by the empty sum convention. Adding one more row gives the triangular number recurrence for . The row lengths form an arithmetic progression, while their running totals are triangular numbers.
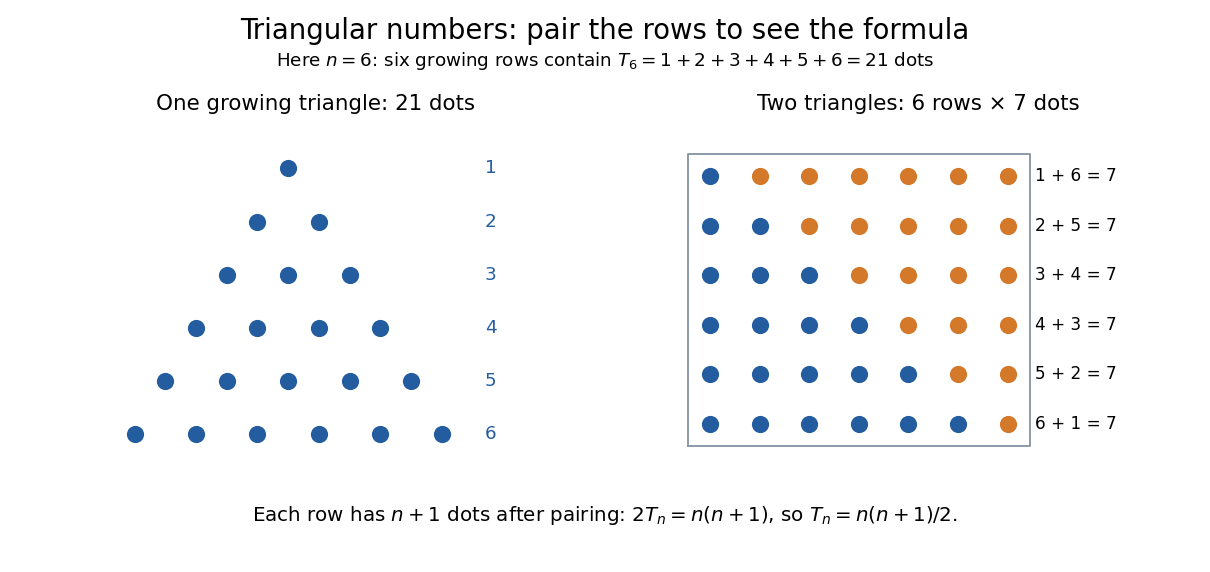
Pair the rows with a reversed copy: . There are such pairs, so two copies contain dots. Dividing by two proves the formula. This rectangle picture explains the factor one-half without requiring a formula for a long summation. For example, one hundred rows contain dots.
The same count appears whenever every pair of different objects must be considered once. Five participants make ten possible handshakes; five sensors have ten different pairwise comparisons; a complete graph on five vertices has ten edges. These are the triangular number pair-counting identity, with one fewer row than objects. The distinction prevents a common error: counts all pairs from six objects, whereas five objects give .
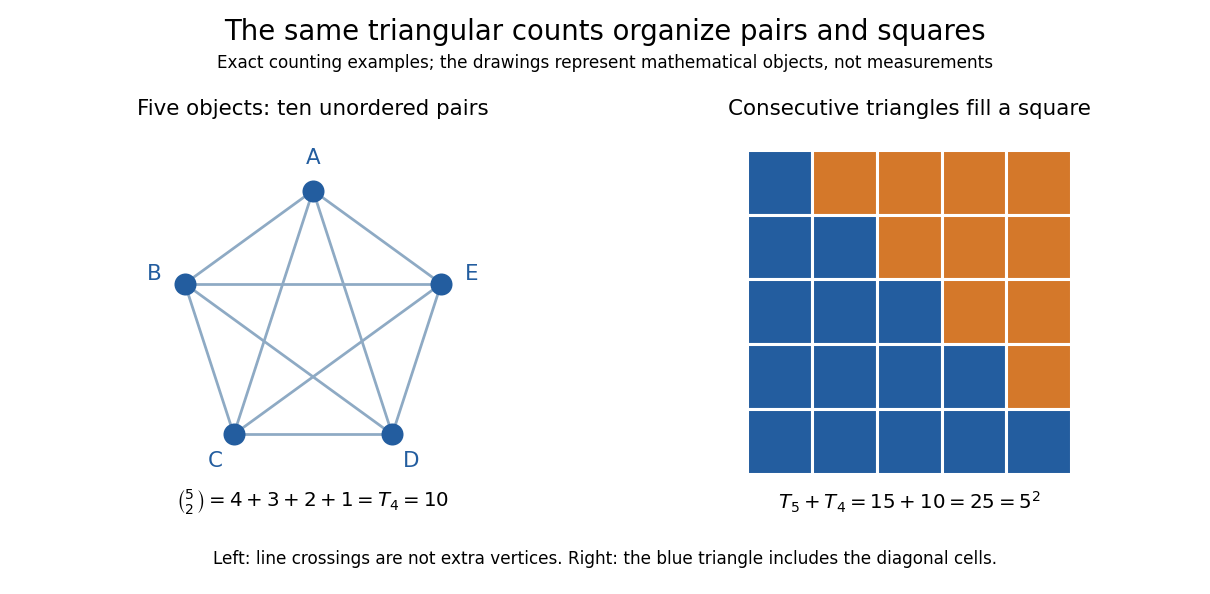
The triangular number square-complement identity says that two neighboring triangular numbers fill a square. Combining that identity with the one-row difference makes the difference of squares equal to . It leads to Nicomachus's theorem: the sum of the first cubes of numbers is the square of a number . A change in the way one groups objects exposes a relation between summation, multiplication and geometry.
This geometric view is already visible in Nicomachus's Introduction to Arithmetic by Nicomachus (Hahn teacher edition): Book II, Chapter 8 describes growing triangular rows, Chapter 12 combines successive triangular counts into squares, and Chapter 20 groups successive odd integers into cubes of numbers.[ref]
Introduction to Arithmetic by Nicomachus (Hahn teacher edition). Book II, Chapters 8, 12 and 20, printed pp. 63–64, 70 and 75
The linked edition uses Martin Luther D'Ooge's translation, revised with modern teaching material by Nathanael Hahn. Our empty-row index is a modern convention; the historical passage starts from unity and calls three the first actual triangle.For a positive integer , adding the row of length to the previous arrangement gives . Thus the first differences of the triangular numbers are . The triangular number recurrence provides incremental computation: after , adding seven gives .
For distinct objects, the number of unordered pairs of different objects isOrdering the objects gives pairs with the first object, new pairs with the second, and so on down to one. Alternatively, ordered pairs count every unordered pair twice. The binomial coefficient therefore counts the edges of a complete graph on vertices. This is also consistent with the handshaking lemma: each vertex has degree of a vertex , and the degree sum counts every edge twice.
For ,An -by- array of cells has cells. One side of the diagonal, including the diagonal itself, contains cells; the other contains . For , the two counts are fifteen and ten, giving twenty-five. The identity is stated in Introduction to Arithmetic by Nicomachus (Hahn teacher edition) (Book II, Chapter 12, §§1–2, printed p. 70).
A nonnegative integer is a triangular number exactly when is a perfect square. Its square root is then an odd integer, and the row index isCompleting the square in proves necessity; reversing the calculation proves sufficiency. For example, , giving . In contrast, lies strictly between and , so twenty is not a triangular number. The criterion turns an apparently open-ended search through a sequence into one exact perfect square check.
A squared triangular number is the square of a number , where is a triangular number. Beginning at , the values are . Nicomachus's theorem gives them a second description as cumulative sums of cubes of numbers.
For every nonnegative integer ,For example, . A short proof uses the triangular number recurrence and the triangular number square-complement identity:Summing this difference of squares identity gives a telescoping sum; all intermediate squared triangular numbers cancel. Nicomachus describes a related grouping of the odd integers: take one, then the next two, then the next three, producing , which are . This historical grouping is recorded in Introduction to Arithmetic by Nicomachus (Hahn teacher edition) (Book II, Chapter 20, §5, printed p. 75).
A square triangular number is simultaneously a triangular number and a perfect square. For example, . This differs from a squared triangular number: is not itself triangular, by the recognition criterion for triangular numbers. Writing gives , a Pell equation that explains why this intersection of two counting patterns has additional arithmetic structure.
The geometric mean replaces a list of nonnegative real numbers by one repeated value that preserves their product of numbers. For inputs,For two positive inputs, is their positive square root. The geometric mean of and is three: replacing by retains the same product. In contrast, their arithmetic mean five retains the sum . The geometric mean is zero if any input is zero; the logarithm formula below requires every input to be positive. [ref]
https://dlmf.nist.gov/1.2.iv. NIST Digital Library of Mathematical Functions, §1.2(iv), equation 1.2.18: geometric mean
.Its usefulness becomes immediate for successive growth factors. Suppose a hypothetical positive quantity starts at , is multiplied by , then by . It goes , so the geometric mean factor is : a constant factor of one for both steps gives the same endpoint. The arithmetic mean factor is ; repeating it would give , a different endpoint. A mean of factors summarizes multiplicative change; subtracting one afterwards gives the equivalent change per step. Equal-duration steps are necessary to interpret this as change per common time interval.
For positive inputs, logarithms turn multiplication into addition, soThus the geometric mean is an arithmetic mean in logarithmic coordinates, followed by the exponential function. For positive measurements with a common unit, one can use dimensionless ratios to a fixed reference : . Changing the common unit rescales by the same factor as the inputs. As a check, doubling one input and halving another retains while usually changing the arithmetic mean.
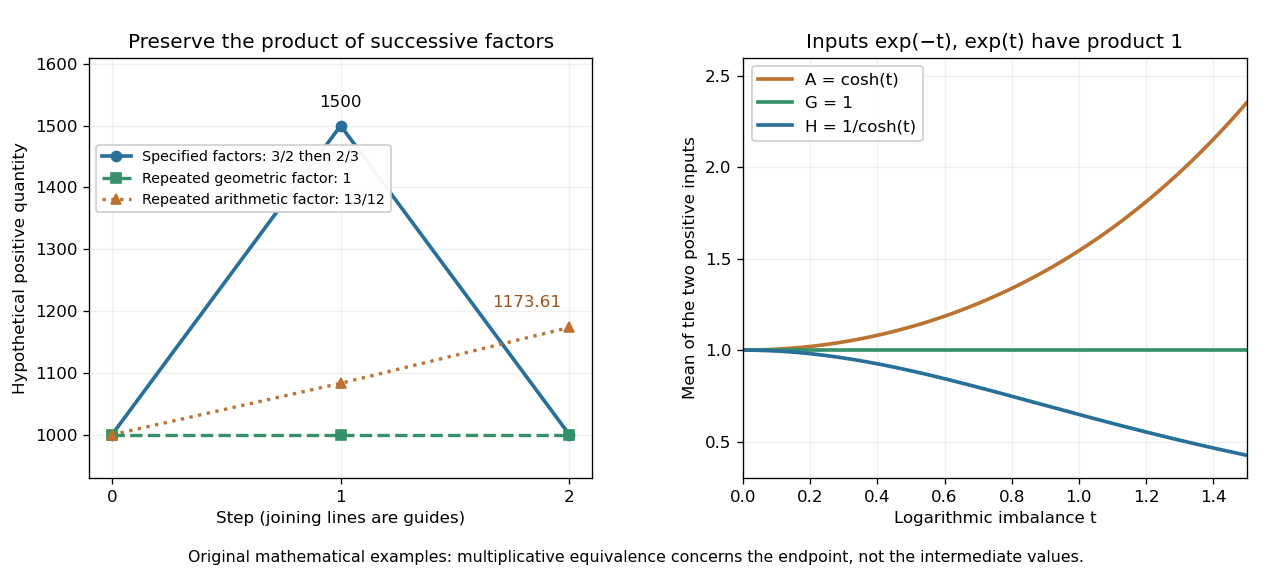
The geometric mean preserves multiplicative endpoints and sits between the harmonic mean and arithmetic mean
. Left: the original toy factors and return a quantity to its starting value; repeating their arithmetic mean would produce a larger endpoint. Right: the dimensionless inputs and keep product one while , , and separate as the inputs become less equal. Lines joining time steps are guides, not a continuous growth model. Details.The arithmetic-geometric mean inequality gives . Apply that same inequality to the multiplicative inverses to obtain , where is the harmonic mean. Consequentlyfor positive inputs, with equality throughout exactly when all inputs agree. For and , the three values are , , and . They preserve, respectively, the sum of inverses, the product, and the sum. No one of these summaries preserves all three for unequal inputs.
For positive quantities measured at successive steps, the growth factor is a dimensionless ratio. It can be below one when the quantity shrinks. Repeated multiplication givesso the common factor reproducing the endpoint after identical steps is their geometric mean. A factor corresponds to a relative change ; factors must be averaged before subtracting one when summarizing compounded change.
For example, increasing by ten percent gives , then decreasing the result by ten percent gives . The factors are and , whose product is . Their geometric mean is , whereas their arithmetic mean is one. Thus equal positive and negative percentage changes need not cancel when applied successively to different bases.
For positive real numbers and nonnegative weights with , the weighted geometric mean isIt takes a weighted mean of logarithms. A zero weight excludes that input; equal weights give the ordinary geometric mean. If occurs times in a list of total length , its correct weight is . For the list ,and replacing all four entries by preserves the product .
There is also an optimization interpretation. A logarithmic transformation turns multiplicative discrepancies into additive ones. For a positive representative , the weighted mean minimizes squared deviations identity givesThus uniquely minimizes weighted quadratic loss in logarithmic coordinates. The weighted arithmetic mean minimizes squared discrepancies in the original coordinates. These two objectives explain why different choices of what constitutes an error select different summaries.
The strictly concave function and the reversed Jensen's inequality give , where is the weighted arithmetic mean. Apply the same reasoning to the multiplicative inverses to get for the weighted harmonic mean. Thus ; equality holds exactly when all positive-weight inputs agree. For this list, , , and . The weights specify which inputs are represented and must stay the same across the comparison.
Starting from , replace the lower endpoint by the geometric mean and the upper endpoint by the arithmetic mean. The arithmetic-geometric mean inequality gives . The bounded monotone sequence theorem gives limits, and the arithmetic recurrence forces them to coincide. The limiting value is the arithmetic-geometric mean of the initial pair.
The natural numbers are the nonnegative integersThey count the elements of finite sets: the empty set has cardinality zero, and a two-element set has cardinality two. Addition and multiplication preserve natural numbers, while subtraction need not: is an integer outside .
The convention here includes zero. The positive integers instead begin at one. The well-ordering principle for the natural numbers ensures every nonempty subset has a least element, supporting mathematical induction and proof by minimal counterexample.
The minimum excludant of a finite set of nonnegative integers is the smallest nonnegative integer absent from :For example, , while and . It always exists and is at most : the candidates cannot all belong to a set of cardinality .
In Sprague-Grundy theory, the Grundy number of a position in a finite acyclic impartial game is the mex of the values of its legal successor positions. The minimum excludant therefore converts the available moves into a reusable numerical description of a game position.
For a finite set of positive integers, its minimum excluded positive integer isFor example, gives three, while gives one. The answer lies between one and , since those candidates cannot all lie in .
The ordinary minimum excludant permits zero and would be zero for either example, because contains only positive integers. Choosing the positive or nonnegative convention is therefore part of the definition of the desired result.
Every nonempty subset of the natural numbers has a least element in their usual order. Applying this principle to positive integer linear combinations proves Bézout's identity. This principle for the usual natural-number order is distinct from the general well-ordering theorem asserting that every set can be equipped with some well-order.
Assume that a proposed statement fails for some natural number, and choose the least failing index using the well-ordering principle. Prove the necessary base cases and reduce the least failure to a smaller index that must satisfy the statement. If that smaller case implies the alleged failure also satisfies it, there is a contradiction. Reductions by a step larger than one require enough consecutive base cases to cover every possible residue class.
A real number is an element of the complete ordered field . This includes integers, rational numbers such as , and irrational numbers such as . The number line represents each real number by a point, and the total order distinguishes which of two different points is larger.
The field operations permit addition, subtraction, multiplication and division by nonzero real numbers. Completeness adds the least-upper-bound property: every nonempty set of real numbers that is bounded above has a supremum in . For example, the positive real numbers whose squares are less than two have supremum . That supremum is not a rational number, illustrating why the rational numbers alone leave a gap.
The density of the rational numbers means every real number can be approximated arbitrarily closely by rational numbers. Constructions through Cauchy sequences or Dedekind cuts make those approximations into a precise description of .
A negative real number is a real number , lying to the left of zero on the number line. Equivalently, for a positive real number . Examples include , and ; zero is excluded.
The sum of two negative real numbers is negative, while their product is positive. Multiplication by a negative real number reverses an inequality: if and , then . These are consequences of compatibility between the total order and the arithmetic of an ordered field, rather than independent rules about written minus signs.
A nonnegative real number is a real number . The set of all such numbers is , which includes zero as well as the positive real numbers. The word nonnegative is therefore weaker than strictly positive.
This set is closed under addition and multiplication, but negating a nonzero member leaves it. Every real square and every absolute value is nonnegative. A variance can equal zero, as it does for a constant random variable; calling every variance positive would incorrectly exclude that legitimate case. Nonnegative constraints similarly allow zero as a feasible boundary value in mathematical optimization.
The condition that a real number is at least zero. A nonnegative flow in a directed flow network follows the specified orientation or has zero value; a negative algebraic solution would describe the opposite orientation instead.
A positive real number is a real number with . Zero is excluded; allowing zero gives a nonnegative real number. Both and are positive.
The sum, product, and reciprocal of positive real numbers are positive. Consequently the positive real numbers form a group under multiplication, and the natural logarithm converts that multiplication into addition: . Positivity is also the domain restriction that makes the real logarithm well-defined.
For coprime integers , a Stoneham number isFor example, . The rapidly growing exponents separate long blocks in its base- expansion.
These constants are useful as explicit constructions in the theory of normal numbers: the Stoneham number is normal in base under the stated coprimality hypothesis. Normality means every finite block of base- digits has the expected limiting frequency; it is much stronger than merely being irrational.
For a real number , its cube root is the unique real number satisfying . The function is strictly increasing, so negative inputs also have a unique real cube root.
The integer cube root of a nonnegative integer is , the unique integer satisfying . It can be computed by binary search using integer cube comparisons.
A number line represents real numbers as points on a line, with zero as origin and a chosen positive direction and unit scale. Addition becomes a shift and multiplication becomes a rescaling about zero.
A linear scale places a value at a position , where and are constants. Equal differences in occupy equal distances because . This contrasts with a logarithmic scale, which assigns equal distances to equal ratios.
The Archimedean property says that the natural numbers are unbounded in the real numbers. In particular, for every positive real number there is a positive integer with . Otherwise a purported upper bound for all natural numbers contradicts the least-upper-bound property by translating that bound by one.
A binary representation writes a number in positional notation with radix two and binary digits zero and one. To the left of the binary point the place values are ; to its right they are . For example,Binary notation changes the numeral, not the underlying number. The same value is in decimal. A finite binary fraction represents a dyadic rational, while an infinite binary expansion can represent any real number in the unit interval. Storing a finite binary string additionally requires an interpretation such as unsigned interpretation or two's complement.
After adding least-significant binary digits, the numerical sum of the two processed input suffixes equals the written result digits plus , with . Initially both suffixes are empty. For the next column, write and pass to the next column. Multiplying these column quantities by preserves the equation. After all columns, the remaining carry supplies the extra leading digit, proving correctness without converting either full input to a machine integer.
For an -bit binary string , the unsigned interpretation assigns positive positional weights to its bits. Its values range from zero to . The same stored bits have two's complement value , so interpreting a machine word is a separate choice from storing its bits.
For a positive integer , its bit length is the number of binary digits in its usual representation:Equivalently, is the unique positive integer satisfying . For example, has bit length four, and has bit length four too. The inequalities provide an exact characterization without a floating-point logarithm.
Many integer programming interfaces define the bit length of zero as zero. That convention counts no significant one-bit; it differs from the written binary numeral , which has one character. A fixed-width machine word can also contain leading zero bits that do not contribute to the value's bit length.
Every real number has a binary expansionFor , construct it by repeated doubling. Set , then and , using the floor function. Each remainder stays in , and induction givesThe remaining error is less than , so the finite partial sums converge to . For , choose every binary digit equal to one and use the geometric series.
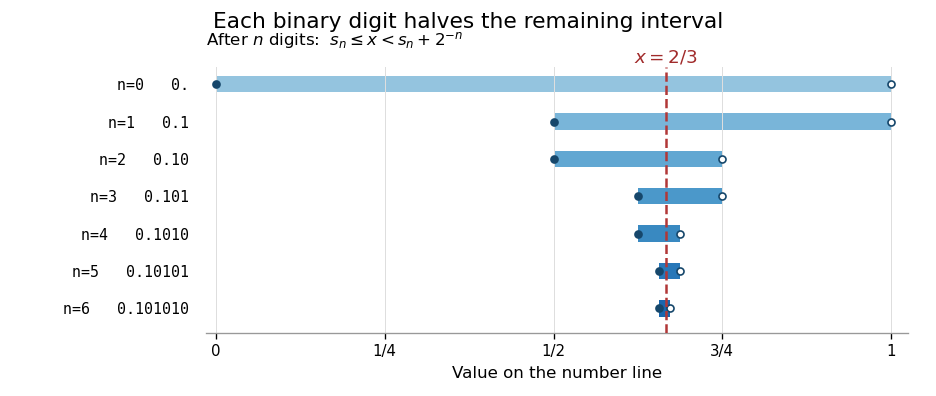
An expansion need not be unique: . For , this ambiguity occurs precisely at the dyadic rationals, through a terminating expansion and an alternative ending in ones. At the endpoints, the displayed purely fractional form uses all zeros for zero and all ones for one. A general nonnegative real number is represented by adding the finite binary representation of its floor to an expansion of its fractional part; a negative real number is handled by a separate sign. In that broader notation, too.
A base-two positional fraction with a binary point separating nonnegative and negative powers of two. For example, . A finite expansion is a dyadic rational: with fractional places, its value is an integer divided by . Conversely, any nonnegative reduced fraction whose denominator is a power of two has a finite binary expansion. Leading integer zeroes and trailing fractional zeroes do not change its value.
A representation with and only finitely many nonzero coefficients. If counts these representations, then , , and for . The integer parity of determines whether the coefficient of must be 1 or may be 0 or 2.
A dyadic rational is a rational number of the form with an integer and a nonnegative integer . Examples are , , zero and every integer. In lowest terms, its denominator is a power of two, so its magnitude has a finite binary expansion.
A positive dyadic rational also has a binary representation ending in infinitely many ones. Replacing the last nonzero binary digit by zero and filling all lower places with ones preserves the value, becauseFor example, . Zero has no second nonnegative expansion of this type. The same ambiguity applies to the magnitude of a negative dyadic rational, with its sign kept separately.
The extended real numbers adjoin and to . They preserve the total order but leave some arithmetic expressions, such as , undefined.
Integer arithmetic computes with integers. Addition, subtraction and multiplication preserve integer values; division can instead return a quotient and remainder through Euclidean division. For example, gives five complete groups and a remainder of two. The ceiling count for fixed-size batches requires six groups to hold all 102 items.
Mathematical integers have no fixed size bound. A computer representation may have one, so an exact arithmetic formula still requires sufficient space for its inputs and intermediate values. The floor function and ceiling function define mathematical bounds independently of a chosen representation.
Integer arithmetic in which storage grows with the number of numerical digits needed, instead of imposing a fixed word size. It allows exact addition, multiplication, and exponentiation on large integers, subject to available memory; operation costs grow with operand length.
Store an integer in a nonempty array of numeral digits, with the least significant digit first and a fixed radix . Normalized digits satisfy . High-order zeros do not change the value. Adding digit arrays coefficientwise or multiplying them by discrete convolution gives the correct value before normalization, because these operations add or multiply the corresponding powers of the radix. Exact temporary arithmetic, or a radix and accumulator size chosen to prevent integer overflow, is required.
When the radix is , print the highest nonzero normalized digit without leading zeros, then every lower digit as exactly decimal characters. Internal zero blocks must be retained. With base , the low-first digits print as
12 followed by 000 followed by 004, giving 12000004. An all-zero representation prints a single zero, independent of its allocated length.Process a digit-array integer representation from low to high positions. The integer division supplies and . Replacing the current digit by and adding to the next position preserves the represented value. Append zero storage when a positive carry leaves the allocated array. The processed prefix remains normalized and the value stays fixed.
This also works with signed temporary digits when the represented value is nonnegative. A negative carry cannot leave the final allocated position: the normalized lower digits represent a value less than that position's next radix power, which could not offset that negative carry. Positive carries eventually stop beyond the value's finite radix expansion. Thus the usual nonnegative-digit algorithm admits this useful extension without interpreting truncated division as floor division.
Arbitrary-precision integer arithmetic performs exact addition, subtraction, multiplication, and integer division using as many machine words as the value requires. A typical representation stores a sign and digits in base , with each digit occupying one machine word. Carries propagate between words just as in written decimal arithmetic.
For example, can be stored exactly even when a single machine integer has only bits. The attainable size is limited by memory and execution time, rather than a fixed numeric range. The cost grows with the number of bits, so an arithmetic operation on a large value cannot automatically be counted as constant time.
Big-integer multiplication multiplies arbitrary-precision integers represented by arrays of digits. For and , first compute the coefficient sums , then propagate carries in base . Thus the main step is a convolution followed by carry handling.
The school method needs digit multiplications for two -digit inputs. Karatsuba multiplication splits each input into two halves and uses three recursive products instead of four, giving arithmetic work under the usual digit model. For larger inputs, transform-based methods accelerate the convolution. Which method is fastest depends on input size and implementation overhead.
An arbitrary-precision integer stores an integer using a variable number of machine words. Unlike a fixed-width integer, it grows when more binary digits are needed. The sign and a finite sequence of base- digits represent its exact value.
For example, the integer requires hundreds of bits but no rounding. Arbitrary-precision integer arithmetic operates on these representations; it is distinct from approximate floating-point arithmetic. Memory and computation still impose practical bounds, so arbitrary precision does not mean infinite available storage.
Addition combines two numbers into their sum. For natural numbers, joining disjoint collections of sizes gives a collection of size . On a number line, adding shifts a starting position by : rightward when and leftward when .
Starting at and adding reaches . Starting there and adding returns to , because . Additive inverses turn this return move into an algebraic rule. With real numbers, addition is commutative and associative: exchanging two shifts or grouping several shifts differently leaves the final position unchanged.
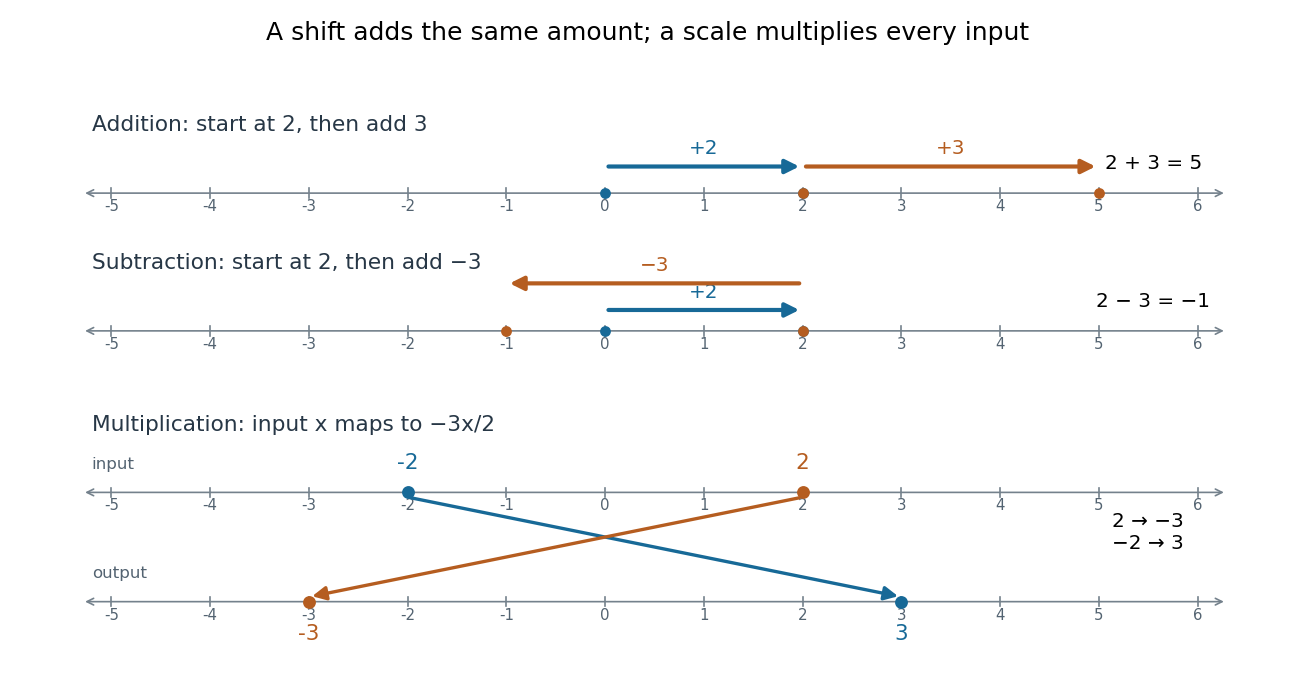
Addition shifts positions on a number line, while a negative multiplication factor changes both scale and direction
. Details. The bottom panel applies . Input becomes , and input becomes . Multiplication by a negative real number rescales distances from zero and reverses direction, giving a reflection in mathematics as well as a scale change. This is a different operation from shifting every input by one fixed amount.
An additive inverse of is an element whose sum with is the additive identity: . Every element of an additive group has an additive inverse.
The associative property proves uniqueness. If and , thenFor example, the additive inverse of the integer is . The need for an inverse depends on the ambient system: has no additive inverse among the natural numbers, so addition on the natural numbers does not form a group.
A finite sum adds finitely many terms, for example for a positive integer . The empty sum is the additive identity. In an abelian group, the associative property and commutativity of the abelian group make the result independent of grouping and order.
For an integer , Faulhaber's formula expresses a sum of powers as a polynomial in the upper limit:where are the Bernoulli polynomials. The identity makes the sum telescope. This is a discrete analogue of finding an antiderivative.[ref]
For the result is ; for it is . Although the displayed polynomial has rational coefficients, it takes integer values at nonnegative integers.
For a fixed nonnegative integer , the Faulhaber polynomial is the rational-coefficient polynomial satisfying for nonnegative integers . It is characterized by and .
For example, has degree three and leading coefficient . In general the degree is and the leading coefficient is , since taking a finite difference lowers the degree by one. Faulhaber's formula constructs these polynomials from the Bernoulli polynomials.
The Euler-Maclaurin formula relates a finite sum to an integral and endpoint derivatives. If are integers, and has continuous derivatives through order on , thenHere are Bernoulli numbers. With the periodic Bernoulli function, the exact remainder isThis form rearranges the last endpoint correction in the NIST statement.[ref]
For on and , the remainder vanishes because the second Bernoulli polynomial has integral zero over each unit interval. The result is , the square pyramidal number formula. For other functions, retaining or bounding makes the finite truncation a controlled approximation.
A sum whose resulting value is a prime number. This is a condition on the value, rather than a requirement that the summation index run over prime numbers. Counting subsets with a prime-valued sum can use subset sum counts followed by a primality filter on the possible totals.
A telescoping sum cancels intermediate sequence terms, leaving boundary terms. For a finite sequence of real numbers , the displayed identity follows because every occurs once with each sign. Applying it to an infinite series also requires checking the limit of the boundary terms; finite cancellation alone does not prove that the series is a convergent series.[ref]
5.2 Infinite Series. Calculus Volume 2, §5.2 Infinite Series: Telescoping Series definition and successive partial-sum identities
For , expanding the finite sum givesNo monotone sequence assumption is required. Consider the original sequence . Its successive finite differences are , soThe large intermediate rise and fall disappear from the net change. This is useful whenever one knows successive changes rather than every absolute value: adding the changes reconstructs the final value from the initial one. It also checks a cumulative-update calculation without requiring all increments to be positive.
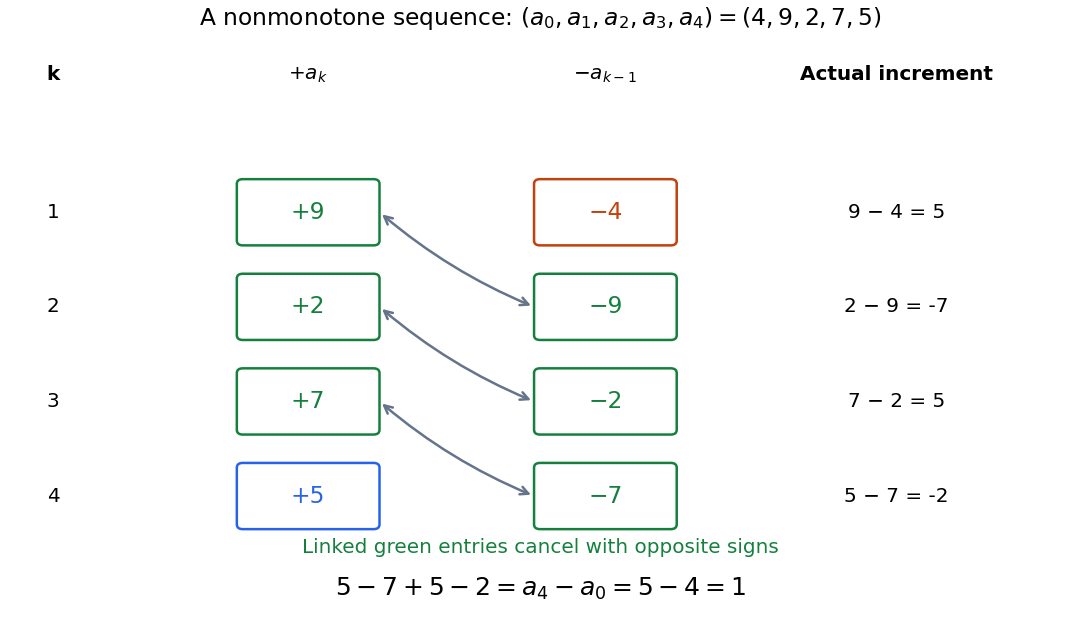
Opposite signs cancel the intermediate sequence terms, leaving the final value minus the initial value
. Original nonmonotone sequence . Linked green entries have the same magnitude and opposite signs; the unmatched entries are and . The increments are , whose sum is one. Details.A finite difference measures one discrete change. The identity is the discrete counterpart of the fundamental theorem of calculus: accumulation of changes returns the endpoint difference. The related summation by parts transfers a finite difference from one factor of a product to another, with explicit boundary terms.
For a meromorphic function , the displayed telescoping sum identity holds wherever every summand is defined. If the two endpoint terms are finite at , their difference gives a holomorphic continuation of the entire sum to , even when individual summands have poles there. This continued value is a common-shift limit; it does not make an originally undefined sum of complex numbers well defined without an additional convention.
The proof is finite cancellation on the common domain of definition, followed by analytic continuation. For , a common shift away from the imaginary axis avoids its poles. Different independently chosen shifts of individual summands need not give the same limit, so specifying the common shift matters.
Sometimes a sum does not initially look like a difference of neighboring entries. A partial fraction decomposition can reveal the cancellation. For the original examplesubtract the two reciprocals:ThusFor , direct addition gives . For , the six positive entries add to . The partial sums approach , and the exact series remainder isThis formula answers an accuracy question as well as a summation question. To make the remaining positive series remainder smaller than , solve . The result is , so the smallest permitted integer is . At , the error is ; at , it is .
For a real sequence , the partial sum of is exactly . Consequently it is a convergent series if and only if has a finite limit , and its sum is . Cancellation takes place inside each finite partial sum; taking a limit is a separate step.[ref]
5.2 Infinite Series. Calculus Volume 2, §5.2 Telescoping Series: general boundary sequence, finite partial sums and finite-limit convergence criterion
The partial fraction telescoping example has and therefore limit . In contrast, let . Its first entry is , so . The even partial sums are zero and the odd partial sums are negative two. Both finite cancellations are correct, but the sequence has no single limit, giving a divergent series.
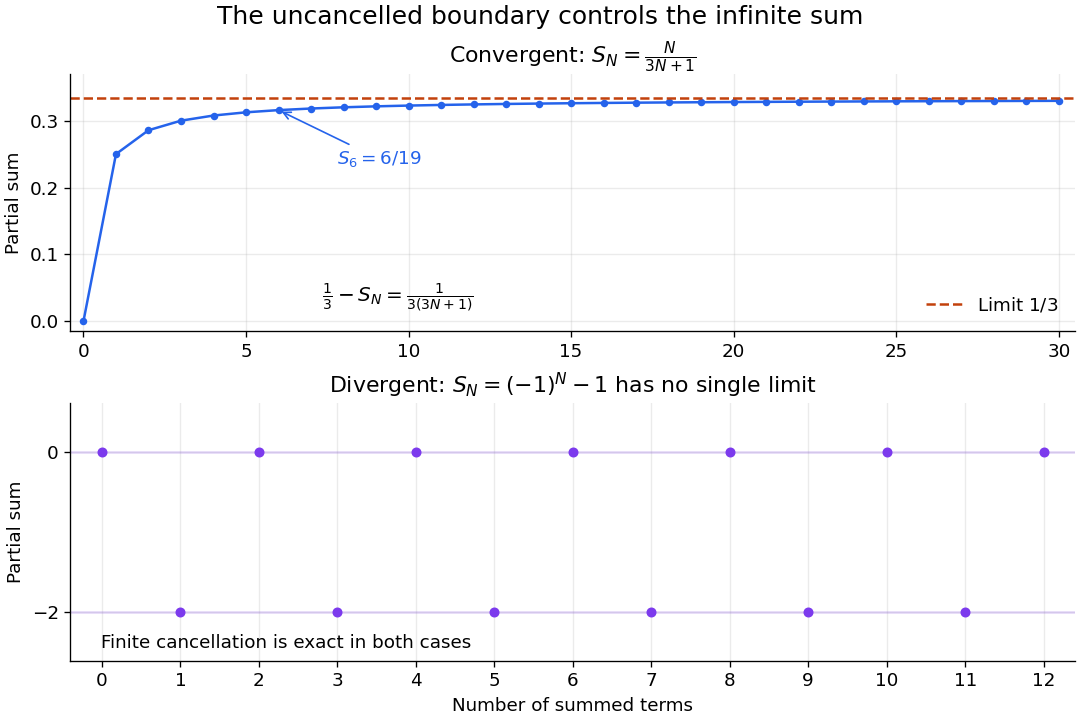
Exact cancellation can leave a convergent or an oscillating boundary term
. Original calculated partial sums. Top: approaches , with known series remainder . Bottom: alternates between zero and negative two. The dots are finite partial sums, not observed data. Details.It is also essential to keep the two contributions paired. For example, is a convergent series with sum one, as its finite partial sum is . Writing it instead as asks to subtract two divergent series. The permitted finite cancellation does not define that separate subtraction. Working through partial sums keeps the indices aligned and the operation meaningful.
A finite sum is the result of repeated addition of its terms, written for example . The empty sum is zero. In an abelian group, associativity and commutativity make a finite sum independent of its grouping and the order of its terms.
For an infinite sequence of real or complex terms, a sum requires a limit of a sequence: the partial sums must converge to a finite value. This is a convergent series. For example, , while has no finite sum. Writing a summation symbol alone does not establish convergence.
An empty sum has no terms and is defined to be zero, the identity element for addition. This keeps the rule for combining sums valid when one index set is empty. In a Galton-Watson process, an empty generation contributes an empty sum of offspring counts, so the next generation is empty too. The corresponding convention for multiplication is the empty product, which equals one.
The weighted arithmetic mean combines values according to how much each contributes to the quantity being summarized. For a finite list of real numbers and nonnegative weights with , defineZero weights ignore an entry; at least one weight must be positive. Multiplying every weight by the same positive number leaves the result unchanged. Writing makes the weighted mean a convex combination, since and . It therefore lies between the smallest and largest input values. [ref]
https://www.itl.nist.gov/div898/software/dataplot/refman2/ch2/weigmean.pdf. NIST Dataplot reference manual: weighted mean
For example, give the values and weights and :The larger weight pulls the result closer to . The balancing identityexplains a geometric interpretation: if the weights were masses placed at positions , the weighted mean would be their center of mass. Here , so the two sides balance even though their distances from the mean differ.
Weights need an interpretation. They can represent numbers of observations, masses, or probabilities in a finite probability distribution. These meanings lead to the same formula, while answering different questions. For instance, combining means of groups uses group sizes as weights to recover the mean over individual observations. For a function and nonnegative weight function , the analogous integral is , provided is integrable and the total weight is positive and finite.
Inverse-variance weighting combines estimates of the same quantity by giving a more precise estimate a larger weight. Suppose are independent, unbiased estimators of , with known variances . For normalized weights,The inverse is taken after squaring the standard uncertainty: twice the standard uncertainty gives one quarter as much weight. The corresponding weighted least squares criterion is ; differentiating it with respect to gives the same weighted arithmetic mean.[ref]
The optimality statement is precise. Any linear unbiased estimator requires . By the Cauchy-Schwarz inequality,Equality holds for the displayed weights. Thus they minimize variance among linear unbiased combinations under these assumptions; a normal distribution is not needed for that proof.
For an original example, combine observed values 10 and 14 with standard uncertainties 1 and 2 in the same units. The normalized weights are and , giving estimate , variance and standard uncertainty approximately . Equal weights give 12 and standard uncertainty .
Correlated errors change the problem. A contribution common to every reading survives every weighting whose coefficients sum to one; precision limits of weighting correlated repeats derives the resulting floor. More generally, use the full covariance matrix and generalized least squares rather than treating correlated readings as independent.[ref]
Guide to the expression of uncertainty in measurement by JCGM. §5.2.2, equation13, and §5.2.4, common inputs
Uncertainty in estimated inverse-variance weights is another limitation: variances estimated from the same data are not fixed known quantities, and an accidentally tiny estimated variance does not justify arbitrary confidence.Uncertainty in estimated inverse-variance weights arises when the variances used in inverse-variance weighting are themselves estimated. A very small estimated variance can give one observation or group a large random weight. The familiar variance formula for fixed, known weights cannot simply be reused with estimated variances treated as exact. NIST specifically warns that weights estimated from few replicates can substantially and unpredictably affect a weighted least squares analysis.[ref]
Suppose independent groups contain independent normal random variables with common mean and group variance . Let and be the group sample mean and unbiased sample variance, and formFor normal samples, each sample mean is independent of its sample variance. Conditional on the estimated weights, the estimator remains unbiased and hasThus the law of total variance gives unconditional variance equal to the expectation of this expression. The true still appear; replacing them by the same random does not establish the actual conditional variance. Outside the independence assumptions, even conditional unbiasedness can fail.
An original two-group example takes and true , so each group mean has variance . If observed sample variances are and , the estimated normalized weights are and . For group means and , the combined estimate is . The plug-in variance isbut the true conditional variance under the stipulated model isThe corresponding standard deviations are about and . Equal weights would have variance . An accidentally small estimated variance has both overstated precision and moved the combination away from the optimal equal weights in this example.
Reciprocal moments of an estimated variance explain the unstable precision estimate. For a normal sample with , has a chi-squared distribution. Integrating its density givesConsequently for , while the second moment requires . The density and its gamma-distribution parameterization are documented in the primary SciPy implementation notes.[ref] With , the inverse sample variance has a finite mean twice the true precision and an infinite variance; the normalized weights remain bounded, so this does not imply their variance is infinite.
More replication or a justified smooth variance model can stabilize weights. NIST describes direct replicate-based weight estimation and variance-function modeling as distinct approaches.[ref]
Weighted Least Squares by NIST. e-Handbook §4.4.5.2, Direct Estimation of Weights and Estimating Weights with a Variance Function
A proposed validation repeats the complete weight-estimation and combination procedure on simulated or replicated groups, checking actual interval coverage as well as point estimates. A bootstrap must reproduce the weight-estimation stage; holding the fitted weights fixed tests a different procedure.Reciprocal moments of an estimated variance determine whether a precision estimate such as has a finite expected value or variance. Small positive values of a sample variance become large values after inversion. An unbiased estimator of a variance therefore need not give an unbiased or even integrable estimate of its reciprocal.
For , let be independent normal random variables with common mean and variance . For the unbiased sample variance , put . Then has a chi-squared distribution. Its probability density function is for .[ref]
For any real , direct integration and the Gamma function giveThe convergence restriction is essential: near zero the integrand has exponent , so the integral diverges when . Substitution of a negative Gamma function argument into the displayed quotient does not define a nonexistent moment.
Rescaling gives the useful general resultIn particular, the mean reciprocal exists for , while its variance requires :For the mean is , the variance is and the coefficient of variation is . For the mean is finite but the variance is infinite. For even the mean diverges. Increasing the number of groups does not repair a nonexistent moment of each raw reciprocal estimate.
Inverse-variance weighting commonly normalizes these reciprocals. Those normalized weights lie between zero and one, so their moments can exist even when the raw reciprocal moments fail. This distinction matters in uncertainty in estimated inverse-variance weights: neither the moment calculation nor a plug-in precision formula alone establishes the accuracy of the final weighted estimator. The results here use the exact normal-sample law; a nonnormal sample requires a different analysis.
For positive mean density, this average weights a velocity by local mass rather than volume. It satisfies the exact identity , so it naturally represents mass flux in averaged conservation laws. The ordinary volume mean generally fails that identity when density and velocity are correlated. Applied inside a phase, the same construction uses density times that phase's indicator as its weight.
For a partition of a set of complete sample observations into groups of known sizes and total , its sample mean is the weighted mean of the group sample means. Indeed, dividing by proves the identity. If the printed group means each have absolute rounding error at most , their compatible pooled mean lies inThis follows because all the weights are nonnegative. Equivalently, the pooled absolute rounding error is at most , by the triangle inequality. A printed overall mean must have a rounding interval intersecting this interval. Disjoint intervals prove incompatibility, rather than merely a difference of displayed decimals. This is a necessary consistency check for means of the same complete sample; it cannot silently equate a full-sample mean with a different complete-case mean or establish a unique repair to inconsistent output.
Suppose disjoint nonempty groups have sizes and arithmetic means . The arithmetic mean of all observations isEach group contributes the sum ; add those totals before dividing by the overall count. This is exactly a weighted mean of group means with weights equal to group sizes. [ref]
Take a synthetic example with two observations equal to and eight equal to . The two group means are and , and the combined mean is . Giving the two groups equal weights instead produces , which summarizes the two group means with equal influence. To summarize all ten individuals with equal influence, use their group counts.
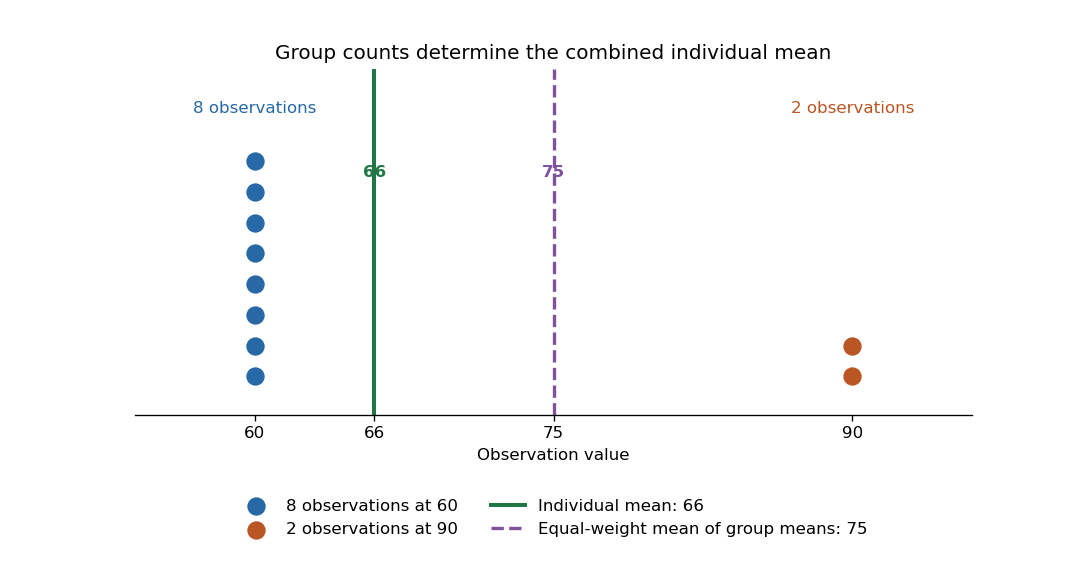
The group means and counts determine the combined arithmetic mean, but do not generally determine the combined variance. Variation within the groups is additional information.
For a finite list of real numbers and nonnegative weights of positive total , the weighted mean uniquely minimizes the weighted sum of squared deviationsExpanding around and using givesEvery displacement from the weighted mean increases the objective. This is the simplest one-parameter weighted least squares problem: represent all entries by one common value.
For the weighted values and with weights and ,Thus , while . The minimum is defined by this squared-error criterion; a different loss can select a different summary, such as a median under unweighted absolute deviations.
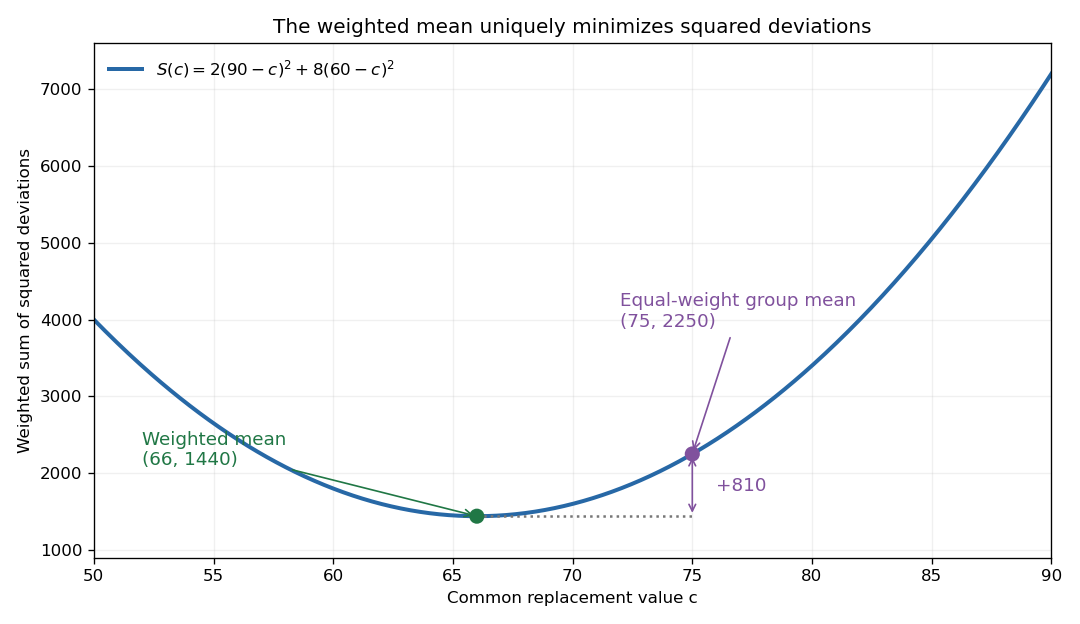
For a nonempty finite list of real numbers , the arithmetic mean isIt is the weighted mean with equal weights, giving each observation equal influence. For , the sum is and the arithmetic mean is . Replacing every value by retains the same total. The residuals sum to zero, so the mean is also the balancing point of these equally weighted observations.
The arithmetic mean minimizes the sum of squared deviations by the weighted mean minimizes squared deviations identity with all weights one. A large input can consequently have a substantial effect: replacing by changes the mean to , while the median remains . The choice of summary depends on what aspect of the data matters.
The harmonic mean of a nonempty finite list of positive real numbers is the multiplicative inverse of the arithmetic mean of their inverses:For two inputs, . Replacing each input by preserves the sum of inverses, making it useful when a fixed amount divided by a rate determines a cost or duration. This positive-input definition avoids division by zero; negative inputs need not retain the usual averaging or ordering properties. [ref]
https://dlmf.nist.gov/1.2.iv. NIST Digital Library of Mathematical Functions, §1.2(iv), equation 1.2.19: harmonic mean
.Travel two legs of equal length at positive speeds , with no stops. Their travel times are and , so the average speed isFor two legs at and , the times are two hours and one hour. The average speed is . The same speeds maintained for one hour each instead cover in two hours, giving the arithmetic mean . A slower equal-distance leg occupies more time, so the data being averaged must include what is held equal. This is total distance traveled divided by elapsed time; a return journey can have zero average velocity while keeping a positive average speed. [ref]
https://undergroundmathematics.org/introducing-calculus/average-speed/averages. University of Cambridge, Underground Mathematics: equal-distance and equal-time speed averages
.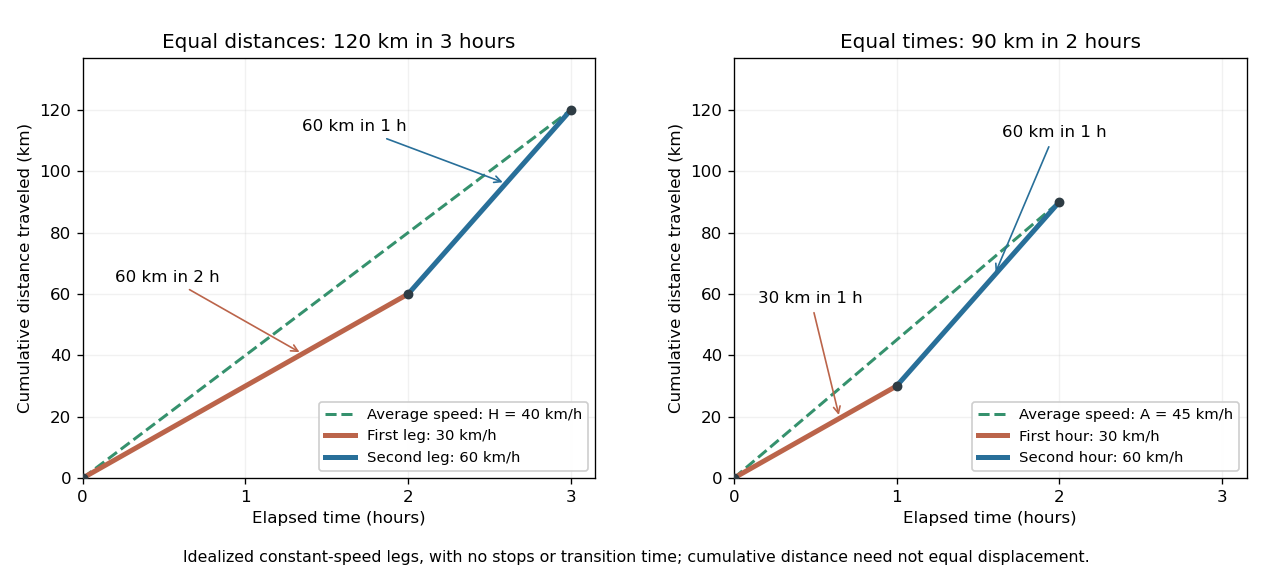
The arithmetic-geometric mean inequality applied to the inverses gives ; together with it yields the comparison in geometric mean. For two inputs the arithmetic–harmonic gap has the exact formFor and the gap is five. With one positive input held fixed and another approaching zero, the harmonic mean approaches zero too: a very slow fixed-distance leg dominates the travel time. Unequal leg lengths instead require a weighted harmonic mean.
For positive real numbers and nonnegative weights with , the weighted harmonic mean isEqual weights give the harmonic mean, while a zero weight excludes that input. For travel at positive constant speeds over positive leg lengths , the weights are fractions of total distance:For at and at , the weights are , elapsed time is hours, and the average speed is . Weighting the speeds by their time fractions instead gives the same result as a weighted arithmetic mean: . The two weight systems describe the same journey in different coordinates and must not be interchanged. [ref].
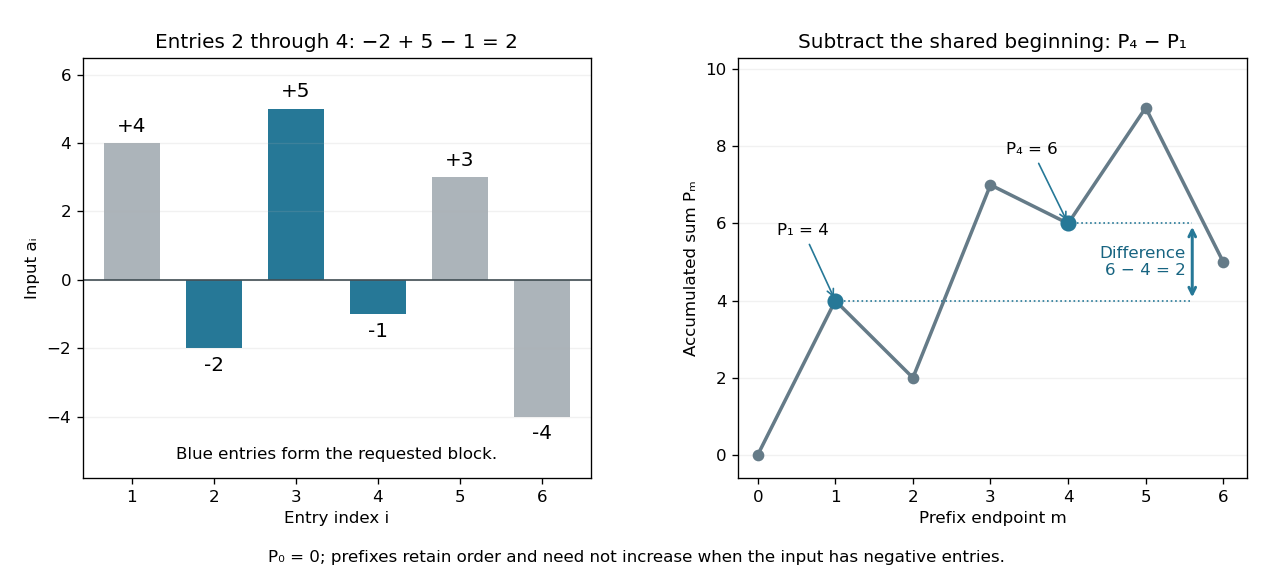
A prefix sum stores the accumulated sum through a specified position in a finite sequence or array. For inputs , include the empty sum and setFor the original input , the prefix array including is . A negative entry makes the accumulated sum decrease; a prefix sum does not have to be monotone. Conversely, the original entry is recovered by subtraction: .
The useful cancellation is that any contiguous block has sumBoth prefixes include the entries before ; subtracting cancels those entries. In the example, the sum from positions two through four is , recovered as . The arithmetic mean of that block is , obtained by dividing its sum by its length. Prefix sums therefore make many repeated questions about an unchanged array cheap: reuse accumulated totals instead of resumming every block.
The sequential recurrence builds all prefixes in time complexity and storage; each block query needs two reads and one subtraction, hence time complexity. These counts assume constant-cost arithmetic and access to array entries. If one input changes, all later stored prefixes change, so this simple representation is most useful when queries outnumber updates. For integer inputs, sufficient numeric capacity must be retained; with floating-point arithmetic, subtracting large nearby prefixes can lose relative accuracy for a small block total. The exact mathematical identity does not eliminate representation error.
The apparently sequential recurrence also motivates a prefix scan: associativity permits a tree of partial calculations that yields all accumulated results in parallel. Guy E. Blelloch's 1990 technical report systematically develops this operation and its applications; its authored chapter version explains the two tree sweeps used to obtain all prefixes. [ref]
https://www.cs.cmu.edu/afs/cs.cmu.edu/project/scandal/public/papers/CMU-CS-90-190.html. Blelloch, Prefix Sums and Their Applications, CMU-CS-90-190, November 1990
. [ref]https://www.cs.cmu.edu/~guyb/papers/Ble93.pdf. Blelloch, authored chapter version, §§1.1–1.2: sequential scans and parallel tree sweeps
.For a finite sequence , its suffix sums are , with . They satisfy , so one backward pass computes all of them in additions.
For , the suffix sums are including the empty suffix. A range sum on is . Thus suffix sums provide the same constant-time range queries as prefix sums, with the accumulation direction reversed.
Articles were limited to the first 100 out of 360 total.
Articles by others on the same topic

Arithmetic is a branch of mathematics that deals with the study of numbers and the basic operations performed on them. The fundamental operations of arithmetic include: 1. **Addition (+)**: Combining two or more quantities to obtain a total. 2. **Subtraction (−)**: Determining the difference between two quantities by taking one away from another. 3. **Multiplication (×)**: Repeated addition of a number a specified number of times.



Definition: "easy" number theory learnt in primary school, notably the operations of addition, subtraction, multiplication and division.