Functional analysis brings linear algebra and topology together to study vector spaces of functions and the linear operators acting on them. A function space such as has infinitely many independent directions: the monomials are linearly independent. Finite linear combinations alone cannot describe all its continuous functions. A useful theory must also say when approximations converge, whether their limits belong to the chosen space, and which operations preserve that norm convergence. Normed vector spaces, Banach spaces, and bounded linear operators provide these three controls.[ref]
A bounded linear operator between normed vector spaces satisfies for every , with one finite constant . The least possible constant is its operator norm. By linearity, the same estimate controls approximation errors:This is exactly continuity for a linear map between normed vector spaces; neither space needs to be complete. It turns an input accuracy guarantee into an output accuracy guarantee, even when the input has infinitely many degrees of freedom.[ref]
https://ocw.mit.edu/courses/18-102-introduction-to-functional-analysis-spring-2021/22bf2f774fb161776032491568148707_MIT18_102s21_lec2.pdf. MIT 18.102, lecture 2: boundedness, continuity, and the operator norm
For a concrete linear functional on , take the integral . In the supremum norm,The constant function attains equality, so . For , the output is ; any approximation with therefore has . The Cauchy-Schwarz inequality also gives on this interval, again with equality at . Thus integration remains a bounded linear functional under the L2 norm, although point evaluation behaves very differently.
The beauty of this viewpoint is that one estimate can justify an entire approximation procedure. Once a sequence converges in the chosen norm, every bounded linear operator carries its limit along. Completeness ensures that Cauchy approximations actually describe an element of the space. The choice of norm matters: it determines which errors are small and which measurements are stable. The examples below distinguish an average, which ignores sufficiently narrow peaks, from point evaluation, which detects their full height. For applications, this decides whether reducing an overall fitting error guarantees an accurate reported measurement. A small L2 norm of the error controls its integral on this interval, while it gives no such guarantee for a single sampled value.
The initial table of content was limited to the first level because it is larger than 1000 articles. There are 1025 articles in total. Expand a branch to load its children.
The Nemytskii operator associated with a scalar function applies pointwise to a function. The domain and target function spaces must be specified; an arbitrary continuous need not preserve them. On a finite-measure domain, a bounded continuous defines a continuous map with . To prove continuity, extract an almost-everywhere convergent further subsequence from every -convergent subsequence and apply the dominated convergence theorem to . This forces convergence of the entire image sequence in .
For normed vector spaces of functions on the same domain, a continuous embedding is an injective inclusion satisfying .
A compact embedding of Banach spaces is an injective continuous linear map that sends every bounded set to a relatively compact subset. Equivalently, every bounded sequence in has a subsequence converging in . One identifies with its image when is the natural inclusion. The Rellich-Kondrachov theorem supplies many compact embeddings between Sobolev spaces and Lp spaces on bounded domains.
A nonnegative function-valued operator is sublinear if and almost everywhere. This pointwise domination notion includes maximal one-sided interval averaging operators and differs from requiring an ordinary linear map.
An operator has weak type , with finite , if the displayed bound holds for every input and every , with one constant independent of both. It controls the distribution of its output rather than requiring its strong norm to be finite.
Let be a sublinear operator with positive constants and and . Split into its part above and its bounded remainder. The latter contributes at most , so the weak bound controls the superlevel measure by . Integrating this estimate with layer cake representation proves the displayed bound for and . In particular it gives the strong estimate for the Hardy-Littlewood maximal function.
For a normed space and , an operator is of weak type when the displayed distribution bound holds uniformly over and . No completeness of is needed. A sublinear operator has pointwise triangle domination and absolute homogeneity; its outputs may be understood modulo almost everywhere equality.
Suppose linear operators and on a normed space satisfy , where has weak type with a normed domain, and all relevant suprema are measurable. If almost everywhere on a dense subspace, the same holds for every input. For a fixed approximation , the limiting error is at most . The measure where it exceeds is at most , which tends to zero as the approximation improves. This is a convergence-to-a-specified-limit version of almost-everywhere convergence from weak-type domination.
For a nonnegative sublinear operator, weak type is the displayed level-set bound for all integrable inputs and positive thresholds. It supplies an exceptional-set estimate for approximation errors; the uncentered maximal weak-type inequality is a central example.
Suppose a family of linear operators, including its limiting operator, is pointwise dominated by a sublinear operator of weak type (1,1). Convergence almost everywhere on an -dense subspace then extends to every input. Approximate the input by errors of norm at most . The weak estimate and the Borel-Cantelli first lemma make the corresponding domination errors tend to zero almost everywhere. Linearity bounds the difference between the full and approximating convergence errors by twice that domination error. This argument does not need an uncountable supremum to be measurable.
An operator algebra is an algebra of linear operators, with multiplication given by composition. In quantum examples it can be generated by creation and annihilation operators subject to the canonical commutation relations or canonical anticommutation relations. Its analytic realization requires specifying a common domain for unbounded operators.
For a lattice system, finite-region observable algebras embed into larger ones by tensoring with the identity. Their union has a norm closure called the quasi-local observable algebra, a C-star algebra. It describes finite-support observables and norm limits of such observables. An operator flipping every spin of an infinite lattice need not belong to it: successive finite-region flips are not norm-Cauchy. Restrictions to this algebra can therefore lose relative-phase information retained by increasingly nonlocal finite-system observables.
A vector is cyclic for an operator algebra when its orbit under that algebra has dense linear span. This is distinct from requiring the powers of one chosen operator to span the space. If the algebra is linear, its orbit itself is already a vector subspace.
A vector is separating for an operator algebra when evaluation at that vector is injective. A cyclic vector for the commutant of an operator algebra is separating for the original algebra: if , then vanishes on its dense commutant orbit.
For a Von Neumann algebra with a cyclic separating vector, this is a densely defined antilinear operator. It is closable: the commutant orbit lies in the domain of its antilinear adjoint and is dense. Write for its closure and for its polar decomposition. In finite dimension it is everywhere defined and invertible. For a tracial vector, is isometric and extends to an antiunitary involution.
The positive operator in the polar decomposition of the Tomita operator. In a matrix-algebra standard representation with cyclic vector , it is . For a tracial vector it is the identity.
The antiunitary factor in the polar decomposition of the Tomita operator. In the finite-dimensional and tracial settings it satisfies and . In a matrix-algebra standard representation by left multiplication, with positive invertible cyclic vector , it acts by .
A unital star-subalgebra of the bounded operators on a Hilbert space that is closed in the weak operator topology, equivalently in the strong operator topology. The Von Neumann double commutant theorem makes these conditions equivalent to equality with the double commutant of an operator algebra. It is norm closed and hence a C-star algebra.
Here a Hilbert space module means a Hilbert space with a unital star-representation of a Von Neumann algebra, rather than a Hilbert C-star module with an algebra-valued inner product. A closed invariant subspace is reducing because the algebra is closed under adjoints. Module equivalence means an intertwining unitary. The polar decomposition of a bounded operator converts an intertwiner into a unitary between its initial and final support subspaces.
Two Hilbert space modules are unitarily equivalent if each embeds isometrically as a closed submodule of the other. For isometric intertwiners and , let and . These summands are orthogonal. The operator acting as on and as on is the required unitary onto .
A Von Neumann algebra whose center consists exactly of scalar multiples of the identity. A group von Neumann algebra is a factor exactly when every nonidentity conjugacy class is infinite. A central operator has a square-summable coefficient vector constant on those classes; an infinite class must therefore have coefficient zero. Conversely, the sum of left translations over a finite nonidentity class is a nonscalar central operator.
For a discrete group, its group von Neumann algebra is generated on by left translations . The vector is cyclic and separating, and its vector functional is tracial. Its modular conjugation acts by with conjugated scalar coefficients. The commutant is the algebra generated by right translations .
A metric embedding represents the points of one metric space inside another by an injective function . The geometric question is how faithfully the representation preserves pairwise distances. For example, binary strings can be treated as vectors so that tools from linear algebra become available, but the chosen norm determines what their separation means. A drawing of the points alone does not specify a metric embedding: both metrics matter.
An isometric embedding preserves every distance exactly. A metric embedding that is a bi-Lipschitz map allows multiplicative error while keeping its bi-Lipschitz distortion bounded over all pairs. A coarse embedding instead controls separation through possibly nonlinear functions of distance. These are different requirements: the Hamming cube as an L1 and L2 metric below preserves Hamming distance exactly in one representation and takes its square root in another.
The usefulness is that a complicated distance comparison becomes a calculation with familiar vectors and norms. This also helps assess a visualization: nearby points should not acquire arbitrarily large separations, and far-apart points should not collapse together. Matoušek's 2013 lecture notes describe how motivations from computer science, especially approximation algorithms, accelerated the study of metric embeddings from the 1990s onward. [ref]
Lecture notes on metric embeddings by Jiří Matoušek. Jiří Matoušek, Lecture notes on metric embeddings, preface and Section 1.1
For an injective function between metric spaces with at least two source points, consider all distance ratiosIf constants satisfythen is a bi-Lipschitz map: both and its inverse on are Lipschitz maps. The bound compares the most expanded pair with the most contracted pair. To define the bi-Lipschitz distortion of this particular metric embedding, use the sharp bounds and :Here the Lipschitz constant of is . If no positive finite bounds exist, the bi-Lipschitz distortion is infinite. For a finite source, every injective function has finite bi-Lipschitz distortion, but its size can depend on the source. Matoušek gives the equivalent definition using one scale factor and a multiplicative error bound. [ref]
Lecture notes on metric embeddings by Jiří Matoušek. Matoušek, Section 1.1: distortion and Lipschitz maps
Changing units is harmless: replacing by , with , multiplies both and by and leaves unchanged. In a normed vector space this can be achieved by multiplying every output vector by . Thus bi-Lipschitz distortion one means that all distances change by the same factor; an isometric embedding additionally requires that factor to be one. A stretch factor with a specified normalization is a related quantity; when comparing sources, check which overall scale has been fixed.
Take the four corners , , , of a square, with Euclidean distance in both source and target. For the linear map , the six unordered pairs exhaust the possibilities: the two vertical sides have ratio , the two horizontal sides have ratio , and the two diagonals have ratio . Consequently , , and . In contrast, , three times the identity function, gives ratio for every pair and has bi-Lipschitz distortion .
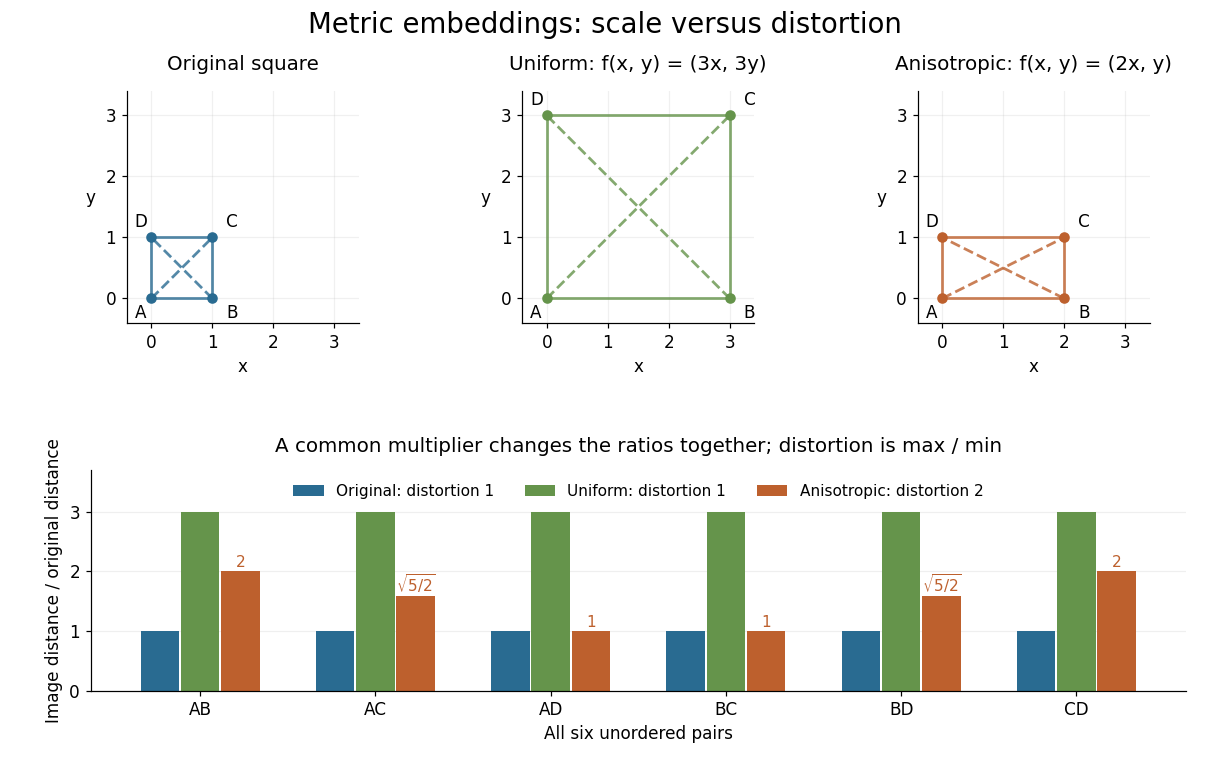
Uniform scaling keeps distortion one; unequal coordinate scaling gives distortion two
. Details. The ratio chart makes the reason visible: a common multiplier moves every ratio together, while unequal coordinate scaling spreads the ratios apart. More generally, in a normed vector space, the ratio bounds giveThis normalization gives Lipschitz constant one and inverse Lipschitz constant . It is only a change of scale, so it cannot improve the bi-Lipschitz distortion.
The best possible bi-Lipschitz distortion of a source into a specified target is a separate quantity:The infimum runs over all injective functions, and need not be attained. The notation means the analogous infimum over metric embeddings into an Lp space. A calculation for one chosen gives an upper bound for ; proving optimality also requires a lower bound for every possible .
For an injective function that does not increase distances, one stretch-factor convention measures the largest compression that must be undone:If the sharp Lipschitz constant of is one, this equals bi-Lipschitz distortion. Fixing the scale matters: uniform compression has stretch factor two in this convention, but bi-Lipschitz distortion one. In a geometric spanner, the corresponding stretch factor is the largest graph-route distance divided by direct Euclidean distance; the graph-to-Euclidean identification does not increase distances. [ref]
https://people.scs.carleton.ca/~michiel/encyc_geometric_spanners.pdf. Gudmundsson, Narasimhan and Smid, Geometric Spanners, §1: the stretch-factor convention
.A map between metric spaces is a coarse embedding when nondecreasing control functions satisfyThe last condition means that distances tending to infinity in the source must also tend to infinity in the target. The upper control prevents bounded source distances from having unbounded image distances. Unlike a metric embedding as defined here, a coarse embedding need not be injective: its lower control may vanish at small distances. Finite bi-Lipschitz distortion implies a coarse embedding by taking and , but nonlinear controls such as allow much more compression.
A family uniformly coarsely embeds into when maps admit the same two control functions and from the definition of a coarse embedding, independent of . For a single finite metric space, the lower control can vanish up to its diameter and then grow without bound; this says little about its representation. For a family with unbounded diameters, common controls have real content: they cannot be chosen afresh after seeing each member's diameter. The Hamming cube as an L1 and L2 metric supplies explicit common controls, in contrast with the expander graph obstruction to uniform coarse embedding.
Use the convention for the Hamming cube . Its elements are length- binary strings, and their Hamming distance counts the differing coordinates:Send each binary string to the vector with the same coordinates, by . Every differing coordinate contributes both to the sum of absolute differences and to the sum of squared differences. Therefore the L1 norm and L2 norm give, respectively,This short coordinate calculation proves that the L1 norm gives an isometric embedding, while Euclidean distance grows like the square root of the number of changed binary digits. For example, and differ twice: their Hamming distance and Manhattan distance are , but their Euclidean distance is . Comparing binary strings in these two geometric representations answers different questions even though the points have the same coordinates.
For distinct pairs ranges over every integer from to . The metric embedding into the L2 norm thus has sharp ratiosNeighbors attain and opposite corners attain . This computes the bi-Lipschitz distortion of this coordinate map; it does not prove that every metric embedding into an L2 space has at least this bi-Lipschitz distortion. Uniformly multiplying the output coordinates changes and together and leaves unchanged.
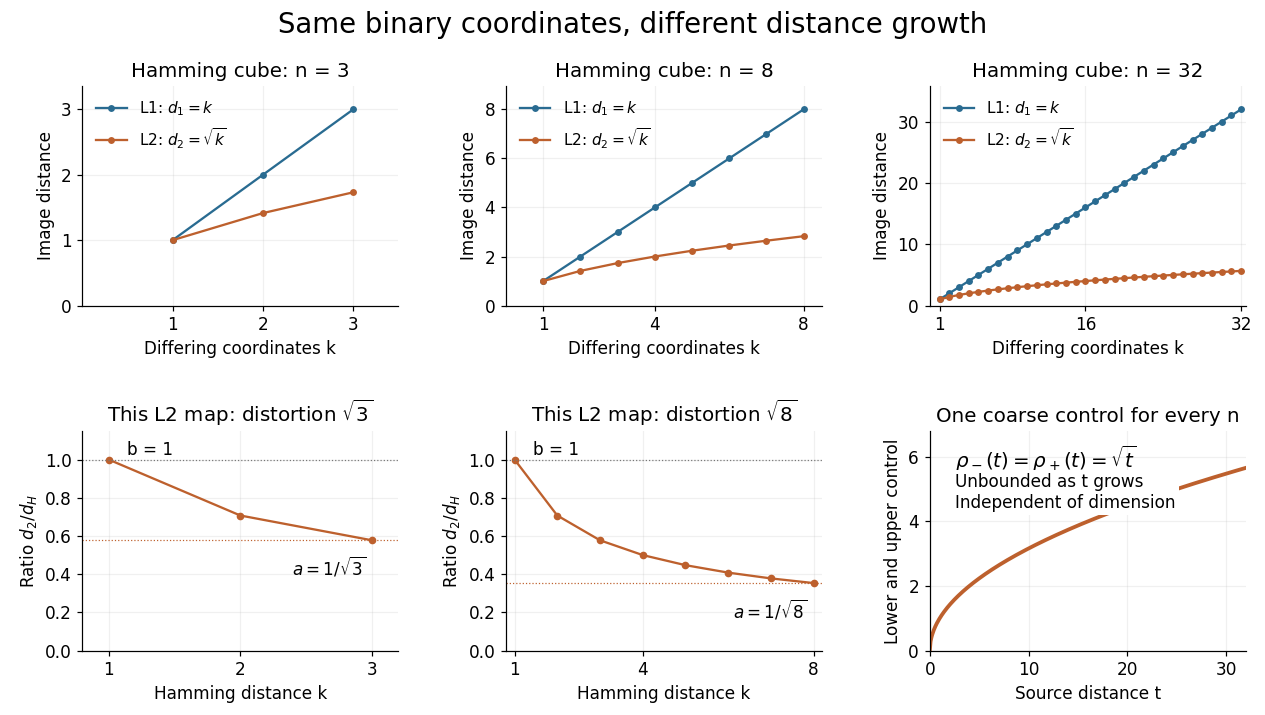
The important family distinction is that these coordinate maps have no dimension-independent bound on their bi-Lipschitz distortion into the L2 norm, yet they do give a uniform coarse embedding of a family of metric spaces. Pad each output vector with zero coordinates to view all maps in the single l2 sequence space, an L2 space for counting measure. Then the same functionswork for every , and . Similarly, padding into the l1 sequence space gives common controls and exact preservation of Hamming distance. These claims use unnormalized Hamming distance; replacing it by normalized Hamming distance changes the family of source metrics.
The geometry has a practical origin: Hamming's 1950 paper uses the number of differing positions between binary strings to study error-correcting codes. Changing one binary digit moves to a neighboring corner, so a question about corrupted messages becomes a question about separation in the Hamming cube. [ref]
https://ineffectivetheory.com/edu/papers/hamming-codes-1950.pdf. R. W. Hamming, Error Detecting and Error Correcting Codes, 1950, Section 5
For a finite graph , its edge-expansion constant isAn expander family has uniformly bounded degrees, orders tending to infinity, and expansion constants bounded below by a positive constant.
For a port-labeled -regular graph and a -regular graph on its port labels, replace every vertex by a copy of . An edge makes a step in , crosses the corresponding edge of , then makes another step in . The result has vertices and degree . Its normalized operator is , where and is the involutive edge rotation of . Decomposing a mean-zero vector into cloud-constant and cloud-orthogonal parts proves the bound .
Choose and a fixed -regular graph on vertices with absolute nonconstant eigenvalues at most . Start with the loop-inclusive complete graph on vertices and iterate . The degree stays , vertex counts are , and . Since , all . The spectral cut bound gives multiplicity-counted edge expansion at least . Removing loops and merging parallel edges loses at most a factor , producing simple expander graphs with maximum degree and edge expansion at least .
If has adjacency matrix and expansion , then every -valued map on its vertices satisfiesFor scalar functions this follows from the layer-cake formula applied above and below a median; integration over the coordinate proves the vector-valued form.
For a nonnegative measurable function ,On a graph, applying this identity to expresses its total variation as the integral of the edge boundaries of the superlevel sets.
More generally, if is differentiable, increasing, and satisfies , then Tonelli theorem and the fundamental theorem of calculus give
Let , , and . Assume the displayed tail inequality and finite positive-threshold superlevel measures. First split at to obtain . Layer cake representation and Tonelli theorem imply . Integrating the original inequality against then gives , with . This is the analytic estimate behind the Doob Lp maximal inequality.
If a -regular graph on vertices has expansion , its distortion obeysThe Poincare inequality controls average image distance by edge lengths, while bounded-degree ball growth makes the average graph distance comparable to .
An expander family does not uniformly coarsely embed into or . Uniform upper control bounds every embedded edge, whereas the expander Poincare inequality bounds the average image distance. A fixed proportion of vertex pairs have graph distance tending to infinity, contradicting the lower control. The case also follows from the isometric Gaussian embedding of a Hilbert space into .
A Banach space is finitely representable in when, for every finite-dimensional subspace and every , there are a subspace and an isomorphism with .
A Banach space is superreflexive when every Banach space finitely representable in it is a reflexive Banach space. Equivalently, it admits an equivalent uniformly convex norm, or every one of its ultrapowers is reflexive.
A Banach space is reflexive exactly when, for every and every sequence in , some convex combination of a finite initial segment lies within of a convex combination of the remaining tail. In a reflexive space both convex hulls approximate a common weak cluster point. The converse is the convex-block form of the James reflexivity criterion.
James's theorem says that a Banach space is reflexive exactly when every continuous linear functional attains its supremum on the closed unit ball. Its separation proof also yields the equivalent convex-block criterion: nonreflexivity produces a bounded sequence whose initial and tail convex hulls remain uniformly separated.
For finite-dimensional subspaces and , the principle of local reflexivity gives an almost-isometric map that fixes and preserves the pairings with . It lets finite-dimensional bidual separation data be realized inside .
A Banach space is superreflexive exactly when, for every , some forces every sequence to have two convex combinations, one before and one after a cut, at distance below . Failure produces a nonreflexive ultrapower; finite representability transfers a violating finite sequence back from any nonreflexive space finitely representable in .
A Banach space is superreflexive exactly when the distortions of the finite diamond graphs tend to infinity. A uniformly separated convex-block sequence recursively realizes all branches of with bounded distortion, while uniform convexity forces quantitative collapse across repeated diamonds.
Every metric space with points admits an embedding into a Hilbert space with distortion . The usual random-subset construction gives an embedding into Euclidean dimension .
Fix a point in a metric space . The Fréchet embedding sends to the bounded function in . The triangle inequality bounds each coordinate by and gives . Taking gives equality, so the map is an isometric embedding. For a separable metric space a countable dense set of anchors suffices. Finite collections of distances to selected subsets instead give one-Lipschitz coordinates that need not be an exact Fréchet embedding.
For every integer , every -point metric space embeds into with distortion at most andThe coordinates are distance-to-subset functions. Randomly sampled subsets at density scales separate every pair at one scale; a union bound leaves the stated number of coordinates.
If a fixed-degree expander on vertices embeds into with distortion , thenIndeed, has distortion , while . Taking gives .
For and any points in a Hilbert space, there is a linear map into Euclidean dimension that multiplies every pairwise distance by a factor between and .
The striking feature is that the target dimension depends on the number of points and the allowed error, independently of the ambient dimension. Fix a finite set , with , and . An equivalent sufficient statement uses squared Euclidean distances: a linear map exists, with , such thatThe finite-set theorem cited here supplies an explicit sufficient target dimension for this squared-distance formulation. [ref]
An elementary proof of a theorem of Johnson and Lindenstrauss by Sanjoy Dasgupta and Anupam Gupta. An elementary proof of a theorem of Johnson and Lindenstrauss, Theorem 2.1, p. 61: bounds for squared distances
Taking square roots gives distance factors and , which lie inside . Conversely, bounds on distances only give squared-distance bounds ; the same numerical tolerance should not be silently used for both. Under the squared-distance bounds, the bi-Lipschitz distortion is at most .
The Johnson–Lindenstrauss lemma preserves this fixed finite set, rather than every vector in the ambient Euclidean space. A linear map with has a nonzero kernel by the rank-nullity theorem, so some nonzero vectors collapse completely. For finitely many points in a real Hilbert space, apply the finite-dimensional argument on their linear span and extend by orthogonal projection onto that linear span. If the sufficient target dimension exceeds the ambient dimension, the identity map already preserves every Euclidean distance exactly, with zero padding if a larger target is requested.
Draw a random matrix whose entries are independent random variables with the standard normal distribution, and setThe factor makes the expected value of the squared L2 norm equal to the original squared L2 norm. This Gaussian Johnson–Lindenstrauss transform is a linear map, generally not an orthogonal projection: its rows are not required to be orthogonal vectors. [ref]
Lecture notes on metric embeddings by Jiří Matoušek. Lecture notes on metric embeddings, §2.1(b), p. 21, and Lemma 2.3.1, p. 24: independent Gaussian coefficients and normalization
For the fixed finite set , let be an allowed failure probability, and defineWith denoting the natural logarithm, a sufficient integer target dimension isThen one draw of this specified random matrix satisfies all the squared Euclidean distance bounds simultaneously with probability at least . Since , the simpler sufficient bound also works. Both are sufficient bounds for this argument; they do not claim the smallest possible target dimension.
This is a probability statement about a map drawn independently of the fixed finite set. It implies existence because the success probability is positive, but permits failed draws. The set cannot be chosen after inspecting the map with this same guarantee. In particular, no single draw preserves every possible finite set in the ambient Euclidean space when .
Here is an original reproducible finite set with 40 points and 512 coordinates. Let be the first four vectors of the standard basis of . With point indices , generateThe four groups have different centers, and the standard normal random variables perturb all 512 coordinates. Generate the coordinates in row order using NumPy's PCG64 pseudorandom number generator with seed 20261013. Then keep this finite set fixed. A second PCG64 stream with seed 424242 generates a matrix of independent random variables with the standard normal distribution; divide it by to obtain the Gaussian Johnson–Lindenstrauss transform.
For all 780 unordered pairs, compute the distance ratio . In this draw, its minimum is approximately and its maximum , giving a maximum relative error in Euclidean distance of about . The squared-distance ratios instead range from approximately to : their maximum relative error is about . Thus this particular draw fails a 20% distance tolerance. The Johnson–Lindenstrauss lemma does not assert that every draw into 32 dimensions must succeed.
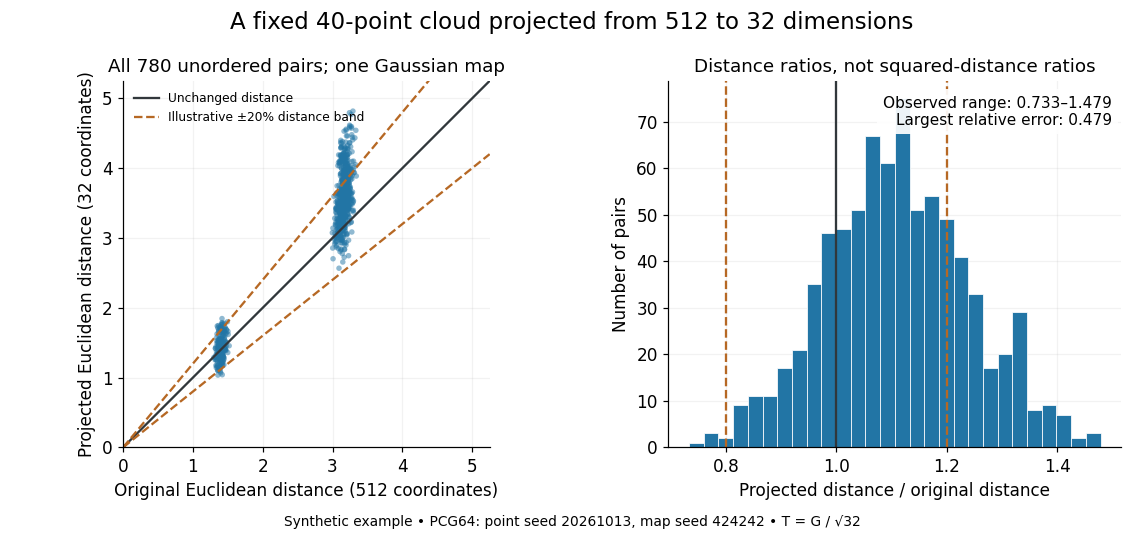
The two bands of original Euclidean distances distinguish pairs within a group from pairs between groups. Their spread after the linear map shows why checking an average distance is insufficient: the Johnson–Lindenstrauss lemma controls every pair. The dashed 20% distance band is an illustrative tolerance, not a confidence interval or a squared-distance band. The affine hull of 40 points has dimension at most 39; 512 is the ambient coordinate count, and no full-dimensionality assumption is required. For this draw the bi-Lipschitz distortion is approximately .
Now keep the same points and draw 48 fresh Gaussian Johnson–Lindenstrauss transforms for each target dimension . NumPy's
SeedSequence(314159).spawn(240) supplies distinct PCG64 streams, ordered first by target dimension, then by draw. Each stream generates a new random matrix, normalized by ; no map is a row prefix of another map. Each plotted value is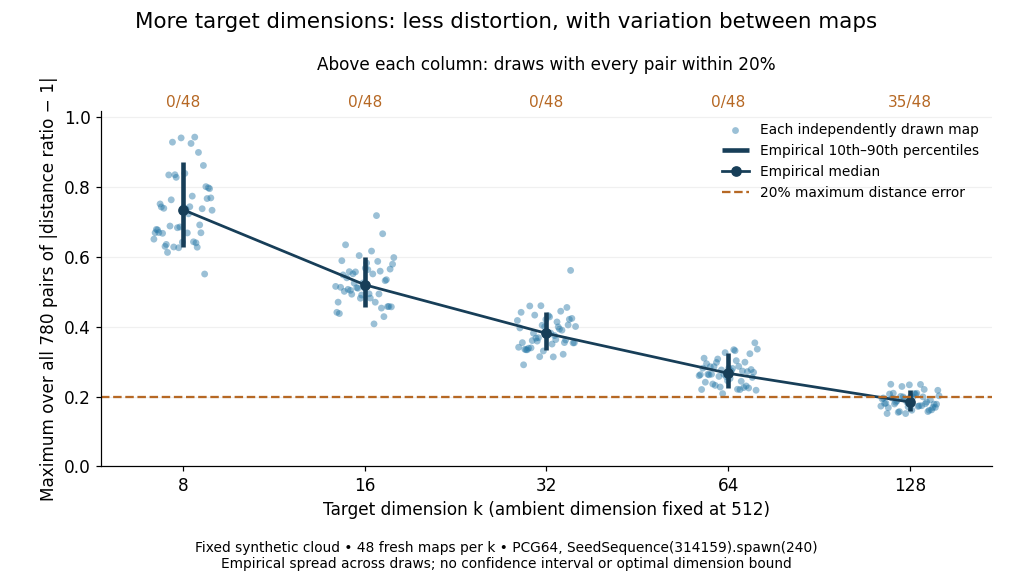
The observed median maximum relative errors in Euclidean distance are approximately , , , , and , respectively. All pairs fall inside the 20% distance tolerance in , , , , and of the 48 draws, respectively. These are computations on one synthetic finite set, rather than optimal dimension bounds or measured physical data. The displayed quantiles describe the sampled maps; they do not certify a success probability for other sets. Even at 128 dimensions, 13 of the sampled maps fail this tolerance.
The practical benefit is that each point acquires fewer coordinates while its pairwise Euclidean distances can remain useful. The choice of target dimension balances compression, accuracy, and failure probability. For example, a conservative sufficient squared-distance tolerance with and gives by the explicit bound above. Here that exceeds the ambient dimension, so the identity map is better for a certified guarantee. The much smaller dimensions in the plots illustrate observed behavior without claiming that this sufficient bound is sharp.
A short concentration inequality argument explains the bound. For a fixed nonzero vector , the normalized row products are independent random variables with the standard normal distribution, soUse the moment-generating function of a chi-squared distribution and the Chernoff bound to obtainFor , elementary logarithm inequalities bound their sum by . Apply the union bound to the nonzero pair differences to get failure probability at most . Independence of different pairs is unnecessary; they use the same map. This combines fixed-vector concentration with a finite-set union bound. [ref]
Lecture notes on metric embeddings by Jiří Matoušek. Lecture notes on metric embeddings, §2.1, pp. 20–21, and proof of Lemma 2.3.1, pp. 25–26: fixed-vector concentration and union bound over pair differences
The unit sphere of an -dimensional normed space has a -net of size at most . If on this net and , then
If has independent Rademacher entries, then for fixed and ,Applying a union bound to all pairwise differences embeds fixed points into dimension while preserving every squared distance within a factor with probability at least .
For a standard normal variable and ,The exponential Markov inequality consequently gives Gaussian concentration for averages of independent copies of .
The random matrixsatisfiesA net argument shows that permits a linear embedding of distortion below .
Every -point metric space embeds into with distortion . Apply the Bourgain embedding theorem, reduce its Euclidean dimension to with the Johnson–Lindenstrauss lemma, and use an Almost-isometric Gaussian embedding from l2 into l1.
On continuous functions , the exponentially weighted supremum norm is . It is equivalent to the ordinary supremum norm and often turns a Volterra integral map into a contraction mapping.
An operator topology specifies convergence of linear operators. Common choices include the norm, strong, and weak operator topologies.
This topology on bounded operators is generated by the seminorms . A net converges exactly when both it and its adjoint net converge in the strong operator topology. It is the topology used in the full-unit-ball version of the Kaplansky density theorem.
For a Hilbert space , the linear span of the matrix-coefficient functionals is a predual of . The unit ball is compact in the resulting weak operator topology by the Tychonoff theorem, and the compact norming dual-pair criterion identifies with the dual of that span.
A Schauder basis of a Banach space is a sequence such that every has a unique norm-convergent expansion .
For a countable minimal total family in a normed space in a Banach space, let be its unique biorthogonal system and let . Uniform boundedness of these projections implies for every : approximate by a finite linear combination , eventually fixed by , and bound the error by . Conversely, if every vector has a norm-convergent expansion in this family, applying each continuous shows that its coefficients must be . Thus , so the projections are pointwise bounded. The Uniform boundedness principle gives their uniform operator-norm bound. This proves the criterion and uniqueness of all expansions.
Relative to a Schauder basis , a block basic sequence consists of nonzero finite combinations supported on successive disjoint coordinate intervals. In the l-p sequence space, disjointly supported vectors of norm one satisfy . Their closed span is consequently isometric to the l-p sequence space.
Suppose is a normalized block basic sequence in the l-p sequence space, , and . Choose norm-one linear functionals supported on the respective blocks with . The bounded linear operator is invertible by the Neumann series. The block projection has norm at most one, and projects onto the closed span of . Thus that span is a complemented subspace isomorphic to the l-p sequence space.
Relative to a Schauder basis, a block sequence consists of nonzero finitely supported vectors with successive disjoint supports: . It is a basic sequence, with basis constant at most that of the original basis.
A block subspace is the closed linear span of an infinite block sequence. Passing to a block subspace preserves the order of supports and permits successive-vector constructions.
If an analytic family of finite normalized block sequences meets every infinite-dimensional block subspace, then after an arbitrarily prescribed coordinatewise perturbation it is strategically large in some block subspace. In the block game, one player chooses an infinite-dimensional block subspace at each turn and the other chooses a successive unit vector from it; strategically large means the vector player can force a finite initial segment into the family.
The basis constant of a Schauder basis is , where are its basis projections. Uniform boundedness makes this supremum finite.
The dual sequence consists of the coordinate functionals in . It is always a basic sequence, though it need not span the entire dual space.
A Schauder basis is shrinking when its dual sequence is a Schauder basis of the whole dual space. Every Schauder basis of a reflexive Banach space is shrinking.
A basic sequence in a Banach space is a sequence that is a Schauder basis for its closed linear span.
Every bounded sequence in a Banach space has either a weakly Cauchy sequence as a subsequence or a subsequence equivalent to the unit vector basis of . The real-scalar proof represents vectors as continuous functions on a compact dual ball and uses infinite Ramsey theory to select independent lower and upper level sets when pointwise convergence cannot be obtained.
For , let consist of finite normalized sequences satisfying for every scalar combination. Its tree order measures the depth of finite copies of the unit vector basis of . A separable Banach space containing no copy of has a countable index because every such tree is closed and well-founded. Countable well-founded trees can be used to construct separable reflexive spaces with arbitrarily high index, precluding a separable reflexive universal space.
An unconditional basic sequence is a Schauder basis for its closed span whose expansions converge after arbitrary permutations or coordinate suppressions. Equivalently, the finite coordinate projections are uniformly bounded. Failure of this property gives pairs of disjointly supported unit vectors at arbitrarily small distance, obtained by separating a finite combination with a large coordinate projection.
Let consist of finite normalized sequences for which every scalar combination and sign change satisfy . These inequalities give a closed tree on a Polish space when is separable. An infinite branch is an unconditional basic sequence. If there is no such sequence, each fixed-constant tree is well-founded and has countable rank of a well-founded tree. Consequently, finite unconditional configurations with one fixed constant and arbitrarily high countable ranks force an infinite unconditional sequence.
A basic sequence is suppression-unconditional with constant if every coordinate deletion satisfies the displayed inequality. When , deletion never increases the norm. Uniformly bounded finite-coordinate projections imply unconditional convergence of the basis expansions; for real scalars, the sign-change constant is at most .
A normalized basic sequence generates a spreading model when the norms of all finite scalar combinations converge as the first index tends to infinity, uniformly over increasing choices of the indices. The limiting norm on finitely supported scalar sequences is unchanged by increasing relabellings of coordinates. Completing this norm gives a Banach space with its canonical basic sequence. A diagonal application of the finite-colour infinite Ramsey theorem produces such a model from a subsequence of every normalized basic sequence.
If a bounded subset of a Banach space is bounded away from zero and zero lies in its weak closure, then contains a basic sequence. More generally, weak closure may be replaced by closure in any Hausdorff locally convex vector topology weaker than the weak topology.
A locally convex topological vector space is reflexive when its canonical evaluation map to its continuous bidual is an isomorphism with the specified strong dual topologies. For a Banach space, this reduces to surjectivity of the canonical map and gives a reflexive Banach space.
A Banach space is reflexive when its canonical embedding is surjective. Equivalently, its closed unit ball is weakly compact.
If is a Banach space and is a norm-closed reflexive linear subspace of , evaluation gives the displayed surjection. Restriction is weak-star continuous and maps the closed unit ball onto the target ball by the Hahn-Banach theorem. The Goldstine theorem then makes weak-star dense in , where . Reflexivity of makes this target weak-star topology equal to its weak topology. Convexity and the Hahn-Banach separation theorem convert weak density of this ball image to norm density.
To pass from density to surjectivity, approximate a desired by with and residual at most . Repeat on each residual. The chosen vectors have summable norms, with sum at most , and the residuals tend to zero geometrically. Completeness of produces with . Using any smaller residual ratio proves the infimum lifting norm equals , although that infimum need not be attained. This argument proves onto-ness, rather than merely density of the evaluation functionals.
A nonempty norm-closed convex subset of a reflexive Banach space attains its distance to zero. For , the sets are nonempty weakly closed subsets of one weakly compact ball, and form a decreasing family. Compactness gives a point in their intersection, of norm . Mazur theorem supplies weak closedness of and the balls; no sequential-compactness theorem is required.
A Banach space is reflexive if and only if its closed unit ball is compact in the weak topology. One direction applies the Banach-Alaoglu theorem to the unit ball in the bidual; the converse follows because Goldstine theorem makes the canonical image of the unit ball weak-star dense, while weak compactness makes that image weak-star closed.
Every bounded sequence in a Hilbert space has a weakly convergent subsequence. The closed span of a sequence is separable; diagonal convergence of coordinates along an orthonormal basis gives a bounded limiting linear functional, represented by a vector of the Hilbert space. Applied to a bounded family of mollifications, this proves that their strong Lebesgue limit inherits the weak derivative bound.
Every bounded sequence in a reflexive Banach space has a weakly convergent subsequence. This is the sequential form of weak compactness supplied by the Eberlein-Šmulian theorem.
A Banach star-algebra is a complex Banach algebra equipped with a continuous algebra involution. Thus the involution is conjugate-linear, reverses products, and squares to the identity. Some conventions additionally require ; this is the isometric convention. In the unital case the involution fixes the unit. The C-star identity is a stronger additional condition. The algebra of continuous complex-valued functions on a compact Hausdorff space, with pointwise operations, complex conjugation and the supremum norm, satisfies both the isometric condition and the C-star identity.
A Banach algebra is semisimple when its Jacobson radical is zero. This does not assert that every quasinilpotent element is zero. For example, the algebra of bounded operators on a Banach space of dimension greater than one is semisimple, but contains nonzero square-zero rank-one operators. This notion also does not require the finite-dimensional direct-sum decomposition associated with a semisimple algebra.
An algebra homomorphism onto a semisimple Banach algebra is continuous. To see the spectral mechanism, suppose and . For any , choose with and , and set , . Apply the spectral-radius three-circle inequality to . On the outer circle its norm tends uniformly to ; on the circle of radius its spectral radius is bounded by . Hence for every , so . The unit criterion for the Jacobson radical gives , and the closed graph theorem finishes the proof.
Truncated convolution makes a commutative nonunital Banach algebra. The Tonelli theorem gives , and the Fubini theorem gives associativity over the integration simplex. Its unitization is with norm and product . The constant function one has convolution powers , of norm . Thus it is a nonnilpotent quasinilpotent element in this unitization.
If an associative unital algebra has a complete norm and separately continuous multiplication, the Uniform boundedness principle applied to , for , yields . The operator norm of then defines an equivalent algebra norm: , and proves submultiplicativity. It normalizes the identity to norm one.
A Hermitian Banach algebra is a Banach algebra with an algebra involution for which every Hermitian element of a star algebra has real spectrum of an element. A closed unital star-subalgebra has spectral permanence for Hermitian Banach algebras. The assumption is weaker than being a C-star algebra and does not require the C-star norm identity.
Let be a closed star-subalgebra of a unital Hermitian Banach algebra , containing the same identity. For Hermitian , the complement of is connected. The resolvent belongs to at large modulus by the Neumann series; its membership in is both open and closed in that complement, so . If is invertible in , both and are invertible there and Hermitian algebra elements, hence invertible in . Their inverses supply respectively a right and a left inverse for in , proving invertibility there. Applying this to proves the spectrum equality.
With left Haar measure, makes a Banach algebra, since . For an Abelian group it is commutative, and the involution is . Its nonzero characters of an algebra are exactly integration against inverses of continuous unitary group characters.
// Target: geometry-and-topology.bigb
Every character of an algebra on with convolution multiplication is uniquely of this form for . If is the point mass at , then . A character has norm one and , so and . Hence lies on the unit circle; multiplication determines all and continuity determines the displayed series. Conversely absolute convergence permits rearrangement of the double series, proving multiplicativity. The maximal ideals are exactly their kernels: each consists of sequences whose Fourier series vanishes at one fixed point of the unit circle.
For a locally compact Hausdorff Abelian group, each continuous unitary character defines an algebra character by . Conversely, if is a nonzero algebra character and , the ratio is independent of , continuous and multiplicative. Translation isometries bound all its integer powers, so its modulus is one. The convolution formula recovers . The Gelfand topology corresponds to the compact-open topology on the Pontryagin dual group; conjugating the characters gives the alternative Fourier sign convention.
Articles were limited to the first 100 out of 1025 total.
Articles by others on the same topic



Functional analysis is a branch of mathematical analysis that deals with function spaces and the study of linear operators acting on these spaces. It is a subfield of both mathematics and applied mathematics and is particularly important in areas such as differential equations, quantum mechanics, and optimization.