Linear operator theory studies linear maps, their spectra, invariant subspaces, and normal forms such as Jordan normal form. In a finite-dimensional vector space, eigenvalues identify parameters for which a shifted linear operator cannot be inverted. In an infinite-dimensional vector space, inversion can fail even without an eigenvector. The spectrum of a bounded operator captures this larger obstruction and connects linear algebra with the approximation questions of functional analysis.
An annihilating polynomial of a linear operator is a nonzero polynomial for which the displayed operator is zero. The minimal polynomial is its unique monic annihilating polynomial of least degree and divides every other annihilating polynomial. For a diagonalizable operator with distinct eigenvalues , the product annihilates it. For an individual vector it suffices to annihilate the eigenvalues contributing to that vector; this gives exact finite-step termination bounds for a Krylov subspace method.
For distinct scalars , the Lagrange interpolation polynomials sum to one. Their values at have images in the respective eigenspaces, since is a multiple of the annihilating polynomial. Hence every vector is the sum of its images. On the th eigenspace, is multiplication by , which proves directness. This gives the decomposition without invoking the primary decomposition theorem. Under this decomposition a linear operator commutes with exactly when it preserves every eigenspace.
The differentiation operator sends a differentiable function to its derivative; its domain and the norms must be specified. On with values in , using the supremum norm on both, it is an unbounded linear operator: satisfies and . Its graph norm is , which is complete. Indeed, the kernel consists of constants and is complete, while is a bounded right inverse by the fundamental theorem of calculus; apply completeness of a graph norm from a bounded right inverse.
For a bounded linear operator, the series converges in operator norm. For an unbounded self-adjoint operator , the spectral theorem instead defines the bounded unitary operator by applying the scalar function to its projection-valued measure. This yields unitary time evolution without assuming that every vector lies in the domain of every power of . In finite dimensions it is the matrix exponential.
For a bounded skew-adjoint operator on a complex Hilbert space, the operator exponential converges in norm because its term norms are bounded by . Continuity of the adjoint operator gives . Absolute convergence permits the Cauchy product of and : its degree- coefficient is , zero for and the identity for . Both multiplication orders therefore give the identity, proving unitarity. The boundedness hypothesis makes this elementary power-series proof valid without domain issues for unbounded generators.
For bounded linear operators, define . The product rule gives and . Multiplying by the integrating factor yieldsThe identity is useful when the two linear operators do not commute: it preserves their order rather than incorrectly differentiating an operator exponential as if all its factors were scalars. For unbounded linear operators, the products and differentiations need a common justified operator domain.
For a bounded operator on a Hilbert space, set . There is a unique partial isometry , zero on , satisfying ; on the range of , define and extend by continuity. This is well-defined and isometric because . For an invertible square matrix, is unitary.
A shift operator translates the components of a function or sequence by a fixed displacement. Bilateral shifts act on doubly infinite sequences; the unilateral shift operator acts on a one-sided sequence space and has distinct forward and backward versions.
The unilateral shifts on sequences move every component one place left or right. Their spectra illustrate behavior absent in finite dimensions.
On the absolutely summable sequence space, this weighted shift has , so . The spectral radius formula gives radius zero. Its spectrum is exactly because it is not onto, while it has no eigenvalues: zero is excluded by injectivity, and any nonzero eigenvalue equation forces all coordinates to vanish starting at the first. Thus it is a nonzero quasinilpotent element of the operator algebra.
On , the unilateral shift operator and left shift operator satisfy and , while has nontrivial kernel. If , the Neumann series makes invertible. Were invertible, this identity would express as a product of invertible operators, a contradiction. Thus the open unit ball about contains no invertible operator.
On the Hilbert space , the left shift deletes the first coordinate. It is the adjoint operator of the unilateral shift operator . The identities and show that it is also the Moore–Penrose inverse of an operator for ; both maps have operator norm one.
An operator is a unilateral shift exactly when it is an isometry, is one-dimensional, and . A unit vector in the first orthogonal complement is wandering, and is a complete orthonormal basis.
A solvability condition is a compatibility requirement on data for an equation to admit a solution in a specified function space or with specified boundary behavior. For a bounded linear operator between Hilbert spaces, the equation requires to be orthogonal to the kernel of the adjoint. A closed range makes that requirement sufficient; the Fredholm alternative for a compact operator applies this principle to with compact . in an asymptotic inner problem, exclusion of a growing homogeneous mode can impose an analogous weighted-integral condition.
The spectrum of a linear operator consists of the scalars for which is not invertible. In finite dimensions it is the set of eigenvalues.
Let be a bounded linear operator on a complex Banach space with , and . Its image of a linear map and kernel contain nonzero vectors, giving eigenvalues one and zero. For ,Direct multiplication proves the formula, so the spectrum is exactly and its spectral radius is one. Since and , the spectral radius formula is explicit: .
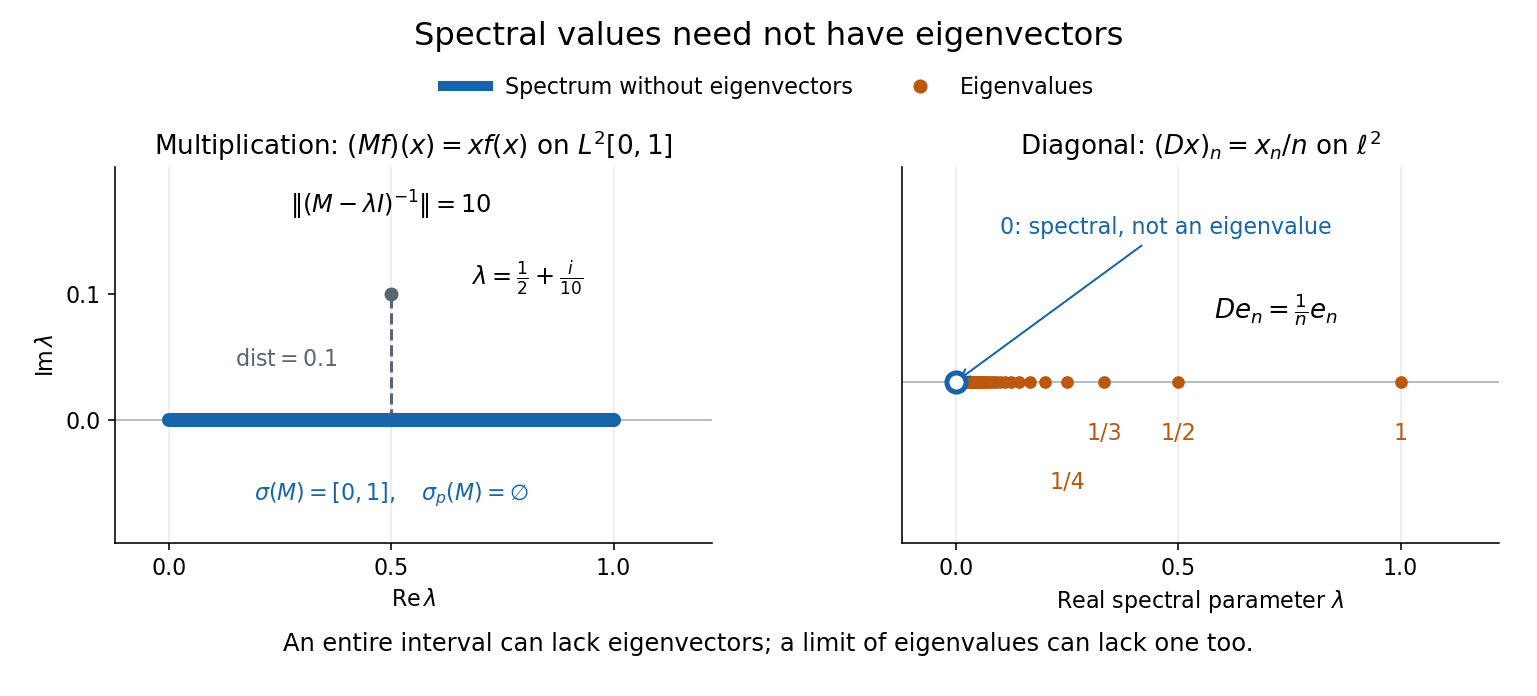
For a bounded linear operator on a complex Banach space, the point spectrum is precisely its set of eigenvalues:Here is the identity operator. Thus membership requires an actual nonzero eigenvector, whereas the spectrum of a bounded operator only requires failure of a bounded inverse. Every eigenvalue belongs to the spectrum, but the inclusion can be strict. The multiplication operator discussed below has an entire interval in its spectrum and empty point spectrum.[ref]
https://www.math.hkust.edu.hk/~makyli/4063/fanotes2_150615.pdf#page=38. HKUST Math 4063 notes, chapter 4, section 3: spectrum and point spectrum
An approximate eigenvalue of a bounded operator is a scalar admitting unit vectors with . Every approximate eigenvalue belongs to the spectrum; for a normal operator, all spectral points are approximate eigenvalues.
The unit vectors realizing an approximate eigenvalue are approximate eigenvectors: their residual tends to zero, although they need not converge to any genuine eigenvector.
In the disjoint convention for a bounded linear operator , the residual spectrum consists of for which is injective but has nondense range. Together with the point spectrum and continuous spectrum it partitions the spectrum of a bounded operator. Some conventions also include noninjective operators with nondense range, so the convention must be stated.
For a self-adjoint operator , a real number lies in the continuous spectrum when is injective with dense range but is not surjective. Such spectral values need not be eigenvalues of normalizable states. The free-particle Hamiltonian on the real line has a continuous energy spectrum.
Let be a Banach space over the complex numbers, and let be a bounded linear operator defined on all of . Its spectrum consists of those for which has no everywhere-defined bounded inverse. Its complement is the resolvent set of an operator . By the bounded inverse theorem, a bijective automatically has a bounded inverse. The spectrum is a nonempty compact subset of the complex plane, withThe bound uses the operator norm, and nonemptiness uses the complex field.[ref]
https://www.math.hkust.edu.hk/~makyli/4063/fanotes2_150615.pdf#page=38. HKUST Math 4063 notes, chapter 4, section 3: compactness and nonemptiness of the spectrum
For a real linear operator, complex spectral values are understood by extending it to a complex vector space; restricting to the real field can give an empty set.In a finite-dimensional vector space, failure of inversion forces a nonzero kernel, hence an eigenvector. An infinite-dimensional vector space allows an injective shifted linear operator that cannot solve every equation . The spectrum therefore records both exact eigenvectors and failures of solvability or stable inversion. Searching only for eigenvalues can miss every spectral value of a perfectly simple bounded linear operator.
Consider the multiplication operator on the complex L2 space , with Lebesgue measure:Its operator norm is one. The inequality gives the upper bound; unit vectors concentrated near approach it. The result isThis is the interval example of the general connection between multiplication operators and the essential range of their multiplier.[ref]
https://hackmd.io/@knikct/BkX1s2PFr. Berkeley Math 224A, lecture 13: spectra of multiplication operators
Indeed, an eigenfunction would satisfy almost everywhere. It vanishes except possibly on the singleton , a null set; such a function is the zero vector in L2 space. Concentrating at one point cannot produce a nonzero L2 function.For , the inverse is completely explicit:The distance to a set is positive, so the inverse multiplier is bounded. Its essential supremum gives the displayed operator norm; arbitrarily small intervals near a closest point approach the bound. Our resolvent of an operator uses , the negative of this inverse, with the same operator norm. For , , and , the inverse norms are respectively , , and . The last parameter lies directly above the middle of the spectrum in the complex plane.
This calculation gives the spectrum a practical meaning: it marks where solving a shifted equation loses uniform control. At , the largest amplification of an input error is . Changing from to increases that factor from ten to one hundred. The equation remains uniquely solvable for each nonzero , but its sensitivity grows as the parameter approaches the spectrum.
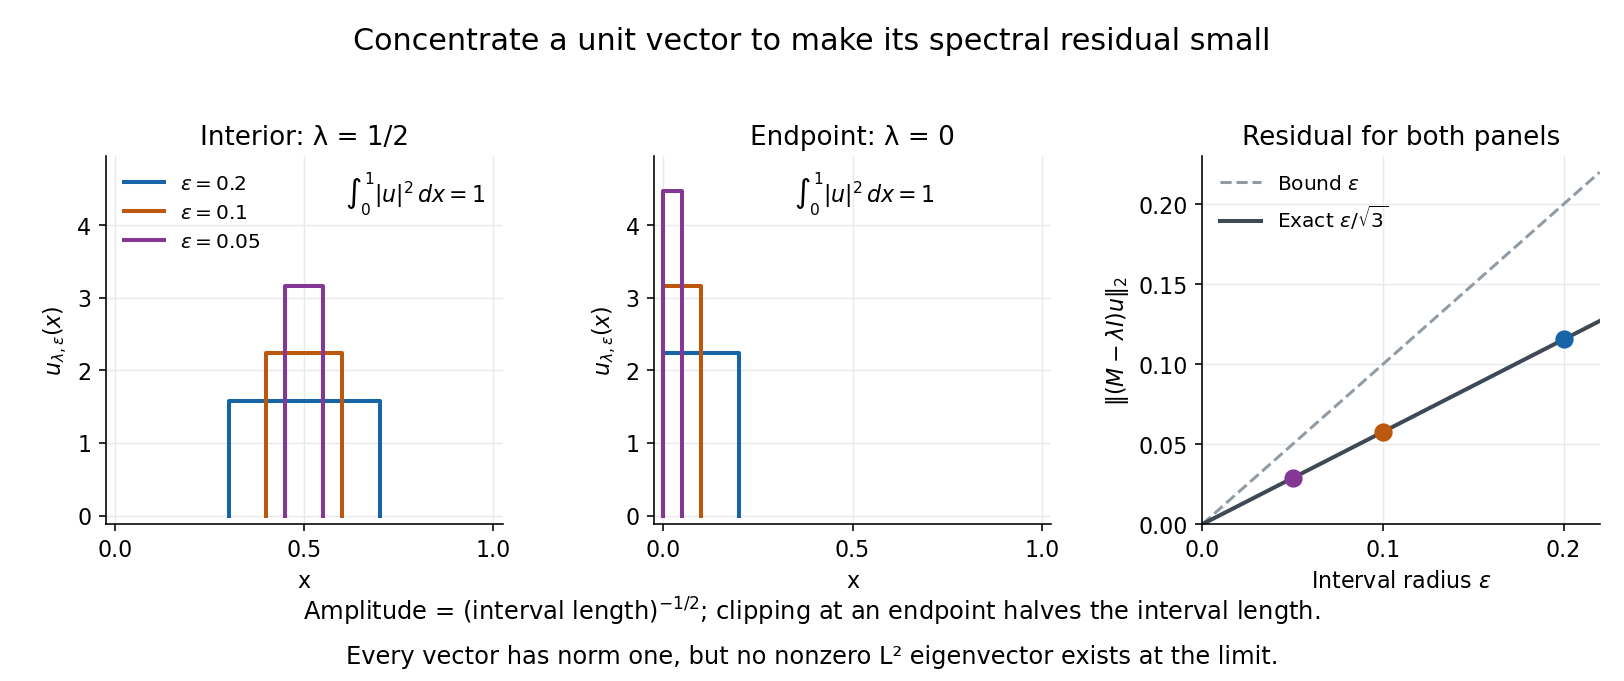
To see directly why every belongs to the spectrum, choose and define a clipped interval and a normalized indicator function:Its L2 norm is exactly one, including at both endpoints. On its support, , givingThus any choice produces approximate eigenvectors. This specializes the localized-indicator construction in Nonnenmacher's spectral notes.[ref]
https://www.imo.universite-paris-saclay.fr/~nonnenma/enseign/Spectral%20Theory%202021%20chap1-4.pdf#page=47. Nonnenmacher, Introduction to Spectral Theory (2021), proposition 4.2.15
A hypothetical bounded inverse would imply , impossible for arbitrarily small .For an interior point with , and the residual is exactly . At or , and the same residual formula holds, but the amplitude is rather than . At , taking gives amplitudes approximately and residuals . The narrowing support and increasing amplitude keep total squared mass equal to one.
For every , the continuous spectrum description is also concrete. Any L2 function can be approximated in L2 norm by its truncations to . Each truncation lies in the range of , since division there is bounded. The range is therefore dense. However, the constant function has no L2 function preimage: is not square-integrable, including at the endpoints.
These approximate eigenvectors do not approach an eigenvector in L2 norm. Any possible limit would have L2 norm one and satisfy by continuity, contradicting the empty point spectrum. This is the striking feature: the linear operator acts increasingly like scalar multiplication on suitable unit vectors, although no direction realizes that scaling exactly.


A complementary example is the diagonal operator on sequence space on complex l2 sequence space, with . The coordinate unit vectors satisfy , soZero is not an eigenvalue, since forces every coordinate to vanish. Nevertheless : these are approximate eigenvectors at zero. More concretely, belongs to l2 sequence space, but would require for all , which does not. Outside the displayed closed set, division by is uniformly bounded, proving that no further spectral values occur. Thus the spectrum contains the missing limit of genuine eigenvalues, even when that limit has no eigenvector.
If is a subspace of a space with an inner product and is its orthogonal projection, the compression of an operator to isIf the columns of are an orthonormal basis of , its matrix in that basis is .
A densely defined operator on a Hilbert space is self-adjoint when it equals its adjoint operator, including equality of their operator domains:For a bounded linear operator defined on the whole Hilbert space, this is equivalent tofor all vectors . For an unbounded self-adjoint operator, the domain condition is essential: the inner-product identity on alone gives only a symmetric operator.
Let on a Hilbert space, with time-independent self-adjoint operator , and conserved quadratic energy . If , set with and . This gives . For , and , soby the Cauchy-Schwarz inequality. Since , . Positivity of follows from and . Thus a negative direction of the restoring energy yields an exponentially growing solution without a normal-mode expansion or a variational spectral theorem. If is positive definite, conserved instead controls the energy norm; a bound in the original Hilbert space norm additionally follows from a coercive lower bound on .
A densely defined semibounded symmetric operator on a Hilbert space has a canonical semibounded extension that is a self-adjoint operator obtained by closing its quadratic form. After shifting the lower bound to zero, complete the initial form domain in the norm ; the associated closed form determines the Friedrichs extension. For the positive Laplace-Beltrami operator on a polygonal surface, this specifies the finite-energy realization at corners. Different choices of the initial form domain impose Dirichlet boundary conditions, Neumann boundary conditions, or mixed boundary conditions; the extension does not choose the boundary condition independently of that domain.
For a bounded self-adjoint operator , a spectral Weyl sequence at consists of unit vectors with . Such a sequence exists exactly at points of the spectrum of a bounded operator. If no sequence exists, the shifted operator is bounded below, with closed range and zero kernel. Self-adjointness then makes its range dense, so it is invertible. This spectral criterion is different from the equidistribution Weyl criterion.
A singular Weyl sequence for a bounded self-adjoint operator at is a spectral Weyl sequence that also converges weakly to zero. Such a sequence exists exactly when is in the essential spectrum of a bounded self-adjoint operator. An infinite-dimensional shifted kernel gives a weakly null orthonormal sequence. If that kernel is finite-dimensional but the shifted range is not closed, choose approximate null vectors in the kernel complement and extract a weakly convergent subsequence; its limit belongs to both kernel and complement, so is zero.
A densely defined linear operator on a complex Hilbert space is self-adjoint when its adjoint operator has exactly the same domain and agrees there. Symmetry only requires and does not guarantee self-adjointness. A self-adjoint operator is a closed operator with real spectrum. Domains matter for differential operators and unbounded multiplication operators.
Positivity makes bounded below with dense closed range for every , excluding negative spectral values. Conversely if the spectrum is nonnegative, has spectrum in by the resolvent spectral mapping identity. The numerical-range endpoint approximate-eigenvalue theorem gives , and positive-form Cauchy-Schwarz inequality gives . For , .
Symmetry gives when is nonreal. Closedness makes the range closed; its orthogonal complement is , so it is also dense and hence surjective. This proves the resolvent estimate and reality of the spectrum. Equality of the adjoint domains is needed in the range argument.
For a self-adjoint operator , solving requires to be orthogonal to every , because . When the range is closed, this condition is also sufficient: and closedness gives . In finite dimensions the range is automatically closed. This Fredholm solvability condition determines amplitude equations by projecting perturbative forcing onto critical eigenfunctions.
A self-adjoint operator is positive definite when for every nonzero vector in its domain. In finite dimension it is invertible and has positive eigenvalues. In infinite dimension, strict positivity of individual quadratic-form values need not give a bounded inverse; the stronger uniform bound with supplies coercivity.
For maps and between finite-dimensional inner product spaces, with , the operator is positive definite. Its quadratic form is , whose zero set is . This uses the adjoint operator relation .
On , the bounded self-adjoint operator is strictly positive. Yet lies in and would require the non-square-summable vector . A positive uniform lower bound, rather than strict positivity alone, guarantees a bounded inverse for a bounded self-adjoint operator.
Every self-adjoint operator on a finite-dimensional real or complex inner product space has an orthonormal eigenbasis, and all its eigenvalues are real. In orthonormal coordinates, a real symmetric matrix has the form , with an orthogonal matrix and a real diagonal matrix. A complex Hermitian matrix instead has , with a unitary matrix and its conjugate transpose. These are the self-adjoint cases of the spectral theorem; Axler gives the real and complex finite-dimensional statements in Section 7B.[ref]
https://linear.axler.net/LADR4e.pdf. Sheldon Axler, Linear Algebra Done Right, fourth edition, Section 7B, Theorems 7.29 and 7.31; accessed 2026-10-11
An orthonormal eigenbasis turns a seemingly coupled linear map into independent scalar multiplications while preserving lengths and angles. If and , thenThe last identity removes every cross term from the quadratic form. The eigenvalues tell us whether it is positive, negative, or mixed in sign, and the eigenvectors identify the corresponding directions. This connects positive-definite matrices, quadratic forms, and the Hermitian Rayleigh quotient range.
For a fully computed example, takeDirect multiplication gives and . Their dot product is zero and each has norm one. ThusWriting changes into . Its level set is therefore an ellipse with semiaxis lengths and , along and . The coordinates change, but the ellipse does not: orthogonal diagonalization reveals its existing geometry.
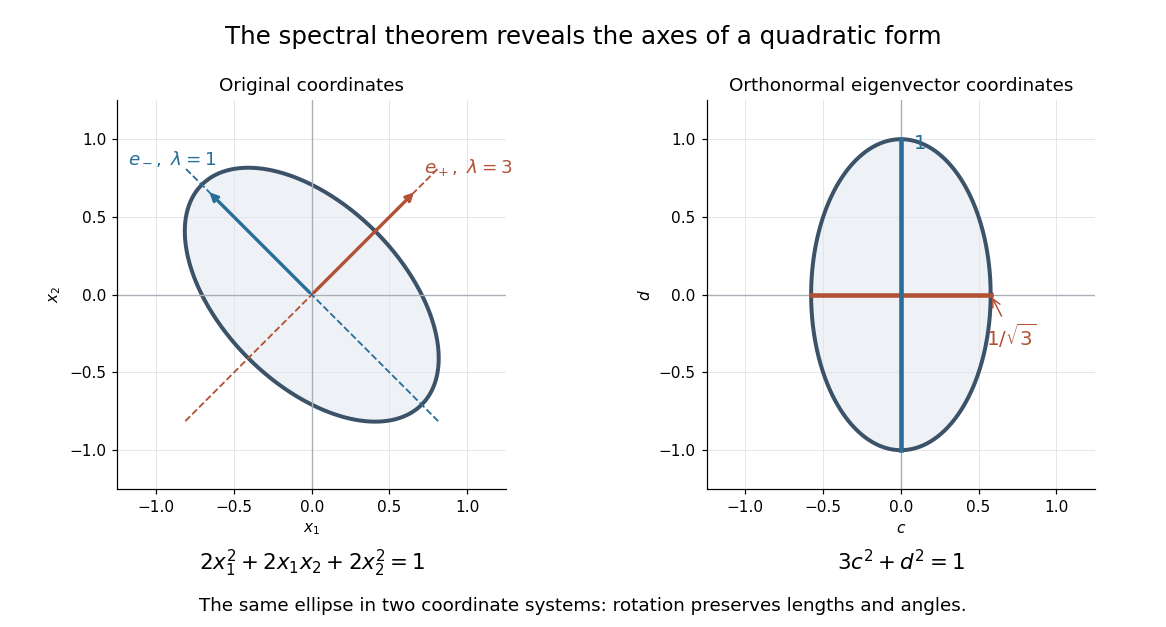
An orthonormal eigenbasis removes the cross term from a quadratic form and reveals the axes of its ellipse
. Details. 
For distinct eigenvalues, orthogonality follows at once from self-adjointness: . Within a repeated eigenspace, choose an orthonormal basis; arbitrarily chosen eigenvectors of the same eigenvalue need not be orthogonal. One outline of the full argument finds an eigenvector, observes that its orthogonal complement is invariant, and repeats in that smaller space. Merely having real eigenvalues is weaker: has two real eigenvalues, but its eigenvectors and are not orthogonal.
A Hermitian operator on a -dimensional Hilbert space, with distinct eigenvalues all belonging to , must occupy this entire grid. This follows from the pigeonhole principle: the set of possible values and the set of distinct eigenvalues have the same cardinality. Its minimum eigenvalue is zero, so the operator is necessarily singular. Distinctness therefore does not imply invertibility; it forces a one-dimensional kernel in this specific complete-grid setting.
An orthonormal eigenbasis of a linear operator is an orthonormal basis consisting of eigenvectors. Each vector can be reconstructed from its scalar components along those mutually perpendicular unit directions. With the convention that the inner product is linear in its first argument,The finite-dimensional spectral theorem supplies such a basis for a self-adjoint operator. In its two-dimensional example, the coordinates of are along and along . The operator multiplies those coordinates by and , and reconstruction gives .
Repeated eigenvalues permit different orthonormal choices within one eigenspace, so the basis need not be unique. The spectral projection of a self-adjoint matrix onto that entire eigenspace is unique: it keeps the geometrically meaningful component without choosing individual axes inside it.
For a finite-dimensional Hermitian matrix , its spectral projection is the orthogonal projection onto the eigenspace for . In an orthonormal eigenbasis, the displayed sum is over every basis vector with that eigenvalue. The projection is independent of the choice of basis within a repeated eigenspace. For distinct eigenvalues ,This is the spectral decomposition grouped by distinct eigenvalues: decompose a vector into orthogonal pieces, then scale each piece. For the matrix ,Thus and : the two pieces add back to . Squaring the matrix simply squares each scalar, , and similarly the matrix exponential is . Spectral projections of a self-adjoint matrix turn repeated matrix calculations into scalar calculations on fixed vector subspaces.
On polynomials with weighted inner productthe operatoris self-adjoint because . Its eigenvalues on polynomials of degree at most are ; its eigenvectors are scalar multiples of the Laguerre polynomials.
At eigenvalue zero the Laguerre differential operator on polynomials gives , equivalently . Thus and the displayed solutions follow from the exponential integral. For any , all solutions with can be written . The choices and are linearly independent despite sharing that one prescribed value.
The second branch grows as at infinity and has a logarithmic singularity at zero. It is consequently excluded from the regular weighted square-integrable eigenproblem with weight . Only the constant zero mode remains in that self-adjoint realization. A normalization at one interior point alone is not enough to select a unique second-order solution.
For polynomial solutions of the Laguerre differential equation, put . The equation gives . Integrating by parts gives the displayed identity; the factor kills the endpoint at zero and exponential decay kills the endpoint at infinity. Its left side is symmetric in , so subtracting the swapped identities proves orthogonality for distinct degrees. This provides a direct energy proof of orthogonality for the Laguerre polynomials without assuming their norm formula.
The ordinary Laguerre polynomials, normalized by , are orthonormal for the weighted inner product displayed above. Their coefficient formula is . To prove the relation, use Rodrigues' formula and integrate by parts times against . For its th derivative vanishes. At zero every derivative of of order less than vanishes, and at infinity the exponential kills every polynomial boundary term. For , , so the integral is . Symmetry covers . Thus these are orthonormal without an extra normalization factor.
The generating function holds for and fixed . From Rodrigues' formula, . Sum first over , using , and then over to obtain the exponential function. The absolute-value double series is finite for , justifying the rearrangement. Alternatively, the weighted inner product and the Laplace transform of a Laguerre polynomial extract the coefficient .
For the ordinary Laguerre polynomial , apply the Laplace transform to each term, using for . The binomial theorem givesThis proves the formula for every nonnegative integer . In particular has transform .
Set . Direct differentiation gives . Apply the Leibniz rule to differentiate times:Hence . By Rodrigues' formula, , so the next two derivatives are and . Substitution gives the displayed Laguerre differential operator on polynomials eigenvalue equation. This derivation also covers .
The Laguerre polynomial normalized by has coefficients . By the Leibniz rule, this is equivalent to Rodrigues' formula, . For any polynomial of degree below , applications of integration by parts give . All endpoint terms vanish: derivatives of of order below vanish at zero and decay at infinity. Since , the same calculation givesThus these orthogonal polynomials are already an orthonormal set for the weighted inner product with weight .
For integers , the standard Rodrigues' formula has the endpoint value and squared norm displayed above. The lowest-power term after differentiations is , giving the endpoint value after division by . For the norm, integrate by parts times against the same polynomial; its leading coefficient is , so the final derivative is . All boundary terms vanish and the remaining Gamma function integral is . Normalizing the value at zero to one divides the polynomial by and its squared norm by the square of that factor. Only when or do these normalizations already coincide.
The real case of the finite-dimensional spectral theorem says that a self-adjoint operator on a finite-dimensional real inner product space has a real orthonormal eigenbasis. In orthonormal coordinates this is the spectral theorem for real symmetric matrices, . The worked ellipse under finite-dimensional spectral theorem shows why both orthogonal diagonalization and orthogonality matter: the new coordinates separate the quadratic form into squares without distorting lengths or angles.
A real normal matrix need not have real eigenvalues. For example, the quarter-turn is an orthogonal matrix, but its characteristic polynomial is and its eigenvalues are . Over the complex numbers it has an orthonormal eigenbasis; over the real numbers it has no eigenvector. Self-adjointness supplies the reality conclusion in the real spectral theorem.
Iterate . For a self-adjoint operator with a unique dominant eigenvalue separated in modulus from the others, a starting vector that is nonorthogonal to its dominant eigenvector gives convergence of the eigendirection at the spectral-ratio rate. For a general diagonalizable matrix, the condition is a nonzero coefficient in the dominant component of its eigenbasis, detected by the corresponding left eigenvector; an ordinary dot product with the right eigenvector does not generally detect that coefficient.
The power method is power iteration; its convergence depends on the dominant spectral component of the starting vector.
For example, has dominant right eigenvector and a dominant left eigenvector . The starting vector has nonzero dot product with the right eigenvector, but : it stays forever in the eigenspace for the smaller eigenvalue . Its coefficient along the dominant direction is zero, as the left eigenvector detects. An orthonormal eigenbasis makes the two tests agree in the self-adjoint case.
When two independent iterates span an invariant two-dimensional subspace, their recurrence gives the characteristic polynomial . For distinct roots , corresponding eigenvectors are and . For a merely approximately dominant subspace, the same computation gives approximate eigenpairs. A single orbit cannot separate a repeated eigenvalue's entire eigenspace when its projection is only one direction.
For a real symmetric matrix with and a starting vector having nonzero component in the leading eigendirection, power-method direction errors arewhereas the Rayleigh quotient error isThe improvement occurs because orthogonality cancels terms linear in the direction error.
For a diagonalizable matrix, the active spectrum consists of eigenvalues whose eigenspaces have nonzero components of the starting vector in its spectral decomposition. These components are orthogonal projections for a self-adjoint operator, but need not be orthogonal projections for a general diagonalizable matrix. With a unique largest modulus in this active spectrum, the power method selects its eigendirection; an exactly absent dominant component is never created in exact arithmetic.
Inverse iteration repeatedly solves and normalizes. It is the power method for and converges toward an eigenvector whose eigenvalue is closest to the shift .
Suppose a diagonalizable matrix has a simple eigenvalue uniquely closest to a shift . If the starting vector has a nonzero coefficient in the target eigenbasis direction, fixed-shift inverse iteration converges to that eigenvector line. In fact, the eigenvalues of are , so after inverse applications, division by leaves the target eigenvector plusThis proves direction error in Big O notation. The multiplicative constant depends on the eigenbasis and starting coefficients, and no uniform reduction at the first step follows for a nonsymmetric matrix. Over the real numbers, produces alternating signs. A nonzero ordinary inner product with a right eigenvector is not generally the same as a nonzero coefficient in the eigenbasis; the latter is the required condition.
If is real symmetric, is not an eigenvalue, one eigenvalue is uniquely closest to , and the initial vector has a nonzero component in its eigenspace, fixed-shift inverse iteration converges to that eigenspace. Its asymptotic direction-error ratio iswhere is second closest to .
If the closest eigenvalue lies above the shift, the dominant eigenvalue of the inverse is positive and normalized iterates approach one fixed sign of its eigenvector. If , that inverse eigenvalue is negative, so the direction converges but consecutive normalized vectors alternate signs. At a shift exactly midway between two simple eigenvalues, the two inverse eigenvalues have equal modulus and opposite signs, so generic iterates alternate between two mixtures instead of selecting one eigenvector.
Subspace iteration repeatedly applies a matrix to several independent vectors and orthonormalizes them, converging to a dominant invariant subspace when a spectral gap separates the selected eigenvalue cluster.
A dominant invariant subspace is spanned by eigenvectors whose eigenvalue moduli exceed those outside the subspace.
When several eigenvalues share the largest modulus, normalized power iterates need not converge individually, but every limit lies in their joint invariant subspace.
For square matrices over a field,If is invertible, the products are similar matrices. In general, apply that case to and for all but finitely many , then use polynomial identity in .
For real matrices , is a real polynomial. If , it is not the zero polynomial, so some real satisfies .
Every square matrix over an algebraically closed field is similar to an upper-triangular matrix. Choose an eigenvector, extend it to a basis, and apply induction to the induced lower-right block.
A linear map on a finite-dimensional vector space over an algebraically closed field has both an upper triangular matrix and a lower triangular matrix in suitable bases. One proof uses invariant subspaces and annihilators to make the induction step entirely in the dual space.
Choose an eigenvector and let . The dual map preserves the annihilator of a vector subspace , of dimension one less. By induction, choose a basis of making the restriction upper triangular. Extend this to a basis of the whole dual space; its matrix remains upper triangular because is an invariant subspace. In the corresponding primal basis, the matrix is , which is lower triangular. Reversing the primal basis makes it upper triangular. Dimension zero and one start the induction. This also allows the original eigenvector to be the first vector of the resulting upper triangular basis.
Eigenvalue interlacing bounds the ordered eigenvalues of a compressed or rank-modified operator between those of the original operator.
Let a real symmetric matrix have ordered eigenvalues , with . If is obtained by deleting one matching row and column, its largest eigenvalue satisfiesThe Rayleigh quotient of is that of restricted to vectors whose deleted coordinate is zero. This gives the upper bound. Some nonzero linear combination of the top two orthonormal eigenvectors has that coordinate zero; normalizing it gives a quotient at least . The argument does not require distinct eigenvalues.
A Jordan basis is a basis consisting of Jordan chains of generalized eigenvectors for a linear operator. Its matrix is in Jordan normal form. Over the complex numbers every finite-dimensional linear operator has such a basis; a real matrix with nonreal eigenvalues requires complexification for this form.
A matrix is defective when an eigenvalue has geometric multiplicity smaller than its algebraic multiplicity. Over a field in which the characteristic polynomial splits, this is precisely the obstruction to an eigenbasis: at least one Jordan block has size greater than one, and generalized eigenvectors are needed to complete a basis. The shear mapping in diagonalizable matrix is the simplest example.
An involution in characteristic two has Jordan blocks of sizes at most two. Its conjugacy type is determined by the rank of , subject to . GL-conjugacy can split in SL if the centralizer determinant map is not onto; that issue must be checked separately. In a one-dimensional untouched block makes that determinant map onto, yielding one involution class. In the two possible nonzero ranks give two classes. Their projective quotients have equal order but different involution class counts.
Perturb each diagonal position of a Jordan normal form matrix by a different arbitrarily small scalar, avoiding the finitely many collisions between diagonal entries. The resulting upper triangular matrix has distinct eigenvalues, hence is diagonalizable. Conjugate back to approximate any complex matrix. Continuous identities proved for diagonalizable matrices can therefore extend to all matrices.
A complex two-dimensional linear operator whose two eigenvalues both equal is similar either to or to . Choose an eigenvector and complete it to a basis. The matrix becomes because its characteristic polynomial is . A nonzero can be normalized to one by rescaling the first basis vector. The two types are distinguished by eigenspace dimension.
Over an algebraically closed field, a linear operator has a unique decomposition into a commuting diagonalisable endomorphism and nilpotent endomorphism . On its generalized eigenspace for , set and . The Chinese remainder theorem makes both parts polynomials in , so they preserve every -invariant subspace. Uniqueness follows by restricting any other commuting decomposition to those generalized eigenspaces. Over a perfect field the semisimple part need only become diagonalizable after scalar extension.
The commutator action of is diagonalizable on endomorphisms: on it acts by . The action of is nilpotent by nilpotence of commutation by a nilpotent endomorphism. The two actions commute, so uniqueness of the Additive Jordan decomposition identifies them as the parts of .
For a complex semisimple Lie algebra and , both parts of its Additive Jordan decomposition lie in . The polynomial semisimple part of shows normalizes . Split by the Weyl complete reducibility theorem; the -component of centralizes . On each irreducible summand of it is scalar by the Schur lemma. Its trace is zero because is a perfect Lie algebra and the nilpotent part has zero trace, so those scalars vanish. Nonsemisimple subalgebras may fail this property: with nilpotent contains neither Jordan part of .
The algebraic multiplicity of an eigenvalue is its multiplicity as a root of the characteristic polynomial. In Jordan form it is the sum of the sizes of all blocks carrying that eigenvalue.
The geometric multiplicity of an eigenvalue is the dimension of its eigenspace. In Jordan form it equals the number of blocks carrying that eigenvalue.
For with and a polynomial , the binomial formula gives . Hence its module on the two-dimensional space is indecomposable exactly when : in that case the nonzero nilpotent part is one Jordan block; otherwise the operator is scalar and every line is a submodule. For over a field of characteristic different from two, the criterion is .
The model matrix has a defective double eigenvalue when . Its characteristic polynomial is , giving the displayed roots. For fixed nonzero the small root is and the other is . These expansions cease to be ordered at , the distinguished limit in which both roots split on a square-root scale. This is the generic leading behavior when a perturbation closes a two-dimensional Jordan block through a nonzero lower-left entry; it need not occur for a perturbation that leaves that entry zero.
A nilpotent Jordan block has zeros on its diagonal and ones on its superdiagonal. Its th power has ones on the th superdiagonal, and a block of size satisfies .
If has eigenvalues and is diagonalizable on a two-dimensional complex vector space, thenIf has one size-two Jordan block, then
Over an algebraically closed field, the characteristic polynomial gives the total size of the Jordan blocks for each eigenvalue, while the minimal polynomial gives the largest block size. For total dimension at most three, these two numbers determine the partition into block sizes: a multiplicity-three eigenvalue has partition , , or according as its largest block has size , , or . Hence two matrices of size at most three with the same characteristic and minimal polynomials are similar.
A Jordan chain of a linear operator for an eigenvalue is a list of nonzero vectors satisfying and for . These vectors are linearly independent: in a vanishing linear combination, applying the largest relevant power of isolates the last coefficient times , then descending induction removes all coefficients. On their span the operator has one Jordan block. This is different from a generalized eigenfunction that solves outside the original function space.
If and , the vector is a generalized eigenvector and solves . The polynomial factor distinguishes a nontrivial Jordan block from an ordinary repeated eigenvalue with a full eigenvector basis.
The generalized eigenspace of a linear operator for an eigenvalue is the union of the kernels . In finite dimension this union stabilizes for sufficiently large .
For endomorphisms of a finite-dimensional complex vector space, suppose repeated commutation with annihilates . Write the blocks of using the generalized eigenspaces of . On , the operator is plus a nilpotent endomorphism. If , it is invertible, so forces that off-diagonal block of to vanish. Thus preserves each generalized eigenspace. This allows a nilpotent Lie algebra representation to be split by generalized eigenvalues even when its acting operators do not commute.
For a linear operator , the generalized eigenspacesbelonging to distinct eigenvalues are linearly independent. On the generalized -eigenspace, is invertible for because the nilpotent part has a finite geometric-series inverse.
A generalized eigenvalue problem asks for a nonzero vector and scalar satisfying . When is invertible, it is equivalent to the ordinary eigenvalue problem .
The generalized characteristic polynomial of a matrix pair is . Every finite generalized eigenvalue is one of its roots.
For a square matrix , its exponential is the convergent power seriesIt is the fundamental matrix for and satisfies .
A matrix exponential defines a positive matrix semigroup if maps nonnegative vectors to nonnegative vectors for all . Here the inequality means entrywise nonnegativity, with zero entries allowed. In finite dimensions this holds exactly when the real matrix has nonnegative off-diagonal entries: if , expand ; conversely, the off-diagonal entries of force for . Zero column sums additionally preserve under .
For finite matrices, or formally on a common invariant domain where the expansion is meaningful, exponential conjugation is generated by the commutator map. Differentiating gives , and its Taylor series yields the nested-commutator expansion. An anti-Hermitian makes this a unitary transformation. For perturbation theory this may be used order by order without asserting convergence for arbitrary unbounded operators.
When a square matrix satisfies , its powers reduce to and . Absolute convergence of the matrix exponential allows even and odd subseries to be separated. Thus and . For real , these are and . For , they are and . At , , including nonzero nilpotent matrices of square zero. This also explains the limiting sine-over-argument coefficients without dividing by zero.
If every eigenvalue of a finite square matrix has negative real part, its matrix exponential decays and its integral converges. The Jordan normal form shows that polynomial factors in are dominated by exponential decay. Integrating gives , proving the displayed matrix inverse formula. In particular, for a Hermitian matrix with negative eigenvalues, the spectral theorem reduces the integral to scalar exponentials with integrals . The minus sign is essential: the integral is positive definite in this Hermitian case, while has negative eigenvalues.
A Hermitian matrix has a unitary spectral decomposition with real eigenvalues . The matrix exponential respects similarity, giving . Its eigenvalues are positive and its conjugate transpose equals itself. In particular for , so it is a Hermitian positive-definite matrix.
Articles were limited to the first 100 out of 267 total.
Articles by others on the same topic
There are currently no matching articles.