Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Invertible matrix
Affine map Created 2026-10-07 Updated 2026-10-14
An affine map combines a linear map with a translation. After choosing coordinate origins, it has the form , , where the matrix is its linear part of an affine map and is a fixed vector. Equivalently, it preserves every affine combination. [ref]
Curves and Surfaces in Geometric Modeling: Theory and Algorithms by Jean Gallier. §2.7, Definition 2.7.1 and linear-map construction, pp. 37–38
An original planar example isIt stretches horizontally, applies a shear mapping, and then translates. The vertices , and become , and . A square grid becomes a grid of parallelograms; straight edges and their weighted points still fit together.
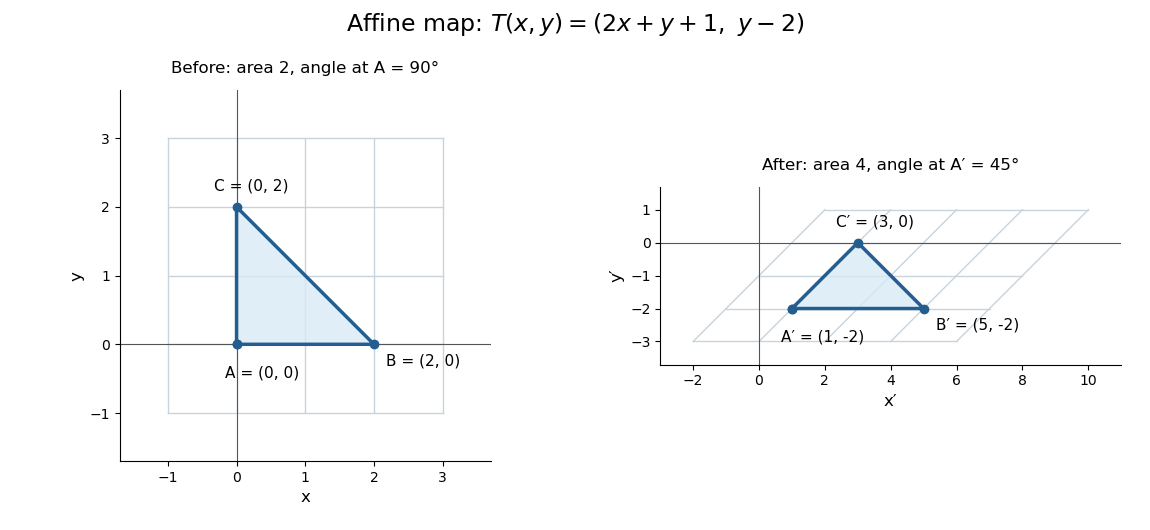
This map is not a linear map with respect to the displayed origins, because rather than zero. It also is not a Euclidean similarity: has length and has length , while the right angle at becomes . Its determinant is , so it doubles planar area. These metric changes explain why affine geometry studies straightness, incidence and weighted points rather than treating every transformation as an isometry.
The linear part is an invertible matrix, giving the concise inverse . More generally an affine map is bijective exactly when its linear part of an affine map is bijective. Between equal finite-dimensional spaces, this means an invertible matrix; the translation cannot repair a loss of rank of a linear map.
Basis matrix 2026-10-25
A matrix whose columns are the coordinate vectors of an ordered basis in a fixed reference basis. It is an invertible matrix, and multiplication by it converts coordinates in the column basis to the reference coordinates: . For a real inner product space with orthonormal reference basis, its Gram matrix is , and its reciprocal basis has basis matrix .
Block elimination 2026-10-14
Write a linear system as and , with an invertible matrix. Solving the first equation for and substituting in the second givesThus the Schur complement is the coefficient matrix remaining after the variables have been eliminated. When it is an invertible matrix, solve the reduced linear system for and recover . In computation, expressions such as mean solving with each column of , using the same LU decomposition or Cholesky decomposition when applicable.
For the example under block matrix inverse and right-hand side , take and . Since , the reduced equation is . Back substitution givesThe original equations return , and , respectively. The reduction retained the influence of on through the correction .
A short proof outline also explains whether is an invertible matrix: the exact matrix factorizationhas invertible matrices on the outside. Therefore is an invertible matrix precisely when the central block diagonal matrix is one. Reversing the factors gives the block matrix inverse, while taking determinants gives the Schur complement determinant identity.
Block matrix inverse Created 2026-09-24 Updated 2026-10-18
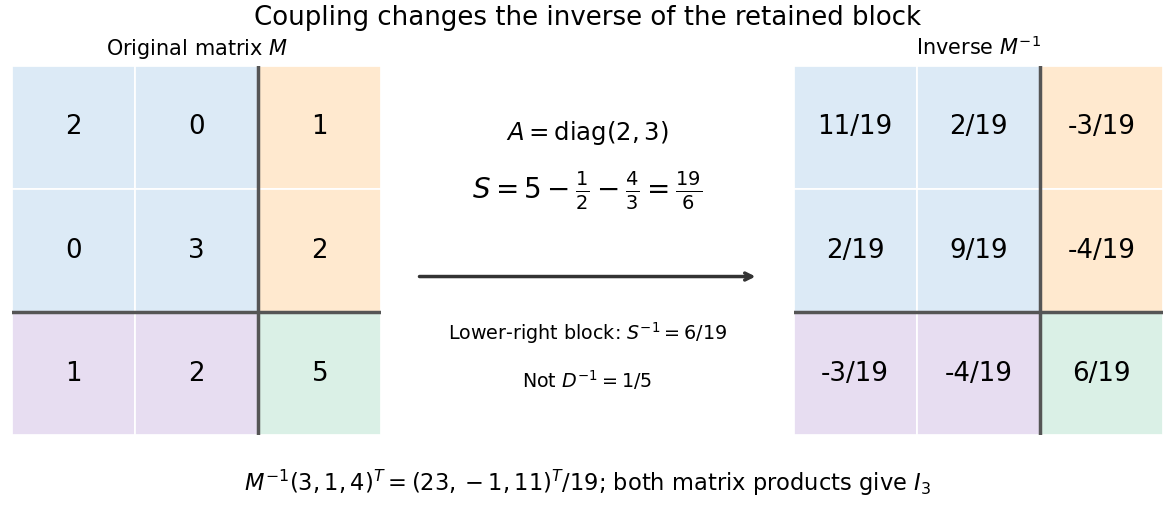
A block matrix inverse expresses the matrix inverse in terms of smaller matrices. Partition a square matrix over a field asIf is an invertible matrix, define its Schur complement . Then is an invertible matrix exactly when is an invertible matrix, andThe order of the matrix products matters. In particular, the lower-right block is , rather than generally : the coupling through and changes the response.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. Appendix A.5.5, printed p. 650: inverse of a symmetric block matrix; §C.4.1, printed p. 673: elimination for general blocks
For an original example, takeThe Schur complement is . Substitution gives the concise answerMultiplying in either order gives the identity matrix; the lower-right entry is , whereas . The difference records the feedback through the two eliminated variables.
Often the desired output is a solution of a linear system, rather than every entry of a matrix inverse. Block elimination solves with and then with , recovering the eliminated variables by back substitution. Reusing an LU decomposition of avoids explicitly forming . A favourable block diagonal matrix or tridiagonal matrix block can make this useful; merely partitioning an unstructured dense matrix does not guarantee a faster solve.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §C.4.1, printed pp. 672–675: Algorithm C.4, factor-solve interpretation and dense complexity comparison
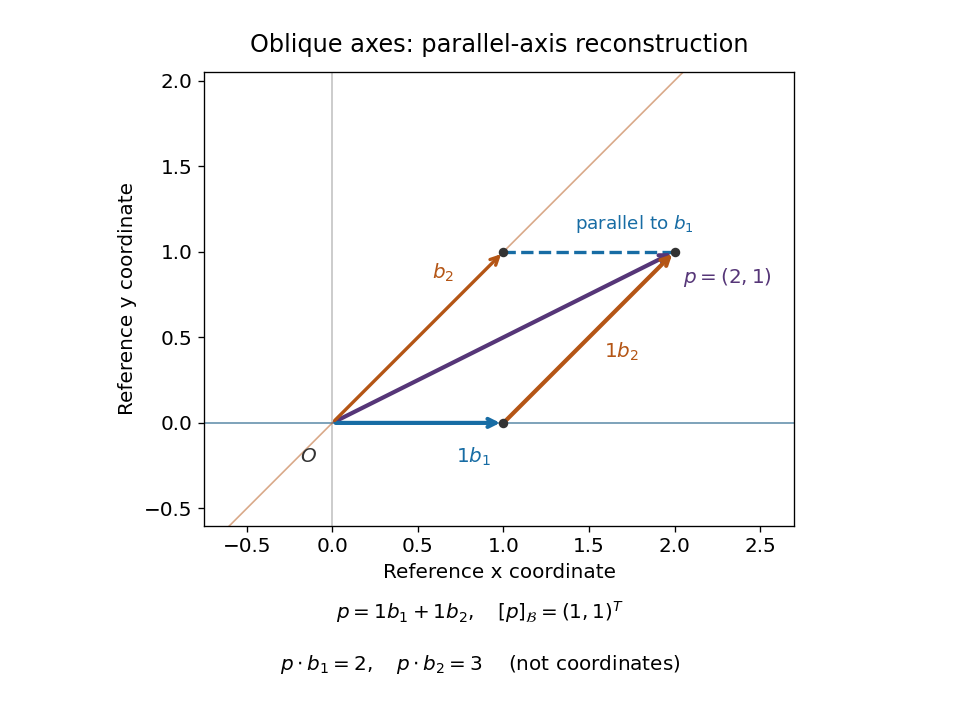
Keep the same origin and the same vector , but use the nonperpendicular basis vectors and . They form a basis because the column matrix has nonzero determinant:The reconstruction is . Its coordinates are read along lines parallel to the other axis, producing a parallelogram. These lines need not be perpendicular to the axis being measured. In contrast, the dot products are and ; treating those as coordinates would reconstruct , a different vector.
The dual basis supplies the right measuring rules for any basis.[ref]
Linear Algebra Done Right by Sheldon Axler (4th edition). §3F, Definition 3.112 and Theorem 3.114, printed p. 106: dual basis and coefficient extraction
Here these coordinate functionals are and , the rows of . They give . Equivalently, their representing vectors , satisfy and extract the coordinates as . These are Riesz dual basis in an inner product space representatives, rather than the original basis vectors.The Gram matrix records how the nonperpendicular directions interact:For any real basis represented by a square invertible matrix , writing gives these identities immediately. One can recover the coordinates either as or by solving . In this example, if , the squared norm is , not . Oblique coordinates remain useful when natural directions are not perpendicular, but the Gram matrix must accompany them when computing lengths or dot products.
Change-of-basis matrix Created 2026-09-29 Updated 2026-10-18
Fix the convention: the columns of the change-of-basis matrix are the new basis vectors written in the old basis. Thus converts new coordinate vectors into old ones; its matrix inverse converts old coordinate vectors into new ones. For the preceding basis,Its determinant is , so is an invertible matrix. Checking which direction converts is essential: different books may call either or the change-of-basis matrix.
For a linear operator, convert the input into the old basis, apply the old matrix, and convert the output back. Reading that sequence from right to left givesFor example, let the old diagonal matrix stretch horizontal components by and vertical components by . ThenThe output represents , just as . The matrices look different because their bases differ, but they encode the same linear operator. This relation is called matrix similarity; it preserves the underlying action.[ref]
https://ocw.mit.edu/courses/18-06-linear-algebra-spring-2010/46108efb43dcf33e989eb5e101fcf9b5_MIT18_06S10_L31.pdf. Strang, Lecture 31 transcript: coordinate conversion and similar matrices
Cholesky decomposition as a sum of squares Created 2026-10-18 Updated 2026-10-31
For any real vector , a Cholesky decomposition gives the quadratic form identitySince is an invertible matrix, this squared Euclidean norm is positive whenever . The factorization thus certifies positive definiteness and gives coordinates in which the quadratic form is a sum of ordinary squares. For the matrix above,The level set is an ellipse; the linear map sends it to the unit circle. The points and go to and , respectively.
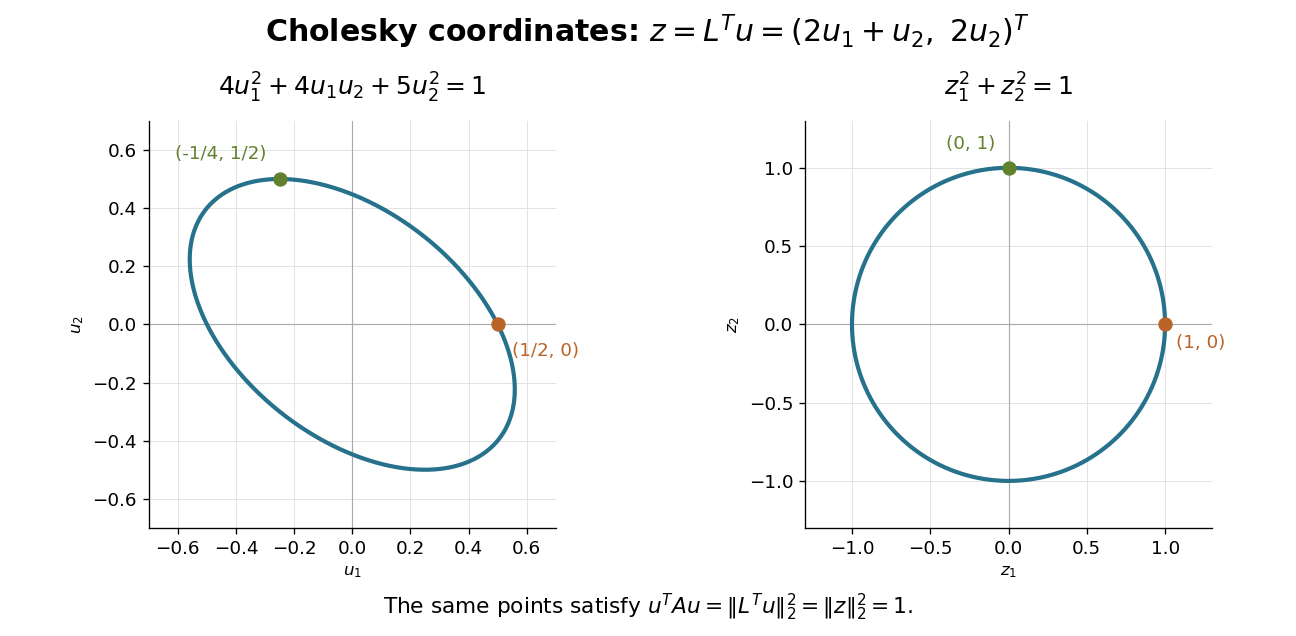
The same factor works in the reverse direction for Gaussian random vectors. If has independent unit-variance, zero-mean Gaussian random variables as coordinates, has covariance matrix . In this example and : their variances are and , while their covariance is . This is a concrete way to generate specified correlations from independent draws.
A triangular factor is not generally a square root of a matrix in the sense . Here . The Cholesky decomposition uses the product with the transpose, which is also what makes the quadratic form a squared Euclidean norm.
Choosing a different block pivot 2026-10-14
An invertible matrix need not have an invertible chosen diagonal block. For example,has singular matrices as both one-by-one diagonal blocks. Neither diagonal-block formula applies in that partition. Interchanging the two rows produces the identity matrix and a usable pivot element. This is why a failed block pivot is not proof that the full matrix is a singular matrix; Pivoted LU decomposition changes the order before eliminating.
Conversely, invertible diagonal blocks do not suffice: has but Schur complement , so it is a singular matrix. Both hypotheses in the block matrix inverse formula have work to do.
Column rank Created 2026-10-14 Updated 2026-10-18
The column rank of a matrix is the dimension of its image of a linear map, equivalently the dimension of the linear span of its columns. Multiplication on the left by an invertible matrix preserves all column linear relations, and elementary column operations preserve their linear span. In row echelon form the pivot columns form a basis of the column space. Its dimension equals the number of nonzero rows, and hence the row rank.
Continuation predictor-corrector step 2026-10-14
For the cubic polynomial, an oriented, normalized tangent vector isIts Euclidean norm is one and . The sign here follows increasing ; for a general solution branch, choose the sign of each new tangent vector so its dot product with the previous one is positive. First predict , then apply Newton method starting at toThe second equation keeps the correction on the transverse line in this two-dimensional example; in higher dimensions it is a hyperplane. Solving the linear system and updating corrects both coordinates together.
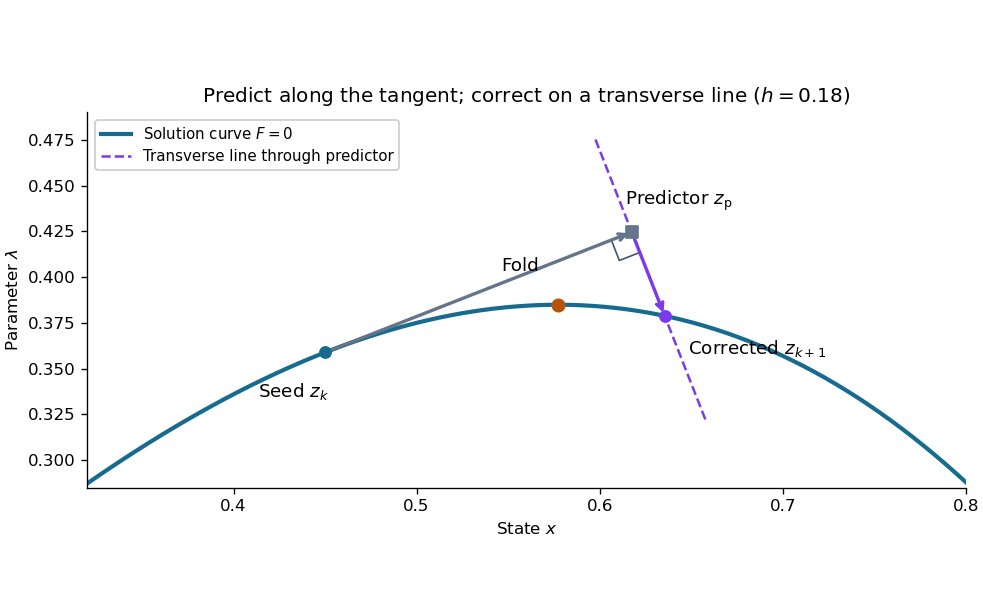
This step gives and . Check both equations: the solution must satisfy and . Checking only the first could accept any point on the solution branch. The new exceeds , so the step crosses the continuation fold, even though the predictor's exceeds .
At the seed, set . The determinant of the correction Jacobian matrix with the exact unit vector above isAt either continuation fold, , and : the correction remains invertible. More generally, if has full rank and a one-dimensional kernel spanned by , adding gives an invertible matrix, since a vector annihilated by both rows must be zero. This is a local argument; the old transverse hyperplane need not work arbitrarily far along the curve. Reduce and retry when correction fails, and check the equations and orientation after successful steps. Scaling state and parameter coordinates also matters, because it changes the Euclidean norm used to normalize the tangent vector.
// Target: analysis.bigb
Let the columns of an invertible matrix be a new basis expressed in the old basis. The same vector has old coordinate vector and new coordinate vector . If a covector has old row , its new row is , sinceThus the scalar dual pairing stays unchanged. If covector coefficients are stored as a column , their new column is ; this is the inverse transpose of the transformation on vector coordinates. These conventions express the covariance and contravariance of vectors. [ref]
https://www.math.brown.edu/streil/papers/LADW/HTML_2026_04-30/Ch8.html. Sergei Treil, Linear Algebra Done Wrong, §8.1.1: coordinate changes in the dual space
.For the basis , ,The linear functional has rows and . Both calculations give five: . Changing the basis changes the descriptions, not the measured value.
For four distinct projective points on the complex projective line, use the conventionwhere is the determinant of chosen representative vectors. Rescaling any representative cancels, and applying an invertible matrix multiplies every bracket by its determinant, which also cancels. Thus the expression is a projective invariant. The projective general linear group action on the projective line has a unique element taking the first three points to . In those coordinates the displayed expression is exactly . Consequently the cross-ratio completely determines the orbit of the ordered quadruple under the projective linear group. Its value lies in .
Cube root of a matrix 2026-10-25
A cube root of a matrix is a square matrix of the same size over the specified field satisfying . Every complex invertible matrix has one: put it in Jordan normal form, choose a scalar cube root of each nonzero eigenvalue, and apply the truncated binomial cube root of the identity plus a nilpotent matrix on each block. The Nilpotent Jordan block has none, even though its square is nonzero. If , then , making a nilpotent matrix of size three; the Cayley-Hamilton theorem then gives , a contradiction.
Determinant Created 2026-09-24 Updated 2026-10-14
The determinant assigns a scalar to a square matrix. For a linear map on the real plane, it measures signed area scaling: its absolute value tells how much area grows, and its sign records whether the orientation of a vector space is preserved or reversed. In three dimensions, the same idea measures signed volume. Over a field, a square matrix is an invertible matrix exactly when its determinant is nonzero. These are two views of one phenomenon: losing an independent direction collapses full-dimensional volume and makes the original input impossible to recover uniquely.[ref]
https://www.math.ucla.edu/~rse/algebra_book.pdf#page=716. Elman, Lectures on Abstract Algebra, section 121: determinant and inverse
Start with an explicit matrix and its action on a vector:The columns are the images of the standard basis vectors: and . Consequently the unit square with corners becomes the parallelogram with corners . Its area is five. Every small patch of this square undergoes the same linear map, so the factor describes the whole deformation, rather than just one specially chosen boundary. The matrix mixes horizontal and vertical components, but its determinant compresses that combined effect into one area factor.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section01.html. MIT calculus notes, section 4.1: determinants and area
Now exchange the columns:The parallelogram occupies exactly the same region, but its generating vectors arrive in the opposite order. Moving from the first column to the second now turns clockwise rather than counterclockwise. Ordinary area remains five; the oriented volume in two dimensions changes sign. A negative determinant therefore signals reversed orientation of a vector space, not a negative amount of material. Keeping the sign makes successive reversals calculable: two reversals restore the original orientation of a vector space.
Compare a singular matrix:Its columns are linearly dependent: the second is twice the first. The unit square collapses onto the segment from to , which has zero area despite nonzero length. Since , the kernel of a linear map contains a nonzero vector; inputs differing by that vector have identical outputs. The collapsed picture explains why an inverse matrix cannot exist.
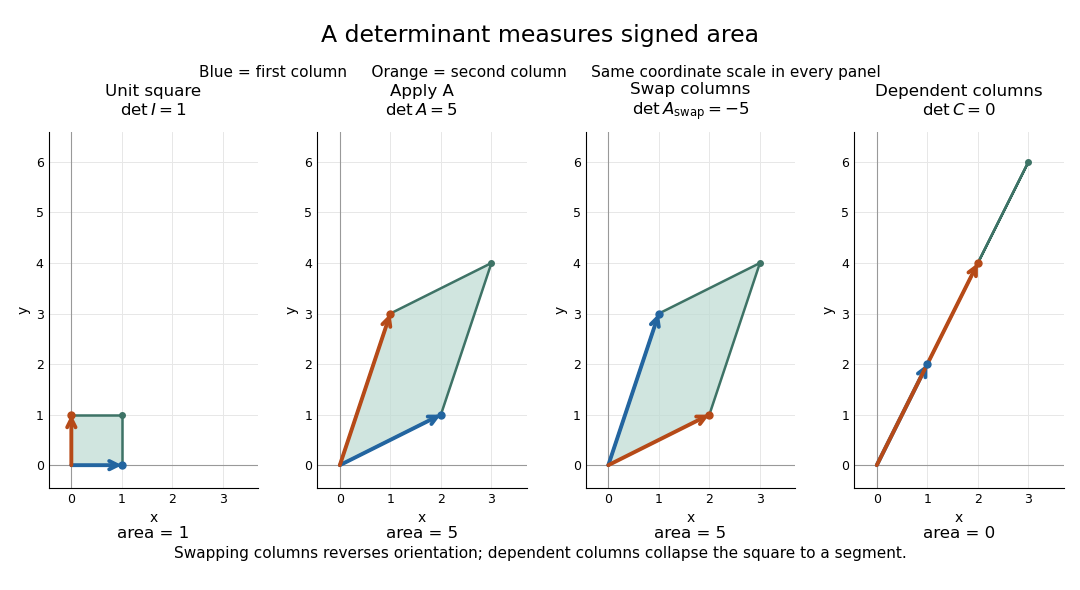


For , recovery is possible, and the complete matrix multiplication check isHere is the identity matrix. The inverse matrix restores the original square, shrinking its area by . Generally, the adjugate identity gives whenever the determinant is nonzero over a field; this is why the denominator matters.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section04.html. MIT calculus notes, section 4.4: determinant and inverse
The multiplicativity of the determinant describes two successive deformations. Matrix multiplication means that applies first, then . TakeThe first linear map doubles area; the second multiplies the resulting area by five. Thus the unit square passes through areas , with the last parallelogram bounded by . Direct calculation agrees:This explains physically why area factors multiply instead of adding. The general identity holds for square matrices of the same size, including singular matrices. If either stage loses a direction, later processing cannot recover the discarded information.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter32/section04.html. MIT calculus notes, section 32.4: determinant products
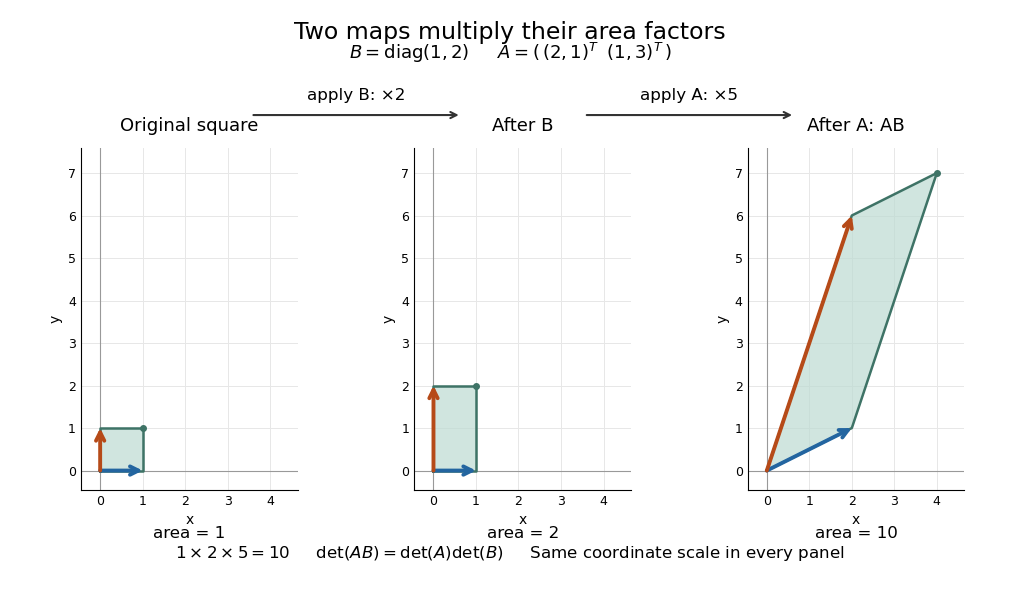
Successive linear maps multiply area factors: one becomes two, then ten
. Details. 
The same interpretation works in three dimensions without drawing a new picture. The diagonal matrixsends the unit cube to a rectangular box with side lengths two, three, and one. Its ordinary volume is six. The minus sign comes from reversing the third direction, so the oriented volume is minus six. Replacing the last diagonal entry by zero flattens the cube into a planar region: its area may be positive, but its three-dimensional volume is zero. This distinction matters whenever a linear map changes shape: the determinant measures size in the full input dimension, rather than the size of whichever lower-dimensional object remains.
The determinant measures neither trace nor perimeter. For , the trace happens also to be five, but the identity matrix in two dimensions has trace two and determinant one. The first parallelogram above has perimeter , compared with four for the unit square; boundary length follows a different rule. Nor does determinant one require every length to stay fixed: the diagonal matrix preserves area while stretching one direction and compressing the other.
These properties make the determinant useful when coordinates obscure what a deformation does. A nonzero determinant certifies that linearly independent input directions remain distinguishable; its magnitude counts the area or volume represented by a transformed cell. That second role reappears in the change of variables formula, where the Jacobian determinant corrects the sizes of small cells. Signed volume also separates a deformation that reverses the orientation of a vector space from one that merely stretches it, even when both give identical ordinary volume factors.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter24/section02.html. MIT calculus notes, section 24.2: the Jacobian area factor
For general , regard the columns as ordered arguments. The determinant is the unique alternating multilinear map to the scalar field normalized by . The multilinearity of the determinant means linearity in each column separately, with all others held fixed:Alternation means equal columns give zero; exchanging columns negates the result. Normalization sets the oriented volume of the standard basis to one. These properties also hold in rows. For real three-dimensional columns, their determinant is the scalar triple product, and its absolute value is the enclosed volume. Over other fields, the algebraic definition still works even without a geometric notion of positive volume.[ref]
https://web.mit.edu/18.06/www/Spring16/lecture22.pdf. Barwick, MIT 18.06 Lecture 22: the determinant axioms
Separate linearity does not mean the determinant is a linear map on the whole matrix. Scaling every column of an -by- matrix by gives . For our two-dimensional example, : doubling both directions quadruples area. The power records how many independent directions are being scaled together.
The properties suggest practical computations. Adding a multiple of one column to another preserves the determinant: the extra term has repeated columns and vanishes. This is the algebra behind an area-preserving shear mapping. Alternatively, expansion along a row uses cofactors, each a matrix minor multiplied by a sign:where deletes row and column . The Leibniz formula for determinants supplies the general entry formula. Both calculations encode the same geometric invariant; the defining properties explain their structure without requiring memorization of a separate recipe for every size.[ref]
https://ocw.mit.edu/ans7870/18/18.013a/textbook/HTML/chapter04/section03.html. MIT calculus notes, section 4.3: cofactor expansion
Diagonalizable matrix Created 2026-09-24 Updated 2026-10-14
A finite-dimensional linear operator is diagonalizable over a specified field when it has an eigenbasis. Equivalently, its matrix admitswhere is an invertible matrix whose columns are eigenvectors, and is a diagonal matrix of the corresponding eigenvalues. This change of basis reveals a linear map as independent one-dimensional scalings. The matrix may look coupled in the original coordinates, but each coordinate in the eigenbasis evolves on its own.
For the symmetric matrix computed in eigenvector, takeThen , hence . The orthonormal basis version is , an orthogonal matrix satisfying . Every real symmetric matrix has an orthonormal eigenbasis by the spectral theorem; a general diagonalizable matrix need not have orthogonal eigenvectors.
The immediate payoff is repeated application: adjacent factors cancel, giving . In this example,The component in grows while the component in stays fixed. After division by its Euclidean norm, this particular sequence approaches . This is the mechanism behind the power method; an initial vector entirely in would stay there and never find the dominant eigenvalue .
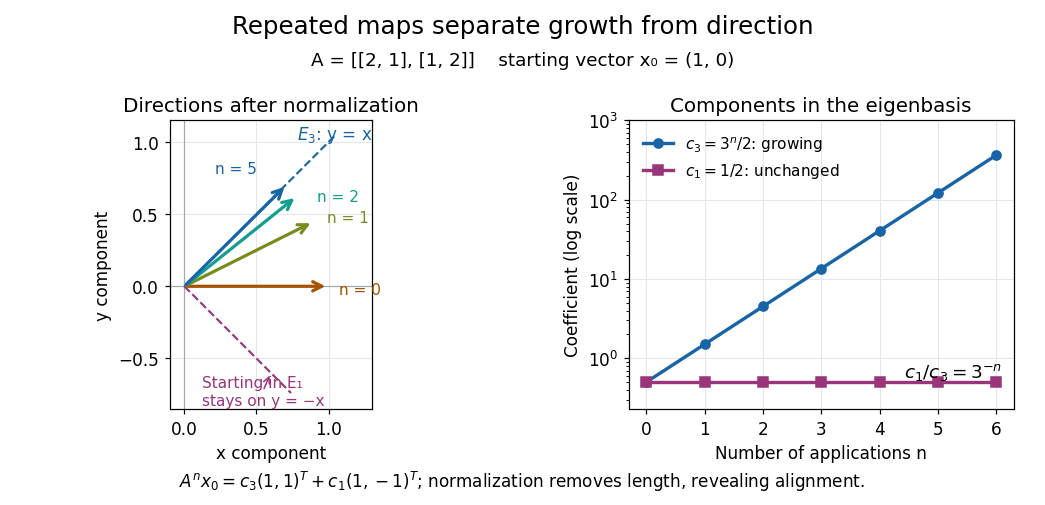
Repeated maps: eigenvalue growth, alignment, and the exceptional starting direction
. Details. 
Two different obstructions deserve comparison. The planar rotation in eigenvector is diagonalizable over but not over , because its eigenvalues are and . By contrast, the shear mappinghas only , of algebraic multiplicity two, and , of geometric multiplicity one. There is no second independent eigenvector, even over . This is a defective matrix, already a two-dimensional Jordan block. Its powers areThus even though both eigenvalues are one, repeated application can produce growth. Eigenvalues alone miss the coupling recorded by a Jordan block. A repeated eigenvalue is harmless when it has enough independent eigenvectors, as demonstrates. More generally, a matrix is diagonalizable exactly when its characteristic polynomial splits over the chosen field and every eigenvalue has equal geometric multiplicity and algebraic multiplicity. The proof outline is to join bases of the distinct eigenspaces; their direct sum fills the space exactly under these conditions.
A physical motivation is the separation of normal modes. Consider two equal masses between three identical springs of stiffness , with the outer ends fixed. By Hooke's law and Newton's second law, the displacement vector obeysThe eigenvectors and have eigenvalues and : the masses move together in the first normal mode and oppositely in the second. Writing separates the coupled equations into two harmonic oscillators,Their angular frequencies are and ; the eigenvalues give squared angular frequencies after multiplication by . This is the beauty of diagonalization: finding the right directions turns interacting motions into independent patterns. For a physical treatment, see Yen-Jie Lee's "Coupled Oscillators, Normal Modes" (MIT 8.03SC, 2016), and the local article normal modes of two equal masses between three springs.[ref]
Diagonal scaling of Gershgorin discs 2026-10-14
A positive diagonal matrix , with , is an invertible matrix and changes the coordinate scales through the similarity transformation . Its diagonal entries are still , while . Thus the Gershgorin discs have the same centres but different radii. Matrix similarity preserves the characteristic polynomial and eigenvalues, so the original and scaled disk unions are both valid bounds and may be intersected. Suitable scaling can compensate for badly unbalanced off-diagonal entries; it need not shrink every radius.[ref]
https://cklixx.people.wm.edu/teaching/math408/408-note.pdf. Chi-Kwong Li, Math 408 lecture notes, §6.1: similarity transformations for eigenvalue localization
For example,The original Gershgorin discs are and . Their union is simply the huge first disk; the small second disk contains no eigenvalue. After scaling, both radii are , giving or . The two Gershgorin discs overlap, so their individual eigenvalue counts are not certified. The scaled matrix is a real symmetric matrix, however, so matrix similarity now proves that the original matrix has real eigenvalues in and is an invertible matrix. Directly, both matrices have characteristic polynomial , henceThe scaling changes the available bounds, while these eigenvalues stay fixed.
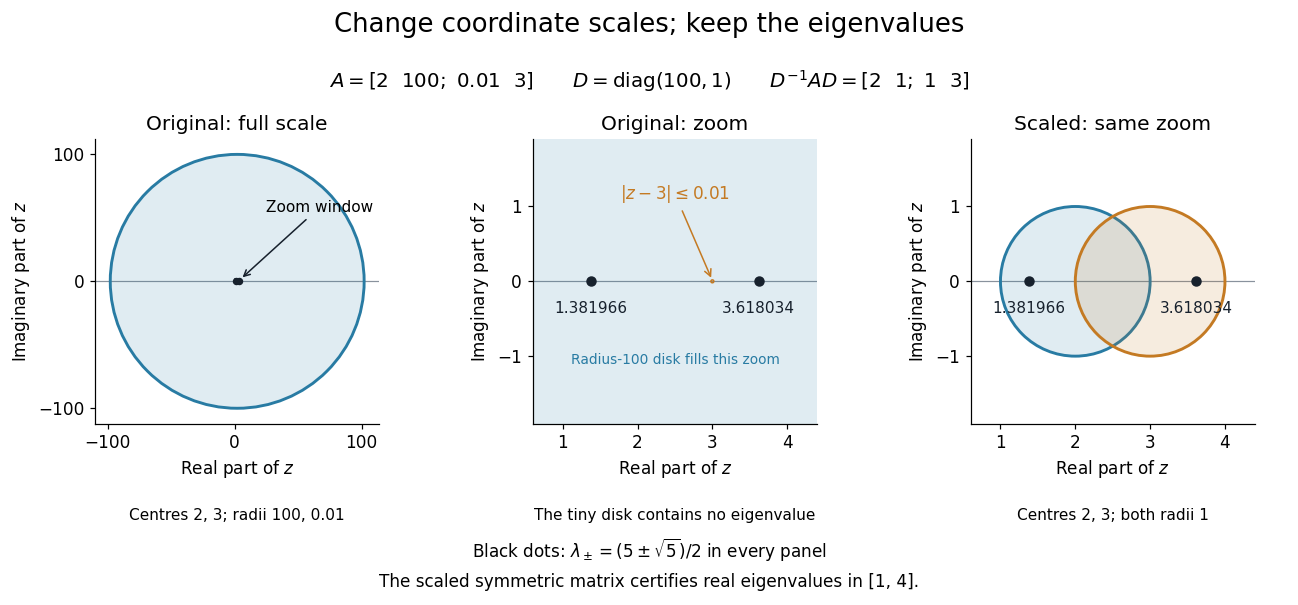
Diagonal similarity scaling replaces a radius-100 Gershgorin disc by two radius-1 discs while preserving both eigenvalues
. Details. 
Eigenvectors under similarity 2026-10-14
Under , an eigenvector in old coordinates becomes in new coordinates. Indeed,Since is an invertible matrix, the new coordinate vector is nonzero. The inverse conversion proves that the two eigenspaces have the same dimension, hence the same geometric multiplicity.
For , the eigenvector has eigenvalue . In the oblique basis of the opening example, its coordinate vector isThe tuple changes from to , but reconstruction gives : the physical vertical direction is unchanged. Calling the eigenvectors unchanged is accurate only for the underlying vectors, not for their coordinate vectors.
Energy-norm proof of convergence of SOR 2026-10-31
Let be a real symmetric positive-definite matrix, with diagonal and strictly lower triangular. Put and for . The matrix norm induced by an energy norm reduces the question to . Direct multiplication and giveThe left side is positive semidefinite. The matrix following the scalar coefficient on the right is positive-definite, since has positive diagonal and is an invertible matrix. For , every eigenvalue of therefore lies in . Hence its spectral radius is below one and . Iteration errors consequently decay geometrically in the energy norm. The argument proves convergence from every initial vector, without requiring the original iteration matrix to be symmetric.
Full row rank Created 2026-09-28 Updated 2026-10-18
An matrix has full row rank when its matrix rank is , equivalently when its rows are linearly independent vectors. This requires . Its column space is all of , so the represented linear map is surjective and every linear system is solvable. If , its nullity is , so solutions are not unique.[ref]
One-to-one and Onto Transformations. Interactive Linear Algebra, §3.2.2, Onto matrix transformations theorem and Tall matrices do not have onto transformations
For example, the matrix transpose of the matrix in full column rank isIt has full row rank two. Every output has solutions , with . A square matrix of size has full row rank and full column rank together exactly when its matrix rank is ; then it is an invertible matrix. A nonsquare matrix cannot have both properties, and has no two-sided inverse: such an inverse would make its linear map a linear isomorphism between vector spaces of different dimensions.
Gaussian elimination Created 2026-09-24 Updated 2026-10-25
Gaussian elimination applies elementary row operations to reduce a linear system to triangular form. Dense elimination uses arithmetic operations.
Gaussian elimination solves a linear system by removing one unknown from later equations at each step. Write the coefficients and right-hand side together as an augmented matrix . Apply the same elementary row operations to both parts until the coefficients form a row echelon form; for a square invertible matrix, this gives an upper triangular matrix system. Then back substitution recovers the unknowns from the last equation upward. The useful simplification is that each successive equation involves fewer unknowns, while the set of solutions stays the same.
Why do elementary row operations preserve solutions? Interchanging equations changes only their order. Multiplying an equation by a nonzero scalar can be undone by division. Replacing equation by itself plus times equation , with , can be undone by adding times the unchanged equation . Equivalently, an elementary matrix is an invertible matrix, so if and only if . Applying an operation to without also applying it to loses this equivalence.
At step , choose a nonzero pivot element after any row interchange. For every , form the elimination multiplier and perform the elementary row operation . Its coefficient in column becomes in exact arithmetic. Later operations combine rows that already have zeros in earlier columns, so those zeros survive. If an active column has no nonzero candidate, general row echelon form reduction skips it; a square invertible matrix always has a candidate at each step with suitable row interchanges. Partial pivoting also considers roundoff error when selecting the candidate.[ref]
2.6 Row pivoting. Fundamentals of Numerical Computation by Tobin A. Driscoll and others; §2.6.1, Definition 2.6.1: select the largest absolute candidate; §2.6.3: permute the right-hand side too
For a dense matrix with one right-hand side, the classical algorithm uses arithmetic operations over the real numbers, counting each addition, subtraction, multiplication and division as one. At step , the coefficient update has entries, each costing one multiplication and one subtraction; the elimination multipliers, right-hand-side updates and back substitution contribute lower-order terms. Searching for partial pivoting adds comparisons, and storing the dense coefficients uses space. These assumptions exclude the different storage and work patterns of sparse Gaussian elimination; the exact loop counts appear in LU factorization and solve costs. Here denotes Big O notation.
Recording the same steps as an LU decomposition makes Reusing LU factors for multiple right-hand sides possible. This is useful whenever the coefficients stay fixed while the forcing vector changes: the expensive elimination is done once. The choice of pivot element matters even when the linear system is well conditioned, as Tiny-pivot roundoff in Gaussian elimination demonstrates.