Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Probability
Ramsey spectroscopy 2026-10-18
Ramsey spectroscopy measures a transition frequency by comparing the relative quantum phase acquired between two coherent interactions with the reference oscillator. In a beam, a state selector and apertures admit particular internal quantum states and trajectories; an analyzer and detector measure state-dependent transmission. In an optically prepared atomic clock, optical pumping and fluorescence can perform those functions. The preparation and readout determine which part of the beam contributes; they are not themselves the two coherent interactions.
For an ideal accepted particle, the first resonant half-duration Rabi pi pulse splits the probability amplitude between and . The second combines two indistinguishable alternatives: a transition in the first region followed by no transition in the second, or the reverse. Their relative quantum phase depends on the dark flight and the drive oscillation phases. Adding probability amplitudes gives quantum interference; adding only the two alternatives' probabilities would erase the fringe. “Dark” means that the transverse drive is absent: a static magnetic field and the internal Hamiltonian operator can still act.
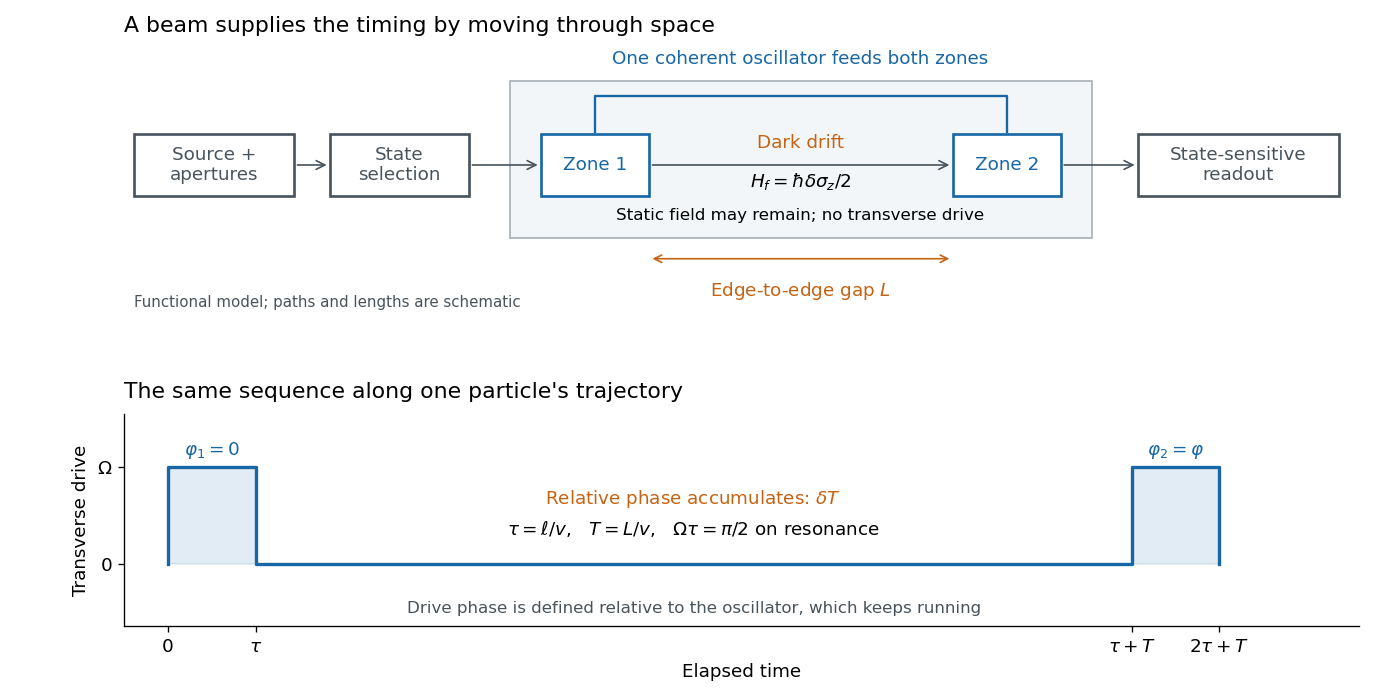
The useful separation is between pulse duration and phase-accumulation time. Short regions can share one coherent oscillator while a long drive-free interval resolves small frequency differences. A scan over reference frequency locates a fringe pattern; controlled changes of the second pulse's oscillation phase distinguish that coherent signal from phase-insensitive background. A reference scan must also identify the central fringe before atomic clock frequency lock, because neighboring fringes provide competing lock points.
Random-cluster inverse correlation length 2026-10-14
Positive association of random variables and translation invariance give for axis connection probabilities. The Fekete lemma applied to proves the displayed limit of a sequence and the bound . The lower single-edge conditional bound gives , so the decay rate is finite and nonnegative. It may be zero.
For an edge with endpoints already connected without that edge, including any boundary wiring, the conditional open probability is . Otherwise opening the edge merges two components, so the conditional probability is . For , this conditional probability increases when more other edges are open or more boundary vertices are identified. This is the local mechanism of boundary monotonicity of the random-cluster measure.
Random cuts of a cycle 2026-10-25
Choose distinct edges uniformly from an -vertex cycle graph, with , and delete them. Two specified vertices at oriented distance remain connected exactly when one of their two complementary edge-disjoint paths is uncut. All cuts must then lie in the other path, giving the displayed probability. The two events are disjoint because at least one edge is cut. Set when .
Summing the connectivity indicators for all other vertices gives an expected numberof other vertices in a tagged connected component. The sum identity follows by classifying -element subsets according to their greatest element. For three cuts this is other vertices.
Let be a nonzero multivariate polynomial over a field , with total degree at most . Choose a nonempty finite set . For independent random variables , each with a uniform distribution on a finite set on , the Schwartz-Zippel lemma givesNonzeroness is essential; the zero polynomial always evaluates to zero. The total degree sums exponents within each monomial, rather than taking their maximum: has total degree five. The field need not be finite, but must be finite. The estimate reduces error only when .[ref]
CMPT 710 - Complexity Theory: Lecture 18. CMPT 710 and CMPT 407 - Computational Complexity - Fall 2007; CMPT 710 - Complexity Theory: Lecture 18, §3.1, pp. 3–4: Lemma 4 and its inductive proof
The proof begins with the root bound for a polynomial. For several variables, write , with . The total degree of is at most . By induction, vanishes with probability at most . Otherwise the remaining univariate polynomial has at most polynomial roots. Adding the two contributions gives .[ref]
CMPT 710 - Complexity Theory: Lecture 18. CMPT 710 and CMPT 407 - Computational Complexity - Fall 2007; CMPT 710 - Complexity Theory: Lecture 18, §3.1, pp. 3–4: split by the leading coefficient in the last variable
The algorithm samples a point, performs exact polynomial evaluation, rejects the identity if the value is nonzero, and otherwise accepts. The lemma bounds false acceptance for every fixed nonzero input. For the polynomial identity testing over a finite field example, has and , so its exact error attains the bound. Numerical near-zero values from floating-point arithmetic do not satisfy this exact algebraic contract. A polynomial-time algorithm claim additionally needs efficient sampling and evaluation, including the bit cost of representing and operating on field elements. Counting field operations alone does not establish that cost.
Randomized block coordinate descent 2026-10-25
A coordinate descent method that randomly selects a block and updates only its coordinates. Suppose each coordinate is selected with probability , every block has Lipschitz constant at most , and the objective function is a strongly convex function with modulus . The block descent lemma and the strong convexity gradient inequality giveFor uniform blocks of size in coordinates, updates constitute an optimization epoch, and the epoch complexity is . Here is the initial objective function gap, and the target is its expected gap at most . A coordinate-based common bound is ; actual constants can improve it.
Target: gradient-descent.bigb, under Gradient descent. Randomized statistical test 2026-10-25
A randomized statistical test specifies a measurable rejection probability for each possible data value. It can be implemented by rejecting when an independent uniform random variable on satisfies . A deterministic test has only the values zero and one. Under a simple hypothesis , its rejection probability is , which is its test size for and its statistical power for .
The Neyman-Pearson lemma permits randomization on an equality set of the form to reach a prescribed test size. Continuous observations do not rule out an equality set of positive probability: if both hypotheses give the same probability density function, their likelihood ratio is identically one. This explains why a precise statement of the lemma includes boundary randomization even for continuous data.
Randomly shifted lattice point process 2026-10-14
Let have the uniform distribution on and place a point at every , . This is a simple point process, locally finite, and a stationary point process: a translation only changes the phase modulo one, preserving its uniform distribution. For every Borel set , the Tonelli theorem givesIts consecutive points are exactly one unit apart, despite having the same intensity measure as a unit-rate Poisson point process. This is the one-dimensional translated-grid construction.[ref]
Spatial Point Processes and their Applications. Section 2.1, Example 2.3, printed pp. 26-27: randomly translated grids have constant intensity
Every half-open interval of length one contains exactly one point. For and , , each count has the Bernoulli distribution with parameter , andMore generally, an interval of length , with a nonnegative integer and , contains or points with probabilities and . Its count variance is , while a unit-rate Poisson point process has count variance .
Random quadratic with uniform coefficients Created 2026-10-07 Updated 2026-10-14
For independent uniform on , real roots occur on , a region of probability . On that region both roots are nonpositive. Both lie in exactly when . Its area is , so the conditional probability of both absolute values being at most one is . Joint probability density integration turns algebraic discriminant and root constraints into simple planar areas.
Random spanning of a binary vector space 2026-10-25
Take independent uniform samples from a -dimensional vector space over the two-element field. At current matrix rank , the existing span contains of the possible vectors, so a new sample increases the matrix rank with probability . The mean waiting time for that increase is by the geometric distribution. Adding the waiting times gives . For , the bound follows by separating and using for ; for , no samples are needed.
After samples, failure to span implies that some nonzero linear functional vanishes on all samples. Each fixed nonzero functional does so with probability ; the union bound over the possibilities gives failure less than . This provides both an expected sample count and a fixed-budget high-success version of Simon's algorithm.
Random variable Created 2026-09-24 Updated 2026-10-14
A real-valued random variable is a measurable function from a probability space to the real numbers with their Borel sigma-algebra. More general targets give random elements. For every Borel set , measurability ensures that is an event, so the question "does the observed value lie in ?" has a defined probability.
The function is fixed; its input outcome is uncertain. This separates what we measure from how the uncertainty is modeled. A probability distribution is the resulting pushforward measure, . A cumulative distribution function, probability mass function, or probability density function describes that measure in an appropriate setting. The random variable and its probability distribution are different objects: the former also retains its relationship to other measurements on the same sample space.
For two independent uniform dice, let record their results and define and . The 36 ordered pairs are equally likely, but the resulting probability mass functions differ:For the sum, count the diagonal of the outcome grid having total . For the maximum, subtract the pairs with both results below from the pairs with both results at most . These examples show how a deterministic function transforms a simple input probability distribution into a nonuniform output one.
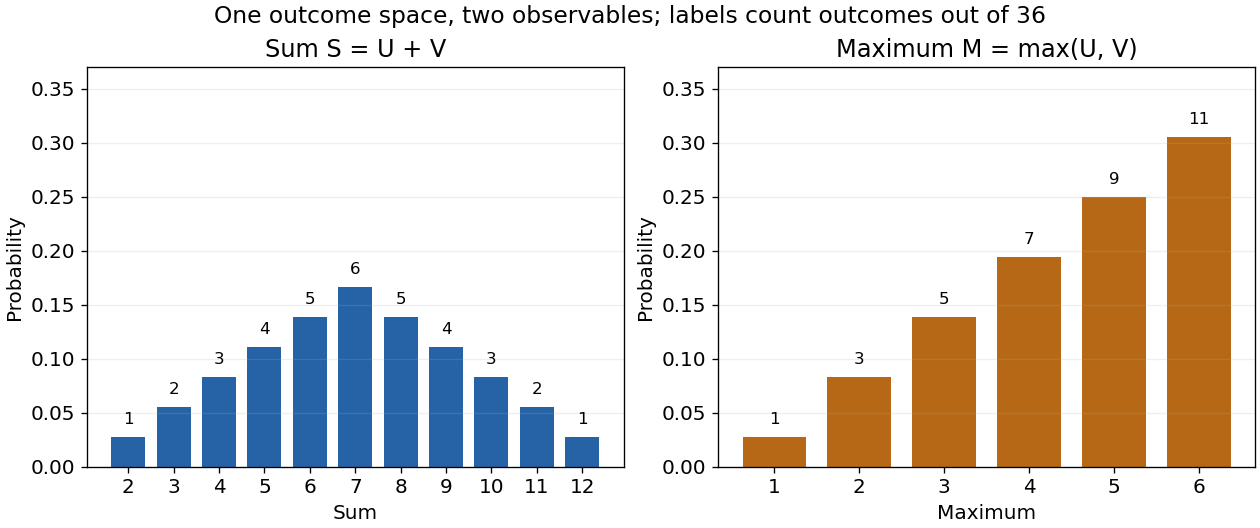


The corresponding expected values are and . The first follows immediately from linearity of expectation; the second follows from . Neither number must be an attainable result. An expected value describes an average under the probability measure, not a prediction that the next observation will equal it.
The distinction between a random variable and its probability distribution matters for dependence. and have the same discrete uniform distribution and are independent random variables. and a second copy of also have that same marginal probability distribution, but they always agree. Their joint probability distribution is concentrated on the diagonal; the marginals alone cannot say which relationship holds. This is why a model for several measurements must specify their joint law or an appropriate independence assumption.
Indicator random variables turn events into numbers: equals one on and zero elsewhere, and . This connects event counting with expected value and variance, and lets tools for random variables answer questions about probabilities. More complicated functions of observations can describe totals, waiting times, or estimation errors using the same framework.
Random walk Created 2026-09-24 Updated 2026-10-14
A random walk is a stochastic process formed by accumulating random steps. In its additive form, the increments are independent and identically distributed random variables and the position after steps isThe steps can have more choices than and : they may be integers, real numbers, or vectors. A random walk on a graph instead describes steps between vertices along edges; its available moves can depend on the current vertex.
For example, starting at zero, the steps produce the positions . This is one sample path; other step sequences can have the same endpoint. A simple random walk on the integer line makes this distinction particularly tangible: repeated Bernoulli trials determine both a whole sample path and an endpoint with a binomial distribution. All positions below are dimensionless quantities measured in steps of length one, and counts discrete updates.
The model is useful because it separates an average tendency from accumulated fluctuations. A fair simple symmetric random walk has zero expected value at every time, yet its standard deviation grows: cancellation across many possible sample paths does not keep each walker near zero. The two figures below compare sample paths with exact endpoint probabilities. For the basic additive construction and its independent increments, see MIT, Stochastic Processes I, section 2.
Rational Decisions by I. J. Good 2026-10-13
By I. J. Good.
Published in the Journal of the Royal Statistical Society, Series B, volume 14, number 1, pp. 107–114.
Cited passage: the published summary describes encouraging accurate probability estimates and a connection with information theory.
Rayleigh distribution Created 2026-10-06 Updated 2026-10-18
The Rayleigh distribution is the probability distribution of the Euclidean norm of a two-dimensional random vector with independent zero-mean normal random variables of equal variance as components. If are independent, thenHere is the standard deviation of each component, not of the radius . At this gives the unit-scale probability density function .[ref]
The Rayleigh Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Rayleigh Distribution, Definition and Distribution Functions: independent equal-scale centered normal components and radial density
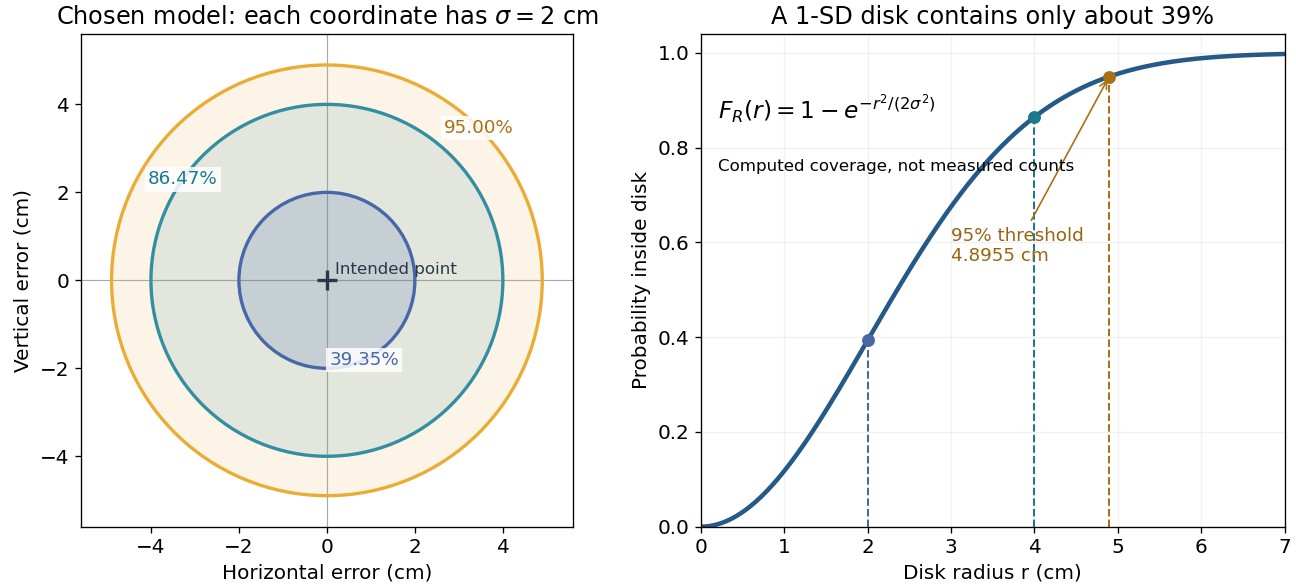
This geometry turns two signed errors into one nonnegative distance. For example, suppose horizontal and vertical positioning errors are independent random variables. Their means both vanish, but the distance from the intended point is usually positive. The Rayleigh distribution with gives the probability of landing inside any centered disk. These are chosen model assumptions, rather than measurements of a particular instrument.
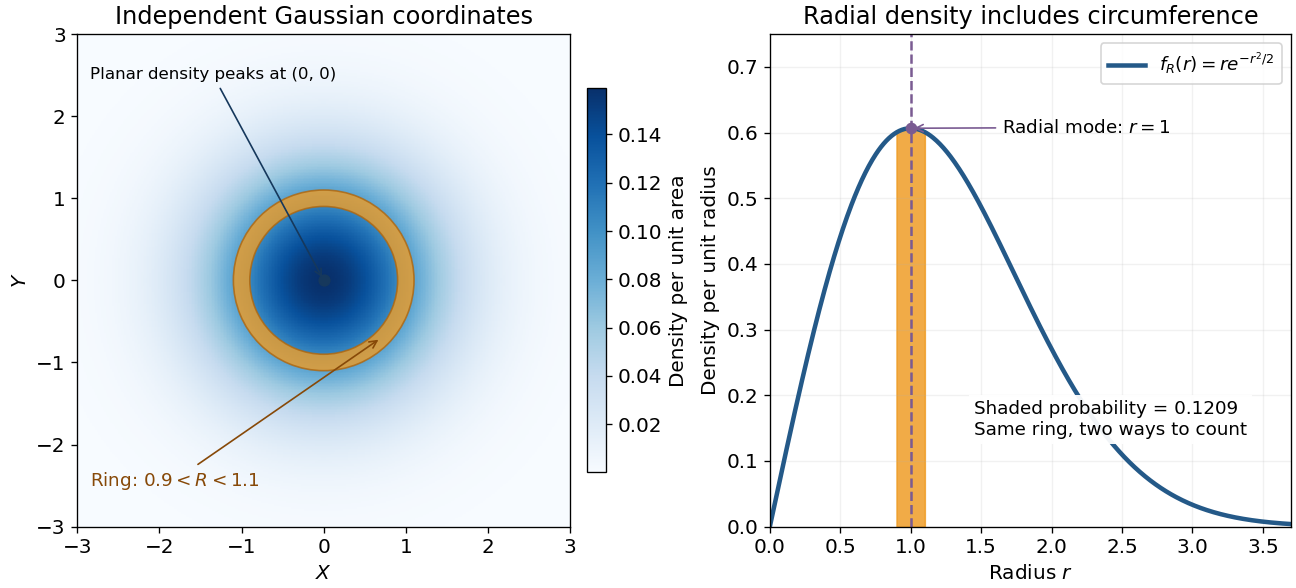

An apparently paradoxical feature is that the most likely location per unit area is the origin, while the radial mode is . A narrow annulus farther out has more area. Near zero that growing circumference outweighs the falling planar density; farther out the exponential function wins. Distinguishing densities measured against different elements of area or length resolves the paradox.
Rayleigh radial thresholds and quantiles 2026-10-18
For , integration gives the survival function and cumulative distribution functionSolving gives the quantile function[ref]
The Rayleigh Distribution. Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist; The General Rayleigh Distribution, Distribution Functions: CDF, quantile and survival functions
For the chosen positioning model ,The disk of radius one component standard deviation therefore contains about 39.35% of outcomes; the familiar one-dimensional normal interval percentage does not apply to a two-dimensional disk. The 95% and 99% radial thresholds areA circle defined by itself still has probability zero; its enclosed disk carries the stated probability.

The closed-form quantile function also gives inverse transform sampling: if has uniform distribution on , then has Rayleigh distribution. Using instead gives the same law. Endpoints are excluded so that the logarithm stays finite.
Reactive strategy (game theory) 2026-10-14
A reactive strategy cooperates with probability after the opponent cooperated and probability after the opponent defected. It ignores its own previous action. Independent behavioural randomization gives a four-state joint-action Markov chain. The reduced marginal recurrences depend on the prescribed initial action distribution.
For normalized linearly independent pure states, their Gram matrix is positive definite. The displayed reciprocal vectors satisfy . The operator has nonzero eigenvalues equal to those of : use the polar factorization of the matrix whose columns are . Choosing gives the POVM effects and . Each conclusive outcome has probability on its own state and zero on every other input. The inconclusive effect preserves positivity, so the construction is a physical measurement in quantum mechanics.
Recombination fraction 2026-10-13
The recombination fraction is the probability that a transmitted gamete carries a recombinant haplotype between two specified genetic loci, relative to the parent's known haplotype phase. Write it as here; the symbol is also common in genetic linkage analysis. In the ordinary symmetric two-locus model, , with for complete genetic linkage and for independent assortment.
For phase-known genotype , fair Mendelian segregation and equal reciprocal gamete probabilities giveFor example, 1,000 independent informative transmissions with observed counts in this order have empirical recombination fraction . Those illustrative counts match the expected values in the toy model, but actual counts fluctuate. The genetic linkage diagram shows both the parental and recombinant classes, so their separate probabilities are not confused with the total .
The recombination fraction measures the probability of an odd number of origin switches along the transmitted chromatid. It is neither the expected value of the exchange count nor the probability of at least one exchange: even positive counts can be invisible at the two endpoints. Converting an observed recombination fraction to a genetic map distance therefore needs an explicit model such as the Haldane mapping function. The distinction between transmitted-chromatid counts and four-chromatid exchange counts is discussed in Weeks, Tang and Kwon (2009), Casares' map function: No need for a 'corrected' Haldane's map function, Genetica 135, 305–307.
Recovery of a continuous Brownian integrand from short increments Created 2026-10-05 Updated 2026-10-06
For a bounded continuous adapted process and a Brownian motion , converges in probability to as . The Itô isometry makes the error numerator small relative to ; the normal distribution of the denominator controls its chance of being too close to zero.
Rectangle crossing in bond percolation 2026-10-14
For the induced square lattice subgraph in , is the probability of an open graph path from its left boundary to its right boundary under independent bond percolation of density . Width and height count lattice spacings. Dual bond percolation exchanges failure with a top-to-bottom dual crossing of dimensions , with the usual exterior boundary vertices.