Source release: Oxford examination archive, member
2018/L/a10101w1.pdf. The dated cover identifies 3 September 2019 despite the archive directory. All eight questions are covered. The supplied Thumb references and proof rules are inputs to the solutions, rather than additional questions.Use a logical right shift to discard one inspected bit at a time. The following Thumb instruction set subroutine accepts the word in
r0, returns its population count in r0, preserves r4, and otherwise uses caller-saved processor registers.popcount_loop:
push {r4}
movs r1, #0
movs r2, #1
movs r3, #32
pop_loop:
movs r4, r0
ands r4, r4, r2
adds r1, r1, r4
lsrs r0, r0, #1
subs r3, r3, #1
bne pop_loop
movs r0, r1
pop {r4}
bx lrands extracts the current least significant bit; adds includes it in the count. lsrs fills the newly vacant high position with zero. subs immediately precedes bne, so the branch tests the zero flag from decrementing the loop counter, not a flag left by the shift.After iterations, the accumulator contains the number of one bits in the original word's lowest positions, and the remaining word is the original unsigned interpretation shifted right by . This loop invariant holds initially and is preserved by each iteration. At every position has been inspected, proving the result. The given example therefore returns 10, and the all-zero and all-one words return 0 and 32. The accumulator cannot overflow: it never exceeds 32.
Extract successive bytes into indices of the byte-table population count table. The last shift leaves only the original high byte, so that index needs no final mask.
popcount_table:
    push {r4}
    adr r2, popbyte
    movs r3, #255
    movs r1, r0
    ands r1, r1, r3
    ldrb r4, [r2, r1]
    lsrs r0, r0, #8
    movs r1, r0
    ands r1, r1, r3
    ldrb r1, [r2, r1]
    adds r4, r4, r1
    lsrs r0, r0, #8
    movs r1, r0
    ands r1, r1, r3
    ldrb r1, [r2, r1]
    adds r4, r4, r1
    lsrs r0, r0, #8
    ldrb r1, [r2, r0]
    adds r0, r4, r1
    pop {r4}
    bx lr
Place the byte table at an aligned nearby label in the instruction-address range of
adr. That instruction forms the table's address relative to the program counter; it does not load a table entry. Each ldrb uses register-offset addressing: the base is r2, the byte offset is the index register, and the loaded byte is zero-extended. Because entries occupy one byte, the index needs no scaling. ldrb r1, [r2, r1] uses the old r1 to form the address before overwriting it with the result.Every bit belongs to exactly one extracted byte, so adding the four table counts gives the whole word's population count, independently of endianness. The calculation reads four bytes from the table and contains no loop.
Count executed instructions, excluding the caller's branch-with-link and assuming the register-return and stack instructions shown above. The shift loop executes six instructions per iteration, plus four entry instructions and three exit instructions: instructions. The unrolled table subroutine executes 21 instructions, including four byte loads.
If every instruction, including a table load and a branch, costs one time unit, the ratio is in favour of the table version. A more informative simple model assigns cost to each table load and unit cost to the other displayed instructions: its cost is , versus 199 for the loop under the same unit branch assumption. Thus this model favours lookup when .
Real running time depends on the processor and memory system. Taken branches can incur extra instruction-fetch or pipeline costs, favouring the unrolled version; slow flash or cache miss events on the 256-byte table can erode that advantage. Instruction and table placement also matter. These assumptions prevent instruction counts from becoming an unsupported universal cycle claim. For a fixed 32-bit argument both implementations have constant worst-case work; the gain is a constant factor, not a different asymptotic class.
Let the new byte table store and, for , . Thus it stores the number of leading zeros in an eight-bit argument: , , and . All entries fit in one byte.
countlz:
    adr r3, lzbyte
    movs r1, #0
    lsrs r2, r0, #24
    bne lz_found
    movs r1, #8
    lsrs r2, r0, #16
    bne lz_found
    movs r1, #16
    lsrs r2, r0, #8
    bne lz_found
    movs r1, #24
    movs r2, r0
lz_found:
    ldrb r2, [r3, r2]
    adds r0, r1, r2
    bx lr
The high byte is tried first. A failed test proves that byte was zero, so the next right-shifted value is again a byte-sized index without masking: all higher bytes have already been proved zero. The offset in
r1 counts those skipped zero bytes in bits. Adding the table result for the first nonzero byte gives the leading-zero count. If every byte is zero, the last lookup contributes eight to the offset 24, giving 32. The example with high byte one gives 7. At most three conditional branches and one table read are needed; no per-bit loop is used.Give the hardware to a single device driver process. Other processes request a conversion through message passing and never touch its memory-mapped input-output registers. The following is protocol pseudocode for Phōs: its operation names specify their required semantics, rather than asserting an unverified spelling of a particular 2019 C interface. The hardware actions and the request/reply design are fully specified.
Use a FIFO queue of accepted requests, each containing its sender and a per-call token. Bind the device's interrupt to a persistent notification addressed to the driver before any conversion is started. A notification must remain pending if it arrives before the driver next waits; this is the lost-wakeup avoidance requirement. The driver receives both client requests and interrupt notifications in its event loop.
configure sensor and connect its interrupt notification to this process
TEMP_DATARDY := 0
clear stale pending interrupt notification
enable sensor interrupt and interrupt-controller delivery
pending := empty FIFO
active := none

forever:
    if active is none and pending is not empty:
        active := remove oldest request from pending
        TEMP_DATARDY := 0
        clear stale pending interrupt notification
        TEMP_START := 1

    event := wait for a request or persistent interrupt notification

    if event is REQUEST(sender, token):
        append (sender, token) to pending

    if event is sensor interrupt and active is not none:
        if TEMP_DATARDY != 0:
            value := TEMP_TEMP
            TEMP_DATARDY := 0
            acknowledge the interrupt through the OS interrupt mechanism
            send RESULT(active.token, value) to active.sender
            active := none
After receiving an idle-time request, the next loop iteration starts its conversion before waiting again. While a conversion is in progress, additional requests join the queue without starting another conversion. A completed reading is copied before its ready flag is cleared, and the next request cannot start until the current result has been delivered. Spurious or stale notifications do not complete a request unless the device's ready register confirms completion.
Clearing old status and notification precedes
TEMP_START; doing so afterwards could erase a very fast completion. The operating system interrupt binding and persistent notification cover completion in the interval between starting the device and entering the wait. Register accesses must use the platform's device-access semantics, including required volatile-qualified objects in C or ordering primitives. Exact initialization and interrupt-connection call names remain an implementation binding, not invented Phōs API calls. The later teaching site's named system is documented separately; it is not used as proof of an identical historical API.[ref]Digital Systems course archive of the University of Oxford. 2018–2019 course record and linked teaching-site description of process/message-based device drivers
Provide a blocking request-reply sensor conversion operation, using synchronous send-and-receive when the system supplies it:
get_temp():
    token := a new token for this process's call
    reply := request-and-wait(
        destination = temperature_driver,
        message = REQUEST(self, token),
        expected_reply = RESULT(token, value))
    return reply.value
Here
request-and-wait means sending the request and remaining ready to accept its matching response; it denotes a protocol action, not a claimed library symbol. Separate blocking send and receive operations are also adequate if they preserve the sender identity and the reply cannot be lost between them. With a synchronous reply, the driver simply waits until this client's receive is ready.The call returns only after the driver has selected this request, issued
TEMP_START, observed completion, read the new value and replied with the matching token. Each call therefore starts its own fresh conversion and returns its own result. It never returns a cached sample or another caller's reply. Local request and response storage belong to the calling process and are not a shared global message buffer.Safety: only the driver accesses the sensor, and
active identifies at most one conversion. Accepted requests are serialized by the FIFO queue. The reply destination and token identify the owner of the resulting sample; no caller can clear another conversion's ready flag or consume another result. Receiving new requests while busy only changes the queue, not the active measurement. These are mutual exclusion and request/result association properties, not timing guesses.Progress: assume each started conversion completes in finite time, the corresponding notification is eventually delivered, the driver and compliant clients are eventually scheduled, and pending message acceptance is fair. A caller remains ready to receive its reply. Every accepted request has finitely many earlier requests in the queue, and later arrivals cannot overtake it. Each earlier request is completed and removed in finite time, so the caller eventually becomes active and receives its own reading. Fair acceptance extends this argument from accepted requests to callers waiting to submit one.
These assumptions are necessary for starvation freedom. A failed sensor, a client that disappears before accepting a synchronous reply, or an unfair scheduler can prevent progress; serialization alone cannot prove otherwise. Under the stated operating model, simultaneous calls are safe and every call completes. A single shared “latest temperature” variable would not establish either a fresh conversion per call or correct reply ownership.
The two lower conducting branches are the series pairs controlled by and by . Their overall NMOS transistor conduction condition is . Apply complementary CMOS network duality: the upper network has the parallel pair of PMOS transistors controlled by , in series with the parallel pair controlled by . Its first end connects to the high rail, its last end connects to , and the junction between the two pairs is internal to the upper network.
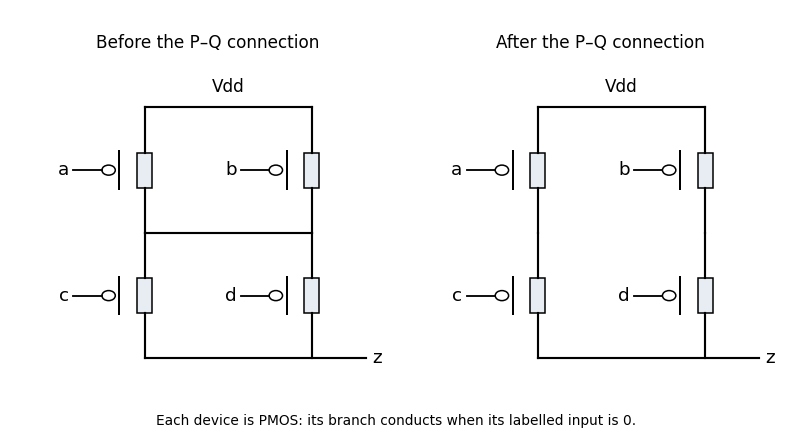
Original completed pull-up networks derived by complementary CMOS network duality
. Details. 
The left panel gives that completion. Every upper transistor uses its correspondingly named input and conducts when that input is low. Its conducting condition is , exactly the complement of the lower condition. Thus the ideal static circuit connects the output to one supply rail for every stable binary input.
The lower network pulls the output low exactly when either series branch conducts. Therefore the Boolean function isThe inversion is important: describes connection to the low rail, not a high output. The pull-up network found in part a implements the complementary high condition.
Joining the two middle nodes makes the upper lower-network transistors, controlled by , parallel with each other. The lower transistors, controlled by , are also parallel. These two parallel groups are in series, so the lower conducting condition becomes .
Its dual upper network must be two parallel branches, one containing the series PMOS transistor pair , the other the series pair . This is the right panel of the original drawing. Its condition is . Merely leaving the old upper network unchanged would break CMOS complementarity for some inputs, allowing a supply short rather than defining the required logic.
The modified output isFor example, gives and . Neither original series branch is complete, but the new connection supplies the cross-route through the transistors controlled by . Interchanging those roles gives the other cross-route example. In fact , so the modified circuit has added exactly those two possible lower conduction routes.
Let be the input sampled at clock edge . The desired registered output after that edge is . Only the last two high samples matter: a longer high run still has two high samples immediately before its first low sample.
A direct synchronous 110 detector uses three D flip-flops, holding , with a common clock and initial state zero. Use the following next-state equations, all evaluated from the old state and the input at the active clock edge:After an edge, records the latest sample and records whether the latest two samples were high. The final equation consequently produces the required pulse from the preceding two-high state and the new low sample. A synchronous reset sets all three state bits to zero. The output is the stored
z flip-flop value, so it changes only after clock edges; exposing the unregistered expression would let input transitions between edges alter the output.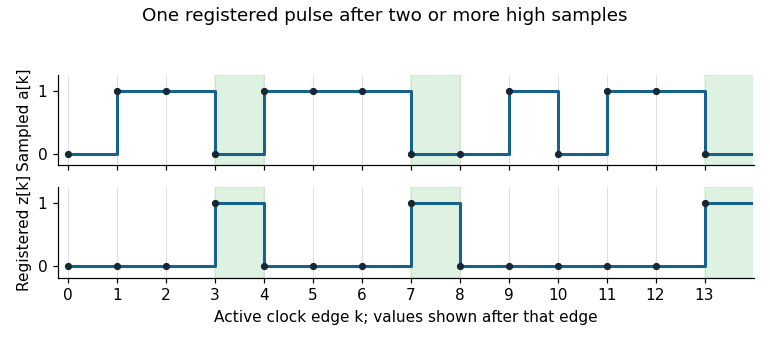
Original sampled-input and registered-output trace for a synchronous 110 detector
. Details. 
An equivalent finite-state machine has states
R (no current high run), H (one high), HH (at least two highs), and P (the pulse state). Its output is one only in P:The pulse cannot last two cycles: after the low input that creates it, is zero, so the next output is zero regardless of the next input. The detector rearms without a global stop and handles repeated patterns indefinitely. The three-flip-flop construction is deliberately direct; minimum storage was not required.
Subtract the first vertex from the other two, giving side vectors and . Their determinant is , the signed area of the corresponding parallelogram. The triangle occupies half that area, hence its area is . Taking the absolute value would remove any sign change caused by reversing the vertex order. This is the determinant formula for triangle area.
Let and . The remaining columns are and , so these two vectors span the column space. They are linearly independent: the determinant of their first two coordinates is . Therefore is a basis of the range, and the matrix rank is two.
Equivalently the range is the plane : both displayed basis vectors satisfy this equation, and their two-dimensional span fills that plane.
The independent-column representation gives . Thus a vector lies in the kernel of a linear map represented by this matrix precisely when and . Writing the two free coordinates separately givesThe two displayed vectors are linearly independent, so they form a basis of the kernel. Its dimension two also agrees with the rank-nullity theorem, .
If is , then is . The equation makes every standard basis vector of a linear combination of the columns of : take the corresponding column of as coefficients. Hence the column space is all of , giving . In particular, and has full row rank.
The system is consistent for every : take , since . Thus is a right inverse giving an explicit solution for every right-hand side.
All solutions are with in the kernel of a linear map represented by . The rank-nullity theorem gives kernel dimension ; the solution is unique when , and is nonunique when .
True. Transposing the inverse identities shows . If , this becomes , exactly the symmetric matrix condition. The reasoning uses the matrix inverse and transpose identities, without assuming that different matrix factors commute.
True. Using the same transpose identity and givesThe final equality follows by multiplying and in either order and obtaining the identity. Thus the inverse is a skew-symmetric matrix as well. The invertibility hypothesis is retained throughout.
True for these square matrices. The determinant multiplication identity gives . Since is invertible, its determinant is nonzero; both factors are therefore nonzero, so both matrices have matrix inverses.
Equivalently, must be injective and must be surjective, and either property implies invertibility for an endomorphism of a finite-dimensional vector space. The equal square dimensions matter: a rectangular matrix and a right inverse can have identity product without being mutually invertible square matrices.
True. The rank-nullity theorem gives . The only vector in this zero-dimensional kernel of a linear map is the zero vector.
False. Take , an , matrix of matrix rank one, and . Then never equals . Full column rank implies injectivity, not surjectivity onto a larger codomain.
True. A square matrix with matrix rank is invertible, and its transpose has the same rank. Applying the rank-nullity theorem to both and gives nullity zero in each case, so both kernels are .
False. Triviality of gives , while triviality of gives because transpose preserves matrix rank. Both conditions therefore force , contradicting the stated unequal dimensions.
Choose independent columns of that form a basis of its column space, and put them in . For each column of , let be its coordinate vector in that basis; put these coordinate vectors in . The column equations give .
By construction has full column rank . The columns of corresponding to the selected basis columns are the standard vectors of , so has full row rank . This proves the requested rank factorization. When , and the corresponding empty-column and empty-row factors have the required shapes and rank zero.
Not unique in general. For any invertible matrix ,is another rank factorization, with the same full ranks. This is a change of basis in the intermediate -dimensional space. For example, even has different full-rank factors. Once a particular ordered basis is fixed, its coordinate matrix is unique; it is the basis choice that creates the freedom.
For the first matrix choose its single independent column:Their product has every column equal to , and both factors have rank one.
For the second matrix, the first and third columns are independent and the second equals the first, givingMultiplication reconstructs the stated matrix. The first factor has independent columns and the second has independent rows, so both have matrix rank two, as required for a rank factorization.
The two square products can have different sizes, but their matrix traces are both the same finite double sum:Interchanging two finite sums and commuting their scalar factors is valid over the real numbers. No commutation of the matrix products themselves is asserted. This proves the cyclic property of the trace in the rectangular-factor case.
Let . If , the matrix is zero and the identity is immediate. Otherwise choose the rank factorization from part b. The column space of is the image of .
An idempotent matrix acts as the identity on its image: if , then . Applying this to each column of gives . Substituting yields . Since has full column rank, the represented map is injective, so each column of is zero. Thus .
Now the rectangular cyclic property of the trace givesThis proves that the trace of an idempotent equals its rank using the supplied factorization method. Orthogonality of the projection is unnecessary: the argument applies to every real idempotent matrix.
The characteristic polynomial isThus the eigenvalues are 1 and 11. Corresponding eigenvectors are and . Their dot product is zero and each has Euclidean norm . Normalizing givesThe columns are orthonormal, so . The eigenvector equations give and hence , proving the claimed orthogonal diagonalization of a real symmetric matrix.
Set . Because is an orthogonal matrix, and exactly when . The preceding diagonalization givesConsequently , with equality only when . The matrix is a symmetric positive-definite matrix, not merely positive semidefinite. In the original coordinates the same identity iswhich also makes positivity transparent.
Real symmetry and positive definiteness are sufficient, and the preceding parts establish both properties for this matrix. If a residual becomes zero, stop: the solution has been reached and the displayed step quotient should not be evaluated as .
For a convergence justification, let solve , let , and let . The quadratic energy error is . Moving by , with , is exact line search for a positive-definite quadratic and givesWriting for the extreme eigenvalues, one has and . ThereforeThe factor lies below one, so the energy tends to zero and positive definiteness forces . Here the bound is , since the eigenvalues are 1 and 11. This proves convergence for every initial vector, rather than merely checking one numerical iteration.
From the zero initial vector, the linear-system residual is . Then , , and . The step is , givingAs a check, the new residual is , orthogonal to the preceding residual as expected after this exact line search. It is nonzero, so one iteration has not already solved the system.
The normal equations for linear least squares areThe supplied QR decomposition gives full column rank because is invertible and . Hence, for every nonzero , . Thus is a symmetric positive-definite matrix and the displayed square system is nonsingular.
Substitution gives . Since is invertible, cancel it on the left to obtain the nonsingular triangular systemThis is the reduced QR least-squares solution. Its geometric justification is the orthogonal decompositionThe second term is independent of , while invertibility of lets the first term be zero at exactly one point. Although , one must not replace by : is tall and its product is the orthogonal projection onto its column space.
The supplied factors give . Back substitution in yields and , soMultiplying by the original matrix gives , so this least-squares minimizer has residual zero: this particular overdetermined system is exactly consistent. Full column rank still guarantees uniqueness of the minimizer.
- The implication introduction rule assumes locally, derives under that assumption, then concludes while discharging the temporary assumption.
- The disjunction elimination rule uses and two local cases: one derives a common conclusion from , and the other derives that same from . It concludes and discharges both case assumptions.
- The negation introduction rule assumes locally and derives logical falsity. Discharging that assumption gives .
The boxes delimit a subproof and identify the lifetime of its temporary assumptions. A result depending on a boxed assumption is available inside that box and its nested boxes; it cannot simply be exported outside. The enclosing rule specifies what may be exported and which assumptions are discharged. Other premises on which the derivation depends remain undischarged. This assumption discharge discipline distinguishes a conditional argument from an unconditional proof.
Derive each negated component in its own subproof, then combine them. Assumption lines below begin local scopes; the listed discharge ranges close those scopes.
| Line | Formula | Justification |
|---|---|---|
| 1 | Premise | |
| 2 | Assume locally | |
| 3 | Disjunction introduction rule, left, 2 | |
| 4 | Negation elimination rule, 1 and 3 | |
| 5 | Negation introduction rule, discharging 2–4 | |
| 6 | Assume locally | |
| 7 | Disjunction introduction rule, right, 6 | |
| 8 | Negation elimination rule, 1 and 7 | |
| 9 | Negation introduction rule, discharging 6–8 | |
| 10 | Conjunction introduction rule, 5 and 9 |
Only the original premise remains open. No classical principle is needed for this direction of De Morgan's laws.
Assume the conjunction and obtain a contradiction in each of the two cases supplied by the premise:
| Line | Formula | Justification |
|---|---|---|
| 1 | Premise | |
| 2 | Assume locally | |
| 3 | Conjunction elimination rule, left, 2 | |
| 4 | Conjunction elimination rule, right, 2 | |
| 5 | Assume first case | |
| 6 | Negation elimination rule, 3 and 5 | |
| 7 | Assume second case | |
| 8 | Negation elimination rule, 4 and 7 | |
| 9 | Disjunction elimination rule, 1, 5–6 and 7–8 | |
| 10 | Negation introduction rule, discharging 2–9 |
The two case assumptions disappear at line 9, while the conjunction assumption remains available until line 10. The proof uses only the primitive rules printed in the paper.
The supplied double-negation elimination rule provides the classical step needed to recover each positive component:
| Line | Formula | Justification |
|---|---|---|
| 1 | Premise | |
| 2 | Assume locally | |
| 3 | Disjunction introduction rule, left, 2 | |
| 4 | Negation elimination rule, 1 and 3 | |
| 5 | Negation introduction rule, discharging 2–4 | |
| 6 | Double-negation elimination, 5 | |
| 7 | Assume locally | |
| 8 | Disjunction introduction rule, right, 7 | |
| 9 | Negation elimination rule, 1 and 8 | |
| 10 | Negation introduction rule, discharging 7–9 | |
| 11 | Double-negation elimination, 10 | |
| 12 | Conjunction introduction rule, 6 and 11 |
Both local negated assumptions have been discharged. The proof establishes the positive conjunction without assuming an unproved derived version of De Morgan's laws.
Write for . The following derives Peirce's law directly from the printed primitive rules, including double-negation elimination:
| Line | Formula | Justification |
|---|---|---|
| 1 | Assume for the final implication | |
| 2 | Assume locally | |
| 3 | Assume inside the scope of 2 | |
| 4 | Negation elimination rule, 2 and 3 | |
| 5 | Logical falsity elimination rule, 4 | |
| 6 | Implication introduction rule, discharging 3–5 | |
| 7 | Implication elimination rule, 1 and 6 | |
| 8 | Negation elimination rule, 2 and 7 | |
| 9 | Negation introduction rule, discharging 2–8 | |
| 10 | Double-negation elimination, 9 | |
| 11 | Implication introduction rule, discharging 1–10 |
Every assumption is discharged, so the last formula is a theorem. In particular, no unproved appeal to the derived
RAA rule is hidden in the argument.In a finite domain , a true existential premise says that at least one satisfies . The subproof treats its witness as an unknown object named , derives without relying on which object was chosen, and can therefore be applied to the actual witness. Thus follows whenever the existential premise is true. This argument does not require knowing the domain's size or selecting a particular named element in advance.
The existential quantifier elimination rule in sequent form records the same assumption discharge: a derivation of yields . The natural-deduction box represents the temporary witness assumption that the sequent rule replaces by the existential premise.
The eigenvariable condition requires that have no free occurrence in the other undischarged assumptions, the existential premise or the exported conclusion . Bound occurrences can be renamed harmlessly. This freshness condition keeps from denoting a previously special object and prevents witness escape. Without it, one could export from , falsely asserting that an arbitrarily named object has the witness property. A two-element domain with only one element satisfying supplies an immediate counterexample.
Articles were limited to the first 100 out of 813 total.
Articles by others on the same topic
There are currently no matching articles.