Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Binomial coefficient
In the Heisenberg group over a commutative ring with , the subset is an Abelian subgroup of group order 16. Its product has central coordinate , symmetric in the two factors. Its inverse element is . The map is a surjective group homomorphism to the additive group of , with kernel of a group homomorphism . Thus is a normal subgroup and has four cosets in the 64-element group.
Unlike the odd-prime case, division by two is unavailable. In fact take and . Then , where the binomial coefficient is computed as an integer before reduction modulo four. Hence and has element order eight. The element has element order two and is not a power of : the powers with outer coordinates two have central coordinates one or three. Their generated subgroups intersect trivially, so the 16-element Abelian group is the direct product of groups .
Alternating binomial moment Created 2026-10-06 Updated 2026-10-14
For nonnegative integers , the alternating binomial moment satisfies when and . Expand the polynomial in falling factorials and differentiate the binomial theorem to prove these identities. Equivalently, alternating binomial coefficients implement a finite difference that annihilates polynomials of degree less than .
Base-p expansion 2026-10-06
For an integer base , a nonnegative integer has a finite positional representation with digits . Repeated Euclidean division gives the digits uniquely; appending zero high-place digits has no effect. The base need not be prime for uniqueness, but a prime base is useful in Lucas theorem and modular binomial coefficients.
Bayes factor Created 2026-09-28 Updated 2026-10-18
A Bayes factor measures how data change the relative support for two specified statistical models. Write for their Bayesian model evidence and define the direction explicitly:For positive finite , a value above one favors over ; a value below one favors over . Reversing the comparison gives , the opposite direction used in some formulas below.
For mutually exclusive, exhaustive with positive prior probabilities, divide their two Bayes' theorem formulas. Their common data normalizer cancels, leavingThe Bayes factor therefore multiplies prior odds into posterior odds. It is evidence conditional on the specified statistical models and their within-model prior distributions; it is not . Model prior probabilities supply a separate input.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Kass and Raftery, Bayes Factors (1995), section 3.1, p. 776: posterior odds, prior odds, and direction of the Bayes factor
For an original stipulated example, consider ten independent and identically distributed Bernoulli trials, with heads as success. Compare with , both fixed before seeing the data. Take to be one particular ordered sequence containing eight heads and two tails. The likelihood function under either point model is , soIf , the prior odds for against are . Hence the posterior odds are , andEqual model prior probabilities would instead give . The same Bayes factor can thus accompany different posterior probabilities. These statements condition on the two-model comparison; they do not establish that either statistical model describes a real coin.
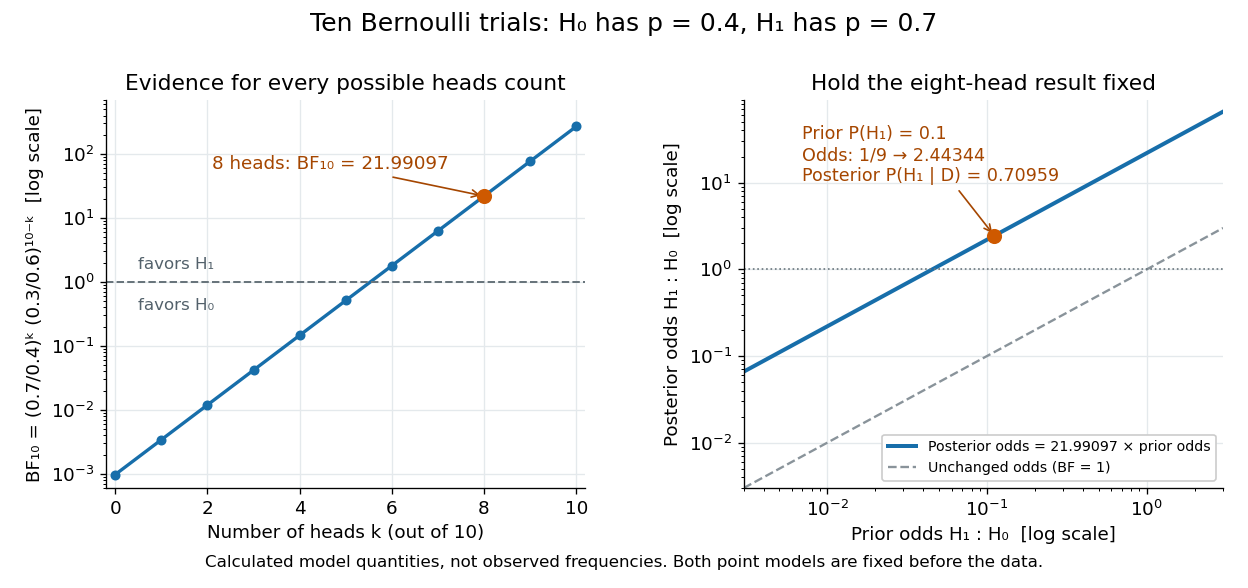
Using the heads count instead of the ordered sequence changes the sample space. The binomial distribution assigns it mass . The same binomial coefficient multiplies both models' Bayesian model evidence and cancels in their Bayes factor. Mixing an ordered-sequence numerator with a count denominator would introduce an erroneous factor of .
Fix the candidate statistical models, their parameter prior distributions, and model prior probabilities before using the current data for this update. The Bayes factor is useful because it separates evidence from model prior odds, but it still depends on the parameter prior distributions. An improper prior has an arbitrary multiplicative normalization: multiplying its kernel by multiplies its formal marginal likelihood by , even if the within-model posterior distribution is normalizable. Without a separately justified convention, the ordinary Bayes factor is then undefined up to arbitrary constants.[ref]
Bayes Factors by Robert E. Kass and Adrian E. Raftery. Kass and Raftery, Bayes Factors (1995), sections 5.2–5.3, pp. 782–783: prior sensitivity and undefined multiplicative constants
Bernoulli number Created 2026-10-05 Updated 2026-10-13
The Bernoulli numbers are a sequence of rational numbers that turns integer power sums into exact polynomials. The same numbers describe corrections when a discrete summation is compared with an integral. For example, the sum of squares is : the leading term is an integral, while the last two terms repair the difference between area and sampled values.
We use throughout. The defining exponential generating function isHere is the exponential function and is a factorial; in particular, the coefficient of is , rather than . At the quotient has limiting value one. The identity can be read algebraically as a formal power series, or as a convergent series for .[ref]
NIST Digital Library of Mathematical Functions. Karl Dilcher, Chapter 24, §24.2(i), equation 24.2.1: defining generating function and convergence domain
To compute the numbers, multiply by and compare coefficients. The resulting recurrence relation, with binomial coefficients, isThus , , and give , , and . Continuing givesThe recurrence relation agrees with equation 24.5.3 after replacing its index by .[ref]
NIST Digital Library of Mathematical Functions. Karl Dilcher, Chapter 24, §24.5(i), equation 24.5.3; first values also in Table 24.2.1
Why do so many values vanish? Put . Direct substitution gives , so is an even function. Its odd power series coefficients vanish: for every positive integer . The exception matters. The alternative convention obtained from has and exactly the same other values. A formula copied between conventions must also retain its summation endpoints.
Historically, integer power sums were studied before the modern Bernoulli number notation. A historical study examines formulas published in 1631 and distinguishes those separate formulas from encoding all exponents using one sequence of constants. This is a useful motivation for the generating function, without assigning all discovery to a single moment. [ref]
Johann Faulhaber and sums of powers by Donald E. Knuth. Donald E. Knuth, Johann Faulhaber and sums of powers, 1992 preprint, pp. 2 and 14: the 1631 power-sum formulas and the uniform Bernoulli-number formula
Bernoulli typical-set example 2026-10-14
Take an IID random variable source of bits with . Its binary entropy isA word of length containing ones has probability . Its information content per symbol isThus weakly typical sequences for this biased source have near . With tolerance bits per symbol, the exact condition isFor , this includes exactly . There are words with each count: a type class with that many possible orderings. Summing the counts and their probability masses givesThese are fewer than one percent of the possible words, yet they carry nearly 64 percent of the probability. The most likely individual word is all zeros, with probability ; it is outside this typical set. No contradiction is involved: the type classes near ten ones each contain many more individual words.
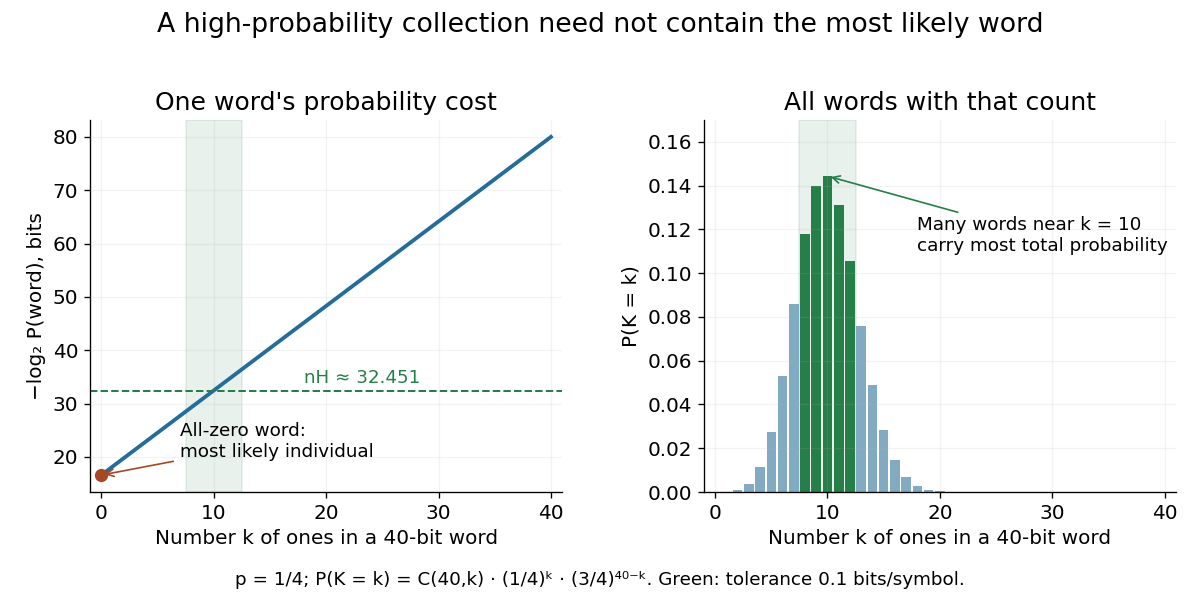
The most likely individual word differs from the counts carrying most probability
. The left plot gives the information content of one word with each number of ones. The right includes the binomial coefficient counting every such word, giving the exact binomial distribution of the count. Both use , ; the green band marks the typical set with tolerance bits per symbol. Details. Beta integral 2026-10-20
For positive real numbers , the beta integral represents the beta function by . In particular, for nonnegative integers , it gives , connecting integration to binomial coefficients.
Bézier curve 2026-10-14
A Bézier curve is a parametric curve specified by control points in a Euclidean space and the Bernstein basis:Here is a binomial coefficient. Each coordinate is a polynomial of polynomial degree at most ; special choices of control points can lower the polynomial degree. The ordered control points form the control polygon. A cubic Bézier curve uses four control points and has the explicit formThe curve passes through and ; the interior control points steer its shape and need not lie on it.[ref]
https://ocw.mit.edu/courses/6-837-computer-graphics-fall-2012/aba8735cf2cf7c71ca5d29b46873309a_MIT6_837F12_Lec01.pdf. MIT 6.837, Bézier Curves and Splines, slides 23–31 and 45–47, 2012
For a worked example, chooseSubstituting these control points givesHere , so neither interior control point, both at height , lies on the curve. De Casteljau's algorithm computes the same point using only successive linear interpolations.
The endpoint tangent vectors follow from the Bézier derivative control polygon:Thus the curve leaves toward and arrives at from . These nonzero derivatives determine the endpoint tangent lines; if an endpoint derivative vanishes, that formula alone does not determine its tangent direction. Endpoint handles are useful when arranging a parametric first-derivative join of Bézier curves.
The parameter is usually not arc length. For this example,Equal steps in therefore do not generally travel equal distances. Distance along the curve is instead the arc length, given by the integral ; its derivative is the norm of the tangent vector and measures the rate of travel.
Two geometric facts make Bézier curves especially convenient for design. First, the Bernstein basis weights are nonnegative and form a partition of unity, since the binomial theorem gives . Hence is a convex combination of the control points and lies in their convex hull.[ref]
https://groups.csail.mit.edu/graphics/classes/6.838/S98/meetings/m15/. MIT 6.838, Bézier Curve and B-Spline Curve, §1.4.1, 1998
The convex hull is the smallest convex set containing the control points, not their axis-aligned bounding box. Here it is a trapezoid, strictly smaller than : the box corner is outside the convex hull. The curve need not fill or touch every edge of either enclosure. The convex hull guarantee concerns ; outside that interval weights can be negative.Second, applying an affine map to every control point gives exactly the same result as applying it to the entire curve. For ,This is affine equivariance of a geometric basis: a translation, rotation or shear mapping can be performed on a handful of control points. For example, transforms the four control points to and transforms the midpoint to , also obtained from the same weights .
These editable handles explain the usefulness of Bézier curves in computer aided geometric design, vector graphics paths and outline fonts: a small collection of points controls an entire smooth stroke, and resizing the design preserves its mathematical shape. Cambridge's computer-graphics notes describe their use in graphic design, typography and PostScript outlines. The industrial context includes Pierre Bézier's work at Renault and Paul de Casteljau's work at Citroën.[ref]
https://www.cl.cam.ac.uk/teaching/1415/CompGraph/cgip.pdf. Neil A. Dodgson and Peter Robinson, Cambridge Computer Graphics and Image Processing, slides 183 and 226–228, 2014
// Target: analysis.bigb
Binomial coefficients with even interior terms Created 2026-10-05 Updated 2026-10-06
For a positive integer , all binomial coefficients with are even exactly when is a power of two. Write the binary expansion . In the polynomial ring , repeated squaring givesIf has one element, there are no interior terms. If it has more than one, the coefficient of is one and that exponent lies strictly between zero and . This characterization gives a useful parity obstruction directly from the binary expansion.
Binomial distribution Created 2026-09-24 Updated 2026-10-14
The binomial distribution counts successes in a fixed number of independent Bernoulli trials with common success probability . Equivalently,Here is a nonnegative integer and . The binomial coefficient counts placements of the successes; each particular arrangement has probability . The binomial theorem makes the masses sum to . At all mass is at zero, and at all mass is at ; these endpoint laws can be read directly without interpreting .
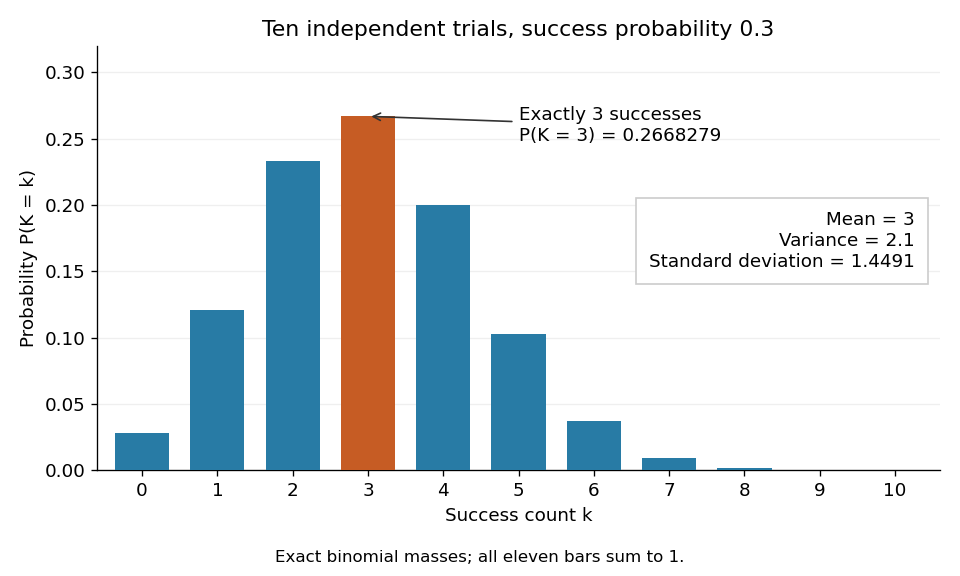
The linearity of expectation and addition of variances for independent random variables giveThe fixed trial count, common success probability, and joint independence are substantive model assumptions. Sampling uniformly without replacement from a finite population instead leads to a hypergeometric distribution. Independent trials with different success probabilities generally give a Poisson binomial distribution. Common marginal success probabilities alone are insufficient: if all ten indicators equal the same Bernoulli random variable with , their sum is zero with probability or ten with probability . Its mean is still three, but its variance is . The standard construction is given in Penn State STAT 504, binomial distribution.
For an exact constructed example, let each of ten independent trials choose uniformly from ten labelled tokens, with replacement, and mark three tokens as successes. Then and . Exactly three successes have probabilityThe mean is , the variance is , and the standard deviation is . Zero successes have probability , so at least one success has probability . A single count calculation replaces enumeration of all equally likely token sequences.


Binomial expansion 2026-10-20
The binomial expansion expresses as for a nonnegative integer . The binomial coefficients give the number of ways to choose which factors supply .
Binomial polynomial 2026-10-05
For , define and . The binomial coefficient formula shows for every nonnegative integer . Since these integers are dense in the p-adic integers, continuity of the polynomial implies , so it is an integer-valued polynomial there and . The Pascal's identity gives for the forward difference operator.
Binomial probability Created 2026-10-18 Updated 2026-10-20
The binomial distribution with parameters and assigns the displayed probability to successes, for integers . Each specified sequence of independent trials has probability , and the binomial coefficient counts the sequences with exactly successes. Outside this range the probability is zero.
Boltzmann entropy of a two-box occupancy Created 2026-10-14 Updated 2026-10-18
Take distinguishable, labeled particles and two boxes of equal volume. Retain only whether each particle is in the left or right box: use a bit for left and for right. Each length-20 string is one coarse microstate of this toy model. Assume the labels make independent side choices with equal probability, so the strings are equiprobable. Equal volumes motivate these weights for noninteracting particles with no preference for either box; equal volumes alone would not establish them for an arbitrary interacting gas.
Now retain only the number in the left box as the macrostate. Choosing which labels are left gives a binomial coefficient, soThe factorials count assignments to labels; the probability of a macrostate sums the probabilities of its constituent microstates. This is the binomial distribution with parameters and . The same binomial coefficient appears in the counting of distinguishable two-level systems, although here the macrostate records occupancy rather than energy. [ref]
https://ocw.mit.edu/courses/8-333-statistical-mechanics-i-statistical-mechanics-of-particles-fall-2013/0cb99318c2ed889316cdcff839759e8d_MIT8_333F13_Lec12.pdf. Mehran Kardar, MIT 8.333 (2013), lecture 12, §IV.C, equations IV.17–18: binomial microstate counts
The largest binomial coefficient occurs at , the balanced macrostate. All-left means and supplies just one string. ThusThere are balanced strings for every all-left string, even though each individual string has the same probability. Exact balance has about of the total probability; equilibrium reasoning concerns the many macrostates near balance too, rather than certainty of exactly ten particles on each side. The diagram compares the counts with their natural logarithms.
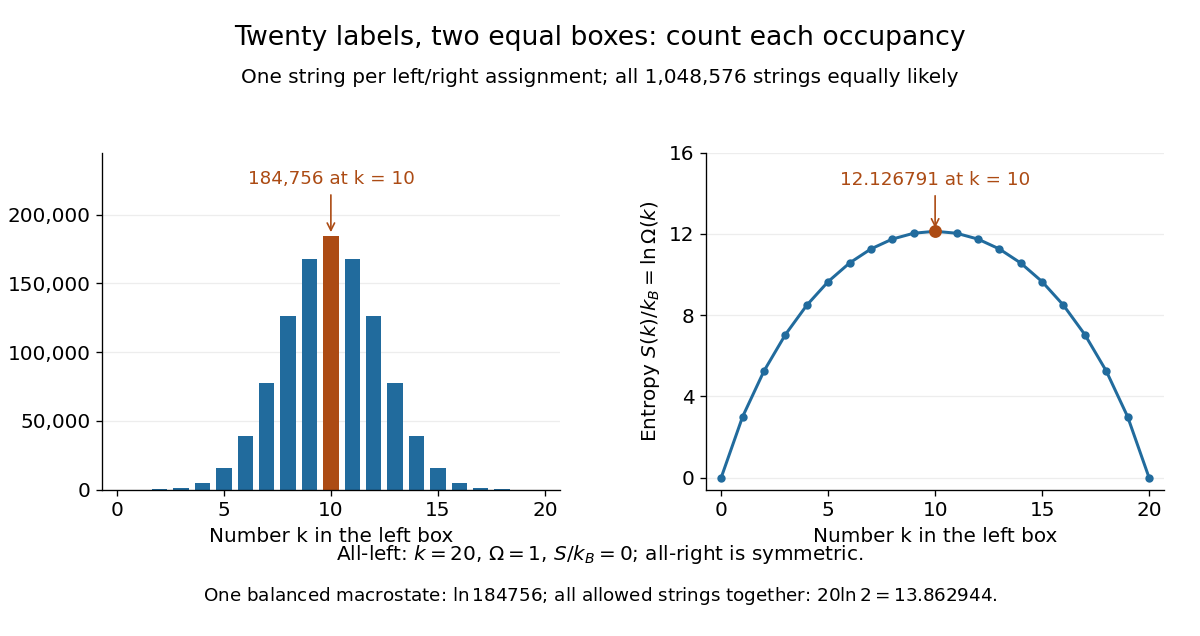
Counts and Boltzmann entropies of the occupancy macrostates of twenty labeled particles
. Details. 
Four fair, independent coins give a smaller worked example with the same binomial distribution. If is the number of heads, the five macrostates contain respectively microstates. Their probabilities are respectively . In particular, two heads is one macrostate containing six ordered coin sequences, with Boltzmann entropy in this counting analogy. A prescribed ordered sequence has one realization. The next diagram enumerates the same sixteen strings as left/right assignments.
Capture-recapture model 2026-10-14
A capture-recapture model is a statistical model for repeated observations of identifiable individuals, including those missed on some occasions. A closed-population capture-recapture model estimates a fixed population cardinality; models allowing individuals to enter or leave can instead describe survival and recruitment. The sampling assumptions determine which likelihood function is appropriate.
For the two-sample closed-population capture-recapture model, condition on the sample sizes and . If the second sample selects distinct individuals from by simple random sampling, then the overlap has the hypergeometric distribution:Here is an integer and the probability mass function is zero outside these bounds. The binomial coefficients count choices of marked and unmarked individuals, divided by all equally likely size- subsets. The hypergeometric distribution has expected valueEquating the observed overlap with this expected value gives the Lincoln-Petersen estimator. The underlying sampling without replacement, probability mass function, and expected value are developed in Raymond P. Guiteras, MIT 14.30 hypergeometric distribution handout, §§1–4 and 8.
For the toy counts , , and , hold the observations fixed and vary the unknown integer . The likelihood function isValues below forty cannot contain the observed set union. Exact comparison of consecutive likelihoods gives two tied maximum-likelihood estimates, and . The Lincoln-Petersen estimator returns ; the Chapman estimator returns and is a different rule for estimation.
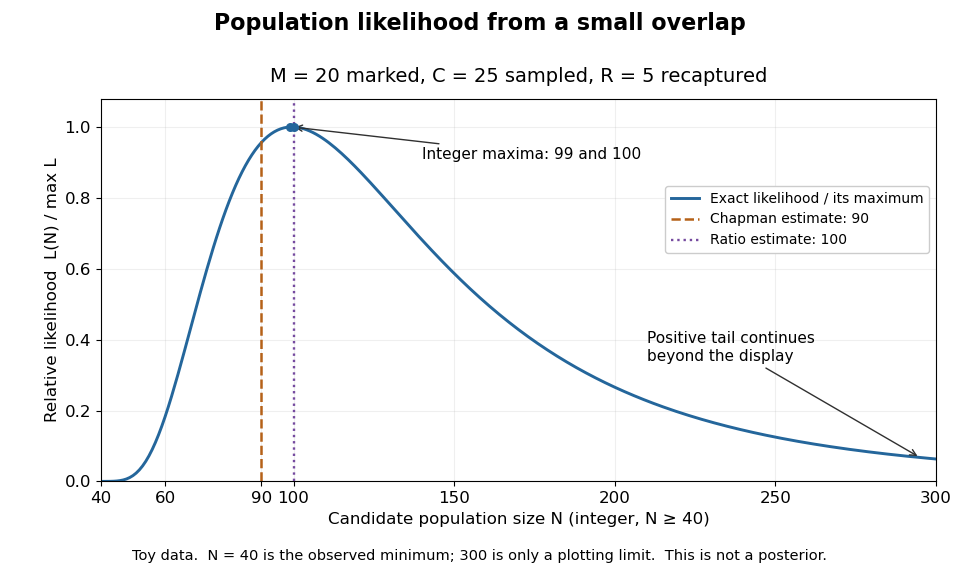
Relative likelihood for the toy overlap: integer maxima at 99 and 100, ratio estimate 100, and Chapman estimate 90
. Details. 
The vertical scale is . This relative likelihood compares how well candidate statistical parameters explain the same observations; it is not a posterior probability. The displayed range is only a plotting window. The likelihood function remains positive for every integer and tends to zero as increases, so the curve has a continuing right tail. The data do not justify truncating statistical inference at three hundred. The conditional hypergeometric distribution formulation also appears in Louis-Paul Rivest and Mamadou Yauck, Small Sample Estimators for Two-way Capture Recapture Experiments, §3, equation (5).
Zero recaptures require care. With and positive , the Lincoln-Petersen estimator has no finite ratio, but the capture-recapture model still gives a valid likelihood function:This likelihood function increases toward one as grows, so there is no finite maximum-likelihood estimate. For the same sample sizes twenty and twenty-five with zero overlap, forty-five distinct individuals would be observed. Lack of overlap supplies a lower bound but very weak information about large population cardinalities.
In more elaborate capture-recapture models, a first-recapture array counts individuals released at occasion and next observed at . A probability of survival and a probability of detection contribute a no-observation continuation factor . The resulting likelihood function depends on both survival and detection; these probabilities need not be separately identifiable at the last observation interval. Missing-count EM for capture-recapture describes one way to fit such a model, and identifiability remains a separate issue from computing an estimator output.
Central limit theorem Created 2026-09-24 Updated 2026-10-14
Let be real independent and identically distributed random variables with expected value and finite, strictly positive variance . Write and for their sum and sample mean. The central limit theorem statesPrecisely, for every real ,where is the standard normal distribution function. The conclusion is convergence in distribution to the standard normal distribution. If the variance is zero, every observation equals almost surely; the displayed normalization is then undefined and there is no fluctuating error to describe.
The striking feature is that the observations need not have a normal distribution. They may be binary, bounded, or strongly skewed. Their detailed probability distribution disappears from this limit except through the expected value and variance. The subtraction removes predictable growth: . The division implements variance normalization: variance additivity for independent random variables gives , so every has expected value zero and variance one. For nonzero , an uncentered sum drifts; without rescaling its spread grows.
For a concrete example, let each have a Bernoulli distribution with success probability . Then has a binomial distribution, with expected value and variance . Its exact probability mass function and its normalized count areHere is a binomial coefficient. Individual trials are conspicuously skewed, yet their centered, rescaled counts approach the same standard normal distribution as sums of fair trials.
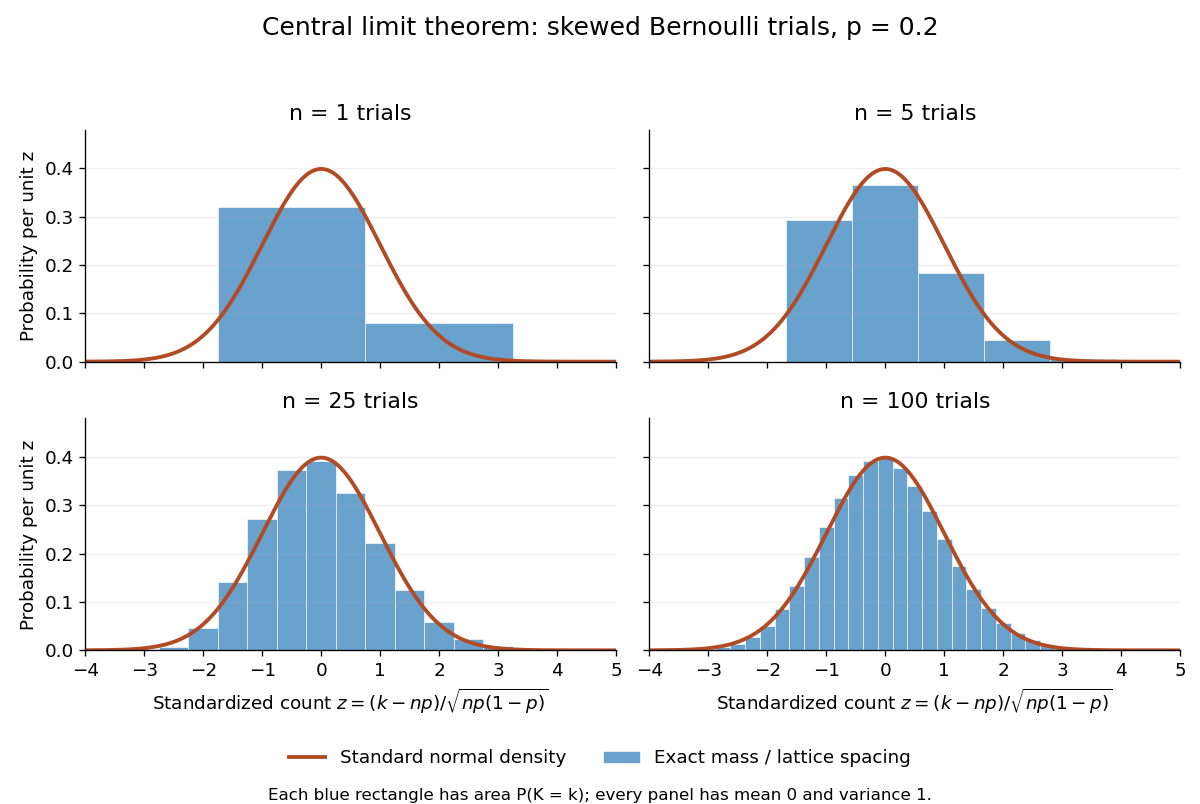
Exact standardized binomial distributions approach the standard normal curve
. For independent Bernoulli trials with , each blue bar has width equal to the normalized lattice spacing and area equal to the exact binomial distribution mass at its center. Heights are mass divided by spacing, so they can be compared with the orange probability density function of the standard normal distribution. All four normalized counts have expected value zero and variance one. The rectangles visualize discrete masses; they do not make the discrete probability distributions continuous. Details.
At , has expected value and standard deviation . The exact binomial distribution gives . A normal approximation with the continuity correction uses the interval to :The small discrepancy is an approximation error, not an equality supplied by the central limit theorem.
The strong law of large numbers and weak law of large numbers locate the average: , respectively by almost sure convergence and convergence in probability. The central limit theorem magnifies that shrinking error and describes its shape. In terms of the sample mean, the resulting normal approximation is , with standard error . This explains why four times as many independent observations halve the standard error. When is known, has approximately coverage for at large , giving a confidence interval. This coverage refers to repeated samples, not a guarantee for an individual interval.
A useful application is the Monte Carlo method: estimate a success probability by the proportion of successful simulated trials. Nicholas Metropolis and S. Ulam's original paper, "The Monte Carlo Method" (1949), illustrates this with games of solitaire and estimation of a region's volume by randomly selected points, and discusses why estimates require probabilistic error control. The strong law of large numbers justifies convergence of such proportions for independent repetitions; the central limit theorem supplies their large-sample error scale when .[ref]
https://hedibert.org/wp-content/uploads/2013/12/1949MetropolisUlam.pdf. Metropolis and Ulam, The Monte Carlo Method, JASA 44 (1949), 335–341, especially pp. 336–337
There are three useful limits to this picture:
- A heavy-tailed distribution can have infinite variance, so the displayed hypothesis must be checked. A Pareto distribution with minimum one and shape has finite expected value three but infinite variance. The strong law of large numbers still applies, but the stated central limit theorem does not. More dramatically, the Cauchy sample mean has an unchanged distribution: even averaging need not concentrate when the expected value is undefined. A heavy-tailed distribution with finite variance is allowed by the stated central limit theorem.
- Independence matters. If all equal the same nonconstant Bernoulli random variable, then and . There is no accumulation of new information, and the variance of the sum grows like , not . Other versions of the central limit theorem can allow dependence, but require hypotheses controlling it.
- Convergence in distribution is a limiting assertion, with no universal sample size or error rate under finite variance alone. It does not automatically give accurate relative estimates of very small tail probabilities. Nor does it mean that discrete point masses converge as probability density functions: a binomial distribution remains discrete for every finite . If the success probability changes with so that and , the relevant result is the Poisson limit theorem, rather than the fixed- argument above.
A historical original-paper reference is J. W. Lindeberg's "Eine neue Herleitung des Exponentialgesetzes in der Wahrscheinlichkeitsrechnung" (1922), published in Mathematische Zeitschrift 15, pp. 211–225. The Lindeberg condition and Lindeberg-Feller central limit theorem below describe a version for sums whose summands need not share a probability distribution.[ref]
https://doi.org/10.1007/BF01494395. Lindeberg, Eine neue Herleitung des Exponentialgesetzes in der Wahrscheinlichkeitsrechnung (1922)
A brief proof outline uses the characteristic function of . Its expected value is zero and its variance is one, so the finite second moment givesThe Taylor expansion of the complex exponential, with its remainder controlled by , and the dominated convergence theorem justify this step without a third-moment assumption. Independence then gives the characteristic function of :The limit is the characteristic function of the standard normal distribution; the Lévy continuity theorem turns this into convergence in distribution.
The central binomial coefficient satisfies . Prime factors between and give a dyadic upper bound for the Chebyshev theta function. The prime-power exponents in the factorial quotient are sums of zeros and ones, so the central coefficient gives a linear lower bound for the Second Chebyshev function. Higher prime powers contribute only ; hence the prime-counting function has upper and lower bounds of order .
Suppose a continuous map changes sign on negating either input. Its quotient pulls back the real tautological line bundle to the tensor product of vector bundles . The fiber map sends to . The First Stiefel–Whitney class of a tensor product of real line bundles consequently gives . The Künneth theorem and the mod-two cohomology ring of real projective space implyEvery interior binomial coefficient in row must be even. By binomial coefficients with even interior terms, for some . This is a necessary condition, not an assertion of existence in every such dimension.
Combination (combinatorics) 2026-10-20
Combinatorics Created 2026-09-24 Updated 2026-10-13
Combinatorics studies discrete structures through counting, construction, and extremal questions. Its objects include subsets, permutations, graphs, and set partitions. The question is often easy to ask: how many teams can we choose, how many arrangements avoid a collision, or how few connections are enough? The challenge is to organize the possibilities so that every permitted object is counted exactly as intended.
For example, choosing two people from five gives ten teams. Choosing a captain and deputy from those same five gives twenty assignments. The difference is whether order is part of the object: a team is a subset, while the two named roles distinguish an ordered pair. The binomial coefficient and the rule of product encode these two counting problems. Choosing the right objects comes before manipulating a formula.
The beauty is that a change of viewpoint can turn enumeration into an explanation. Double counting connects two descriptions of one collection; Pascal's identity splits a selection into cases; the inclusion-exclusion principle repairs overlapping counts. These methods also supply exact finite models for probability and help measure the possibilities an algorithm must handle. Richard Stanley's textbook introduces the subject through counting questions and then develops these general tools. [ref]