Probability inequalities bound event probabilities from limited information, such as moments, without requiring a complete probability distribution. Markov's inequality uses a nonnegative random variable's expected value; Chebyshev's inequality uses a variance to bound deviations from a mean. The attraction is a guarantee that applies to many possible probability distributions. Their bounds can be conservative for a particular model, and distributions attaining equality show when the available information really cannot give more.
The Lyapunov moment inequality says that higher positive absolute moments give no smaller absolute moment sizes on a probability space. For a real random variable and ,allowing an infinite value. For the left expression is an Lp norm; below one it is a quasi-norm, so the usual triangle inequality terminology needs that distinction. The comparison uses a probability measure of total mass one; arbitrary unnormalized measure spaces need a factor depending on their total mass.
For a nonnegative count, the first moment size is its expected value, while the second is the square root of its second moment. Both ten-trial counts in second moment method have first moment size one. The independent count has second moment size , whereas the shared-outcome count has second moment size . The second moment distinguishes models with the same average because its square increases the influence of rare large counts.
More generally, for with a Bernoulli random variable of parameter ,It rises from one at toward ten as . Replacing by a parameter gives , which decreases toward zero for a fixed positive exponent when , making the rare-event and large-exponent limits different questions. For a scaled Rademacher random variable taking values and two with equal probabilities, every absolute moment size is exactly two: increasing the exponent does not distinguish signs when the absolute value is constant.
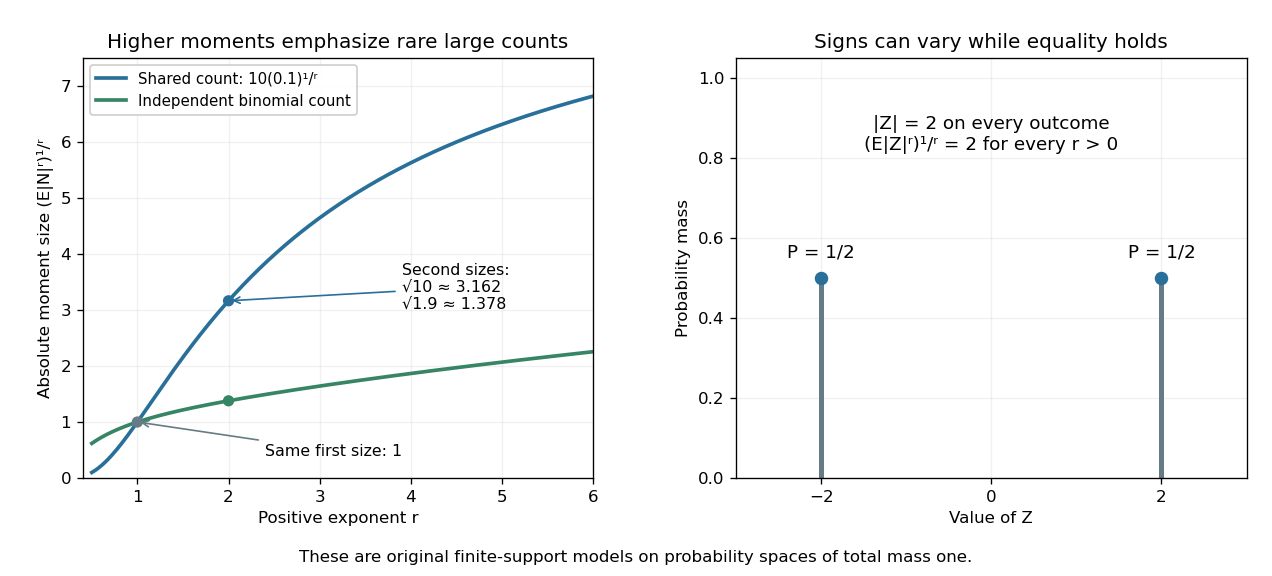
Lyapunov moment inequality reveals how higher moments emphasize large outcomes and when equality holds
. Left: the two original ten-trial models from second moment method have the same mean one, but different absolute moment sizes at exponents above one. The shared model has with . Right: equal masses at and two keep almost surely, giving equality for every pair of positive exponents. These are fully specified mathematical probability models. Details.
For finite , apply the reversed Jensen's inequality to the strictly concave function and the nonnegative random variable :Taking the positive th root proves the claim. Equality in this finite case holds exactly when is constant almost surely. If the higher moment is infinite, the upper bound is infinite and remains valid. Exponent zero is excluded from the statement; logarithmic or geometric limiting summaries require separately stated conventions, especially when can vanish.
For a real random variable with finite variance , expected value , and a threshold , Chebyshev's inequality givesOne can also cap this upper bound at one, since a probability cannot exceed one. If , taking gives . For example, at least of the probability lies strictly within two standard deviations of the mean. This statement needs only the finite variance assumption. If the variance is zero, almost surely and every positive deviation threshold has zero tail probability.
Consider a random variable uniformly distributed on . Its expected value is zero and its variance is . At the actual tail probability is , while Chebyshev's inequality gives . At the actual tail probability is zero, while the bound is . A valid bound need not describe the exact shape or bounded support of a particular probability distribution.
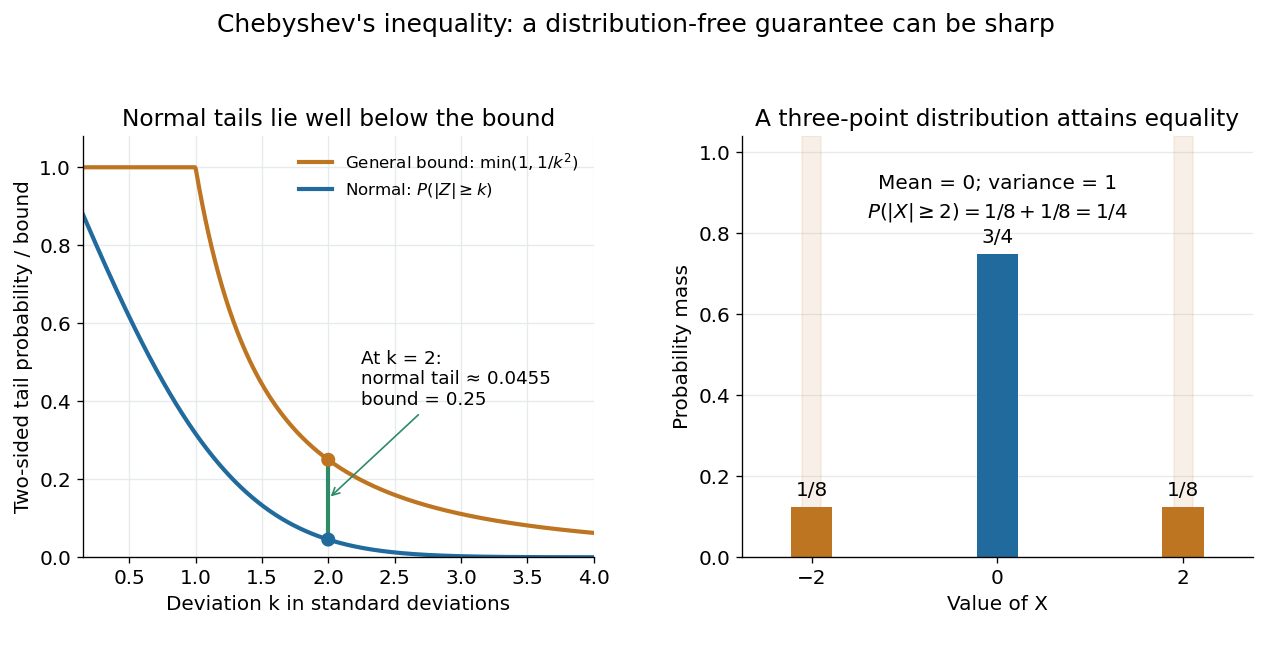

For the standard normal distribution, the actual tail probabilities beyond two and three standard deviations are approximately and , whereas the general bounds are and . More knowledge of the probability distribution can therefore improve the estimate. The comparison does not diminish the guarantee: the three-point example in equality in Chebyshev's inequality attains it exactly.
The proof is a one-line use of Markov's inequality on the nonnegative random variable . The event equals , and . This explains why the denominator is squared and why a finite variance supplies the necessary information. [ref]
https://ocw.mit.edu/courses/18-175-theory-of-probability-spring-2014/887e96172e82a615dac16fb26702d88b_MIT18_175S14_Lecture8.pdf. Scott Sheffield, MIT 18.175, lecture 8: Markov and Chebyshev bounds
.One important use is control of a sample mean. For independent and identically distributed random variables with finite variance , the variance of a sample mean is . HenceFor every fixed tolerance, the bound tends to zero as the sample size grows, proving the finite-variance case of the weak law of large numbers. For and , makes the bound . This is a sufficient bound under the stated assumptions, rather than an optimal required sample size.
An early historical source is Pafnuty Chebyshev's 1867 paper “Des valeurs moyennes”, published in French translation by N. de Khanikof. Its opening theorem bounds deviations of sums using their expected values and second moments, linking averages with control of exceptional outcomes. [ref]
https://www.numdam.org/item/JMPA_1867_2_12__177_0.pdf. Chebyshev, Journal de mathématiques pures et appliquées, 2nd series 12, 177–184 (1867)
.An unbiased coefficient estimator with known variance gives a conservative level- test of a zero coefficient by rejecting when its absolute value is at least . Chebyshev's inequality bounds the null rejection probability by . This test needs the variance assumptions but no Gaussian error distribution; a normal-reference test requires additional distributional justification.
For , assign probability to each of and , and the remaining probability to . This probability distribution has expected value , variance , and tail probability . Thus Chebyshev's inequality is sharp when only these two moments are supplied. For example, , , gives masses , , . Replacing with would exclude the two extreme points in this example.
Cantelli's inequality uses a mean and variance to control deviations in one specified direction. For a real random variable with expected value , finite variance , and ,Applying the same statement to gives the lower tail probability bound . No independence or particular probability distribution is required. If , the random variable equals almost surely and both positive-threshold tail probabilities are zero.
For variance one and a threshold two above the mean, the upper-tail probability is at most . Applying the two-sided Chebyshev's inequality to contain that upper event would give the weaker bound . For the standard normal distribution, the actual upper tail probability at two is about , much smaller than either bound. Yet the two-point probability distribution in equality in Cantelli's inequality attains , showing why the smaller Gaussian value cannot be promised from these two moments alone.
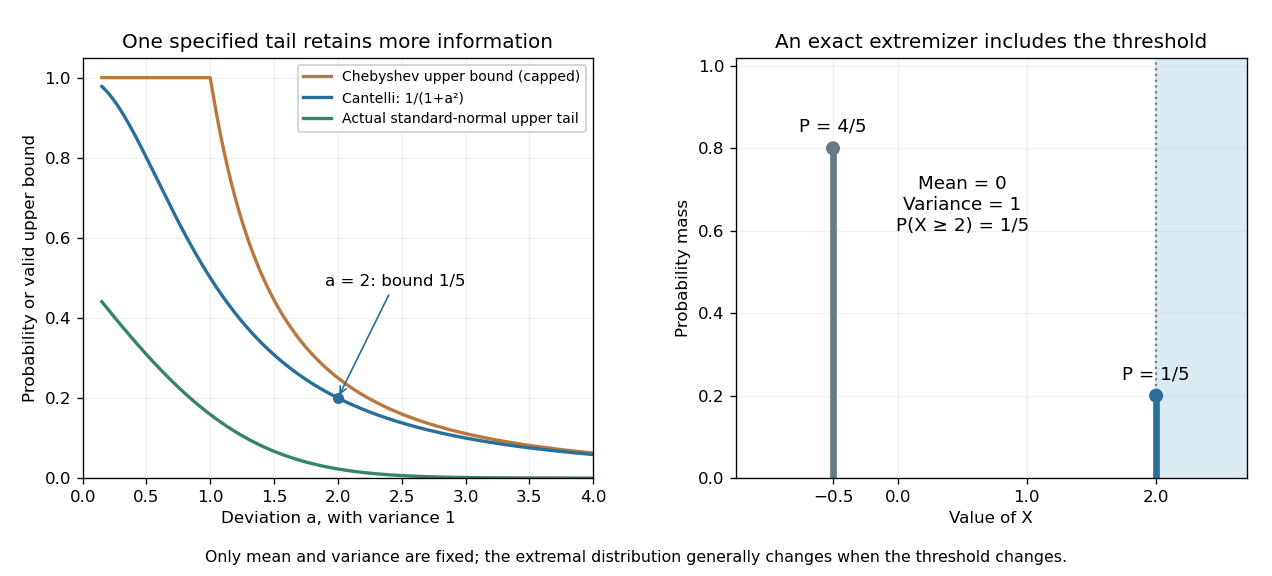
Cantelli's inequality sharpens a variance-only upper-tail bound and is exact for a two-point probability distribution
. Left: actual upper tail probabilities for the standard normal distribution are compared with Cantelli's inequality and the capped two-sided Chebyshev's inequality used as an upper-tail bound. Right: masses at and at two have mean zero and variance one. The upper mass is included by the non-strict threshold . These are specified mathematical models, not observations. Details.
A short explanation is to centre and choose a nonnegative shift . On , the square is at least , so Markov's inequality givesThe best shift is , giving the displayed bound. Choosing the shift before squaring exploits the direction of the deviation; squaring the unshifted random variable treats both directions together. This shifted-square proof is also the strategy requested in the University of Utah's 2005 qualifying problem on Cantelli's inequality. [ref]
https://quals.math.utah.edu/topics/borel-cantelli-lemmas/. University of Utah Mathematics, 2005 question 4: shifted-square Cantelli bound
.The one-sided improvement should be used for a one-sided question. Adding upper and lower bounds by the union bound gives for . When , that is at least the Chebyshev's inequality bound ; when , both two-sided expressions exceed one and must be capped. The separate one-sided bounds generally cannot be attained simultaneously by the same probability distribution.
For and , place probabilitiesTheir weighted deviations cancel, giving expected value ; their weighted squared deviations give variance . Only the upper point belongs to , so its tail probability attains Cantelli's inequality. With , , , the locations are two and , with masses and . The optimized shift makes the lower point zero before squaring, explaining equality in the Markov's inequality step.
The threshold convention matters: this example has . For a strict threshold, placing the upper point at instead gives probabilities approaching the same bound as , with the prescribed mean and variance retained. Extra restrictions on the support of a probability distribution can change which extremal models are allowed.
The first moment method uses the expected value of a count to control whether any counted occurrence exists. For a random variable taking nonnegative integer values, Markov's inequality givesConsequently, implies , proving that an outcome with no counted occurrence exists. For a sequence of such counts, shows that with probability tending to one. The first moment method uses information about the average count, while the complementary second moment method also uses its variance.
The second moment method uses a random variable's expected value and second moment to establish that a counted or measured quantity is positive with substantial probability. It is useful when a positive average alone could be caused by extremely large values on very rare outcomes. Controlling the variance rules out too much of that concentration in rare outcomes.
For a nonnegative random variable with and finite second moment, the second-moment bound for positivity givesEquivalently, . The method also includes the simpler Chebyshev's inequality bound . Thus a sequence of such random variables with has with probability tending to one. These statements require no independence assumption. The variance argument and its use for random counts are developed in Zhao's lecture notes. [ref].
For an original toy count, let count successes in ten independent Bernoulli trials with success probability . The binomial distribution givesConsequently . The exact probability is . The first moment method and union bound only give the upper bound here. First and second moments therefore answer complementary existence questions.
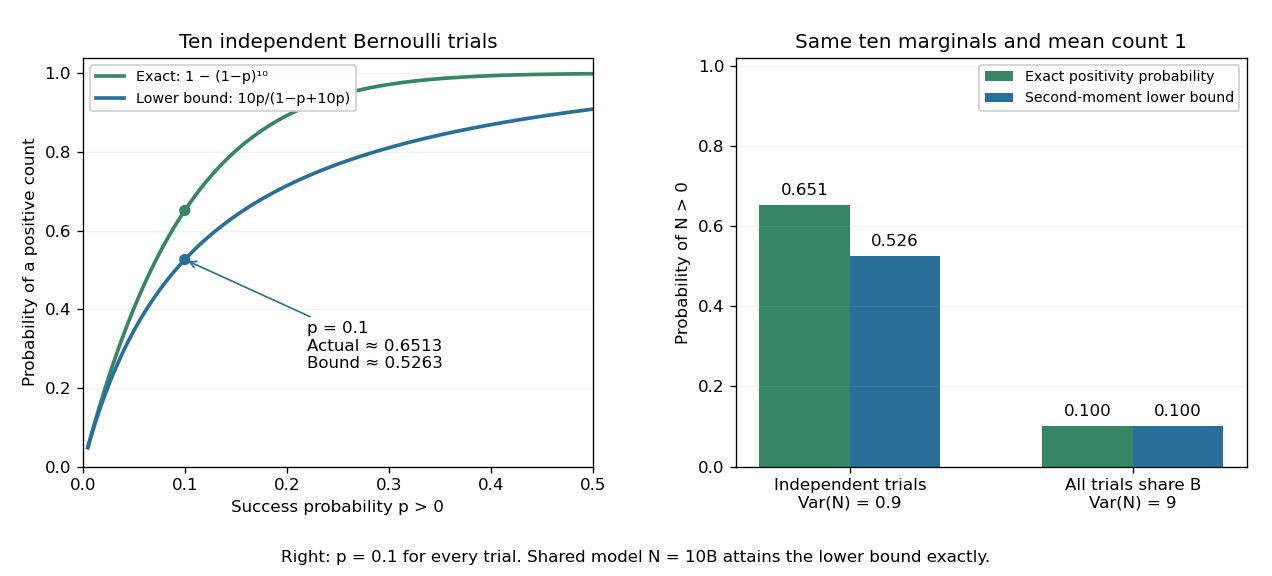
The second moment method certifies a positive count, while statistical dependence can change the conclusion despite an unchanged mean
. Left: exact binomial distribution probabilities of at least one success and second-moment lower bounds for ten independent trials as the success probability varies. Right: the same ten trials with either occur independently or share one common Bernoulli outcome. Both counts have mean one, but the perfectly linked count has much larger variance and only probability of being positive. All data are original specified probability models. Details.
For a sum of indicator random variables, the variance of a sum isIndependence makes the covariances vanish, but the formula itself also covers dependent counts. For the same ten success probabilities, let every trial share a single Bernoulli random variable : then , with mean one, variance nine, and . The second-moment lower bound is exactly . Ignoring the positive covariances would produce the false independent-count conclusion. Zhao's discussion of sums of indicators explains why overlapping counted structures require these pairwise terms. [ref]
https://ocw.mit.edu/courses/18-226-probabilistic-methods-in-combinatorics-fall-2022/mit18_226_f22_lec06-07.pdf. Zhao, MIT 18.226, §4.1: indicator covariances and Bernoulli counts
.For a nonnegative random variable with positive expected value and finite second moment, write . The Cauchy-Schwarz inequality giveswhich proves the bound in second moment method. It is the zero-threshold case of the Paley-Zygmund inequality. Equality occurs when is a fixed positive value on the event and zero elsewhere, almost surely. For with a Bernoulli random variable of parameter , equals the exact positivity probability.
The variance identity turns the lower bound into a statement about variance relative to the squared mean. A small ratio forces positivity to be likely. A positive expected value alone does not do so: keeping while taking with probability and zero otherwise makes the positivity probability as small as any chosen .
For a nonnegative random variable and threshold , Markov's inequality givesThe useful case has finite expected value; an infinite right side gives no finite information. The bound also holds if is nonnegative almost surely. Combining it with the elementary bound one gives . Nonnegativity is essential: negative values could otherwise cancel the contribution of large positive values to the expected value.
The idea is an average budget. Every outcome where contributes at least times its probability to , and the other outcomes contribute nonnegative amounts. Formally, the indicator function gives ; taking the expected value proves the bound. [ref]
https://ocw.mit.edu/courses/18-175-theory-of-probability-spring-2014/887e96172e82a615dac16fb26702d88b_MIT18_175S14_Lecture8.pdf. Sheffield, MIT 18.175, lecture 8: the expectation argument
.For example, let take , , , with respective probabilities , , , . Its expected value is . At , the tail probability is , while the bound is . At , the tail probability is , while the bound is . A different probability distribution with the same expected value, putting masses and at and , attains the bound exactly at .
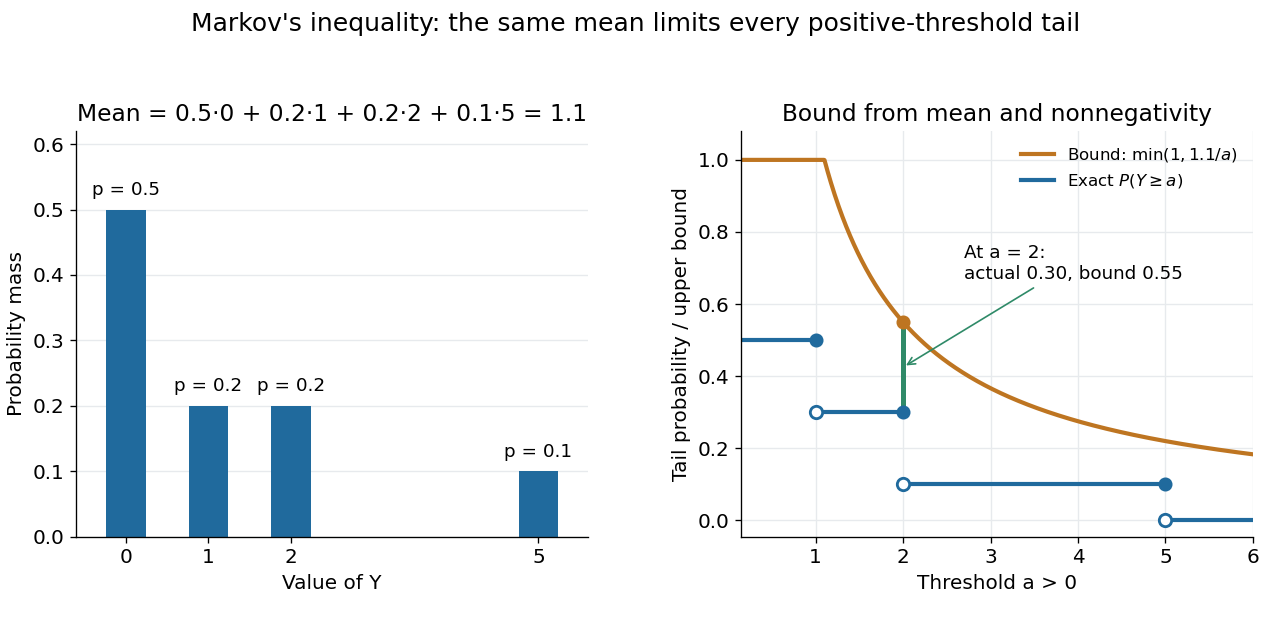

Markov's inequality is useful when a moment is easy to compute but a full probability distribution is difficult to determine. A nonnegative count with expected value less than one must have some positive probability of being zero, giving the first moment method. Applying the same bound to a squared centered random variable gives Chebyshev's inequality. Applying it to an exponential function of a random variable gives an exponential Markov bound, which can exploit more than a single moment.
Let be a nonnegative integer-valued random variable with , where and are integers. On , the integer is at least . Markov's inequality gives . Independent restarts therefore need at most attempts in expected value to achieve . The denominator bound on the expected value matters for this runtime guarantee.
If is an integrable random variable and is a finite, strictly positive -measurable random variable, thenIndeed, . Monotonicity of conditional expectation and the measurable-factor rule for conditional expectation giveDivision by the strictly positive proves the claim. Only the displayed product needs to be an integrable random variable; neither nor needs to have finite expected value. The measurable threshold represents information already available before asking how likely the remaining exceedance is.
For a finite-expected value nonnegative random variable and , equality in the uncapped Markov's inequality holds exactly when takes only and almost surely. Indeed the nonnegative difference has zero expected value exactly when it vanishes almost surely. Giving probability yields and . This shows the bound cannot generally be reduced using only the nonnegative random variable's expected value.
Applying Markov's inequality to the positive random variable givesHere is the moment-generating function, and the useful bound requires it to be finite at the chosen . Optimizing over gives the Chernoff bound method: an exponential function weights large values more strongly before applying the same average-budget argument.
For example, let have the Poisson distribution with parameter one. Its expected value and variance are both one, and its moment-generating function is . At threshold four, choosing givesThis minimizes the exponent because its derivative is , with positive second derivative. The direct Markov's inequality bound is , and the two-sided Chebyshev's inequality bound, applied to a deviation of at least three from the mean one, is . The exact Poisson distribution tail probability is . These compare three valid bounds obtained from progressively different information; none is an exact tail probability formula for general random variables.
A concentration inequality bounds the probability that a random variable differs substantially from a typical value such as its expected value or median.
Equip the symmetric group with its uniform probability measure and unnormalized Hamming distance. If has Lipschitz constant , it obeys the displayed two-sided bound, and each one-sided tail has the same exponential without the factor two. Reveal a uniform permutation one image at a time. Two possible next images have completion sets paired by swapping those two values, changing exactly two coordinates. Thus the corresponding conditional means differ by at most . Each increment of the Doob exposure martingale has conditional range length at most . Applying the conditional Hoeffding lemma gives ; optimizing the exponential Markov bound proves the bound. A mere absolute-increment bound of gives a weaker constant, so using the range length matters.
For an event in a product of finitely many probability spaces with its product measure, take the closed convex hull of the mismatch vectors , . The distance of this hull from zero is . Equivalently it is the supremum, over nonnegative coordinate weights of squared sum at most one, of their minimum mismatch sum. Averaging mismatch patterns is the feature that distinguishes this quantity from ordinary Hamming distance.
On a finite product of standard probability spaces, for any measurable event of positive probability,Consequently . Here is the Talagrand convex distance. The distance-event conclusion can be read with outer probability when necessary.
Let the largest last-coordinate section have probability , and another section probability . Mix mismatch vectors from these two sections with weights . Their squared norm is at most . Hölder's inequality and induction bound that section's exponential integral by . The scalar estimate for Talagrand product induction makes it at most . Average over sections and use with to close the induction.
For ,where the endpoint is used directly if . Put . For , choose and set . Then and , proving the bound. For , take ; the result follows from the already proved boundary case and monotonicity of . This estimate closes the section-by-section induction for the exponential Talagrand convex distance moment.
For a nonnegative integrable random variable , the entropy functional isIt is the unnormalized relative entropy of the measure with density proportional to relative to the original probability measure.
Here for a probability measure. The coefficient depends on the normalization of the energy. With the joint energy for , standard Gaussian measure has optimal constant two.
// Target: analysis.bigb
Differentiate with and a changing exponent. The derivative is . Apply the logarithmic Sobolev inequality to and the power inequality for symmetric Markov energies. Choosing makes the upper bound zero.
// Target: probability-and-statistics.bigb
The Hoeffding inequality turns finite interval bounds and independence into exponentially small tail probabilities for a sum. It requires neither a normal distribution nor identical probability distributions. Let be independent essentially bounded real random variables, with deterministic finite bounds almost surely. Define the centered sum and its squared-width budget byFor and ,The union bound therefore gives . If , every is constant almost surely, so and both positive-threshold tail probabilities vanish. The equal-width version is stated in the authored Stanford notes.[ref]
The quantity is a sum of squared interval widths, not the variance of . Centering changes the endpoints to and , leaving each width unchanged. For example, independent random variables in and have , whatever their expected values or probability distributions. A deviation at least three above their total expected value has probability at most . If all widths equal , the sample mean satisfies
Independence is essential to this general guarantee. Take one Bernoulli random variable with success probability and set every . Each lies in , but for every the sample mean is either zero or one. Thus , whereas incorrectly inserting these dependent observations into the formula would give , less than one for . Some special dependent models have their own valid concentration inequalities; arbitrary statistical dependence cannot be ignored.
For the short proof, apply Markov's inequality to with , factor the expectation using independence, and apply the Hoeffding lemma to each factor:Minimizing this quadratic polynomial at gives the upper tail probability; applying it to gives the lower one. This is the Chernoff bound method. The original 1963 article is Probability Inequalities for Sums of Bounded Random Variables by Wassily Hoeffding; its publisher record identifies the article, but its full text was unavailable during this source check. The argument above is a direct derivation rather than a claim to have inspected that article's proof.
Let be even and let be independent Bernoulli variables with parameter , arranged on a circle. The probability that some consecutive half-circle has is at most . For a fixed , the variable has the binomial distribution , and the signed imbalance is . Apply Hoeffding inequality to this single binomial variable, then take a union bound over the at most intervals. Consequently suffices for uniform balance with probability tending to one whenever .
Let be independent and identically distributed Bernoulli random variables with success probability , and let be their observed frequency, a sample mean. Since every interval width is one, . Substituting into the Hoeffding inequality givesFor tolerance and failure probability , solving yields the sufficient sample sizeHere is the natural logarithm. For and , guarantees an error smaller than with probability at least , for every . The two-sided bound at this sample size is approximately . A specified single direction instead needs , or for these choices. Halving the tolerance multiplies the unrounded sufficient sample size by four; reducing the failure probability tenfold adds before rounding.
This is a conservative sufficient sample size, not a necessary minimum. For a specified , the count has a binomial distribution, whose exact upper tail probability isFor , the Hoeffding inequality bounds this by . An arbitrary frequency threshold uses ; if , the event is impossible. The discreteness of the count and its variance can make the exact tail probability substantially smaller. At , , , the exact upper tail probability is about , while the bound is . At , , the same deviation gives the same bound but an exact upper tail probability about .
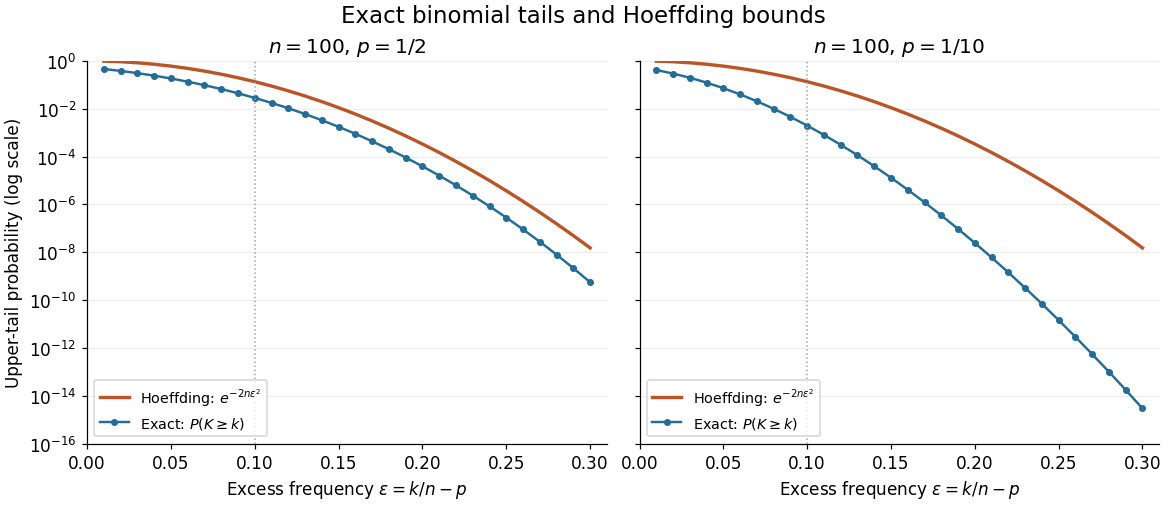
Exact binomial distribution tails compared with the Hoeffding inequality
. Two original specified models, each with independent Bernoulli trials. Each dot includes its integer threshold , with horizontal coordinate . Exact finite sums are evaluated with rational arithmetic before conversion for plotting. The Hoeffding inequality uses the width one in both panels; it does not use the smaller variance at . These are model probabilities, not measured frequencies. Details.
For a fixed positive sample size of independent and identically distributed Bernoulli random variables, letThe Hoeffding inequality makes a conservative confidence interval for : for every . Indeed, exclusion from the closed interval implies , an event contained in the deviation event bounded by . Clipping to retains coverage because already lies there. For , , and an observed frequency , , giving approximately .
Coverage concerns repeated independent samples: the unknown is fixed and the confidence interval is random. This fixed- guarantee does not justify repeatedly checking the same bound and stopping as soon as it looks favorable. The Hoeffding sample size for Bernoulli frequencies chooses in advance; guarantees across repeated inspection times require separate control of the additional events, for example through a union bound with an allocated failure probability at each time.
The Hoeffding lemma controls the entire centered moment-generating function using only an interval width. For an essentially bounded real random variable with finite deterministic bounds almost surely, every real satisfiesEquivalently, . This single-random variable statement needs no independence assumption; independence enters when applying it to the factors for a sum in the Hoeffding inequality. Both signs of are allowed, and equality holds at or when .[ref]
In the convention for a centered sub-Gaussian random variable , the Hoeffding lemma supplies . This upper parameter need not equal the actual variance. For a Bernoulli random variable of success probability ,The actual variance is , whereas the supplied parameter is for every . This explains part of the conservatism visible in Hoeffding sample size for Bernoulli frequencies.
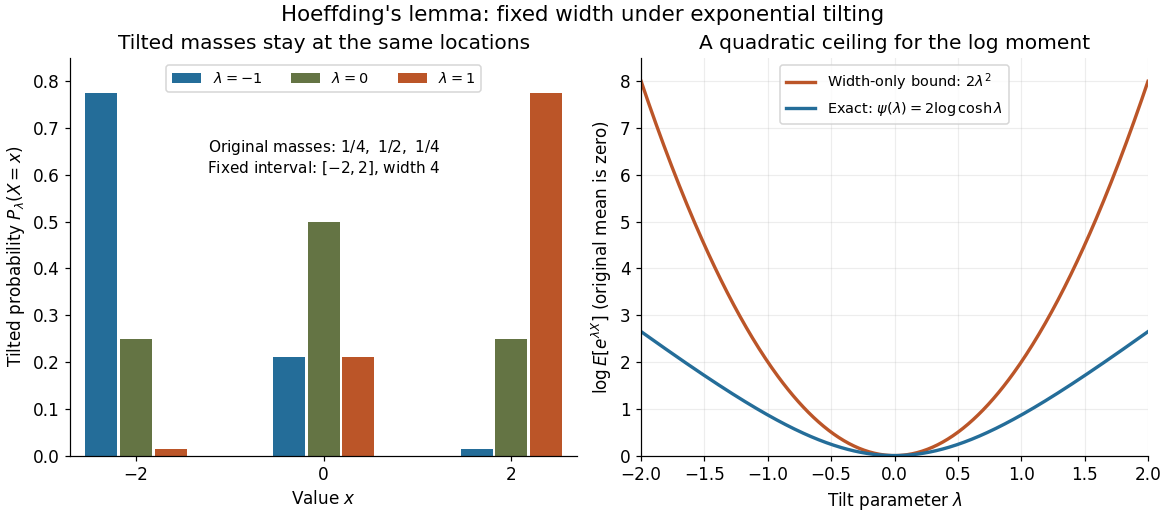

A short proof exposes why the constant is . Put and define exponential tilting byThe tilted probability measure has the same interval of possible values, and differentiating the cumulant-generating function gives . Boundedness justifies these derivatives for every finite . Under any such tilted law, Popoviciu's inequality on variances gives : the variance is no larger than the expected value of the squared distance from the interval midpoint, itself at most . Since , the integral form of Taylor's theorem yieldsThis expression handles either sign of without changing the argument.
The constant cannot be reduced uniformly over all essentially bounded real random variables. Equal endpoint probabilities at and give , a scaled Rademacher random variable, andThus the sharpness is already forced near zero by the variance; the bound need not be equality at nonzero parameters for a particular probability distribution.
For a binomial distribution with and , the Bennett inequality at standard deviations tends to , whereas the Hoeffding inequality tends to two. The raw Bennett inequality bound is eventually smaller for any fixed ; after clipping at one it is nontrivial in the limit only when .
The Bennett rate function has Taylor expansion near zero. It is the optimized exponent in the Chernoff bound based on the moment-generating function estimate for the Bennett inequality.
If each probability measure has Poincaré constant , then the product measure has Poincaré constant at most . This follows by iterating the law of total variance and applying Jensen inequality to derivatives of conditional expectations.
If has Poincaré constant and is -Lipschitz, then the pushforward measure has Poincaré constant at most . Apply the original inequality to and use the chain rule.
For the uniform distribution on ,The constant is sharp and is the mean-zero Poincare-Wirtinger inequality on the interval.
For standard one-dimensional Gaussian measure, . Thus , while . Every nonzero therefore attains ratio two, proving optimality of the Gaussian constant.
For bounded smooth positive bounded away from zero, differentiation and Gaussian integration by parts give the displayed identity. The Ornstein-Uhlenbeck gradient commutation identity and weighted Cauchy-Schwarz inequality bound its right side by . Integrating and setting proves the Gaussian logarithmic Sobolev inequality. Positive clipped approximation extends it to functions of finite Gaussian Dirichlet energy.
For every , Markov inequality applied to givesOptimizing over gives the Chernoff bound in terms of the moment-generating function of .
For a matrix of independent standard normal entries and , diagonal entries of have two-sided tails bounded by , while off-diagonal entries have tails bounded by . A union bound over diagonal entries and distinct off-diagonal entries controls their common entrywise maximum norm.
If are independent random variables and has bounded differences constants , thenand the same bound holds for the lower tail.
Give a graph on labelled vertices independent edge weights in , and let be the maximum total weight of a matching. Put each edge into the block of its lower-numbered endpoint. There are at most independent blocks. Every matching uses at most one edge from any block, since the block's edges share that endpoint. Changing a whole block therefore changes the weight of each fixed matching by at most one. Comparing the old and new maximizing matchings shows the same bound for .
The Doob exposure martingale for these blocks has increments bounded by one, so Azuma's inequality givesThe important feature is grouping independent edge coordinates into vertex-centred blocks. Exposing all edges separately would give a weaker denominator of order on a dense graph. Identical distributions are unnecessary; independence and the common range bound suffice.
For a nonempty of relative size at least , its Hamming distance function has the bounded differences property with all constants one. If , the concentration bound at gives , so for . Then , proving that the radius- neighbourhood contains at least cube points.
If a function of independent coordinates has one-sided squared-difference proxy at most , Talagrand's one-sided inequality gives a Gaussian lower-tail bound . Applied to the negative of a concave function, it gives the corresponding upper-tail bound.
An integer-valued function is -certifiable when every input with has a set of at most coordinates whose values alone guarantee that .
The entropy method combines a coordinatewise certificate with tensorization of entropy to bound the moment-generating function of a certifiable random quantity and hence its tails.
A nonnegative function of independent coordinates is self-bounding when there are coordinate-deleted versions such that andThese inequalities make the natural variance proxy no larger than the function itself.
A nonnegative function is weakly self-bounding when coordinate-deleted functions satisfy andThe squared coordinate sensitivity is then controlled by the observed value of the function itself.
For a weakly self-bounding function of independent random variables, the coordinatewise variance inequality giveswhere .
For a nonnegative function of independent random variables, entropy is at most the sum of its conditional coordinate entropies. This tensorization is a basic step of the entropy method.
The Efron–Stein inequality bounds the variance of a complicated output by the effect of replacing one input at a time. Let be mutually independent random variables, not necessarily identically distributed, and for a measurable function , with . Take with having the same probability distribution as , all inputs mutually independent. DefineUse the same function , keeping every other input fixed. ThenThe expected value averages over both the original inputs and their replacements. An infinite right side gives a trivial bound; under the stated square-integrable condition every term is finite.[ref]
Lecture 7a: Efron Stein inequality by Purnamrita Sarkar. Lecture 7a: Efron Stein inequality, slides 1–2 and 7, PDF pp. 2–3 and 8: independent inputs, conditional-variance bound and independent-copy form
For a concrete four-state example, take independent Bernoulli random variables with and , and set . This output records whether either input is one. The states have respective probabilities , soReplacing changes only when and . A fresh Bernoulli draw can repeat the old value: the replacement is not a forced flip. By independence, the expected value of the squared change isSimilarly,Thus Efron–Stein inequality gives . The larger second contribution reflects both its replacement probability and how often the other input leaves the output sensitive to it.
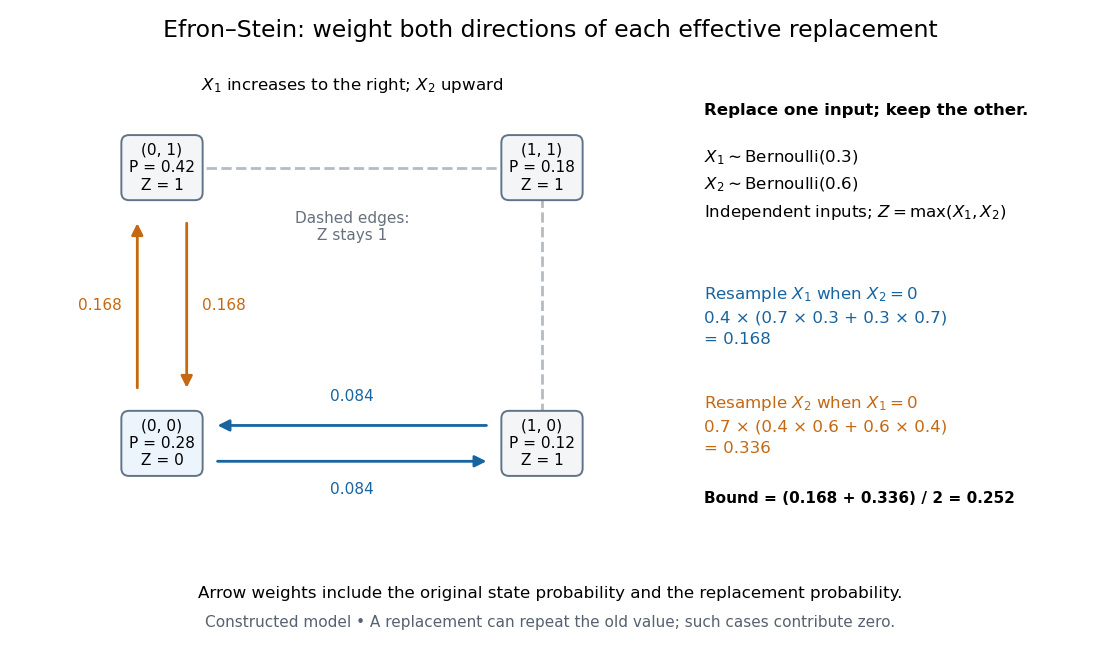
Four weighted states explain the Efron–Stein inequality resampling contributions
. Original constructed model: independent Bernoulli random variables with parameters and , and . Each node shows its joint probability. Directed arrow labels are joint probabilities of the original state and replacement value, rather than conditional transition probabilities. Only solid edges change ; same-state replacements and the dashed edges contribute zero. Both directions count before the factor . Details.
For the same inputs, consider instead . The variance of a sum of independent random variables givesHere and , so the Efron–Stein inequality is exact: . More generally, for with square-integrable summands, each contribution equals and these variances add exactly.
Independence is essential. Let for a single Bernoulli random variable with parameter , and take . Its variance is one. If each coordinate is nevertheless replaced by an independent draw from its marginal Bernoulli distribution, each squared-change expected value is , giving the false proposed upper bound . Replacement now creates off-diagonal states and that the original input never visits. The original coordinates fail the hypothesis of Efron–Stein inequality.
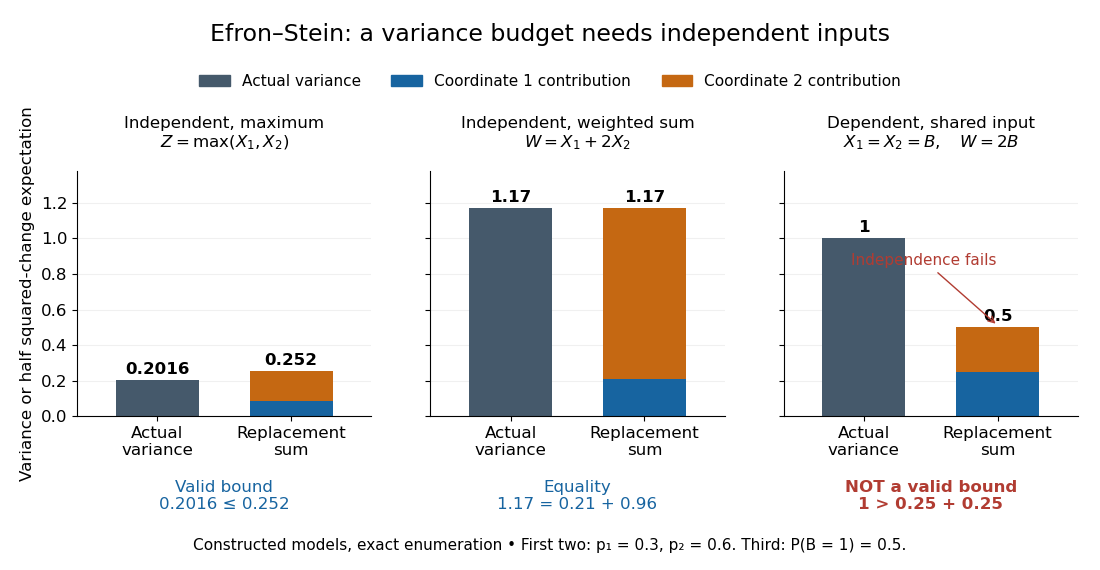
The Efron–Stein inequality can be loose, exact, or inapplicable when independence fails
. Exact enumeration in three constructed models: the four-state maximum has variance and bound ; the weighted sum on the same independent inputs has variance and bound ; the dependent model has variance one but marginal replacement produces , which is not a valid bound. Stacked contributions are half the squared-change expected values. The third panel deliberately violates the theorem's assumption. Details.
The attraction is local calculation: a function may involve many inputs, yet changing one can have a simple effect. Each half squared-change expected value supplies a coordinate's contribution to an upper budget for the total variance. Applying Chebyshev's inequality then bounds a tail probability using that budget. These contributions need not partition the actual variance, as the maximum example shows.
The name commemorates Bradley Efron and Charles M. Stein. Their 1981 paper The Jackknife Estimate of Variance appeared in The Annals of Statistics, volume 9, issue 3, pp. 586–596.[ref]
Bradley Efron's Profile, Stanford University. Publications: The Jackknife Estimate of Variance, Efron and Stein, 1981, 9(3), 586–596
Write for all inputs except . Under the Efron–Stein inequality hypotheses, variance tensorization is the equivalent conditional variance formConditioning freezes the other inputs. Then are independent with the same conditional probability distribution, givingTaking expected values explains the factor .[ref]
Lecture 7a: Efron Stein inequality by Purnamrita Sarkar. Lecture 7a: Efron Stein inequality, slides 2 and 7, PDF pp. 3 and 8: conditional variances and the independent-copy identity
For Bernoulli input with parameter , let be the value of with coordinate set to one minus its value with that coordinate set to zero, keeping fixed. The two-point conditional variance isFor the maximum example, and . The two averaged conditional variances are and , precisely half the respective resampling terms. In the dependent example , each other coordinate already determines , so both conditional variances vanish; variance tensorization also fails without independence.
For a short induction proof, separate the last input using the law of total variance. Apply the smaller-dimensional statement to the conditional expectation; Jensen's inequality for the square bounds its coordinate contributions by the original ones. One input gives equality, starting the induction.[ref]
Lecture 7a: Efron Stein inequality by Purnamrita Sarkar. Lecture 7a: Efron Stein inequality, slides 3–6, PDF pp. 4–7: variance decomposition and conditional Jensen step; the induction outline here reorganizes those ingredients
A modified logarithmic Sobolev inequality bounds the entropy of by a one-sided coordinate-difference energy. For independent coordinates and arbitrary coordinate-deleted functions , tensorization givesIf that energy is at most , one common normalization is
The Herbst argument integrates a logarithmic Sobolev bound on to control the centered cumulant-generating function , then applies a Chernoff bound to obtain concentration.
A transport-entropy inequality controls an optimal expected transportation cost between probability distributions by their Kullback-Leibler divergence.
If each coordinate law satisfies the same convex transport-entropy inequality, then the product law satisfies the sum-cost version. Sequentially couple conditional coordinates, apply Jensen inequality, and use the chain rule for relative entropy.
A centered random variable is sub-Gamma in the right tail with variance parameter and scale parameter whenfor .
Suppose independent centered sub-exponential random variables satisfy for , and put . Independence adds the log moment-generating functions. The Chernoff bound with gives the displayed two-sided tail. If each variable has common scale , one may take and , giving . This form of Bernstein's inequality allows unbounded variables with factorial moment control, including the centered square of a sub-Gaussian random variable.
For independent centered variables and , the th moment of their sum is bounded, up to a constant depending only on , by the sum of their th moments plus the power of their total variance.
Talagrand's concentration inequality gives strong concentration in product spaces using convex distance. If has positive product probability, its convex-distance enlargement has Gaussian tails. A Talagrand concentration inequality for certifiable functions follows by bounding this distance using bounded differences and small certificates.
This is an application of Talagrand's concentration inequality to certifiable functions. Talagrand's product-space inequality gives sub-Gaussian-type concentration for a bounded-differences, certifiable function, with a variance scale controlled by the certificate size.
Suppose an integer-valued certifiable function is -Lipschitz under one-coordinate changes and a value at least has a certificate of at most coordinates. Any input with value at most must differ on at least certificate positions. Equal weights on those positions bound its Talagrand convex distance from the low-value event. Applying Talagrand's convex distance inequality gives the displayed product bound. For , median tails integrate to , and deviations of order have exponentially small probability.
For the longest increasing subsequence length on a product space of independent coordinates, a witness of length uses only coordinates. Any point with subsequence length at most must differ on at least witness positions. Weights on those positions show . Thus for ,At a median , this gives upper tail and lower tail . Integrating the tails places the mean within of the median, so the natural concentration scale near the mean is . A random permutation is represented by the ranks of independent continuous variables; arbitrary dependent sequences need not obey this conclusion.
Boole's inequality, also called the union bound, bounds the probability that at least one of several events occurs by adding their individual probabilities. For a finite or countable family of events in the same probability space,The union includes outcomes where several events occur together. There is no independence assumption: adding the individual probabilities counts such outcomes repeatedly, which can only make the sum larger. The cap at one uses the total mass of a probability measure. For infinitely many events, the sum is a nonnegative series, possibly infinite; an infinite sum gives only the bound one. This is countable subadditivity of a measure specialized to a probability measure. See Probability: Theory and Examples (fifth edition) by Rick Durrett (Section 1.1, Theorem 1.1.1(ii), printed p. 2).
For example, choose uniformly from the twelve outcomes , using the discrete uniform distribution. Put . If , these are disjoint events and their union has probability , exactly the union bound. If , the union has only six outcomes, so its exact probability is , although both individual probabilities are still and the bound is still . If , the exact probability falls to with the same bound. These examples isolate overlap in the union bound by keeping the individual probabilities fixed.
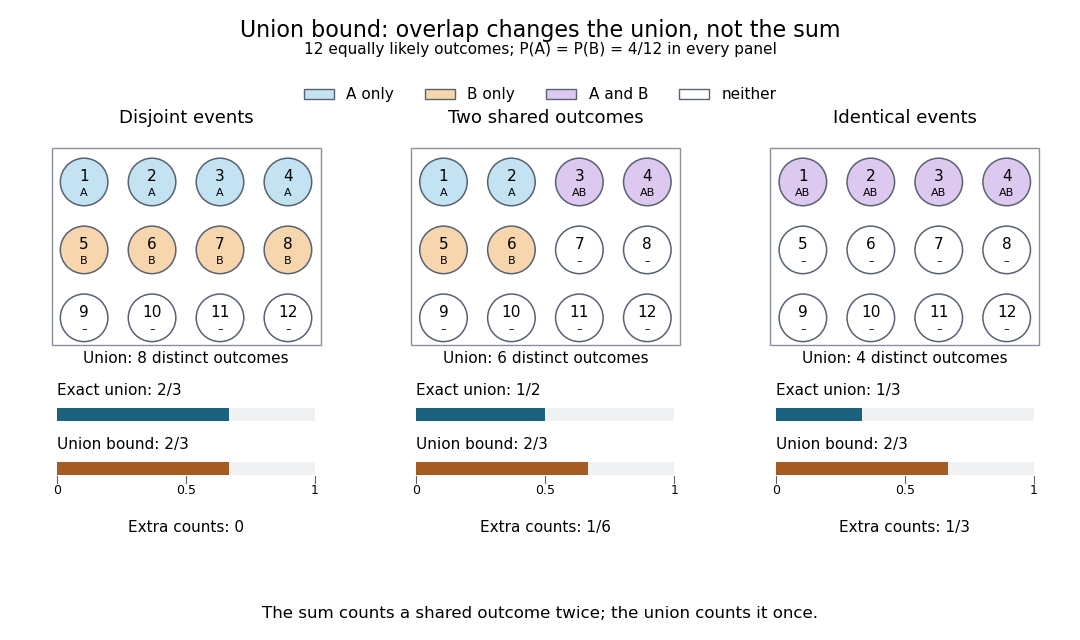
The same individual event probabilities give different exact union probabilities as overlap increases
. Each panel is a fully specified discrete uniform distribution on twelve numbered outcomes. Blue means only, orange means only, purple means their intersection, and white means neither. The bottom bars compare the exact union probability with the sum of the individual probabilities. The three unions contain eight, six, and four outcomes; the sum counts eight in every panel. Details.
The union bound is useful when each event is easy to control but their joint behavior is difficult to determine. A short proof uses indicator functions: at every outcome,Taking expected values and using linearity of expectation proves the finite bound.[ref] For a countable family, the finite unions increase to the full union; continuity of probability passes the finite inequalities to the limit. The closure of a sigma-algebra under countable unions ensures that this limiting union is an event. For the continuity of probability step, see Probability: Theory and Examples (fifth edition) by Rick Durrett (Section 1.1, Theorem 1.1.1(iii), printed p. 2).
For three events in one classical probability space, the inclusion and the union bound prove the displayed inequality. It is therefore an unconditional theorem of classical probability. In a polarization Bell test, a model assigning simultaneous setting-independent pass/fail outcomes to three possible analyzer directions must obey it. Equal unbiased marginals and quantum pair correlations instead give . Directions violate the resulting constraint for , because . The conclusion excludes that common classical joint model. Conditional probabilities from sequential measurements cannot be inserted without their marginal factors or treated as if all three contexts shared an already established joint distribution.
For finitely many events, or a countable family with finite sum of individual probabilities, equality in the uncapped union bound holds exactly when every pairwise intersection has probability zero. Equivalently, at most one event occurs almost surely. Pairwise disjoint events give equality, but literal disjointness is stronger than necessary: shared outcomes of probability zero do not change either side. For the capped bound, if the sum exceeds one, equality instead means that the union is an almost sure event; overlap can then have positive probability.
The cap and the disjoint case are both sharp. If the individual probabilities sum to at most one, put the events on separate pieces of a sample space to attain their sum. The twelve-outcome disjoint example does this with two events of probability . If the sum exceeds one, a covering union can attain the cap: on the same twelve-outcome sample space, and have sum and exact union probability one. These are sharpness examples, not an assertion that every overlapping family attains the bound. Positive-probability disjoint events are also not independent events, because their joint probability is zero while the product of their individual probabilities is positive.
For a finite family, the random variable counts the events that occur. Linearity of expectation gives , while is the exact union probability. Their difference isAn outcome in exactly events contributes extra counts, weighted by its probability. This nonnegative difference vanishes exactly in equality in Boole's inequality. For two events it is , as the inclusion-exclusion principle for probabilities shows. For more events, the Bonferroni inequalities use pairwise and higher intersection information to bound the exact union probability; blindly subtracting pairwise intersections from the sum gives a lower bound, rather than a corrected upper bound.
Severe overlap can make the union bound arbitrarily pessimistic. Let all events be the same event with probability , where is an integer. A concrete model is the discrete uniform distribution on with . The exact union probability is , whereas the sum and capped bound are both one. The ratio is : adding more names for the same event does not create more ways to fail. The identity above describes the gap in the uncapped sum; capping at one can reduce that gap.
A failure-probability budget assigns nonnegative numbers to a finite or countable family of failure events in a common probability space, with verified bounds . The union bound guarantees that the probability of any failure is at most . By De Morgan's laws and the complement rule of probability, the probability that every requirement succeeds obeysThus guarantees simultaneous success with probability at least , even when all failure events depend on the same observations. The numbers are upper allowances; adding them is not a calculation of the exact failure probability.
For three requirements, give each a failure-probability budget . The total budget is , so simultaneous success has probability at least . On a sample space of twenty equally likely outcomes, let , , and . These disjoint events attain the budget and the success bound. If instead all three failure events equal , their individual probabilities are unchanged, but exact failure has probability and simultaneous success has probability . This second model shows how overlap can leave the guarantee conservative.
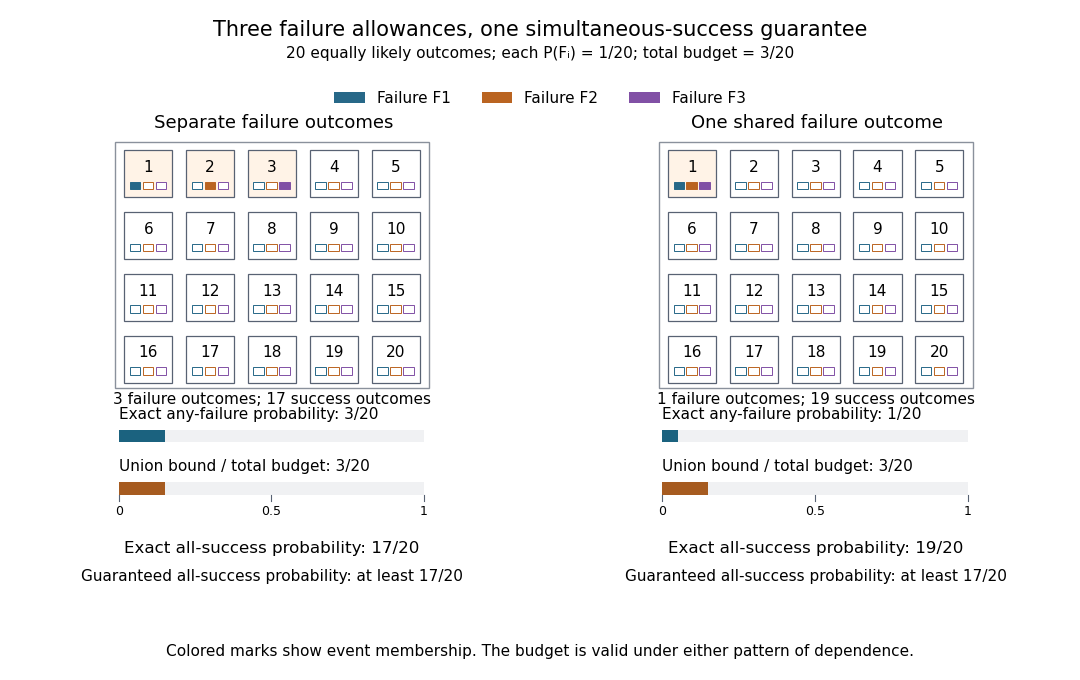
A shared failure-probability budget covers both separate failures and one common failure
. The two panels each have twenty equally likely numbered outcomes. The blue, orange, and purple marks identify membership in , , and , respectively. Their individual probabilities are in both panels. The union has three outcomes on the left and one on the right, while the union bound is in both. The event of simultaneous success is the complement of an event of any failure and contains seventeen or nineteen outcomes. These are illustrative probability models, not measured failure rates. Details.
For requirements, an equal allocation is convenient; unequal allocations also work when some requirements are harder to satisfy. For infinitely many requirements indexed by , the allocation uses total budget by the geometric series. A fixed positive allowance for every requirement instead gives an infinite sum and no positive simultaneous-success guarantee from the union bound. The individual probability bounds must cover all the failure events being combined: omitting possible failure modes leaves the resulting guarantee about the listed requirements only. The same addition of error allowances underlies the Bonferroni correction in simultaneous hypothesis tests.
For , the intersection of all pairwise intersections is . Apply the union bound to the complements of the pairwise intersections and then take the complement to obtain the displayed lower bound. A sum exceeding therefore forces positive common probability without any independence assumption.
The FKG inequality gives positive association under a log-supermodular probability measure on a finite distributive lattice.
This lattice condition on configuration masses is the hypothesis of the FKG inequality. A product measure on a finite Boolean lattice satisfies it with equality, since in each coordinate the minimum and maximum retain the original two coordinate values. It implies positive association of random variables for increasing functions.
For a strictly positive law satisfying the FKG lattice condition on a finite Boolean lattice, and an increasing function , tilt to . For , the lattice inequality and give the Holley condition for . For any increasing , differentiate at from the right. The derivative is , proving positive association of random variables.
For two increasing events of equal probability under a product measure, positive association of their complements gives . Hence . For equal-probability increasing events, the same reasoning gives .
If increasing events have a common probability, applying the Harris-FKG inequality to their decreasing complements gives .
Harris' inequality states that two increasing events under an independent Bernoulli product measure are positively correlated.
Under a product measure on a finite Boolean lattice, an increasing event and a decreasing event obey the displayed inequality. The complement is an increasing event, so Harris' inequality gives . Subtract from to obtain the result. This implication includes degenerate Bernoulli distribution parameters and .
An event in a partially ordered configuration space is increasing when changing coordinates upward cannot make a configuration leave the event.
For a sequence of nontrivial increasing events on finite product measures, write for the parameter at which the success probability is . An additive sharp threshold means that for every fixed . When the threshold parameter itself tends to zero, relative sharpness instead compares this window with ; additive sharpness alone is then a weaker assertion. The Friedgut-Kalai sharp threshold theorem provides an explicit additive bound for transitive increasing events.
An increasing event on a finite product of identically distributed coordinates is transitive if a group action preserving the event is transitive on the coordinate set. Its influences are all equal. Transitivity concerns coordinates, and does not assert transitivity on successful configurations.
An event is decreasing when closing additional edges cannot destroy it. Its complement is an increasing event.
For increasing containment events in a Bernoulli product space, let , , andwhere the sum is ordered and dependency means overlapping coordinate supports. ThenIn particular it is at most when , and at most when .
For increasing containment indicators, attach independent Bernoulli selectors of parameter . Janson inequality applied to the selected events gives . Set and apply the exponential Markov bound. The estimates give exponent at most . Optimizing at proves the displayed lower-tail bound, with the dependency sum ordered and excluding the diagonal.
The Janson dependency sum adds over ordered pairs of distinct containment events whose coordinate supports overlap.
For containment-event indicators in a Bernoulli product space,It follows by exposing the avoidance events in sequence, separating disjoint coordinate supports, and applying Harris' inequality to the remaining decreasing events.
Articles by others on the same topic
There are currently no matching articles.