Graph theory studies vertices and the edges connecting them: which graph paths exist, how efficiently we can travel, and which connections are indispensable. A road map becomes a graph when junctions are vertices and road segments are edges; a communications network uses routers and links instead. The drawing helps us see connections, but its apparent lengths need not be the costs being optimized. Record travel times or transmission costs separately in a weighted graph.
The appeal of graph theory is that one model serves many practical questions. Graph paths describe routes, connected components of a graph identify isolated regions, and minimum spanning trees connect all locations cheaply. The shortest path problem asks a different question: find the cheapest journey between specified locations. Our four-vertex example below makes that distinction concrete and shows how the Dijkstra algorithm discovers a route without trying every graph path.
A path-cycle matching in a finite simple graph is a collection of mutually vertex-disjoint paths and cycles in a graph. Its used edges form a subgraph with every degree of a vertex at most two. Conversely, every finite connected component of a graph with maximum degree at most two is a graph path, a cycle in a graph, or an isolated vertex; following successive edges proves this classification. Discarding unused isolated vertices therefore converts any such subgraph into a path-cycle matching without changing its edge count. On a bipartite graph, maximizing the used edges is exactly bipartite b-matching with every .
A tree of bags of graph vertices such that every vertex occurs in a bag, both endpoints of every graph edge occur together in a bag, and the bags containing any fixed vertex form a connected connected subgraph of a tree. Its width is . The connected-occurrence condition lets subproblems agree on shared variables while solving a constraint satisfaction problem; an arbitrary cover of edges by small bags is insufficient.
The minimum width of a tree decomposition. A tree has width at most one, while a clique of vertices forces width at least . Every pair of vertices in the clique shares a bag; their connected bag connected subgraphs of a tree have a common intersection by the Helly property of connected connected subgraphs of a tree, placing the whole clique in one bag. Small treewidth is useful for dynamic programming on finite-domain constraint satisfaction problems.
During repeated deletion of vertices of current degree below , every subgraph of minimum degree at least is contained in the active induced subgraph. If an active vertex has degree below , its degree in any subgraph of the active graph is no greater, so no candidate can contain it. This proves the invariant inductively. A queue of threshold crossings and adjacency lists implements peeling in time.
The unique maximal induced subgraph with minimum vertex degree at least , possibly empty. It is found by repeatedly deleting vertices of degree below . The k-core peeling invariant proves that every subgraph satisfying that degree bound survives inside the result; in particular the final vertex set does not depend on deletion order.
A dominating set of a graph is a vertex subset such that every unselected vertex has a neighbour in . Equivalently every vertex lies in or is adjacent to an element of . This condition differs from vertex cover, which requires every edge to have an endpoint in the selected set.
An edge cover of a finite graph is a subset of its edges incident to every vertex. It exists if and only if there is no isolated vertex, with the empty graph covered by the empty set. A minimum-cardinality edge cover uses as few edges as possible; a minimum-weight edge cover minimizes their total weight. These objectives are related to maximum cardinality matching and maximum-weight matching, respectively, by the edge cover and matching identity and minimum-weight edge cover by matching savings.
An edge cover minimizing the sum of selected edge weights. For nonnegative weights and no isolated vertex, it is computable in polynomial time by the minimum-weight edge cover by matching savings construction. It need not have minimum cardinality.
Persistence of a specified network property under a specified class of perturbations. Robustness of connectivity and robustness of dynamical function are different questions.
Alternative routes or components can preserve function after failure, provided they do not share the same relevant failure mode.
Maintenance or recovery of specified network performance after a disturbance, including its transient response and recovery time.
A failure changes loads or dependencies so that further components fail. Connectivity of the surviving graph alone does not determine whether a cascade occurs.
A small interaction pattern occurring unusually often relative to a specified network null model. A circuit's wiring and proposed dynamical function should be distinguished from the statistical evidence that its pattern is enriched in a network.
Community detection partitions a network into groups according to a specified structural criterion, often excess internal connectivity. The output depends on the objective, so a partition inferred from topology need not by itself establish distinct biological functions.
A network null model specifies the reference network ensemble or expected connectivity against which a pattern is measured. For standard network modularity, expected edge weight is . The reference is part of the scientific model: choosing a different reference can change what counts as excess structure.
Network modularity measures excess within-community edge weight relative to a network null model based on degrees of vertices. For an undirected unweighted graph, its standard form is . A single community containing every vertex has ; a partition with more internal connectivity than expected can have positive .
The Louvain method is a greedy multilevel community detection algorithm maximizing network modularity. It alternates positive-gain single-vertex moves with contraction of communities into weighted vertices. Different vertex orders can produce different local optima; a result is not a certificate of globally maximum modularity.[ref]
Eigenvector centrality assigns nonnegative vertex scores proportional to the sum of neighbouring scores: . It uses a nonnegative eigenvector of the adjacency matrix for its largest positive eigenvalue. State the normalization, such as Euclidean norm one. For a three-leaf star graph, hub and leaf scores have ratio .
Degree-preserving edge rewiring replaces two edges and by and , preserving every endpoint's degree of a vertex. On simple graphs, reject proposed self-loops and duplicate edges. Symmetric random proposals with rejected moves retained preserve a uniform distribution on the reachable realizations; adequate mixing remains a separate requirement. Connectivity can change unless explicitly constrained.
A scale-free network has a degree distribution with an approximately power-law tail over a meaningful range. Evidence requires degrees from enough vertices to assess that range and compare alternative tail models. Large clustering coefficients or short graph distances alone do not establish this property.
A degree distribution assigns the fraction or probability of vertices having each degree of a vertex. For an observed network, . Preserving every labelled degree preserves this distribution, but preserving only its mean does not.
Small-worldness compares a network's clustering and average shortest-path length to reference values through . The common classification is a ratio-based convention rather than a significance test; random-reference variability must be assessed separately.[ref]
A small-world network combines elevated local clustering coefficients with mean graph distance comparable to a chosen reference ensemble of random graphs. Both the reference ensemble and the clustering convention must be specified. A network can have these properties without having a power-law degree distribution.
For a vertex with neighbours in a simple graph, its local clustering coefficient is , where counts edges among those neighbours. It is the fraction of possible neighbour-neighbour edges that are present. A common network summary averages these local coefficients, setting them to zero for degrees below two; this differs from weighting by the number of neighbour pairs.
An acyclic spanning subgraph containing a spanning tree of each connected component of the original graph. For a graph with vertices and components, a spanning forest has edges.
The intersection graph of chords of a circle: each chord is a vertex, and two vertices are adjacent when their chords cross. Two chords with distinct endpoints cross exactly when their endpoints alternate around the circle.
The intersection graph of the segments in a permutation diagram. Two segments cross exactly when their endpoint orders disagree. A set of mutually noncrossing segments corresponds to a monotone subsequence of the endpoint permutation.
A diagram of straight segments joining two parallel lines, with distinct endpoints on each line. Ordering the endpoints along the two lines encodes a permutation; crossing segments define the associated permutation graph.
A discrete process in which a vertex holding at least its degree in chips may send one chip along each incident edge. On the infinite line, a firing removes two chips from a site and gives one to each neighbor. When stabilization exists, commuting local firings explain why their order does not change the final stable configuration.
For an alphabet of size , the order- directed graph has words of length as vertices and words of length as edges. An edge goes from its prefix of length to its suffix of that length. An Eulerian cycle therefore lists every length- word once as a cyclic window, producing a De Bruijn sequence.
A geometric spanner is a weighted graph on points in Euclidean space, with edge weights equal to their Euclidean distances, in which every pair has a graph path of length at most times its direct distance. Its stretch factor is the largest ratio , where is shortest-path distance. A square's four perimeter edges, without diagonals, give stretch factor : adjacent points have ratio one, and diagonal pairs have route length instead of . The aim is to retain short routes with fewer edges than a complete graph. [ref]
https://people.scs.carleton.ca/~michiel/encyc_geometric_spanners.pdf. Gudmundsson, Narasimhan and Smid, Geometric Spanners, §1
.Here excess means edges minus vertices. For a connected graph it is one less than the number of independent cycles. Deleting a leaf and its incident edge, or suppressing a degree-two vertex, preserves excess. This convention differs by one from the cyclomatic number for connected graphs.
A connected bicyclic graph has two independent cycles, equivalently excess one. Its 2-core has the same excess and every removed vertex lies in a tree attached to the core. The graph kernel captures the finite collection of possible branching structures.
If counts labelled bicyclic cores on vertices, the bicyclic kernel classification gives . Three internally nonempty paths between two branching vertices give for . Attach a forest with those core vertices as roots to obtain . After division by the relevant sum is . Its upper bound follows from ; its lower bound uses , where this product stays bounded below. The sum is bounded above and below by positive constants. The restriction is necessary: .
The graph kernel of a bicyclic graph satisfies , with all degrees at least three. It therefore has either one degree-four vertex carrying two loops, a bouquet graph, or two degree-three vertices. In the latter case connectivity and degree counting give either three parallel edges, the three-edge Theta graph, or one edge between the vertices and one loop at each, a dumbbell graph. All bicyclic cores are subdivisions of these three kernels, subject to simplicity restrictions on loop lengths and parallel paths.
The 2-core is what remains of a finite simple graph after repeatedly removing every vertex with fewer than two surviving graph neighbours. It strips away dangling trees while keeping the part that can support itself under this local rule. Precisely, for an undirected graph , its 2-core is the unique maximum by set inclusion induced subgraph such thatThe empty vertex set is allowed: the condition is then vacuous, without needing to define the minimum degree of the empty graph. "Maximum by inclusion" means that contains every other vertex set satisfying the condition. It is stronger than merely saying that one chosen set cannot be enlarged: the 2-core simultaneously contains all possible qualifying induced subgraphs. In this particular family, every inclusion-maximal qualifying set does equal that unique maximum; the union argument in why the 2-core is unique explains why. [ref]
An O(m) Algorithm for Cores Decomposition of Networks by Vladimir Batagelj and Matjaž Zaveršnik. Batagelj and Zaveršnik, An O(m) Algorithm for Cores Decomposition of Networks, §2, definition of a core
For a complete worked example, let denote the edge and takeThe triangle in a graph has a branching tail attached at , and is an isolated vertex. In alphabetical order the initial degrees of vertices are . Deleting turns into a leaf of a graph; deleting leaves with degree of a vertex two; deleting changes no other degree of a vertex. Now delete , which makes a leaf of a graph, and finally delete . Exactly the three edges of remain: .
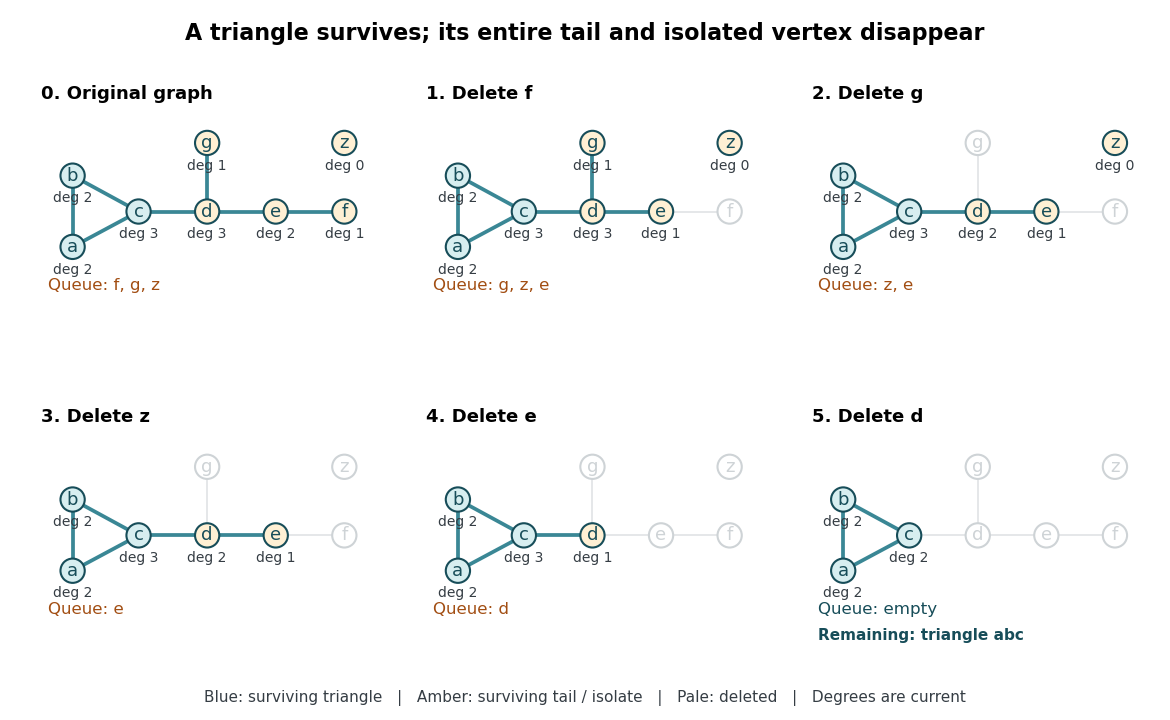
The complete leaf pruning for the 2-core trace: each panel recomputes the displayed degrees of vertices from the surviving induced subgraph, while the FIFO queue determines the next deletion
. Details. A forest has empty 2-core: every nonempty finite forest has an isolated vertex or a leaf of a graph, so deletion cannot stop at a nonempty remainder. In particular, an isolated edge, an isolated vertex, a path graph, and the empty graph all have empty 2-core. Every cycle graph is its own 2-core. Two disjoint triangles in a graph also form their own 2-core, so a 2-core need not be a connected graph; attaching a tree to either triangle changes neither surviving triangle.
Use adjacency lists and a FIFO queue to implement the deletion rule in time complexity . Compute each initial degree of a vertex once, mark every vertex alive, and put all vertices of degree of a vertex zero or one in the FIFO queue. Each vertex is inserted at most once. Repeatedly remove the front vertex , mark it dead, and traverse its original adjacency list. For each still-alive graph neighbour , decrease the stored degree of a vertex of by one; if it has just become one, append . A vertex already queued can drop from one to zero before its turn, but it stays queued and requires no second insertion. Stop when the FIFO queue is empty; the alive vertices induce .
For the displayed example, initially enqueue in that order. The successive FIFO queues, after each deletion and all its updates, areThis explains the delayed deletion of : its initial degree of a vertex was three, but the relevant degree of a vertex is always its current one in the surviving induced subgraph. Removing only the original vertices of degree of a vertex one would give the wrong answer.
Initialization inspects every vertex and every adjacency list entry once. During deletion each original adjacency list is traversed at most once, so at most entries are inspected in an undirected graph. All insertions, removals and stored-degree updates cost constant time each. Thus total time complexity is and additional storage, beyond the adjacency lists, is . The cost includes isolated vertices; repeatedly rescanning the whole surviving graph after each deletion would lose this bound. The single-threshold FIFO queue method is enough for the 2-core; the full k-core of a graph decomposition computes all thresholds.
Suppose is any vertex set whose induced subgraph has every degree of a vertex at least two. No vertex of can be the first one deleted from : before such a deletion it still has its two graph neighbours within , contradicting eligibility for deletion. Consequently every qualifying survives every legal deletion sequence. Once deletion stops, its remainder itself qualifies, because every surviving vertex has at least two surviving graph neighbours. Therefore for every qualifying : is the unique maximum and the final remainder is independent of deletion order. The intermediate FIFO queues and deletion orders can differ.
There is also a direct existence argument. If and qualify, then qualifies: each vertex retains at least the two graph neighbours it already had in or in . Taking the union of all qualifying vertex sets produces the maximum. This rules out a collection of competing, incomparable inclusion-maximal answers. It also explains why restricting the search to connected subgraphs would change the question.
A 2-core can contain bridges in a graph, and even vertices that lie on no cycle in a graph. Consider the dumbbell graph, also called a barbell in this example, made of two disjoint triangles in a graph joined by a graph path with two internal vertices:Here have degree of a vertex three, and every other vertex has degree of a vertex two. No deletion is possible, so the whole graph is its 2-core. Yet are bridges in a graph: deleting any one separates the two triangles. None belongs to a cycle in a graph, and belong to no cycle in a graph either. Keeping only edges on graph cycles would incorrectly discard the entire joining graph path.
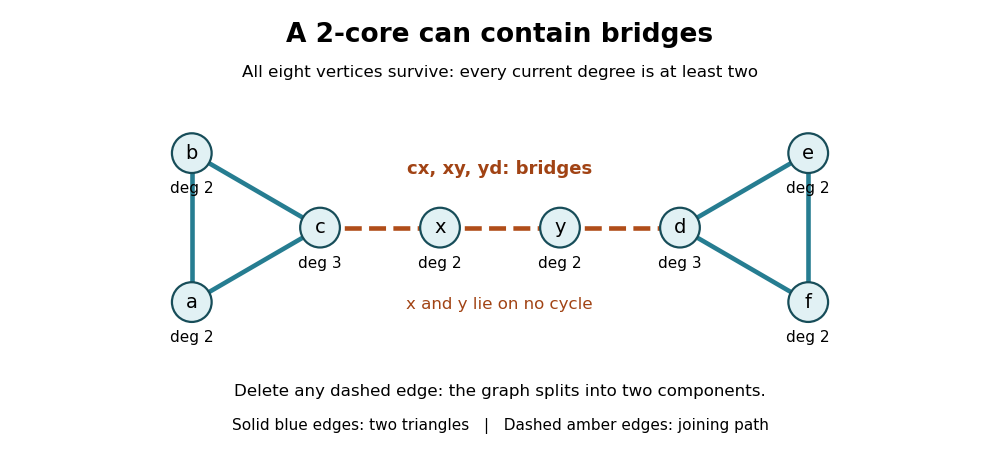
Every vertex of this dumbbell graph survives in the 2-core, including the joining graph path whose three edges are bridges in a graph
. Details. Every cycle in a graph does survive pruning, because each of its vertices keeps its two cycle graph neighbours. The barbell shows that the converse fails: the 2-core can be larger than the union of all graph cycles. Its condition is local minimum degree, not protection against a single connection failing.
A biconnected component is a different object: a maximal connected subgraph with no cut vertex of its own. Under the block convention used here, the barbell has five biconnected components: its two triangles and its three individual joining edges, each with its endpoints. Its cut vertices are . A 2-connected component with at least three vertices must remain connected after any single vertex is deleted; the whole barbell fails that test. An informal phrase such as "biconnected core" therefore needs its own definition and must not be substituted for 2-core. Even an isolated edge is a block under this convention, although its 2-core is empty.
The usefulness of the 2-core is this precise separation of local persistence from global robustness. In a connected graph with nonempty 2-core, the deleted vertices form a forest, with each of its connected components of a graph attached by exactly one edge to the 2-core. Otherwise a deleted graph cycle, or a graph path joining two surviving attachment points, would itself have survived. Stripping these attached trees exposes a smaller structure for studying graph cycles, graph excess and the graph kernel, while preserving the joining bridges in a graph that organize that structure.
For a connected graph whose 2-core contains a vertex of degree of a vertex at least three, suppress each maximal graph path with degree-two internal vertices to a single edge, allowing its two endpoints to coincide. Here suppression is the reverse of graph subdivision. The resulting multigraph, retaining self-loops and parallel edges, is its graph kernel. Each suppressed internal vertex removes one vertex and one edge, preserving graph excess; counting a self-loop twice toward degree of a vertex, every remaining vertex has degree of a vertex at least three. A purely cyclic 2-core is a separate unicyclic case: it has no branching vertex to anchor this construction.
For the barbell in bridges and connectivity in the 2-core, the graph kernel has two vertices , one self-loop at each, and a single joining edge . Suppressing contracts the joining graph path to that bridge in a graph; suppressing the two other vertices on each triangle turns the triangle into a self-loop. The graph excess stays . Thus forming a graph kernel compresses degree-two chains rather than deleting everything outside graph cycles.
For a nonnegative integer , the k-core of a graph is the unique maximum by set inclusion induced subgraph in which every degree of a vertex is at least , allowing the empty graph. Repeatedly delete vertices whose current degree of a vertex is less than . These induced subgraphs are nested: ; the case is the 2-core. In their 2003 preprint, Vladimir Batagelj and Matjaž Zaveršnik give an algorithm for the entire core decomposition, using degree buckets and constant-time position updates. Their general bound is ; the title's form applies to connected graphs with at least two vertices, where . [ref]
A chordal graph is a finite simple graph with no induced cycle of length at least four. Equivalently, every cycle in a graph with at least four vertices has a chord: an edge joining two nonconsecutive vertices of that graph cycle. The word "induced" matters: the induced subgraph on the chosen vertices must contain exactly the cycle's edges, with no chords. Triangles are allowed. This definition concerns adjacency, independently of how the graph is drawn.
For the square cycle graph , take vertex set and set of edges , where abbreviates . Its graph neighbourhoods are and . The square is an induced cycle, so is not a chordal graph. Add the single edge : now , , , and . The only possible four-vertex graph cycle has chord , so this new graph is a chordal graph. Its maximal cliques are exactly and .
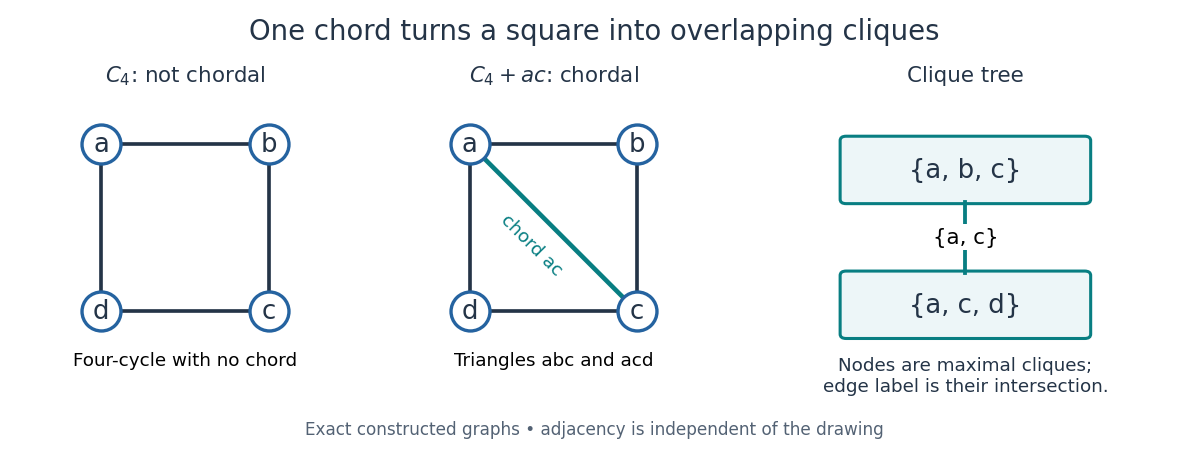
An induced cycle loses its obstruction when one diagonal is added; the resulting maximal cliques form a junction tree
. Details. Connect these two maximal cliques by a single edge labelled with their intersection . The result is a junction tree, also called a clique tree: its nodes are maximal cliques, and the nodes containing any fixed original vertex induce a connected graph inside the tree. Here occur in both nodes, while each occur in just one. This is the running intersection property. More generally, a nonempty connected graph is a chordal graph exactly when its maximal cliques admit such a tree; a disconnected chordal graph can be represented by one such tree per connected component of a graph.[ref]
A chordal graph need not be a planar graph: the complete graph is a chordal graph, since every pair of distinct vertices is adjacent, but its ten edges violate the planar graph edge bound . Conversely, even a plane drawing whose bounded faces are triangles can hide an induced cycle: a wheel graph with a four-vertex rim and a central vertex joined to the whole rim still has the rim as an induced cycle. Adding chords to obtain a chordal graph is called triangulation of an undirected graph; this is an adjacency condition, rather than a requirement about planar faces.
Why is this structure useful? The maximal cliques collect local interactions, and the running intersection property makes their overlaps sufficient for consistent communication. For random variables with finite state sets, a probabilistic graphical model of the square-plus-diagonal form can havewhere the two nonnegative clique potentials have a positive normalizing constant . Eliminating produces the two-variable junction-tree sum-product messageThe shared clique carries everything needed from the eliminated side. For possible states per random variable, this example uses two sums over configurations after reusing the message, rather than directly summing over configurations. The example's message is an exact finite sum, with no simulated data. Large maximal cliques still make exact inference expensive; chordal graphs provide a decomposition, not a universal guarantee of cheap inference.[ref]
Triangulation adds fill edges to an undirected graph to make it a chordal graph. Given an elimination ordering, join all remaining neighbors of each removed vertex. The completed graph has that perfect elimination ordering. Fill edges can enlarge the cliques used for exact probabilistic graphical model inference, without changing the original probability factors; they do not assert new biological relationships.
A perfect elimination ordering of a finite simple graph is a permutation of its vertices such that each set of later graph neighboursis a clique. Thus is a simplicial vertex in the remaining induced subgraph . Empty and one-vertex sets satisfy the clique condition automatically. The order here is the order of deletion: goes first.
The characterization is powerful: a finite simple graph is a chordal graph if and only if it has a perfect elimination ordering. For one proof outline, the earliest vertex of an induced cycle of length at least four would have two later graph neighbours on that graph cycle that are not adjacent, contradicting the clique condition. Conversely, every nonempty chordal graph has a simplicial vertex, and every induced subgraph of a chordal graph is a chordal graph; repeatedly deleting such a vertex supplies the ordering.[ref]
In the square-plus-diagonal chordal graph above, is a perfect elimination ordering, with later graph neighbourhoods , , , and . Starting instead with fails: its graph neighbours do not form a clique, because is absent. Thus even a chordal graph can have a poor elimination ordering.
For a larger example, join three triangles along shared edges, usingThe exact graph neighbourhoods are , , , , and . The ordering has later graph neighbourhoods , , , , and , all cliques; this certifies that the graph is a chordal graph without enumerating its graph cycles. Its maximal cliques , , form a junction tree in that order, with intersections and .
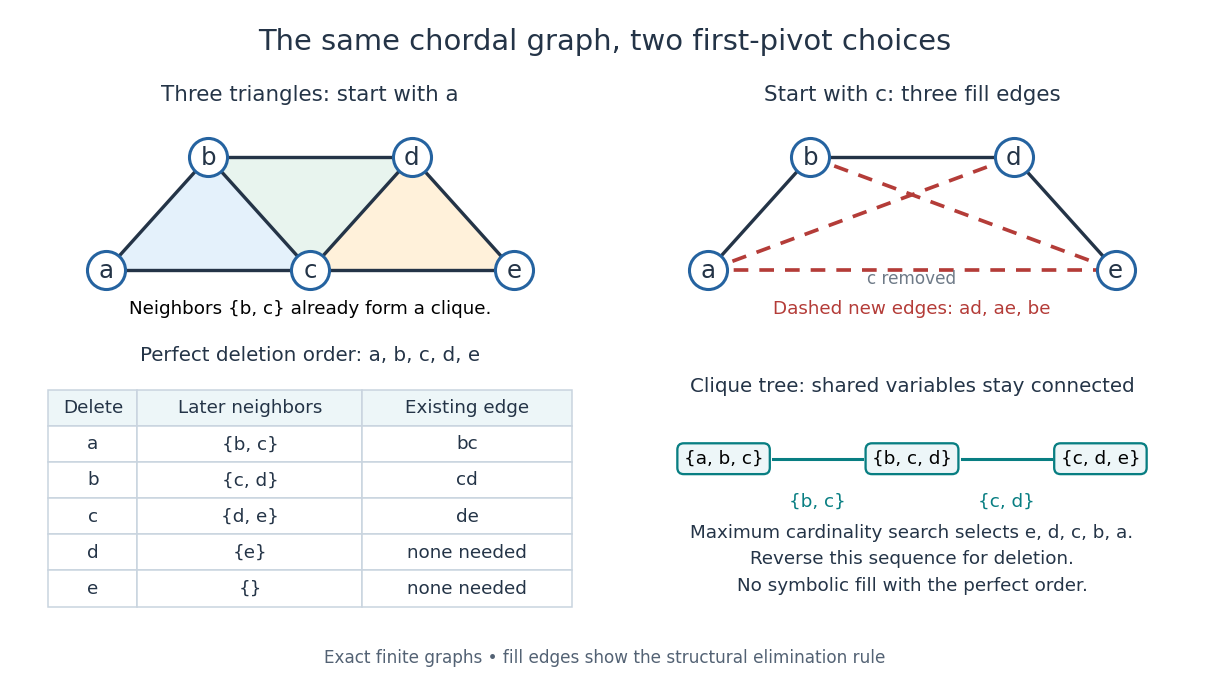
A perfect elimination ordering removes three overlapping triangles without fill-in; choosing the central vertex first adds three edges
. Details. To find an ordering, maximum cardinality search starts with all scores zero, repeatedly selects an unselected vertex of largest score, and increases each unselected graph neighbour's score by one. Reverse the selection order to obtain a candidate perfect elimination ordering. For the three-triangle graph, one valid selection sequence is , with scores at selection ; reversing it gives the displayed deletion order. On a chordal graph every tie choice works. On an arbitrary graph, test the resulting later graph neighbourhoods for the clique condition to recognize chordal graphs. Suitable adjacency lists, score buckets and a linear-time verification method give recognition.[ref]
The deletion rule also explains sparse Gaussian elimination. For a symmetric positive-definite matrix whose matrix graph is , eliminating pivot applies the Schur complement updateOnly pairs of remaining graph neighbours of can acquire new off-diagonal entries. A perfect elimination ordering already has all those edges, so Cholesky decomposition creates no symbolic fill-in. Positive definiteness ensures nonzero pivots in exact arithmetic. Special numerical cancellation can suppress predicted entries, and floating-point rounding affects their values.[ref]
Chordal Graphs and Semidefinite Optimization by Lieven Vandenberghe and others. §9.1; equation 9.2; Theorem 9.1
In the three-triangle graph, deleting first instead connects every pair in and adds exactly . The graph was already a chordal graph; the extra fill-in comes from the ordering.One further reward is optimal graph coloring. Process a perfect elimination ordering backwards and give each vertex the smallest positive color absent from its already colored graph neighbours. Those graph neighbours form a clique, so this greedy algorithm uses at most the clique number colors; any clique of that size requires at least that many. In the three-triangle graph, coloring gives colors , so both the chromatic number and the clique number are three. Every maximal clique also occurs among : take its earliest vertex and use maximality. The same ordering therefore supports graph coloring, maximal clique extraction and sparse computation.
Historically, Donald J. Rose, Robert E. Tarjan and George S. Lueker's 1976 paper connected graph elimination to symmetric sparse matrices and gave a search-based algorithm for finding a perfect elimination ordering when one exists. Its abstract distinguishes a minimal elimination ordering from a minimum one: removing avoidable fill-in does not by itself minimize the total number of added edges.[ref]
A simplicial vertex is a graph vertex whose graph neighbourhood is a clique. Every isolated vertex and every leaf of a graph qualifies. In the three-triangle chordal graph, initially qualify, but only becomes a simplicial vertex after deleting . This is a property of adjacency in a graph; a vertex of a simplicial complex is an element of a different kind of structure.
Maximum cardinality search is a graph search in which an unselected vertex's score counts its already selected graph neighbours. Repeatedly select a vertex of maximum score, breaking ties arbitrarily, and update its unselected graph neighbours. On a chordal graph, the reverse selection order is a perfect elimination ordering. On , selecting instead yields candidate deletion order ; 's later graph neighbours are not adjacent, so the clique check fails.[ref]
The Johnson graph has the -element subsets of an -element set as vertices, with two vertices adjacent exactly when their intersection has elements. Relabelling the ground set gives graph automorphisms. The maximal cliques of a Johnson graph allow reconstruction of those ground-set labels when the two clique sizes are different.
One edge of a Johnson graph replaces one element of a -subset, so it can increase intersection with a fixed target by at most one. Replacing each element outside the target by one missing target element gives a path reaching this lower bound. Equal-distance ordered pairs have equal sizes of intersection, the two differences and the remaining ground set; a permutation matching these four regions proves distance transitivity.
For , the maximal cliques of are the families containing a fixed -subset, of size , and the families contained in a fixed -subset, of size . To see why these exhaust the possibilities, write two adjacent vertices as and . A common adjacent vertex either contains or lies in . A vertex of the first kind outside that union is not adjacent to a vertex of the second kind omitting an element of , so a clique cannot mix these alternatives. For and , , the clique sizes and four distinguish the families containing pairs. Their incidence recovers , whose stars of size distinguish the individual ground-set points from its triangular cliques.
The maximum degree of a finite graph is the largest number of edges incident to one vertex. A bound on degree bounds the number of vertices within distance of a fixed vertex by . Such counting bounds turn a large vertex count into a lower bound on diameter.
For a simple graph, let count the common neighbours of vertices . Choosing two such neighbours makes a four-cycle, and each cycle is counted twice through its opposite pairs. The displayed identity follows even when extra edges are present, since cycles are counted as subgraphs rather than induced subgraphs. Also . Applying Cauchy-Schwarz inequality to degrees and Jensen inequality to common-neighbour counts gives extremal edge and cycle bounds.
The shortest path problem asks for a graph path from a source vertex to a destination vertex minimizing its total edge weight. Here is the cost of traversing edge , and costs add along the graph path. If no route exists, its shortest-path distance is . With nonnegative edge weights, deleting cycles in a graph from a walk never increases its cost, so repetitions cannot improve the optimum.
Consider the undirected graph with vertex set and the six edge weightsEach edge can be traversed in either direction at the same cost. The direct graph path costs ; costs ; costs . The cheapest graph path is , costing . The remaining graph path costs , exhausting the possibilities without repeated vertices.
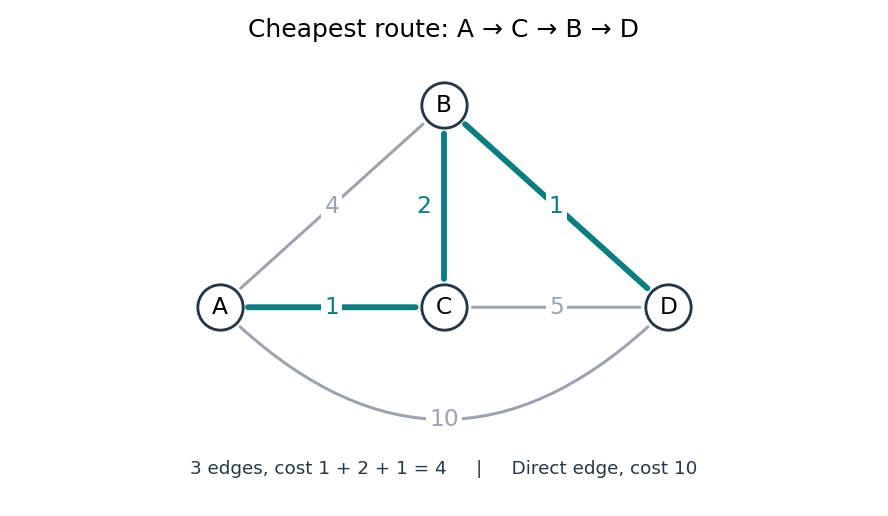
The shortest path problem: three highlighted edges cost less than the direct connection
. Details. Thus fewest edges and least total cost are different objectives. Breadth-first search minimizes the number of edges, which suffices when every edge has the same positive cost. Unequal nonnegative costs call for the Dijkstra algorithm. On a map, weights might be minutes rather than kilometres: a longer-looking route can arrive sooner. This is why a weighted graph separates the network's connections from what a particular journey costs.
The Floyd-Warshall algorithm computes all-pairs shortest graph path lengths in a finite weighted directed graph with no negative-length cycles in a graph. Initialize , use the arc cost for each existing directed edge, and use when no arc exists. For , update every ordered pair by the displayed rule. The storage is lengths and the running time is .
For correctness, let be the shortest simple graph path length whose intermediate vertices lie among the first . A shortest allowed graph path either avoids or splits at its unique occurrence of , giving the recurrence. Conversely, concatenate shortest paths through and remove any repeated-vertex sections; each such closed walk has nonnegative length, so removal cannot increase the length. This proves equality. The update can be performed in place because and the th row and column remain unchanged during stage .
If negative-length cycles in a graph are present, a shortest walk may not exist and the recurrence need not compute shortest simple graph paths. Two optimal subpaths can concatenate into a repeated-vertex walk with a negative cycle; deleting that cycle increases its length. A negative diagonal entry in the algorithm's final array detects this obstruction to finite shortest-walk distances.
Adding the same constant to every edge weight adds times the number of edges to each path's cost. Routes with different edge counts need not retain their order. For example, edges , , of weights make the two-edge path optimal with cost zero. Adding three changes the direct cost to four and the two-edge cost to six. The graph is a Directed acyclic graph and all shifted weights are positive, yet the minimizing path changes.
Compute shortest-path distances from one fixed source to every vertex, together with predecessor information when shortest paths exist. Dijkstra's algorithm handles nonnegative weights; the Bellman-Ford algorithm admits negative weights and detects reachable negative cycles. A Directed acyclic graph instead permits one pass in topological order.
Initialize source distance to zero and other distances to infinity, then process vertices in topological order, relaxing their outgoing edges once. Every predecessor on a path to a vertex appears earlier, so induction through that ordering proves that its distance is final when processed. Negative weights are allowed because there are no directed cycles. With adjacency lists, topological sorting and all edge relaxations take time; predecessor pointers reconstruct paths.
The infimum of total edge weights over allowed walks from a source to a target. The value is when no route exists. A negative cycle reachable from the source and able to reach the target makes it . In a finite graph without such a cycle, a finite distance is attained by a graph path, after removing non-improving repetitions.
If every nontrivial closed subwalk has strictly positive weight, removing any repeated-vertex segment strictly decreases a walk's weight. Hence a minimum-weight walk must be a graph path, and it is a shortest path. Strictly positive edge weights are sufficient in an undirected graph. For a trail, positivity of every simple cycle is already sufficient: its first repeated-vertex segment is a cycle because no edge is repeated.
Under the usual unrestricted walk convention, positivity of simple cycles alone is insufficient. A graph consisting of one zero-weight edge has no cycles, but the walk is a minimum-weight walk and is not a path. A zero-weight backtrack cannot be removed with a strict improvement. For nonnegative edge weights, one may erase such backtracks without increasing weight and obtain a shortest path, but cannot conclude that every minimum walk was already a path.
In a positive-weight directed graph, run the Dijkstra algorithm from each source and minimize over closing edges. In an undirected graph, minimize only over edges absent from the current shortest-path tree. A tree edge would otherwise give a spurious traversal out and back. A non-tree candidate contains a genuine cycle no longer than its score, even when the two tree routes share a prefix.
For the undirected optimum, choose a shortest cycle and a source on it. If an incident cycle edge is absent from the tree, its candidate is bounded by the cycle length. Otherwise its two neighbours lie in distinct tree branches, and some edge on the remaining cycle segment crosses branches. That edge is non-tree; shortest distances to its endpoints are bounded by the two complementary cycle segments, again giving a candidate no greater than the optimum. Thus the minimum candidate equals the shortest-cycle length. Repeated Dijkstra algorithm runs take running time with a binary heap.
Let be the minimum weight of a route from a fixed source to using at most edges; repeated vertices are permitted. Initialise to zero at the source and infinity elsewhere. Every feasible route either already uses at most edges or appends one edge to such a route, proving the displayed dynamic programming recurrence. Reading exclusively from the previous row enforces the edge budget. Negative cycles cause no unbounded objective because the budget is finite. Each round scans all edges, costing when only edge-incident vertices and the specified endpoints are processed. With nonnegative weights, cycle removal gives an equally good or better simple path within the budget.
In a finite graph with positive integral edge weights, replacing by makes every transformed shortest path minimise original weight first and edge count second. Positive weights imply that an optimal route is simple, with at most edges. Original integral path weights that differ have a gap of at least one; multiplication by outweighs every possible difference in simple-path edge counts. Among equal-weight paths, only the added edge count differs. Thus a single ordinary shortest path computation solves lexicographic weight-and-hop minimisation.
For a graph on vertices with all edge weights in , every minimum-weight shortest path has the smallest possible number of edges. Indeed, positivity permits a simple optimum, and a simple -edge path weighs at most for , while any path with more edges weighs at least . A breadth-first search followed by weighted dynamic programming along increasing-hop edges therefore solves the single-source problem in time. Choosing an arbitrary breadth-first tree alone is insufficient: equal-hop routes may still have different weights.
Suppose two pieces occupy a common connected component of a graph in an unweighted undirected graph. For integers , in each round an evader moves at most edges, then a pursuer moves up to edges along a shortest path to the new evader position, stopping upon capture. Let be their finite graph distance at a surviving round boundary.
The triangle inequality bounds the separation after the evader moves by . If that separation is at most , the pursuer captures it. Otherwise the pursuer reduces it by exactly , givingHence every surviving history has at most rounds. With a finite branching factor, the surviving search tree is finite and depth-first tree search becomes a complete search algorithm. This does not make its first goal optimal for arbitrary rewards. Initial reachability is essential: an infinite graph distance supplies no decreasing finite bound.
Unlike the sum in the usual shortest path problem, the bottleneck cost of a nonempty graph path is its largest edge weight. The optimum is the smallest threshold at which the endpoints become connected by edges of weight at most that threshold. Sorting edges and increasing the threshold, with a disjoint-set data structure maintaining components, finds this value. The minimax path property of a minimum spanning tree provides a single tree representing such optimal routes for every pair of vertices.
A shortest-path tree rooted at a source vertex is a spanning tree whose unique tree route from the source to every vertex solves the shortest path problem in the original weighted graph. Dijkstra's algorithm constructs one for a finite connected graph with nonnegative edge lengths, recording a predecessor whenever a distance improves. It need not be a minimum spanning tree: one minimizes each source-route length, the other the total weight of the tree's edges.
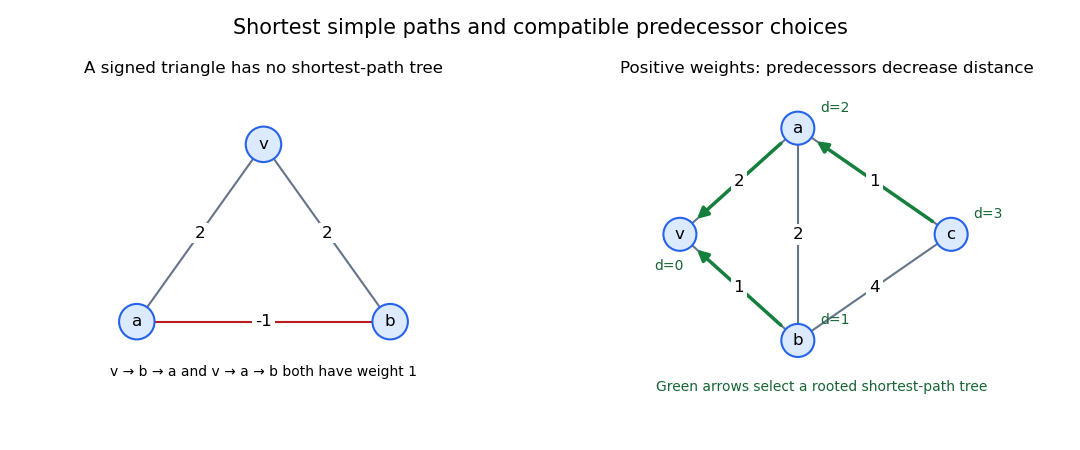
In a finite connected graph with strictly positive edge weights, choose any shortest path from a root to every other vertex , and let be its penultimate vertex. Every prefix is shortest: a better prefix followed by the final edge would give a cheaper walk, whose positive-weight cycles can be erased to give a cheaper path. Thus the displayed distance identity holds.
Following predecessors strictly decreases the shortest-path distance, so no predecessor cycle is possible. Since every nonroot vertex has a predecessor, every chain reaches the root. Opposite predecessor choices cannot select the same undirected edge, again by strict distance decrease. The selected graph is connected and has exactly one edge per nonroot vertex, so is a spanning tree. Along its root paths the distance differences telescope, proving that it is a shortest-path tree even if the original shortest paths were chosen independently.
In a triangle with root , assign and . Among graph paths, the unique shortest path from to is , and that from to is , both of weight one. A shortest-path tree would have to contain all three edges, impossible for a tree. The example uses shortest simple paths; arbitrary walks can have unboundedly negative weight by repeatedly traversing the negative edge.
A graph path of minimum total edge weight between its endpoints, among the permitted paths. In an unweighted graph, its weight is the number of edges. A shortest path need not be unique.
An algorithm that makes each vertex's distance permanent once it is selected. With nonnegative directed edge lengths, the Dijkstra algorithm selects the unfinalized vertex with least tentative distance; a shorter route through another unfinalized vertex is impossible because its remaining route has at least that next tentative distance. For an all-to-one problem, incoming directed edges to the selected vertex are relaxed. Negative lengths can invalidate this finalization argument.
The Bellman inequalities turn local directed edge checks into a global certificate for the shortest path problem. Here the convention is all-to-one: every journey ends at a fixed vertex , and is the cost of the original directed edge . Work in a finite directed graph with finite real costs. Write for candidate labels, normalized by , on the vertices that can reach . A feasible potential means precisely that these finite labels satisfyfor every directed edge within that set. These labels give lower bounds on costs to . A discovered directed path of cost instead gives an upper bound. The following constructed graph shows both bounds and the exact distances between them; its weights are illustrative costs, not measured travel data.
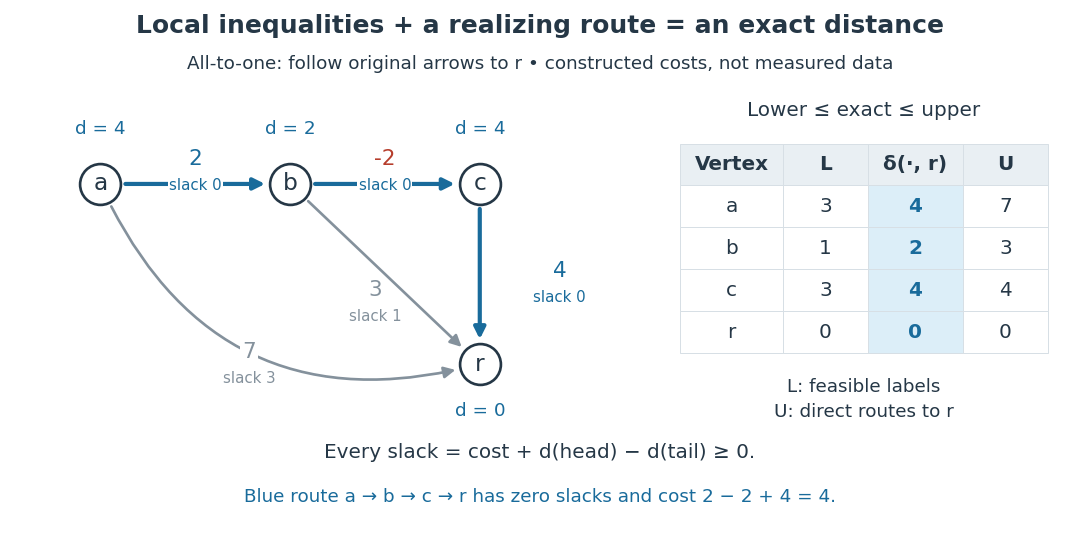
The arrows in the picture point toward the destination, whereas edge relaxation propagates an improved label in the opposite direction: an improved can lower . In the pictured graph, the directed paths from to cost , , and . Thus . The candidate in vertex order is feasible, but underestimates the exact distances . Merely satisfying the Bellman inequalities does not make a candidate exact.
Why do they give lower bounds? Along any directed path , successive substitution givesThe same calculation works for a directed walk, with repeated vertices allowed. Taking the infimum of route costs gives . A discovered route gives . If the bounds meet, , they certify an optimum without enumerating routes. Equivalently, check the Bellman inequalities for the proposed distances and exhibit directed paths realizing them. The authored Bellman-Ford algorithm implementation checks the corresponding single-source inequalities and equality on recorded route edges; reversing every directed edge gives this all-to-one convention.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Sedgewick and Wayne, BellmanFordSP.java, optimality checks
For the exact labels in the picture, the slack is respectively on , , , , . Zero slack means equality; the zero-slack directed path realizes the cost . This is the useful beauty of the certificate: a few local inequalities rule out every cheaper journey, while one explicit journey attains the bound.
Keep unreachable vertices separate: when no directed path to exists, and a finite lower bound alone cannot certify that fact. Extended labels can use for finite , but never compute a slack as . If can reach a negative-cost directed cycle and then reach , repeatedly traversing the directed cycle makes route costs unbounded below: their infimum is , with no finite shortest directed walk. A finite feasible potential on such a directed cycle is impossible, since summing its Bellman inequalities would give . A negative-cost directed cycle that cannot reach does not affect distances to . These are statements about unrestricted directed walks; requiring a directed path with no repeated vertices is a different optimization problem when negative-cost directed cycles exist.[ref]
Lecture 17: Shortest Paths III: Bellman-Ford. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006, Lecture 17, pp. 1 and 5: relevant negative cycles and simple paths
For the single-source convention, the same original directed edge instead gives with , a lower bound on distance from . The endpoint carrying the label on the left therefore changes with the direction of the problem.
An algorithm whose tentative distance labels may be revised repeatedly until all relevant Bellman inequalities hold. Bellman-Ford algorithm uses this approach: a label is an upper bound supplied by a discovered directed path, and relaxing an directed edge can replace it with a shorter discovered directed path. A finite label is not declared permanent merely because it has been processed.
The Bellman-Ford algorithm solves the single-source shortest path problem in a finite directed graph with finite real edge weights, allowing negative weights. It repeatedly applies edge relaxation, so an improved tentative distance can improve its neighbours on a later visit. This makes it a label-correcting shortest-path algorithm.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Robert Sedgewick and Kevin Wayne, BellmanFordSP.java, signed-weight single-source solver and queue-based relaxation
If no negative-cost directed cycle is reachable from the source, at most complete passes suffice for all distances; a further check detects a reachable negative-cost directed cycle.[ref]Lecture 17: Shortest Paths III: Bellman-Ford. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006, Lecture 17, pp. 3–4: complete-pass algorithm, proof and reachable-cycle corollary
There are two orientations to keep distinct. The usual single-source problem asks for distances from , extending routes along outgoing directed edges. The Bellman inequalities above instead concern distances to a sink , prepending incoming directed edges to known routes. The All-to-one Bellman-Ford recurrence below preserves that convention. Reversing every directed edge, with its weight unchanged, converts one problem into the other.
Here is an original single-source example with source , vertex set , and precisely these directed edges:The negative edge is harmless: this directed graph has no directed cycle. Its best route to is , of cost . The other routes to cost through and through .
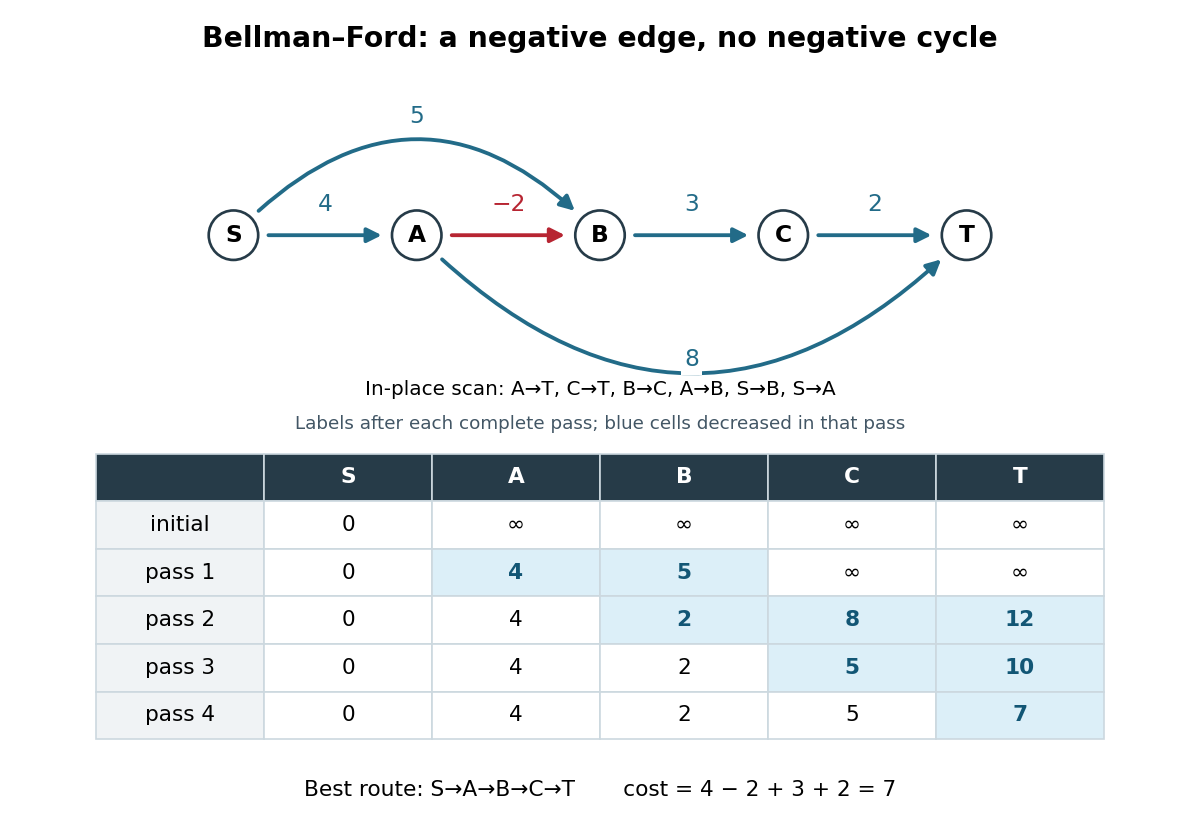
Initialize and the other tentative distances to . In each pass apply single-source edge relaxation, , scanning in the order , , , , , . Skip a candidate with . The figure records labels after each complete pass and uses current labels immediately: it is an in-place trace. In pass 2, still uses , giving ; only later does lower to . Pass 3 carries that improvement to , and pass 4 carries it to . The final labels in order are ; the final shortest-path predecessors are for respectively.
The scan order explains the delay. Scanning instead as , , , , , gives those same final labels in just one in-place pass. The Synchronous Bellman-Ford recurrence has a precise bound on the number of edges used by a recorded route; an in-place pass can propagate along several edges and need not have that interpretation. Both implementations have the pass guarantee under the stated no-reachable-negative-cycle hypothesis.
With a stored list of edges, complete-pass Bellman-Ford algorithm has time complexity and uses extra space for labels and shortest-path predecessors, using Big O notation and constant-cost arithmetic. The extra accounts for initialization even when is empty. A pass with no strict decrease permits early termination. A queue variant instead revisits outgoing edges of vertices whose labels improved; the authored implementation provides this alternative and has worst-case running time on its usual nontrivial instances.[ref]
BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Robert Sedgewick and Kevin Wayne, BellmanFordSP.java, class documentation, constructor and relax method
For nonnegative weights, the Dijkstra algorithm and its existing distance-frontier figure explain how permanent labels can avoid these repeated passes; the existing edge relaxation figure illustrates one update at a time.For the single-source problem, let be the minimum cost of a directed walk from to using at most edges. Set and for , use for finite , and let a minimum over an empty set be . ThenEvery entry on the right comes from the previous round, requiring separate old and new arrays. The proof is the last-edge decomposition: a permitted directed walk either already uses at most edges, or ends with some after a prefix using at most . Conversely, each candidate describes a permitted directed walk. This dynamic programming viewpoint gives an exact meaning to every intermediate label, even when negative-cost directed cycles exist. Apply the formula to the source too: its initial zero is not a permanent constraint.
If no negative-cost directed cycle is reachable from , removing repeated-vertex portions of a directed walk cannot increase its cost. Whenever a destination is reachable, some shortest directed path therefore uses at most edges, and . Unreachable vertices keep distance . For in-place passes, every finite label still comes from a discovered directed walk; moreover, pass has offered every prefix of length of a shortest directed path, regardless of scan order. Its labels can improve faster than the synchronous labels, while the same upper bound on passes remains valid. This is why repeated local corrections eventually settle a global shortest path problem.
A negative-cost directed cycle matters to a particular destination precisely when it is reachable from and can itself reach .[ref]
Lecture 17: Shortest Paths III: Bellman-Ford. 6.006 Introduction to Algorithms, Fall 2011 by Massachusetts Institute of Technology, 6.006 course staff; MIT 6.006, Lecture 17, p. 1: cycle between source and destination; p. 4: reachable-cycle corollary
Repeating it times adds times its negative total cost to a route. Thus the infimum of directed walk costs is , rather than the cost of a finite shortest directed walk. The distinction is about reachability, not simply the presence of a negative edge or a negative-cost directed cycle anywhere in the graph.Add of weight to the worked example. Now has total weight . Add also an isolated vertex with a self-loop of weight . From , the distances of are , because all four are reachable from the first negative-cost directed cycle. The source retains distance : no directed edge leads back to . The unreachable retains distance , despite its negative-cost self-loop.
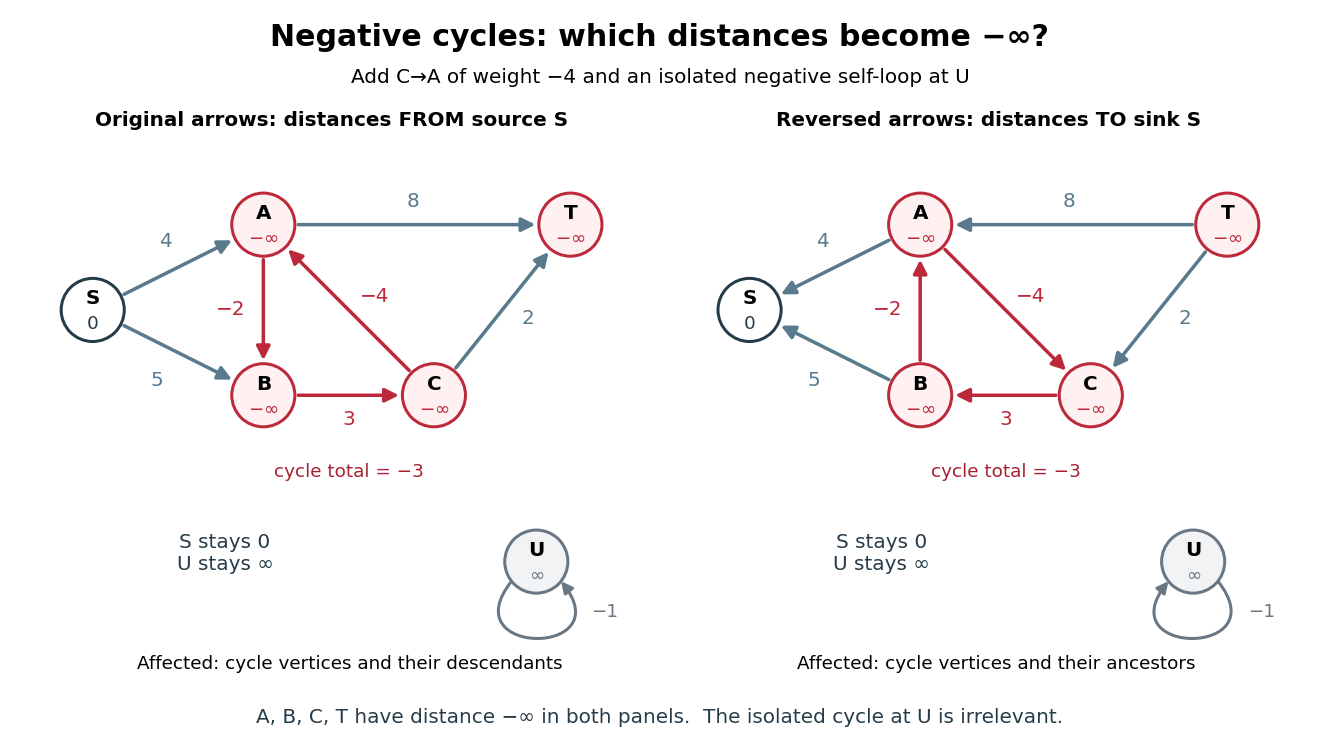
Relevant negative-cost directed cycles: descendants from a source become ancestors when every directed edge is reversed
. Details. For example, extra laps before proceeding to give costs . This construction also shows why requiring a directed path with no repeated vertices would change the problem: only directed walks permit arbitrarily many laps. Merely finding one reachable negative-cost directed cycle does not justify setting every reachable label to ; in the figure is a counterexample.
To detect and classify, perform full passes without clamping any label, then test all directed edges against a fixed copy of the resulting labels. Collect heads of edges satisfying and . An empty collection certifies that no negative-cost directed cycle is reachable from . Otherwise run graph search forwards from all collected vertices: precisely the reached vertices have distance . A vertex unreachable from still has distance ; each remaining vertex has its finite shortest distance.
Why is this classification exact? Every unaffected reachable vertex already has its shortest distance after passes, since any route ending there avoids reachable negative-cost directed cycles. Thus it cannot be the head of a strict improvement, or be reached from such a head. Conversely, all vertices on a reachable negative-cost directed cycle have finite labels by that time. If none of its edges could improve a label, summing around it would imply . At least one of its heads is therefore collected, and the forward graph search reaches the entire directed cycle and every affected descendant. Detecting a directed cycle alone and marking its descendants are separate tasks; finite intermediate labels in the affected region are not answers.
Keep the original all-to-one orientation of the Bellman inequalities: concerns routes from to a fixed sink , and belongs to the original directed edge . Initialize and for . The synchronous dynamic programming recurrence isIt prepends the first edge of a route instead of appending the last: is the minimum cost of a directed walk from to using at most edges. In particular, improving can improve labels on incoming directed edges . The same original directed edge therefore updates its tail in this convention, whereas single-source edge relaxation updates its head.
If no negative-cost directed cycle can reach , rounds suffice for every distance to , and automatically. This hypothesis concerns directed paths from the cycle to the sink, not paths from the sink to the cycle. In the base example with its original arrows and sink , the distances in order are . Once of weight is added, instead have distance to , while keeps distance and keeps .
More generally, precisely when can reach a negative-cost directed cycle that can reach . Thus the affected vertices are the ancestors of such a directed cycle. A negative-cost directed cycle unable to reach is irrelevant. Reversing all arrows makes a single source, turns these ancestors into descendants, and makes the detection and forward graph search above directly applicable. The right panel of the figure uses that reversal with sink ; its distances to equal the left panel's distances from .
Do not force the root to remain zero outside the hypothesis. Consider the two directed edges of cost and of cost , with sink . The recurrence gives and : the latter records one lap of a negative-cost directed cycle through . Repetition makes both unrestricted distances . Clamping at zero and omitting its update would instead leave the stationary labels , concealing that behaviour. Initialization specifies the cost of the empty directed walk; it does not forbid cheaper nonempty returns to the root. Cycle detection must test every relevant directed edge, including those whose relaxation updates the root.
The Dijkstra algorithm solves the single-source shortest path problem in a finite graph with nonnegative edge weights, finding distances to all reachable vertices. Start with tentative distance and elsewhere. Repeatedly choose the unfinalized vertex with least tentative distance, declare that label permanent, and perform edge relaxation on its outgoing edges. For an undirected graph, inspect both directions. A finite tentative distance always records the cost of a discovered graph path, but can improve before finalization.
In our example, finalizing discovers at , at , and at . Choose next: edge relaxation through lowers to and to . Choose : edge relaxation through lowers to . Finally choose . The permanent distances are therefore , , , ; the evolving tentative distances were and .
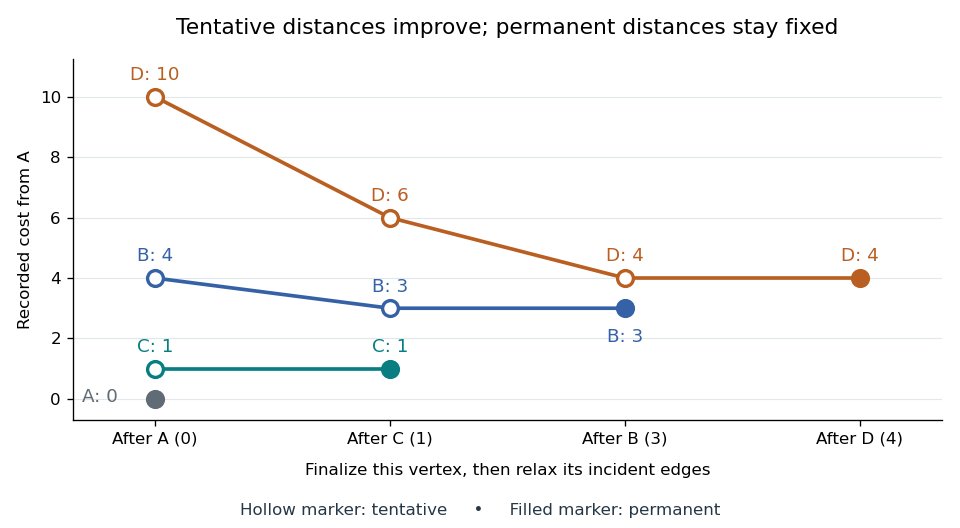
Tentative distances fall until the Dijkstra algorithm makes each label permanent
. Details. Store a shortest-path predecessor whenever edge relaxation improves a label. The final table contains enough information to reconstruct routes, rather than merely their costs:
| Vertex | Distance from | Shortest-path predecessor | Finalization order |
|---|---|---|---|
| None: source | |||
Following shortest-path predecessors backwards gives ; reversing the order gives . If only this destination matters, stop when is finalized. Stopping when is first discovered would incorrectly return . If the smallest remaining tentative distance is , all remaining vertices are unreachable.
Why is the permanent choice safe? Suppose the selected vertex had a cheaper graph path. Let be the first unfinalized vertex on that graph path. Its preceding vertex was finalized, so edge relaxation has already offered a label no larger than that prefix's cost. Nonnegative remaining edge weights make the whole cost at least this prefix's cost; selection gives . A cheaper graph path would contradict these comparisons. Zero weights are allowed; ties can be resolved arbitrarily. This is the reason the label-setting shortest-path algorithm works, rather than a lucky feature of the drawing.
Negative weights break that reasoning. In a directed graph with costing , costing , and costing , the Dijkstra algorithm would finalize at before discovering the cheaper cost . The Bellman-Ford algorithm handles negative edge weights when no relevant negative directed cycle exists.
With an adjacency list and an indexed binary heap implementing a priority queue, the time complexity is for , using Big O notation. Each vertex is extracted at most once, each edge is inspected once per direction, and each successful edge relaxation decreases a heap key in time. This assumes constant-cost arithmetic and comparisons; exact computation with very large weights adds their representation cost. The queue uses space beyond the graph. Simply scanning all remaining vertices gives instead.[ref]
https://algs4.cs.princeton.edu/44sp/DijkstraSP.java.html. Princeton, DijkstraSP implementation
[ref]https://algs4.cs.princeton.edu/code/javadoc/edu/princeton/cs/algs4/IndexMinPQ.html. Princeton, indexed binary heap operations
The 1959 paper presents the shortest path problem as its second problem, after the minimum spanning tree problem, and grows known shortest routes in increasing distance order.[ref]
https://www.cs.yale.edu/homes/lans/readings/routing/dijkstra-routing-1959.pdf. Dijkstra, A note on two problems in connexion with graphs, pp. 269–271
In his later recollection, Dijkstra dated the shortest-route discovery to 1956: a demonstration for the ARMAC computer used a simplified Dutch railway map and printed the route between towns. A practical request became an enduring algorithm because the same distance rule applies to any suitable graph.[ref]https://garfield.library.upenn.edu/classics1983/A1983QA19900001.pdf. Dijkstra's recollection, published in 1983
Among paths of minimum total weight, choose the fewest edges. Store a lexicographic order pair and extend it across weight as . For positive edge weights, every extension strictly increases its first component, so Dijkstra's algorithm settles these pairs correctly when its priority queue and relaxation both compare the full pair. Equal total weight then selects the smaller hop count; arbitrary vertex-name tie-breaking does not express this objective.
A tentative distance is the cheapest cost so far recorded by a shortest path problem algorithm. For the single-source convention, initialize and elsewhere. Every finite label is the cost of a discovered route from to , soIt is an upper bound supplied by an actual route, not a guess that might be too low. The loop invariant follows directly from edge relaxation: extending a discovered route to by supplies another discovered route. The usual label initialization and this safety property are stated and proved in the authored MIT notes.[ref]
https://ocw.mit.edu/courses/6-006-introduction-to-algorithms-fall-2011/6277a1f06100c26a7ff21031af6757b5_MIT6_006F11_lec16.pdf. MIT 6.006, Lecture 16, p. 1: relaxation safety
In the trace under edge relaxation, first records the direct directed path . Later records , and finally records . Each label is a usable route cost, but the first two are not shortest. An infinite tentative distance means no route has yet been discovered; only a completed search establishes unreachability. The isolated vertex in that example remains at .
In a directed graph, the discovered route is formally a directed walk, which may repeat vertices; in the pictured acyclic graph it is always a directed path. Negative-cost directed cycles can keep supplying cheaper directed walks without a finite optimum. In the all-to-one convention, the same meaning applies to discovered routes from to . Do not confuse either version with the lower bounds supplied by feasible potentials in the Bellman inequalities: one records something achievable, the other rules out anything cheaper.
Edge relaxation tests whether extending a recorded route by one directed edge improves a tentative distance. For a single source and an original directed edge of weight , form the candidate . If is finite and , replace by and record the shortest-path predecessor . Otherwise leave both unchanged. The minimum formula in the header gives the resulting label in either case. The authored implementation uses this strict comparison and records the incoming directed edge.[ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/DijkstraSP.java. Sedgewick and Wayne, DijkstraSP.java, relax method
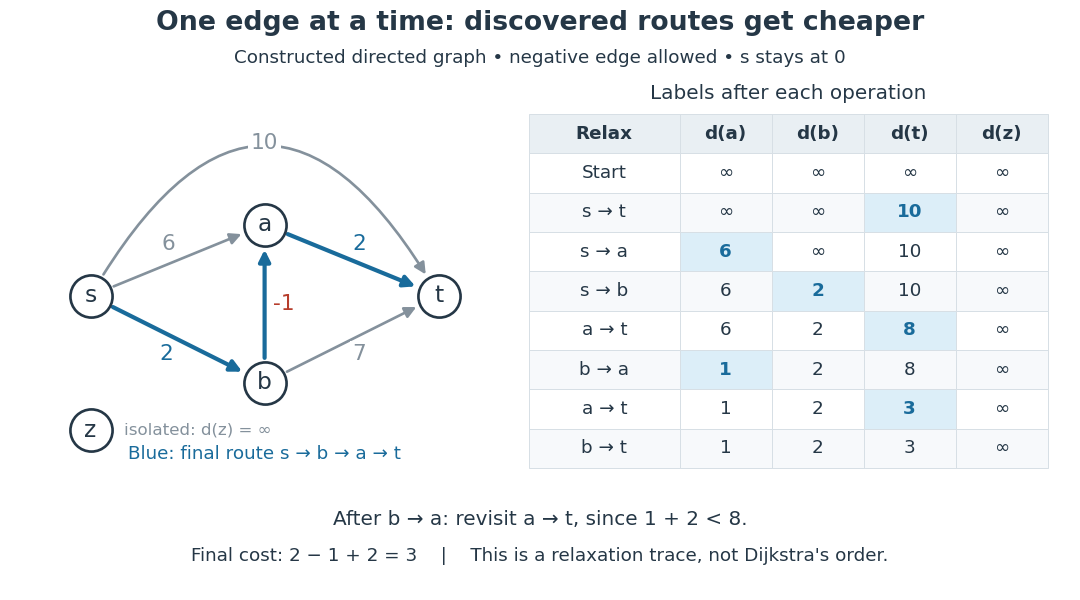
The table lists labels after each specified operation, keeping throughout this constructed acyclic graph. Relaxing first offers . Relaxing then offers , lowering from to ; revisiting now offers . Finally offers , so the label stays. Changing a label can make a previously checked outgoing directed edge worth checking again. This trace illustrates the operation itself, with a deliberately specified order, rather than a run of the Dijkstra algorithm.
A single edge relaxation does not require nonnegative weights: its candidate is the cost of a real extended directed walk, even when the last directed edge has negative weight. Nonnegative weights are needed by the Dijkstra algorithm to make its selected minimum tentative distance permanent. The Bellman-Ford algorithm permits negative weights and revisits labels; its authored implementation also checks for reachable negative-cost directed cycles.[ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/DijkstraSP.java. Sedgewick and Wayne, DijkstraSP.java, nonnegative-weight precondition
[ref]BellmanFordSP.java. Algorithms, 4th edition by Robert Sedgewick and others; Sedgewick and Wayne, BellmanFordSP.java, signed weights and cycle detection
For the all-to-one convention of the Bellman inequalities, relax the same original directed edge by . This prepends to a discovered route from to , and improves the tail label , not the head label . Skip the operation when . In exact arithmetic, a full pass over all relevant directed edges with no improvement establishes all their Bellman inequalities; combined with the discovered-route upper bounds, this certifies finite distances. One unsuccessful operation establishes only that this particular candidate did not improve its label at that moment.
A shortest-path predecessor records the previous vertex on a chosen route from source to . When edge relaxation strictly improves through , set . For a multigraph, store the actual directed edge, since two edges with the same endpoints can have different weights. Initialize all vertices, including the source, without a shortest-path predecessor. The authored implementation reconstructs a route by following these incoming edges backwards, then reversing their order.[ref]
https://raw.githubusercontent.com/kevin-wayne/algs4/master/src/main/java/edu/princeton/cs/algs4/DijkstraSP.java. Sedgewick and Wayne, DijkstraSP.java, edgeTo and pathTo
At the end of the edge relaxation trace, , , and . Following them gives , so the forward directed path is , of cost . This makes the distance useful: a number tells us the best cost, whereas the shortest-path predecessors tell us which connections to take. In the Dijkstra algorithm, reconstruct a destination's shortest route after its label becomes permanent. In a label-correcting shortest-path algorithm, wait for convergence and the appropriate negative-cost directed cycle check. During correction, a predecessor's label may have changed since its child's last update: immediately after in the trace, the current chain to costs although still records the earlier discovered route of cost .
Strict improvement is a useful guard against directed cycles in the recorded pointers. Consider and of cost zero, followed by and , also of cost zero. After the first two edge relaxations, both labels are zero and both shortest-path predecessors are . If equality also allows pointer replacement, the last two operations can set and : following pointers loops forever despite correct distance labels. Keeping the old pointer on ties prevents this example; choosing among equal-cost routes requires a separate rule that preserves a route to the source. Strict improvement alone does not protect against reachable negative-cost directed cycles, which can force endless decreases. Equality on recorded edges plus the Bellman inequalities certifies route costs only when the pointer chains actually terminate at the source.
For all-to-one distances to , record a next vertex whenever relaxing improves . Follow these successors forward in the original directed graph to reach . They are shortest-path predecessors when viewed in the reversed directed graph; keeping the direction convention explicit prevents returning a route whose arrows point the wrong way.
A graph property is a class of finite graphs closed under isomorphism. Its labelled order- slice consists of members on vertex set . Closure under taking arbitrary subgraphs and closure under taking only induced subgraphs lead respectively to subgraph-closed graph properties and hereditary graph properties.
All edges of a simple undirected graph have at least one common endpoint. The empty graph is included when there is at least one vertex, and isolated vertices are permitted. This is the star predicate with isolated vertices allowed; a connected star graph is a special case. Its decision-tree depth is the full number of edge bits for .
For , a full star graph requires every nonincident edge to be certified absent, and fixing those bits suffices. Rejection is certified by at most three present edges with empty common intersection; a triangle needs all three. Hence query certificate complexity is for this property.
For , count the empty graph once, all one-edge graphs once, and each larger accepted graph under its unique center. The latter weighted contribution is , giving . Its nonzero value proves evasiveness by the alternating-sum criterion for decision-tree evasiveness.
The speed counts the labelled graphs with a given property on vertex set . For proper unbounded hereditary graph properties, its base-two logarithm has leading term , where is the property's colouring number.
A hereditary graph property is closed under taking induced subgraphs. It can be described by forbidden induced graphs. Unlike subgraph closure, this condition allows edges to be essential to membership. Its colouring number of a hereditary graph property governs its quadratic enumeration rate.
This parameter measures the largest completely unrestricted clique-independent partition class contained in the property. It is zero for bounded-order hereditary classes and infinite for all graphs. For proper unbounded classes it is a positive integer; it differs from the degeneracy-based colouring number of an individual graph.
For a proper hereditary graph property with unbounded orders, the colouring number determines the leading labelled speed. The lower bound comes from one contained clique-independent partition class. For the upper bound, forbid one induced graph from each next-size partition type and use the induced regularity template lemma. Its intermediate-pair graph is clique-free, and sparse or almost-complete pairs have negligible entropy. Bounded-order properties have colouring number zero and are outside this formula.
Graphs in admit a partition into total classes, of which are designated cliques and are designated independent sets. Cross edges are arbitrary and empty classes are allowed. Balanced cross-edge choices give quadratic labelled speed coefficient . Comparing this count with every -class type shows that the hereditary colouring number of this class is exactly .
Membership is preserved under deleting vertices and edges. This is the decreasing meaning of monotonicity in extremal graph enumeration; it differs from an increasing monotone graph property used for random-graph thresholds. For a proper unbounded class, its least excluded chromatic number determines the leading quadratic logarithm of its labelled speed.
Articles were limited to the first 100 out of 883 total.
Articles by others on the same topic



Graph theory is a branch of mathematics and computer science that studies the properties and applications of graphs. A graph is a collection of nodes (or vertices) connected by edges (or arcs). Graph theory provides a framework for modeling and analyzing relationships and interactions in various systems. Key concepts in graph theory include: 1. **Vertices and Edges**: The basic building blocks of a graph. Vertices represent entities, while edges represent the connections or relationships between them.