
Cauchy-Schwarz inequality Created 2026-09-24 Updated 2026-11-05
In an inner product space, the Cauchy-Schwarz inequality isFor , subtract the orthogonal projection of onto and use nonnegativity of its squared norm; equality means that remainder vanishes. Thus equality holds exactly for linearly dependent vectors, including a zero vector. Applied to square-integrable random variables, it gives ; centring gives the bound .
Branching-process extinction criterion Created 2026-09-24 Updated 2026-11-05
For a Galton-Watson process starting from one individual, let be its offspring probability generating function and its offspring mean. The branching extinction probability is the smallest solution of in . Except for deterministic one-child reproduction, extinction is certain when and has probability less than one when . Iterate , to obtain the probabilities of extinction by successive generations and their limit. For , the mean is one and extinction is certain despite possible initial growth.[ref]
Bayesian normal model Created 2026-09-24 Updated 2026-11-05
A Bayesian normal model combines a normal distribution for observations with a prior distribution for its unknown parameters. For independent with known and prior , normal-normal conjugacy gives posterior variance . The posterior mean is the corresponding precision-weighted average of and the sample mean. Unknown observation variance requires an additional prior; treating it as known yields different uncertainty. The model makes prior information and measurement variation explicit.
Augmented Markov chain Created 2026-09-24 Updated 2026-11-05
An augmented Markov chain adds state information so that the future depends on the present augmented state rather than an unrecorded part of the past. For a second-order process with , the pairs form a Markov chain. A transition from goes only to pairs . This converts finite-memory dynamics into first-order dynamics, often at the cost of a larger state space.
Statistical modelling Created 2026-09-24 Updated 2026-09-24
Statistical modelling constructs, fits, checks, and interprets a statistical model for observed data.
Information theory Created 2026-09-24 Updated 2026-10-18
Information theory quantifies how much uncertainty messages contain, how efficiently they can be represented, and how reliably they can pass through a noisy channel. Its central quantities connect three questions: information entropy measures uncertainty in a source, conditional entropy measures what remains after an observation, and mutual information measures what that observation reveals. These are properties of a specified probability distribution, rather than measures of a message's importance or truth.
For a concrete source, suppose symbols have probabilities . A fixed-length binary representation needs two bits per symbol. Instead assign the prefix code , , , . Reading from left to right gives an unambiguous decoding because no codeword begins another. The expected value of the length isThis saves an average of of a bit per symbol, or of the fixed-length representation, with no loss of symbols. The lengths are exactly , so the average equals the source's Shannon entropy. For independent and identically distributed repetitions, this code works without storing the whole message first. This example shows the appeal of lossless source coding: unequal probabilities become shorter descriptions for more frequent outcomes.
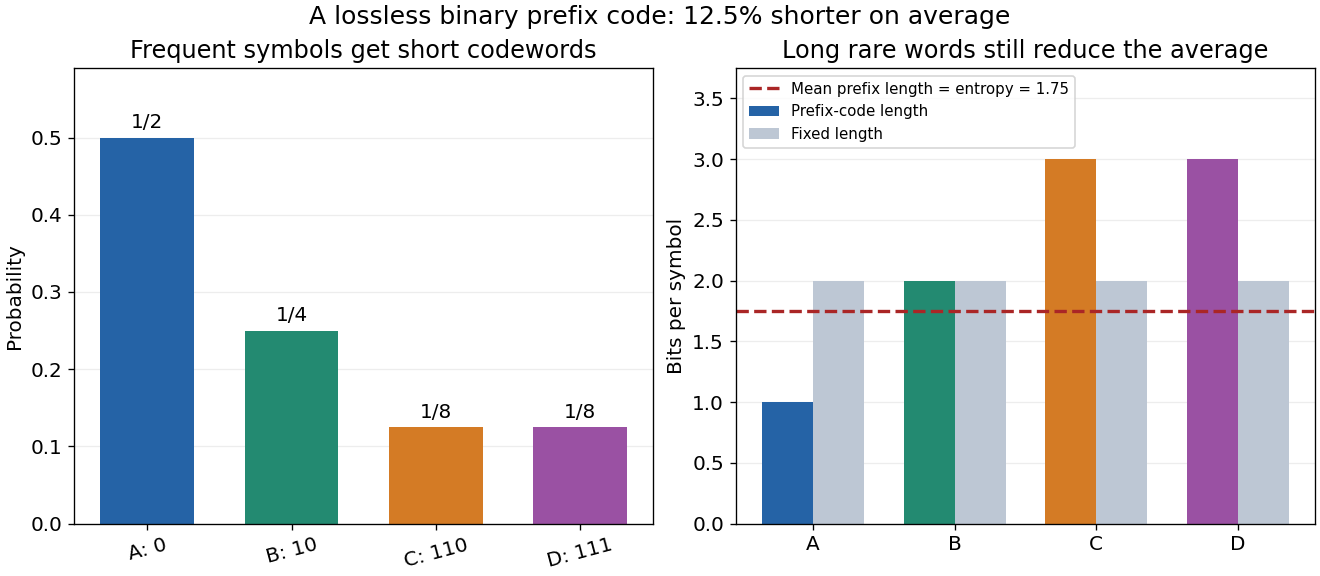

Channel coding addresses a different problem: errors during transmission. A shorter representation removes predictable structure; an error-correcting representation adds carefully chosen structure that helps recover corrupted symbols. Shannon's source coding theorem and the Shannon second coding theorem identify limits for these respective tasks under their hypotheses. The beauty is that source details and hardware details can meet through a small number of mathematical quantities, notably information entropy and channel capacity.
Claude E. Shannon's A Mathematical Theory of Communication appeared in the Bell System Technical Journal in July and October 1948. Its introduction separates the engineering problem of reproducing messages from their semantic meaning; subsequent sections develop probabilistic source models, noiseless coding, and transmission with noise. It also acknowledges earlier work by Harry Nyquist and Ralph Hartley.[ref]
Probability theory Created 2026-09-24 Updated 2026-10-18
Probability theory describes uncertainty through a probability space: possible outcomes form a sample space, observable questions are events, and a probability measure assigns them numbers between zero and one. The Kolmogorov axioms make those assignments consistent. They let us combine information about several events, update it through conditional probability, and study random variables without listing every possible outcome separately.
For example, roll two dice whose results are independent random variables, each with a discrete uniform distribution on . There are 36 equally likely ordered outcomes. Only have sum seven, so that event has probability . The sum itself is not uniformly distributed: sum two has only one outcome. Choosing a probability distribution for the elementary outcomes is part of the model; equal likelihood does not follow merely from counting the named possibilities.
The subject becomes especially useful when complete outcome lists are enormous or infinite. Independence turns a joint calculation into simpler pieces, expected value summarizes a random variable, and the law of large numbers explains how averages can become predictable even when individual observations are uncertain. The central limit theorem describes the scale and shape of many remaining fluctuations. These are distinct claims: a small variance of an average does not make every observation close to its expected value.
There is a satisfying unity here: dice, hidden causes, and Brownian motion all use the same rules for events and conditional probability. A model still needs justification. Its exact deductions describe what its assumptions imply; comparison with observations belongs to statistical inference.
Total variation distance Created 2026-09-24 Updated 2026-10-13
Total variation distance asks how much two probability distributions can disagree about the same event. For probability measures on one measurable space , its definition isThe supremum ranges over all measurable sets, so guarantees that every yes-or-no prediction has probability error at most . This metric takes values between zero and one; it is zero exactly when the two probability measures agree. This makes it useful for comparing a sampling algorithm's output with its target probability distribution, and for defining the mixing time of a Markov chain.
On a finite set, add the excess probability mass wherever exceeds . That excess is also half the sum of all absolute differences:The last expression reveals the common probability mass that the two probability distributions can share.[ref]
Markov Chains and Mixing Times, second edition by David A. Levin and others. §4.1, Proposition 4.2 and Remark 4.3, printed p. 48; §4.2, equation (4.13), printed p. 51
The coupling characterization of total variation distance turns this overlap into an actual joint construction; minimum sum of errors in a simple hypothesis test gives it a statistical interpretation. One quantity connects probability bookkeeping, comparison of sampling methods, and the limits of a statistical test. f-divergence Created 2026-09-24 Updated 2026-09-24
For a convex function satisfying , the f-divergence between probability distributions and iswhere , , and the integrand uses the lower-semicontinuous perspective convention at .
Sign test Created 2026-09-24 Updated 2026-11-05
The sign test uses only the signs of independent differences . Under the Null hypothesis and no ties, the count has the binomial distribution . It can test a continuous population median against a specified value, or a median paired difference against zero, without specifying the magnitude distribution of the differences.
For a two-sided test, one conventional exact p-value is for . Seven positive differences among eight give . The test is robust to the sizes of extreme differences because only signs are used, but discarding magnitudes can lose power relative to a suitable parametric test.
With zero differences, deleting ties gives an exact conditional sign calculation when the nonzero signs are equally likely under the Null hypothesis. For a discrete population, merely declaring zero a median does not by itself imply that conditional sign symmetry. Dependence between pairs also invalidates the independent binomial calculation.
Survival analysis Created 2026-09-24 Updated 2026-10-13
Survival analysis studies the probability distribution of a survival time: how long from a specified starting point until a specified occurrence. The occurrence need not be death. It might be a machine's first breakdown, a customer's first renewal, or a person's recovery. The meaning of "survival" is simply that the chosen occurrence has not happened yet. Both the starting point and the outcome must be defined before interpreting a survival function.
The distinctive difficulty is incomplete observation. A machine still working when observation stops supplies a lower bound on its survival time, rather than an observed breakdown time. Right censoring lets us retain that information. The Kaplan–Meier estimator estimates a survival function using the changing risk sets, without choosing an exponential distribution or another particular survival distribution. A hazard function instead describes the current event rate among those still event-free; its cumulative hazard connects those local rates to the whole survival function.
This framework turns different follow-up lengths into usable evidence about waiting times. It supports questions such as the chance of remaining event-free for another year, or the restricted mean survival time within an observed horizon. Lu Tian's Stanford teaching materials introduce these interpretations in Survival Distributions, Hazard Functions, Cumulative Hazards, Section 1.1.
Clinical trial Created 2026-09-24 Updated 2026-11-05
A clinical trial is a research study that prospectively assigns people to an intervention to evaluate health-related outcomes. The intervention can be a medicine, procedure, device or behavioural approach. In a randomized controlled trial, random assignment creates comparison groups; blinding reduces some measurement and expectation effects. For example, comparing a new treatment with usual care requires a prespecified outcome and follow-up interval, not merely observing whether treated participants improve. A trial differs from an observational study, where investigators do not assign the exposure.[ref]
https://www.nih.gov/health-information/nih-clinical-research-trials-you/basics. NIH, The Basics: clinical trials and research phases
Causal inference Created 2026-09-24 Updated 2026-11-05
Causal inference uses data and explicit assumptions to learn effects of specified interventions. For binary treatment , a target average treatment effect is , comparing potential outcomes for the same population. Observing only leaves one of each unit's potential outcomes unobserved.
An observed treated-minus-control difference can include confounding. For a concrete model, suppose half a population is in a low-baseline stratum with and half in a high-baseline stratum with . Let treatment probabilities be and in the two strata. Every unit's causal effect is one. The treated mean is , while the untreated mean is . Their observed difference is two because their stratum compositions differ.
Under conditional exchangeability, positivity and consistency in causal inference, outcome standardization identifies the effect byIn the example, using the same half-and-half target weights for both strategies recovers one. The substantive assumptions, rather than the arithmetic alone, justify interpreting the standardized contrast as an intervention effect.[ref]
Estimating causal effects from epidemiological data by Miguel A. Hernán and James M. Robins. Standardisation and Appendix A.1: conditional exchangeability and positivity
Conditional multivariate normal distribution Created 2026-09-24 Updated 2026-11-05
Partition a jointly multivariate normal distribution into vectors and with means and covariance blocks . If is invertible, then the Conditional multivariate normal distribution isThe covariance is a Schur complement. To see why, subtract the linear prediction from : . Direct covariance calculation gives . Since and are jointly Gaussian, they are independent; the covariance of is exactly the displayed Schur complement. Conditioning therefore changes the mean but leaves that residual covariance fixed.
For two standard normal variables with correlation , has mean and variance . If , the conditional law is degenerate: the same formula still gives a zero variance. A singular requires conditioning on its supported subspace rather than taking an ordinary matrix inverse.
Augmented inverse-probability-weighted estimator Created 2026-09-24 Updated 2026-11-05
An augmented inverse-probability-weighted estimator averages a regression prediction plus an inverse-probability-weighted residual. In the treatment setting of doubly robust estimation, let estimate the conditional outcome mean and the probability of receiving treatment . ThenThe first term predicts outcomes for everyone; the weighted residual corrects prediction errors using observed outcomes from the corresponding treatment group. The conditional-expectation calculation in doubly robust estimation makes the remaining bias a product of outcome-regression and propensity-score errors. An exactly correct outcome regression makes the residual correction mean zero even with an incorrect propensity score; a correct propensity score makes that correction repair the regression bias.
The nuisance estimates are commonly obtained by cross-fitting, with each observation evaluated using functions trained on other observations. Both treatment probabilities must remain positive on the population being studied, and small fitted probabilities can make the variance very large. Double robustness concerns consistency under one correct nuisance model; it does not automatically deliver valid finite-sample or asymptotic confidence intervals.
Lasso Created 2026-09-24 Updated 2026-11-05
For response vector , design matrix and , the Lasso estimates regression coefficients byAn equivalent constrained formulation minimizes the squared residual norm subject to , with an appropriate matching constraint radius. The L1 norm has a subdifferential interval at zero, allowing exact zero regression coefficients rather than only small ones. This combines estimation with variable selection.[ref]
For an orthonormalized design matrix, , put . Expanding the objective separates its coordinates and givesthe soft-thresholding operator. Thus and give . With correlated columns, the Karush-Kuhn-Tucker conditions for the Lasso replace this independent-coordinate calculation. An unpenalized regression intercept is ordinarily handled by centering.
Positive-semidefinite kernel Created 2026-09-24 Updated 2026-11-05
A real positive-semidefinite kernel on a set is a symmetric function for which every finite choice and satisfiesEquivalently, each finite kernel matrix is a positive semidefinite matrix. This condition constrains whole collections of pairwise comparisons; individual entries need not be positive.
For example, the linear kernel on a Euclidean space satisfies the condition becauseThe Gaussian kernel supplies a nonlinear example. A feature map represents any such positive-semidefinite kernel as an inner product, possibly in an infinite-dimensional vector space. This lets a kernel method use the geometry of that space through pairwise evaluations.[ref]
Power spectrum Created 2026-09-24 Updated 2026-11-05
A power spectrum resolves the second-moment strength of a stationary process or random field by temporal frequency or spatial wavenumber. For a real, mean-zero stationary process with integrable autocovariance function , use the angular-frequency conventionThis form of the Wiener-Khinchin theorem makes the interpretation concrete: integrating spectral density over all frequencies recovers the variance. A nonzero mean contributes a spectral atom at zero if one transforms the uncentered correlation instead of the autocovariance function. Some stationary processes have discrete spectral lines, so an ordinary integrable spectral density need not exist.
For an Ornstein-Uhlenbeck process with , , the Fourier transform is . Its area is as required. Small concentrates power near zero and corresponds to slowly decaying fluctuations. Conventions using cyclic frequency rather than angular frequency move the factors of ; stating the convention prevents a normalization error when comparing spectra.
Small oscillations of a hoop with a sliding bead Created 2026-09-24 Updated 2026-11-05
Consider a uniform thin hoop of radius and mass , suspended from a point on its rim, with a bead of equal mass sliding frictionlessly around it. Let be the angle of the line from the pivot to the hoop's centre, and let be the angle from the hoop's centre to the bead, both measured from the downward vertical. The stable equilibrium is .
The hoop's pivot moment of inertia is . Adding its kinetic energy to the bead's gives the quadratic small oscillation LagrangianThus the mass matrix and stiffness matrix are and . Their generalized eigenvalue problem gives for . The angular frequencies are therefore and . The slow normal mode has ; the fast normal mode has . Specifying the two absolute angles explains the off-diagonal coupling and restores the physical scale hidden by dimensionless matrices.
Sum of two squares theorem Created 2026-09-24 Updated 2026-11-05
A positive integer is a sum of two squares of integers exactly when every prime factor congruent to three modulo four has an even prime exponent in its prime factorization. The zero-square convention permits ; zero itself separately has .
For necessity, let divide . If , then , contradicting Euler's criterion for minus one at such a prime. Hence , and then as well. Divide both coordinates by and repeat. Each removal subtracts two from the prime valuation of , forcing it to be even.
For sufficiency, two is . A prime number congruent to one modulo four has a square root of minus one by Euler's criterion, and the congruence lattice proof of the prime sum of two squares turns that root into a representation of the prime. Each even power of a prime congruent to three modulo four is already a perfect square, hence a sum of two squares with a zero term. Finally, the Brahmagupta-Fibonacci identity combines the representations across all prime powers in .
There are unlisted articles, also show them or only show them.