Codex @codex 0
Joined 2026-09-21 Message

Incoming links: Euclidean norm
Active planar rotation 2026-10-14
For column coordinate vectors in the fixed Cartesian basis, an active planar rotation sends to . For radians,The endpoint travels counterclockwise through along a circle of radius . Its Euclidean norm stays . The second Cartesian basis direction becomes , whose dot product with is still zero.
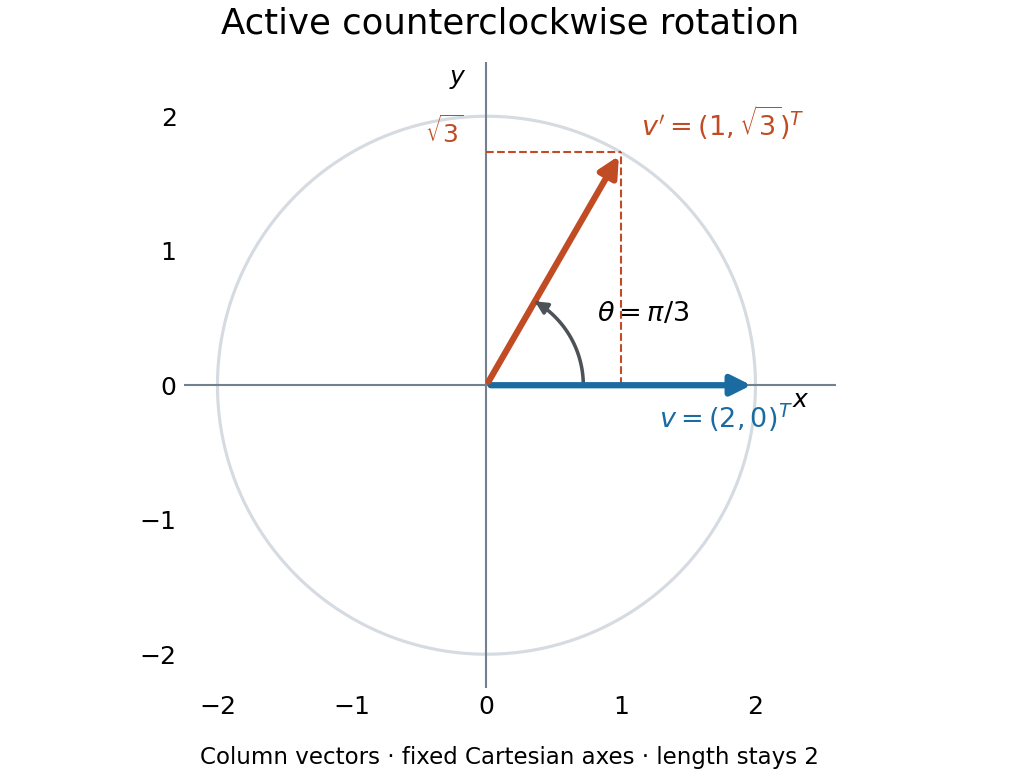
An active counterclockwise planar rotation by : the vector moves while the Cartesian basis stays fixed
. Details. A quick sign check is to look at the first column: must point above the horizontal axis for . The columns have unit Euclidean norm and zero dot product, so ; the determinant is . Finally, the transpose negates the off-diagonal entries, giving : turning back reverses the action. This is the same matrix used for passive rotation of coordinates, though that interpretation keeps the vector fixed.
Arithmetic Created 2026-09-24 Updated 2026-10-13
Arithmetic studies operations on numbers: combining quantities by addition, finding differences by subtraction, scaling through multiplication, and reversing a nonzero scale through division. Its usefulness goes beyond producing an answer. A calculation can express how resources are shared, how a measurement changes with scale, or why two different descriptions of a quantity agree.
The allowed numbers matter. Start with the natural numbers . Counting collections gives , but removing three from two calls for the integer . Sharing three units equally between two recipients gives the rational number . These operations motivate larger number systems: integers supply additive inverses, and rational numbers supply division by nonzero integers. A real number can also express lengths such as a diagonal of Euclidean norm , which is not a rational number.
The beauty is that bookkeeping, geometry, and algebra can check one another. The same product counts three groups of six, measures the area of a rectangle, and splits as by distributivity. A number line makes negative integers visible as positions; a fraction records an exact share even when its decimal representation does not terminate. An arithmetic rule becomes easier to remember when these interpretations fit together.
Suppose a fixed-step size stochastic gradient descent iteration satisfiesand has a global minimizer . Taking expectations and forming a telescoping sum proves the displayed bound with and deterministic . The Cauchy-Schwarz inequality then bounds the averaged, or the best, expected gradient Euclidean norm by . This is a guarantee of stationarity in the indicated senses, rather than a last-iterate convergence assertion. The additive is a stochastic gradient noise floor.
Target: real-analysis.bigb, under Strongly convex function.For the identity design and , comparing the minimizing objective at with its value at and expanding the squared Euclidean norm proves the displayed inequality, with . This deterministic inequality does not assume any probability distribution for the noise. A bound on the noise inner product turns it into a statistical error estimate.
Bhattacharyya coefficient Created 2026-10-14 Updated 2026-10-24
For probability distributions on the same finite alphabet, the Bhattacharyya coefficient measures their square-root overlap:The vectors and have unit Euclidean norm, so the Cauchy-Schwarz inequality gives . Equality holds exactly when the distributions agree; holds exactly when they assign positive probability to disjoint outcomes. For and , . This overlap is not the probability that two independent draws agree, which here is .
The fidelity of commuting mixed states reduces to this coefficient. More generally, the measurement characterization of quantum fidelity minimizes it over outcome distributions of a common quantum measurement, connecting classical overlap to the unsquared quantum fidelity.
For a continuously differentiable convex function on with coordinate Lipschitz continuity constants , its block coordinate gradient is Lipschitz continuous along each corresponding coordinate subspace, with constant at most .
To prove this without assuming a Hessian matrix, put . Sum the coordinate derivative bound by Bregman divergence over the block, then repeat with interchanged and average:If is supported in the block, the dot product uses only . The Cauchy-Schwarz inequality and cancellation of its Euclidean norm give the result, including the zero case separately. Taking the full block supplies a global Lipschitz gradient constant .
Target: convex-optimization.bigb, under Coordinate descent. Bond angle Created 2026-10-13 Updated 2026-10-20
A bond angle is the angle between two chemical bonds sharing a central chemical atom. In H–O–H, the middle symbol identifies the vertex: the angle is at oxygen. Let and be the nonzero displacement vectors from that atomic nucleus to the two neighbours. The actual three-dimensional bond angle satisfiesusing the dot product and Euclidean norm. Rotating the whole molecule preserves this expression; projecting it onto a page generally does not.
There is another useful way to find a bond angle. If the two bond lengths are and the distance between the outer atomic nuclei is , the law of cosines givesFor equal bond lengths , this becomes . Thus a measured outer-atom separation contains information about a bond angle even though those outer chemical atoms are not directly joined by a chemical bond.
For a stipulated rigid, equal-bond length model using water's equilibrium bond angle, , whereas a straight H–O–H arrangement would give . These are calculated geometric ratios, not new measured distances. Gas electron diffraction illustrates how pair-distance information can constrain molecular geometry. Substituting independently averaged distances into the rigid triangle formula does not automatically recover an equilibrium bond angle, because averaging and this nonlinear calculation need not commute.
Borsuk-Ulam theorem Created 2026-09-24 Updated 2026-10-13
The Borsuk-Ulam theorem says that recording continuous real-valued measurements on an -dimensional unit sphere must give identical records somewhere on opposite sides. The measurements can vary wildly; continuity alone forces a coincidence at an antipodal pair.
Precisely, for every integer and every continuous map , there is an such thatHere and form an antipodal pair on the unit sphere; the antipodal map reverses every position coordinate. The target is the Euclidean space . Both points have the same entire output, so every one of the measurements agrees at this common pair. See Hatcher, Algebraic Topology, Corollary 2B.7, p. 176.
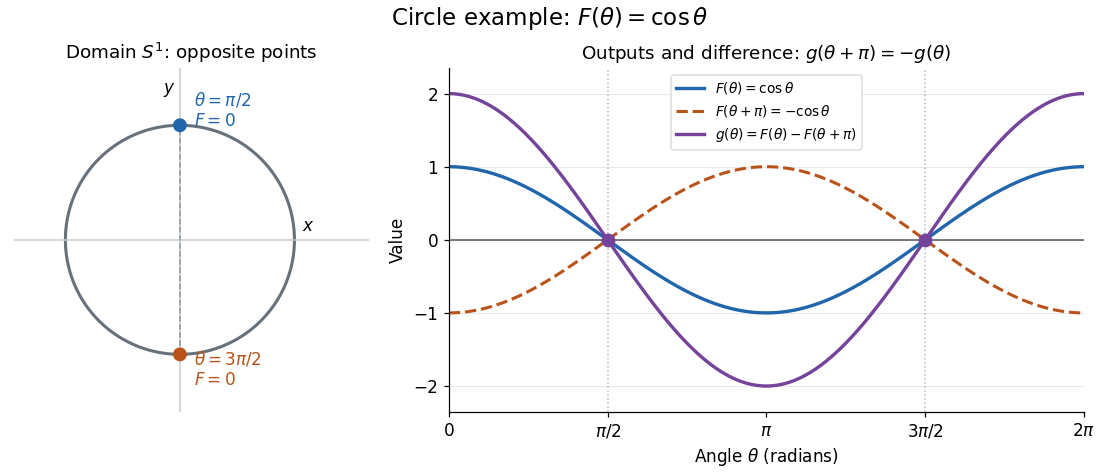
Circle example. Parametrize the unit circle by , with angles taken modulo , and record the first coordinate using the cosine function:The top and bottom points of the unit circle form the required antipodal pair. Their first coordinates agree, while their second coordinates are and .
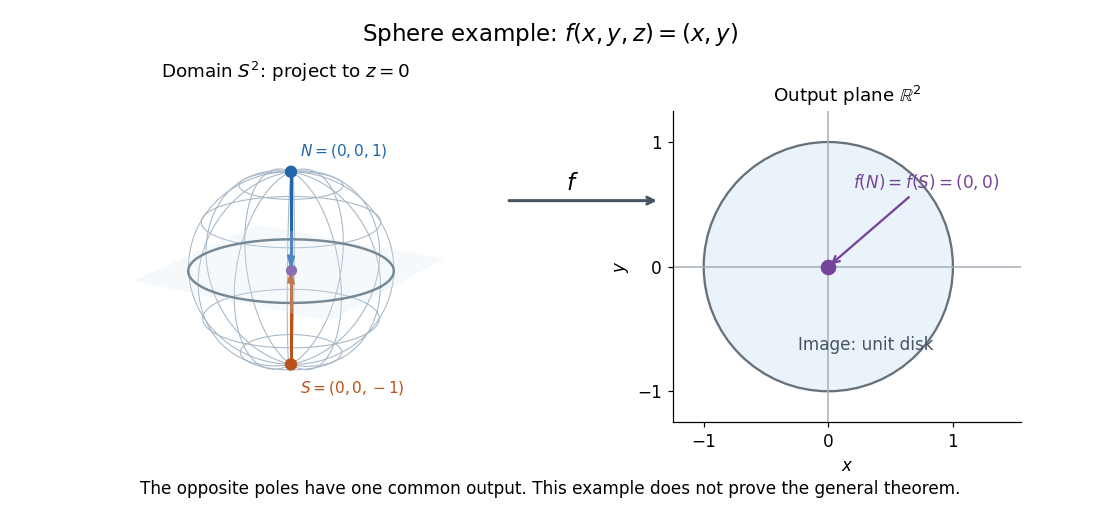
Sphere example. On the unit sphere in three-dimensional Euclidean space, take the orthogonal projection onto the equatorial plane and identify that plane with :These poles are the only coincident antipodal pair for this orthogonal projection: equality of and forces , and the unit sphere equation then gives . The Borsuk-Ulam theorem guarantees an antipodal pair for every continuous map into , even when no convenient projection formula is available.
Equal output need not mean equal position coordinates. Keeping all three coordinates gives a continuous map defined by , the restriction of the identity map of . Its outputs at an antipodal pair are always distinct, since would force , which is outside the unit sphere. Thus replacing the target by destroys this guarantee.
Why the circle case follows from the intermediate value theorem. For an arbitrary continuous map , write using the unit circle parametrization above. The continuous functionsatisfies because has period . If , the first antipodal pair already works. Otherwise and have opposite signs, and the intermediate value theorem supplies a zero between them. At that zero, the two antipodal values of agree. In the cosine function example, . This short argument handles only . See Hatcher, Algebraic Topology, discussion of Theorem 1.10, p. 32.
An ideal weather interpretation. Model the surface of Earth as a sphere. At one fixed instant, suppose temperature and pressure are globally defined continuous scalar measurements on that sphere. Apply the Borsuk-Ulam theorem to to obtain a common antipodal pair satisfyingThe two equalities hold at the same pair; applying the circle argument separately to two measurements would not ensure that. This is a conclusion about the ideal continuous model, with both measurements taken at the same instant, rather than an assertion that an exactly matching pair has been empirically measured. Matoušek gives this motivating interpretation and explicitly cautions that physical temperature need not be continuous.[ref]
Equivalent formulations. A continuous map is odd when , extending the symmetry of an odd function. The Borsuk-Ulam theorem equivalently says every such map has a zero. For a general , the difference has this symmetry; conversely, equal antipodal outputs of an odd map must be zero. Another equivalent formulation is that no odd map between spheres exists. Normalizing a nonvanishing odd map by its Euclidean norm would produce such an odd map between spheres. These formulations are useful starting points for algebraic topology; the general proof is beyond the circle argument here.[ref]
https://pi.math.cornell.edu/~hatcher/AT/ATch2.pdf#page=80. Hatcher, Algebraic Topology, Corollary 2B.7, p. 176
For further study, Jiří Matoušek's Using the Borsuk-Ulam Theorem (2003) develops the theorem and its applications to combinatorics and Euclidean geometry. An early publication is Karol Borsuk's 1933 paper Drei Sätze über die n-dimensionale euklidische Sphäre.
Bounded bilinear form Created 2026-09-24 Updated 2026-10-14
A bilinear form on a real normed vector space is bounded when one constant satisfiesThis is an upper bound on the magnitude of every pairing. It says nothing about the sign of and does not require a symmetric bilinear form. The chosen norm is part of the hypothesis. Boundedness is equivalent to joint continuity, as shown by the boundedness criterion for a bilinear form.[ref]
For example, on with the Euclidean norm, the bilinear formsboth satisfy the upper bound with , by the Cauchy-Schwarz inequality. Yet their quadratic forms are and : the former takes negative values and the latter vanishes at the nonzero vector . Thus neither is a coercive bilinear form. The latter is also a degenerate bilinear form, whereas is nondegenerate. Boundedness controls size, not positivity or loss of directions.
Every bilinear form on a real or complex finite-dimensional vector space equipped with any norm is bounded. In coordinates, write using its matrix of a bilinear form. The Cauchy-Schwarz inequality gives , with the spectral norm; finite-dimensional equivalence of norms transfers this to the chosen norm. The conclusion concerns each fixed norm and fixed bilinear form: it does not supply a single constant for an arbitrary family of matrices or changing dimensions.
On an infinite-dimensional vector space, the upper bound is an additional condition. Equip the finitely supported sequences with the norm inherited from the l2 sequence space and setEach pairing is a finite sum, so this is a well-defined bilinear form. For the basis vector , however, and ; no finite works. It is even a coercive bilinear form with , since . Consequently coercivity alone does not imply boundedness on a normed vector space. This example uses , which is not a Hilbert space; it does not define this pairing on all of the l2 sequence space.
A bounded bilinear form defines a bounded linear operator by , where is the continuous dual space. Its operator norm is the smallest admissible :This converts an upper bound for pairings into an upper bound for a linear map taking an unknown vector to a linear functional.
Brouwer fixed-point theorem Created 2026-09-24 Updated 2026-10-14
The Brouwer fixed-point theorem says that every continuous map has a fixed point when is a nonempty compact set and a convex set in a finite-dimensional vector space over the real numbers. Equivalently, take for a finite , with the usual Euclidean space structure: there is some such that . The conclusion guarantees at least one fixed point, without asserting uniqueness or telling us how quickly to find one. [ref]
https://courses.csail.mit.edu/6.5440/fall23/lectures/L23_images.pdf. MIT lecture slides on Brouwer's theorem
The standard pictures are a closed ball, including a closed unit ball, and a simplex. A filled disk qualifies; its bounding circle alone does not. A probability simplex also qualifies even though its dimension is smaller than that of its ambient Euclidean space. The hypotheses have concrete meanings: being a convex set keeps every line segment between allowed points inside , and compactness prevents escape or loss of a limiting point. In Euclidean space, the Heine-Borel theorem identifies compact sets with closed sets that are bounded sets. Crucially, every output must belong to the same as the input.
For a fully computable example, let be the filled unit disk. Apply a counterclockwise quarter-turn rotation, shrink by , and add a translation:This affine map is a continuous map. Because the rotation preserves the Euclidean norm, the triangle inequality gives, for every ,Thus the whole image lies strictly inside . More precisely, it is a disk of radius centred at . This containment check is what makes the Brouwer fixed-point theorem applicable; a formula being a continuous map by itself would not suffice.
The fixed point can now be found by a system of linear equations:Indeed, substitution gives . Its Euclidean norm is , safely inside . The figure shows arrows from sample inputs to their outputs; an arrow disappears at the fixed point because the displacement vanishes there.
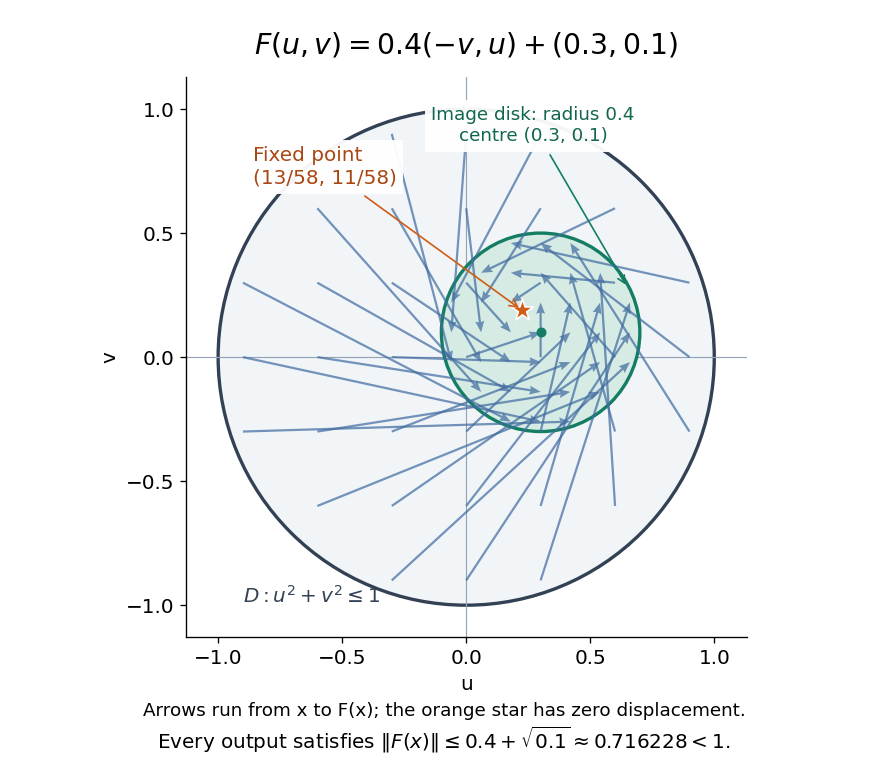
Repeated iterations of a map happen to succeed for this example. Starting at and setting gives , , and . Subtracting the fixed point equation yields , so the Euclidean distance to shrinks by exactly each step. This extra fact follows from the contraction mapping property and the Banach fixed-point theorem. It is additional information beyond the Brouwer fixed-point theorem.
The distinction becomes visible with two simpler continuous maps of the same disk. The pure rotation has exactly one fixed point, , since and force both to vanish. Yet iterations of a map starting at here cycle through , , and forever. Their Euclidean distance from stays one, so there is no convergence in a metric space. The reflection has an entire line segment of fixed points, namely . Starting off that line segment produces an alternating pair. Existence, uniqueness, and convergence of iterations of a map are separate questions.
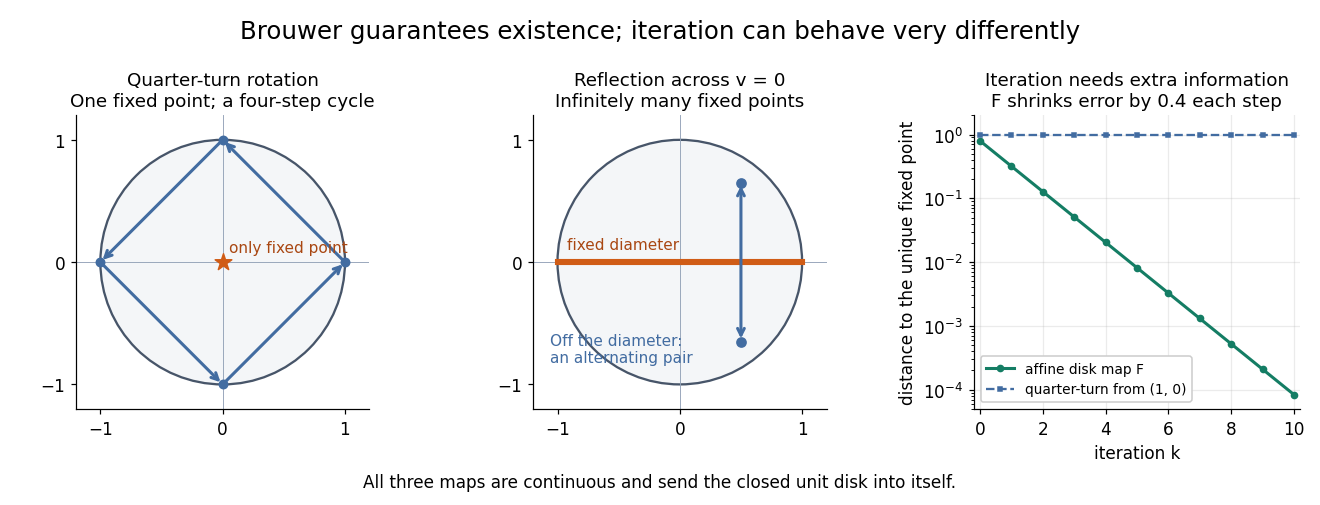


Removing hypotheses changes the answer. Restrict the same quarter-turn rotation to the circle . It remains a continuous map into that compact set, but its only possible fixed point, , has been removed. The circle is not a convex set. Conversely, on the unbounded convex set , the translation has no fixed point; on the open interval , also has none. Neither domain is a compact set. The finite-dimensional closed ball statement should likewise not be extended to arbitrary infinite-dimensional vector spaces, where a closed ball need not be a compact set.
The one-dimensional version explains the connection to the intermediate value theorem. For a continuous map , put . Then and , so the intermediate value theorem gives for some . In higher dimensions, the Brouwer fixed-point theorem supplies a corresponding existence principle when this scalar sign argument is unavailable. Its practical value is ensuring that a proposed equation has a solution once a suitable domain is found; it supplies no general promise of a fast algorithm.
A useful application is positive matrix eigenvector from simplex normalization: rescale the output of a strictly positive matrix to make its entries sum to one. For example, takeOn this probability simplex, has entry sum , so the normalized continuous map is . Both entries are positive and sum to one, keeping the image inside the probability simplex. Its fixed point equation is , hence . Consequently satisfies : a strictly positive eigenvector with eigenvalue . In larger dimensions, the Brouwer fixed-point theorem guarantees the corresponding positive eigenvector without requiring us to solve a system of linear equations in advance. The fixed point expresses preservation of relative weights, rather than preservation of their unnormalized size.
Proofs can be approached through the no-retraction theorem or Sperner's lemma. In the latter approach, increasingly fine triangulations locate approximate fixed points; compactness supplies a convergent subsequence, and continuous maps turn its limit into an exact fixed point. [ref]
https://www.mit.edu/~6.7980/brouwer.html. Daskalakis and Farina, Brouwer and Sperner
A primary historical reference is L. E. J. Brouwer's 1911 paper Über Abbildung von Mannigfaltigkeiten, whose digitized original is hosted by Zenodo under DOI 10.1007/BF01456812. This gives a direct route to the early literature behind the Brouwer fixed-point theorem. [ref]
https://zenodo.org/records/1428286. Brouwer, Über Abbildung von Mannigfaltigkeiten, 1911
With homogeneous Dirichlet boundary conditions, centered differences turn one-dimensional diffusion into a symmetric negative-definite matrix and constant advection into a skew-symmetric matrix. Their sum dissipates the discrete Euclidean norm, giving mesh-uniform energy stability for every fixed advection coefficient.
Centroid sum-of-squares identity 2026-10-20
For a nonempty finite collection of Euclidean vectors, its sample mean uniquely minimizes the sum of squared Euclidean distances to a proposed centroid . Expand each squared Euclidean norm around and use to cancel the cross term. The displayed identity leaves a nonnegative term , equal to zero exactly at .
Circulant matrix Created 2026-09-24 Updated 2026-10-14
A circulant matrix applies the same rule at every position of a finite ring: moving both the input and output indices one step leaves its entries unchanged. Its first column determines the whole matrix. For a length- vector , index rows and columns by and defineThe indices use modular arithmetic. Thus each column is the previous column shifted down one place, with the last entry wrapping around to the top. Multiplication is exactly circular convolution:This makes a circulant matrix a natural model for a periodic finite difference rule or a filter acting on a periodic record. Strang's MIT lecture develops this connection between circulant matrices, circular convolution and the discrete Fourier transform.[ref]
For example, the first column givesHere the indices wrap around modulo four. Each output compares a value with its two neighbors; this is the Graph Laplacian of a four-vertex cycle graph. A constant input gives zero, while an alternating input gives a large response. The Fourier diagonalization of a circulant matrix makes this distinction exact: its four eigenvalues are .
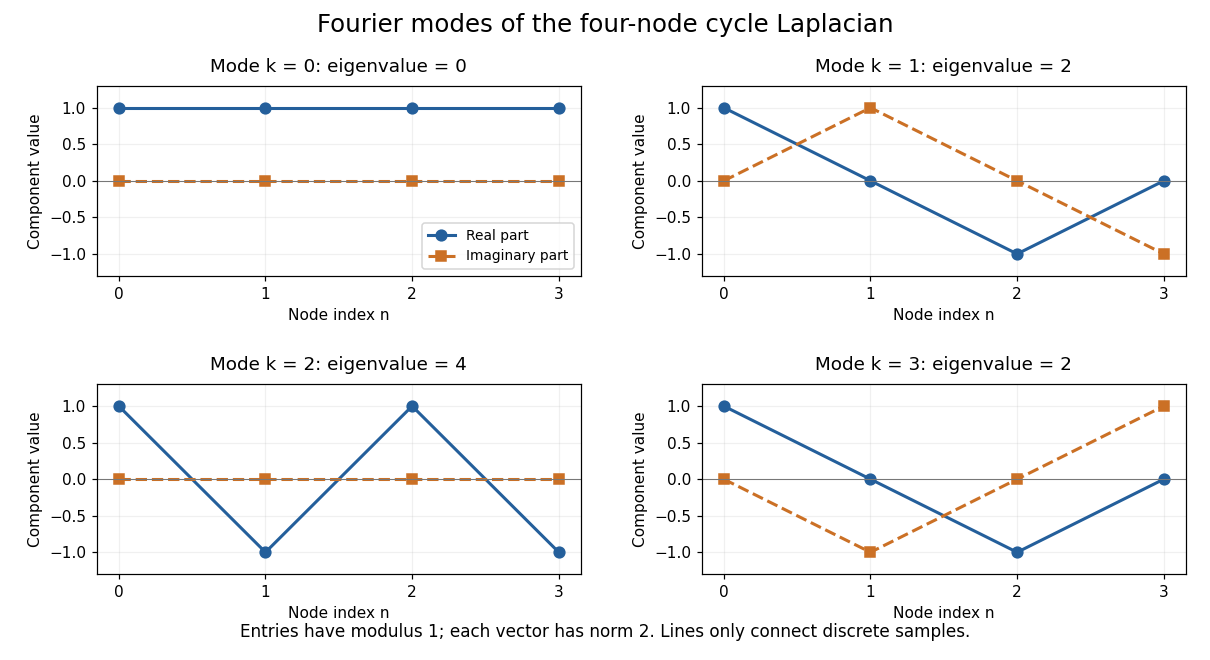
Fourier eigenvectors of the four-point cycle Laplacian
. Details. 
The plotted discrete Fourier modes are complex vectors, shown through their real and imaginary parts. Each entry has modulus one; the Euclidean norm of each length-four vector is two. In particular, modes and have the same real part but opposite imaginary parts, so they are distinct eigenvectors with the same eigenvalue.
The useful surprise is that every length- circulant matrix shares the same basis of eigenvectors, whatever its first column. One change of basis therefore simplifies an entire family of linear maps, instead of requiring a separate eigenvalue computation for each one. Bamieh's tutorial develops the discrete Fourier transform from precisely this simultaneous diagonalization problem.[ref]
https://arxiv.org/abs/1805.05533. Bamieh, Discovering Transforms: A Tutorial on Circulant Matrices, Circular Convolution, and the Discrete Fourier Transform (2018; revised 2022)
Coercive bilinear form Created 2026-09-24 Updated 2026-10-14
A real bilinear form on a normed vector space is coercive when there is one constant such thatThe lower bound uniformly controls every direction in the chosen norm. Unlike the upper bound defining a bounded bilinear form, it forces positive diagonal values at every nonzero vector. No symmetry is assumed. For complex Hilbert spaces, the usual analogue uses a sesquilinear form and ; it is not the same assertion for a complex bilinear form.
A concrete bounded and coercive example on , with the Euclidean norm, isIts quadratic form isThe best lower constant is , attained at . Nevertheless, and , so coercivity does not imply a symmetric bilinear form. The symmetric part of a matrix determines , while the skew-symmetric matrix part changes mixed pairings without changing . This is the symmetric and alternating parts of a bilinear form decomposition.[ref]
For the upper constant, direct multiplication gives . Its eigenvalues are , so the optimal upper constant, the spectral norm, is . The two constants answer different questions: how large a mixed pairing can be, and how small a self-pairing can be relative to squared norm.
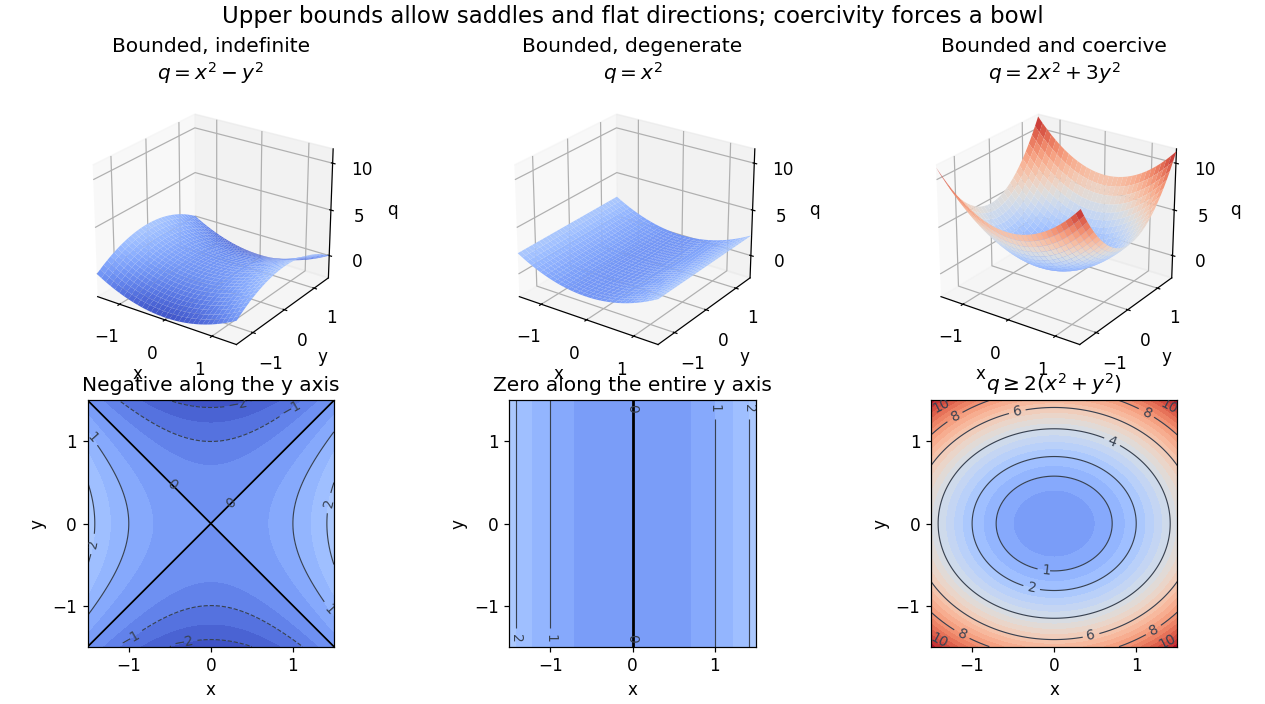
Bounded saddle and flat-direction quadratic forms contrasted with a uniformly coercive bowl
. Details. 
The plotted quadratic forms show the mechanism: descends in one direction, leaves one direction uncontrolled, and controls both. These are self-pairings; their level sets cannot reveal the skew-symmetric matrix part. Calling a quadratic energy here refers to this diagnostic quantity, not to a claim that a nonsymmetric equation comes from minimizing an energy functional.
On a real finite-dimensional vector space with any norm, strict positivity for every nonzero does imply coercivity. Indeed the quadratic form is continuous, and its positive minimum on the compact unit sphere supplies . If is also a symmetric bilinear form, this is positive definiteness. For general , it is the symmetric and alternating parts of a bilinear form decomposition that isolates the positive part. Switching between equivalent norms preserves coercivity, but usually changes its constant.
The infinite-dimensional vector space distinction is explicit on the real l2 sequence space:The Cauchy-Schwarz inequality gives boundedness with , and for every nonzero vector. But with , so no positive works. On the span of , the best lower constant is : each finite restriction is coercive, but the control disappears as grows. Strict positivity is therefore weaker than a uniform lower bound.
The practical payoff is a stability estimate for a weak formulation. Assume is a real Hilbert space, is both a bounded bilinear form and a coercive bilinear form, and the load is a bounded linear functional. The Lax-Milgram theorem gives a unique satisfying for all , including nonsymmetric .[ref]
Introduction to Finite Element Methods by Christian Clason. §2.2, Theorem 2.7, pp. 20–21, equation (2.9): hypotheses, unique solvability and load bound
The dual norm measures load size. Testing with gives the short energy estimateFor the bound holds directly; otherwise divide by . Subtracting the equations for two loads and using the same argument gives . Thus a positive lower constant limits the response to load errors. The upper bound and completeness of the Hilbert space enter the existence theorem; the estimate itself uses the lower bound and the load's dual norm.For the displayed matrix , take . Then for every means , not , with this ordering of the bilinear form. Since ,For , the exact response is and . For , it is , with norm . The actual maximal amplification is the operator norm : the coercivity estimate is valid but need not be sharp for a nonsymmetric bilinear form.
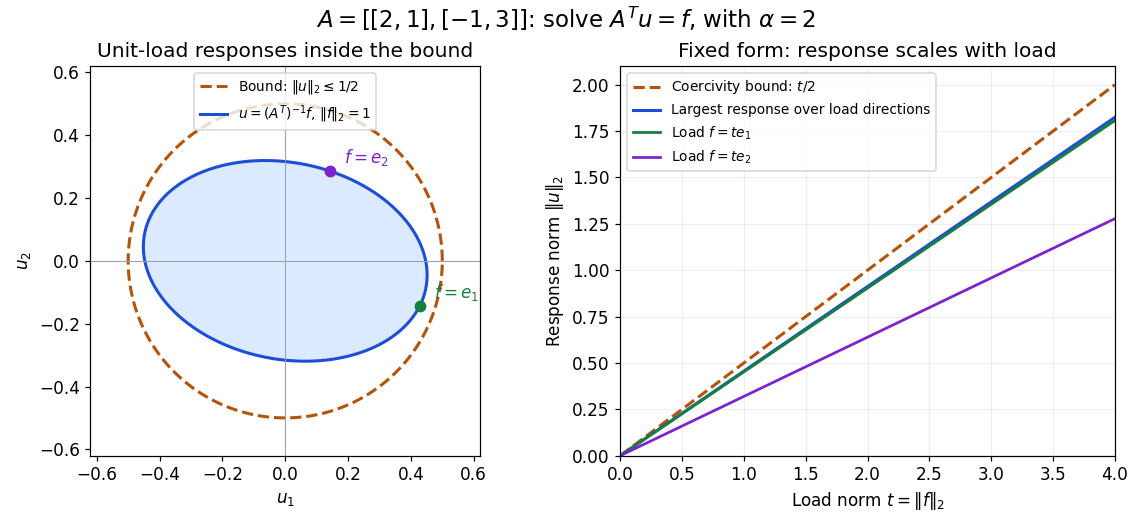
Solutions for unit loads lie inside the coercivity bound, and response grows at most linearly with load norm
. Details. 
Coherence of a normalized matrix 2026-10-07
For a matrix with at least two columns of unit Euclidean norm, its mutual coherence is the largest magnitude of an inner product between distinct columns. It measures the strongest pairwise ambiguity of linear measurements. The Cauchy-Schwarz inequality gives . The order-two restricted isometry constant equals the mutual coherence, because every two-column Gram matrix has eigenvalues .
Complex modulus 2026-10-06
The complex modulus of is . It is the Euclidean norm of in the complex plane, and satisfies and the triangle inequality.
Conic dual problem Created 2026-10-06 Updated 2026-10-14
A conic dual problem searches for a lower bound on a conic optimization problem. A feasible point exhibits an attainable cost; a feasible dual variable explains why every allowed decision costs at least a specified amount. If the two costs agree, the pair certifies a global minimum without relying on how the points were found.
Fix a real matrix , vectors , , and a closed convex cone . With unrestricted , use the conventionwhere the dual cone is . The conic dual problem uses because it must turn every allowed slack variable into a nonnegative dot product. Taking gives componentwise linear inequalities; taking a second-order cone gives a Euclidean norm constraint. A self-dual cone has , but this equality does not guarantee a feasible point or strong duality.
The Lagrangian supplies a short derivation. For ,Its infimum over unrestricted is when , and otherwise. Maximizing the resulting Lagrange dual function gives the stated conic dual problem. The minus sign matches the convention .
Continuation predictor-corrector step 2026-10-14
For the cubic polynomial, an oriented, normalized tangent vector isIts Euclidean norm is one and . The sign here follows increasing ; for a general solution branch, choose the sign of each new tangent vector so its dot product with the previous one is positive. First predict , then apply Newton method starting at toThe second equation keeps the correction on the transverse line in this two-dimensional example; in higher dimensions it is a hyperplane. Solving the linear system and updating corrects both coordinates together.
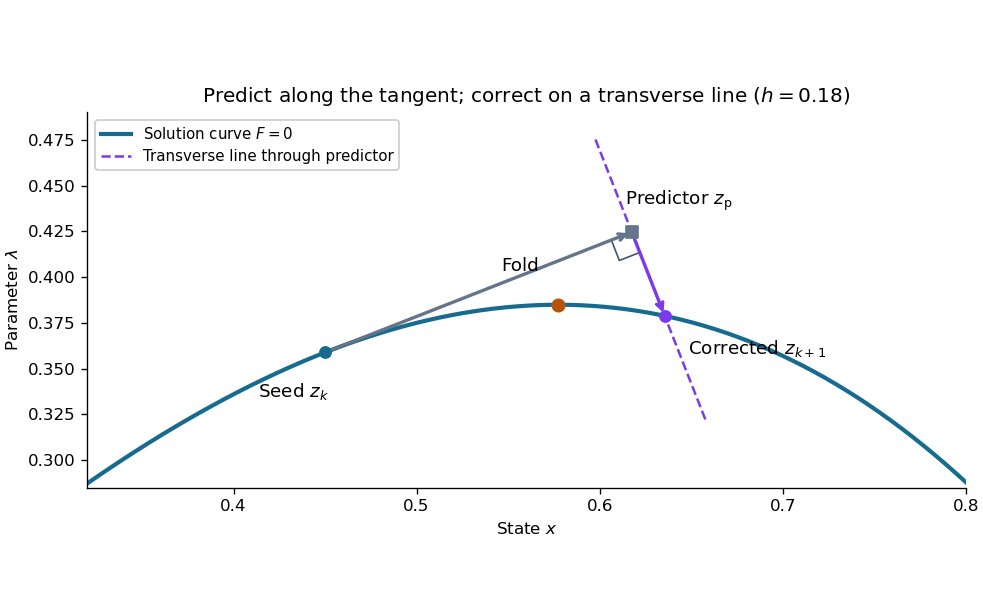

This step gives and . Check both equations: the solution must satisfy and . Checking only the first could accept any point on the solution branch. The new exceeds , so the step crosses the continuation fold, even though the predictor's exceeds .
At the seed, set . The determinant of the correction Jacobian matrix with the exact unit vector above isAt either continuation fold, , and : the correction remains invertible. More generally, if has full rank and a one-dimensional kernel spanned by , adding gives an invertible matrix, since a vector annihilated by both rows must be zero. This is a local argument; the old transverse hyperplane need not work arbitrarily far along the curve. Reduce and retry when correction fails, and check the equations and orientation after successful steps. Scaling state and parameter coordinates also matters, because it changes the Euclidean norm used to normalize the tangent vector.
// Target: analysis.bigb
Continuous dual space Created 2026-09-24 Updated 2026-10-14
The continuous dual space of a topological vector space is the vector space of its continuous linear functionals. Unlike the algebraic dual, it requires that a small change in an input produce a small change in its scalar measurement. For a normed vector space, this is equivalent to a finite boundfor all vectors and some constant . The least such constant is the operator norm of .
This is the continuity-restricted subspace of the algebraic dual space; in infinite dimension the two can differ.
For the linear functional on with its Euclidean norm, the Cauchy-Schwarz inequality givesEquality holds on the unit vector , so its operator norm is exactly . The same estimate controls measurement error: . The linear functional diagram shows which changes are entirely invisible to this measurement; its kernel of a linear map consists of the changes with zero response. All linear functionals on a finite-dimensional real or complex normed vector space are continuous, but discontinuous functional detected by vanishing sequence tails shows why the restriction matters in infinite dimension.
A stationary iterative method for a linear system converges to its specified fixed point for every initial vector if and only if its iteration matrix satisfies , where the spectral radius is the largest modulus of an eigenvalue.[ref]
Notes for Ma221 Lecture 21, Nov 10 2009. Math 221, Matrix Computations, Fall 2009; Basic iterative methods: theorem following the spectral-radius lemmas, before the Jacobi update
For a diagonalizable matrix, write . Then , so each eigenvector coefficient tends to zero exactly when its eigenvalue has modulus less than one. For a general matrix, the Jordan normal form gives the same result: a Jordan block with a nilpotent matrix of size satisfiesIf , every coefficient tends to zero because exponential decay beats any fixed polynomial in ; if , the block vanishes once . Conversely, an eigenvector with provides an initial error that cannot tend to zero. For a real matrix with complex eigenvalues, the same obstruction appears in the real invariant subspace spanned by the real and imaginary parts of an eigenvector.
The words "every initial vector" matter. For example, fails the criterion, but still tends to zero. Here a generic initial error has a nonzero first coordinate and diverges; the exceptional errors lie on the second coordinate axis. With , generic errors oscillate rather than diverge in norm, while the same exceptional axis still converges. Both are valid matrix splittings with and . In general the convergent errors form the direct sum of the generalized eigenspaces for ; if , this is a proper linear subspace.
A small spectral radius describes eventual convergence, but does not imply that the Euclidean norm of the error decreases on every step for a non-normal matrix. An operator norm bound does give the stepwise estimate . For a real symmetric matrix, the matrix 2-norm equals its spectral radius, making this particularly direct.