Control theory studies how to choose control inputs for a dynamical system so that its plant output follows a reference signal, despite control disturbances and imperfect knowledge of the controlled plant. A controller turns the available information into a control signal. The design must consider both the resulting response and stability theory: a rule that corrects a small mismatch can still produce growing deviations if the interconnection is badly chosen. [ref]
https://www.fbswiki.org/wiki/index.php/Introduction. Åström and Murray, Feedback Systems, Chapter 1: Introduction
The central distinction is informational. Open-loop control executes planned commands; feedback control uses the measured output of the actual controlled plant to update those commands. A reference signal can describe a destination, while control disturbances describe influences that the controller did not command. A model can predict where the controlled plant should be; measurement tells the controller what actually happened. The authors provide a free full-book PDF through [ref]
https://www.fbswiki.org/wiki/index.php/Feedback_Systems:_An_Introduction_for_Scientists_and_Engineers. Feedback Systems, second edition: authors' book and download page
.For a concrete comparison, all examples below use the same ideal scalar controlled plant:Here is an illustrative position, the control input, a control disturbance, and the measured output. Both and are dimensionless quantities; the numbers are chosen to expose the mechanism, with no empirical interpretation. The ordinary differential equation says that the present control input and control disturbance accumulate into . The measured output equals the entire state only in this ideal example; a general plant output need not reveal the entire state.
The controlled plant is the part of a control theory model that receives the control input and produces the plant output, including the mechanism that applies the command. The controller is specified separately. In the illustrative ordinary differential equation , the controlled plant accumulates the control input and control disturbance; it does not itself choose .
A plant input is a signal supplied to the controlled plant. The chosen plant input is its control input; other influences can enter as control disturbances. This use concerns a dynamical system, rather than the input of a computation.
A plant output is a quantity exposed by the controlled plant, often modeled as . In the illustrative model it is . An output of a computation has a different meaning.
The measured output is the information about the plant output available to the controller. It may differ from the actual plant output because of measurement noise or feedback delay. In the ideal examples , so the controller observes the actual current state exactly.
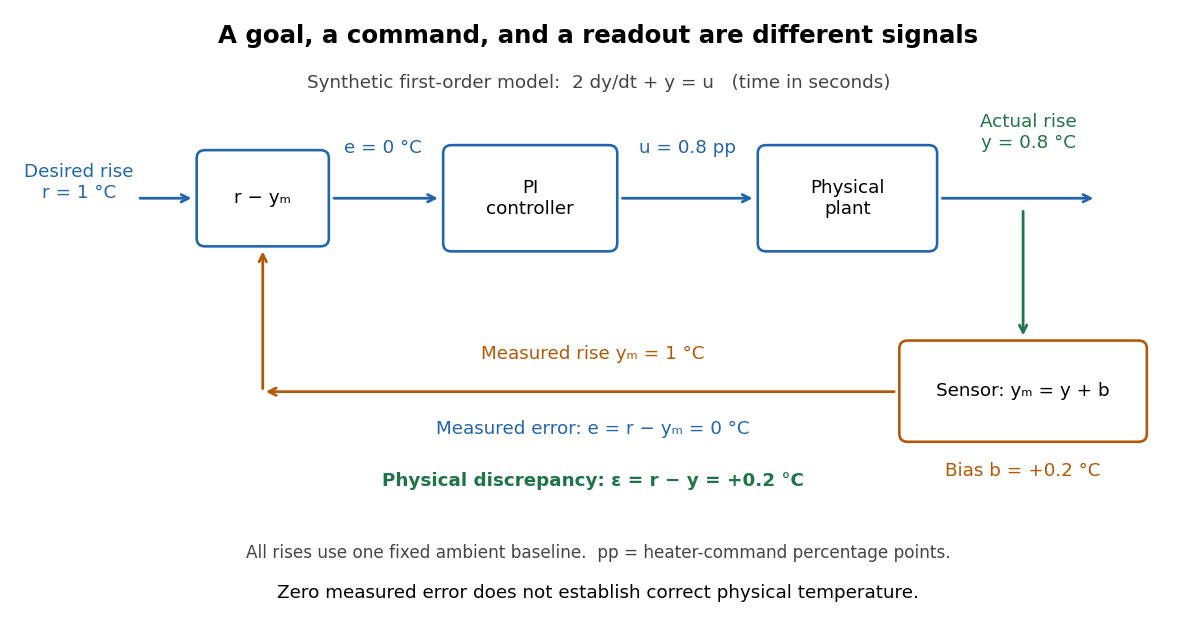
A sensor bias is a systematic offset between the measured output and the physical plant output, modeled here as with constant . Unlike zero-mean measurement noise, a sensor bias persists when repeated readouts are averaged. A sensor bias affects the physical meaning of a zero tracking error; for a temperature readout, independent thermometer calibration can detect it.
A control disturbance is an influence on the controlled plant that is not the chosen control input. In , a constant increases by per unit whenever .
A controller is the rule or mechanism that chooses a control signal. An open-loop control can depend on a precomputed schedule; a feedback control also uses a measured output and can have its own memory, as in integral action.
A feedback gain sets the strength of a controller's response to its observations. For proportional control, means that a tracking error produces a control input when .
Actuator saturation means the applied control input reaches a device limit even if the controller requests a larger or smaller command. In the heater interpretation, the applied command is bounded between and . If integral action continues accumulating a persistent tracking error beyond that limit, its stored integral can grow without producing the requested physical correction, delaying recovery when the goal changes. The unconstrained steady-state tracking error formulas require that the necessary command can actually be applied. [ref]
https://www.fbswiki.org/wiki/index.php/PID_Control. Åström and Murray, PID Control: saturation and integral windup
An ideal PID controller combines proportional control, integral action, and a term proportional to the derivative of the tracking error. With , it gives proportional-integral control. The integral stores past error, while the derivative responds to its current rate of change. Practical implementations must account for measurement noise, which an ideal differentiator can amplify. [ref]
https://www.fbswiki.org/wiki/index.php/PID_Control. Åström and Murray, PID Control
.Controllability asks whether the available control inputs can move a dynamical system between every pair of states in its declared state space. Fixing a duration gives the precise condition for every , where is the state space and its reachable set. With freely chosen duration, every pair must instead be connectable in some permitted finite time, which may depend on the pair. Always specify admissible control inputs, deadlines and any constraints along the path. [ref]
https://fbswiki.org/wiki/index.php/State_Feedback. Åström and Murray, Feedback Systems: State Feedback, reachability definitions
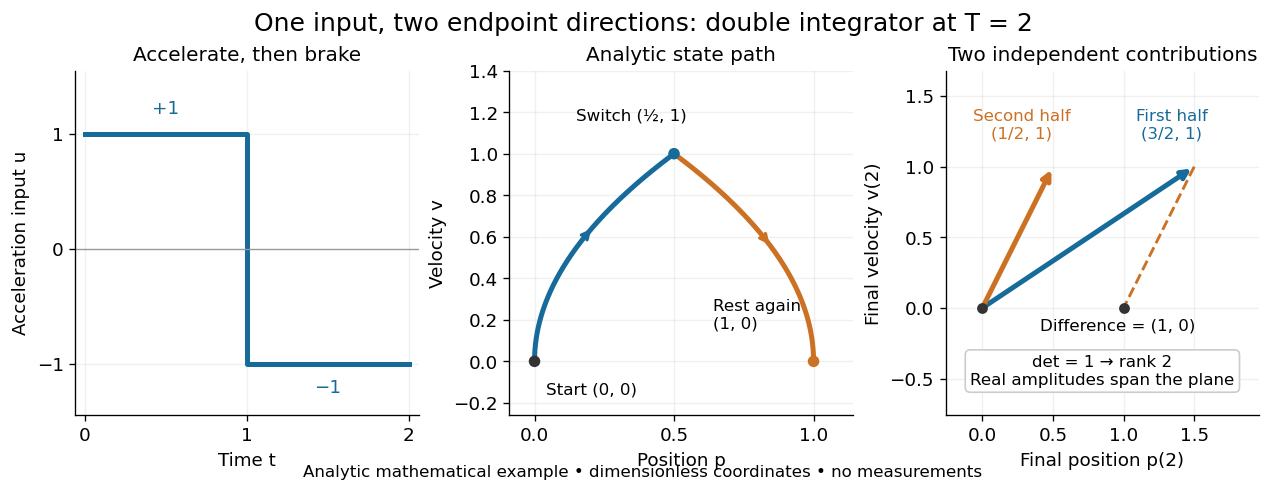
The surprising part is that one control input can control several state variables by acting at different times. For the double integrator, acceleration changes velocity directly, while the accumulated velocity changes position. Starting from rest, accelerate during the first half of the journey and brake during the second: the final velocity can vanish although the final position has changed. The figure is an analytic mathematical example in dimensionless quantities, with no experimental measurements.
Controllability is useful before trying to design a controller: a requested endpoint outside the reachable set cannot be attained by clever choice of feedback control. The Kalman rank criterion makes this an exact linear algebra calculation for the stated linear time-invariant system model. It concerns whole states, so attaining one plant output is not enough to establish controllability. In quantum control, the declared state space may be an orbit constrained by conservation laws; see quantum controllability and unitary orbit of a density operator.
For the linear time-invariant system , with and , the controllability matrix has rows and columns. The columns of are directions influenced directly by the control inputs; account for how the dynamics carry their influence into further directions. The column space of the controllability matrix is the zero-state reachable set for any when inputs are unrestricted. [ref]
https://underactuated.csail.mit.edu/acrobot.html#controllability. Russ Tedrake, Underactuated Robotics: Controllability of linear systems
For a finite-dimensional continuous-time linear time-invariant system on , with constant matrices over the real numbers, no state constraints, and every piecewise continuous function allowed as a control input without an amplitude bound, controllability in any fixed is equivalent to the controllability matrix having rank of a matrix . The same equivalence holds with all square-integrable functions as inputs. A stronger useful statement iswhere is a matrix exponential and is the column space. Thus a rank of a matrix leaves only an -dimensional affine subspace reachable at that time. [ref]
The Kalman rank criterion allows arbitrarily large commands as shrinks. It does not assert controllability with bounded control inputs, nor test a general nonlinear dynamical system just by counting its inputs. For the double integrator, and give two independent directions, despite there being only one control input.
For and the constant matrices over the real numbers in the Kalman rank criterion, the finite-time Controllability Gramian accumulates the influence of all command times. Its column space equals that of the controllability matrix, and is a symmetric positive-definite matrix exactly when the controllability matrix has rank of a matrix . If so, put . Among square-integrable functions steering to at , the commandminimizes , with value . Here in a matrix superscript denotes transpose. This cost is a squared input norm, not necessarily physical energy, and the optimizing command need not satisfy an amplitude bound. [ref]
https://ee263.stanford.edu/archive/contr.pdf. Stephen Boyd, EE263: Controllability and state transfer, slides 18–29 to 18–30
For the double integrator, , so direct integration givesFor a rest-to-rest distance , and the minimum squared input norm is . Compare the two constant commands in the double integrator example, whose cost is : both attain the target, but the smooth command costs less. At , , however, peaks at , so it violates while the two constant commands remain admissible. Controllability, optimal control, and constrained reachability in control theory answer different questions.
Quantum controllability concerns the transformations reachable under specified quantum control inputs. Unitary operator controllability concerns entire propagators; density operator controllability concerns conjugation on every spectral orbit; pure-state controllability concerns normalized state vectors or their physical rays. These notions need not coincide.
A finite-dimensional closed quantum control system with fixed drift and control Hermitian matrices, real control inputs, and dynamics linear in the state at fixed controls and affine in the controls at fixed state. Its Dynamical Lie algebra is generated over the reals by . Reachability depends on the admissible controls, allowed duration and phase convention.
The dynamical Lie algebra of a finite-dimensional Hamiltonian control system is the real span of its skew-Hermitian drift and control generators and all their nested commutators. The sign choice or gives the same algebra. Its connected group determines reachable propagators under the usual freely timed, real-control assumptions. An operator commuting with every generator also commutes with this algebra, imposing invariant sectors.
Let be diagonal and , with every and the adjacent absolute energy gaps distinct and nonzero. The squared drift adjoint action has distinct eigenvalues on these coupling components, so Lagrange interpolation isolates every adjacent symmetric coupling. One more commutator gives its antisymmetric partner. Their mutual brackets produce adjacent traceless diagonals, while brackets along the connected chain give all longer-range matrix units. Thus the special unitary Lie algebra is generated. Any nonzero-trace generator also supplies the central direction, giving all of . This is a sufficient condition in the finite-dimensional freely timed real-control model; connectivity alone does not remove frequency degeneracies.
A drift Quantum Hamiltonian is strongly regular when its energy levels are nondegenerate and distinct unordered transitions have distinct absolute nonzero Bohr frequencies. Sometimes regularity is required only on the graph of allowed control transitions. This lets polynomials in the squared drift adjoint action separate different coupling quadratures and permits frequency-selective resonant quantum control. This notion is unrelated to a strongly regular graph.
For , let be a Lie subalgebra of with codimension one. With inner product on skew-Hermitian matrices, its orthogonal complement is a line . Invariance of the inner product shows that lies in that line for every ; skew-adjointness of the adjoint action makes orthogonal to , hence zero. A nonscalar skew-Hermitian has a centralizer of dimension at most , by its orthogonal eigenspace decomposition, and cannot centralize all of . Thus is scalar and . This gives density operator controllability and all determinant-one gates, but not the central phase direction needed for unitary operator controllability.
For a nonsingular skew-symmetric unitary , if each skew-Hermitian control generator obeys , then so do their real linear combinations and commutators. Differentiating shows that it stays equal to . The reachable group is therefore contained in a unitary conjugate of the compact symplectic group. This is preservation of an alternating bilinear form, not commutation with .
For with real orthogonal skew-symmetric , the dual transforms as . Hence is constant on the reachable unitary orbit of a density operator. Different values can obstruct density operator controllability even when the ordinary spectra agree. For a four-dimensional pairing indices and , the two diagonal arrangements and have invariants and .
Let and , with nonzero , distinct positive . The squared adjoint action of has different eigenvalues on the two adjacent skew-Hermitian couplings. Linear combinations of and its double commutator with isolate both couplings. Further commutators give their real antisymmetric partners, two traceless diagonal generators, and both – generators, hence the special unitary Lie algebra . The drift has nonzero trace; subtracting its traceless part supplies , giving the Lie algebra of the unitary group and unitary operator controllability under the usual freely timed real-control assumptions.
Let be a symmetric unitary matrix and every skew-Hermitian control generator obey . The condition is closed under real linear combinations and commutators, and evolution preserves . In a unitary basis where becomes the identity, the generators are real antisymmetric, so the Dynamical Lie algebra is contained in . The state quantity is invariant under the reachable evolution and insensitive to global phase, obstructing unrestricted pure-state controllability. This is a bilinear-form symmetry; it does not assert that commutes with the Hamiltonians.
For , suppose a skew-Hermitian Lie algebra becomes all of after adding the scalar identity direction. Scalar matrices commute, so is contained in . If contains any nonzero-trace generator, subtracting its traceless part supplies , and was already all of . This permits using identity-augmented commutator calculations without assuming an additional physical identity control.
For freely chosen control duration in a finite-dimensional closed system, pure-state controllability means the reachable group acts transitively on normalized states or their rays. Up to unitary conjugation, the possible Dynamical Lie algebras are , , and for even the standard compact symplectic Lie algebra , with or without . For , the symplectic possibilities are pure-state controllable but generally lack density operator controllability.
A closed system has density operator controllability when every pair of density operators with the same spectrum can be connected by its controls. Under the standard finite-dimensional Hamiltonian assumptions, this holds exactly for Dynamical Lie algebra or . This definition ranges over every spectral orbit; a particular degenerate spectrum can be controllable under a smaller group.
A finite-dimensional closed-system control model is unitarily operator controllable when its reachable propagators include every unitary operator. For the usual real Hamiltonian controls and freely chosen duration, this requires the Dynamical Lie algebra to be . If global phase is ignored, also suffices; exact access to all of still requires the central phase direction.
Reachability in control theory asks about a particular initial state and target : does some admissible control input make at the declared time , or at some allowed duration? Controllability requires this for every pair in the declared state space. This is a property of state evolution, distinct from graph reachability.
For a linear time-invariant system, solving the ordinary differential equation by a matrix exponential givesThe first term is the unforced endpoint. Reachability in control theory asks whether the control input can supply exactly the displacement . The timing matters because the same command is carried by different amounts of subsequent dynamics. [ref]
https://ee263.stanford.edu/archive/contr.pdf. Stephen Boyd, EE263: Controllability and state transfer, slide 18–3
Here is a contrasting mathematical example with one shared control input:The controllability matrix has rank of a matrix one. Since , the difference is invariant under every allowed control input. From the reachable set is the diagonal when input amplitudes are unrestricted: is reachable at using , while is impossible at every duration. Having a control input appear in both state equations did not give independent control of both states. This reachable set is pictured alongside the bounded double integrator below.
The reachable set collects all endpoints attainable from at exactly by admissible control inputs. If arrival any time up to is allowed, use , with . These definitions differ: a general dynamical system may drift away after early arrival, so waiting need not preserve the target. The reachable set is always relative to a declared input class and any constraints on the entire path.
For the double integrator starting from , now require measurable functions as control inputs with almost everywhere. Write for its endpoint at . Two integrals determine the endpoint:Our mathematical example has the exact reachable setTo see the upper boundary, fix : put first and last, switching at . This maximizes the weighted integral for position because early commands have the largest weight ; the required net velocity fixes . Formally, has the same sign as this maximizing command, so changing to any other admissible command with the same integral cannot increase . Reversing the order gives the lower boundary. Pointwise convex combinations of these two commands preserve and attain every intermediate , so the formula describes the whole region, not merely a bound. The extreme commands are bang-bang control.
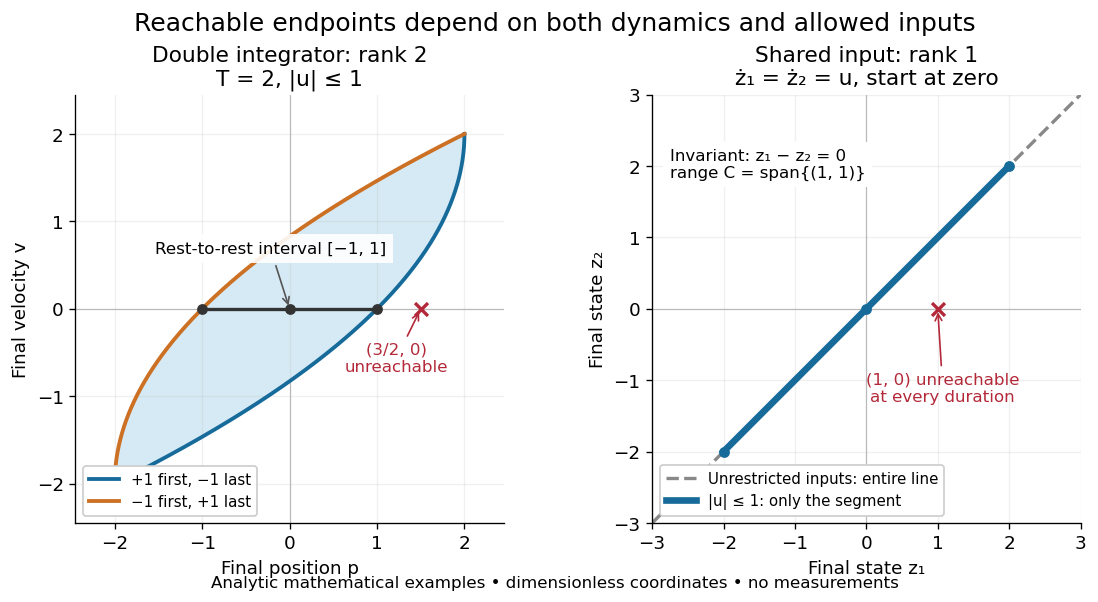
In particular, the bounded double integrator can move from rest to position and rest again exactly when . Its minimum duration is therefore in these normalized units. With freely chosen time every rest-to-rest distance is attainable; with a fixed deadline many are excluded. Changing the amplitude bound to with scales this condition to . This shows why specifying the controls matters even when the Kalman rank criterion gives full rank of a matrix.
In closed quantum control, a density operator reachable set lies inside its unitary orbit of a density operator, since coherent evolution preserves the spectrum. That orbit need not be fully reachable under the available control inputs.
The double integrator is the linear time-invariant system in which one control input is integrated into velocity, and velocity into position. It is a mathematical idealization of one-dimensional motion under commanded acceleration; for a constant mass and net force , Newton's second law gives . The worked examples here use normalized dimensionless quantities and assume no control disturbances, rather than describing a laboratory record. [ref]
https://www-personal.umich.edu/~dsbaero/others/25-DoubleIntegrator.pdf. Venkatesh G. Rao and Dennis S. Bernstein, Naive Control of the Double Integrator, pages 87–88
Writing givesThe Kalman rank criterion therefore gives controllability in every for unrestricted real control inputs. More concretely, choose constants on the first and second halves. Starting at , direct integration givesThe endpoint map has determinant , so these two amplitudes can supply any desired endpoint displacement. For a rest-to-rest move of distance , take , . At and these are the two commands in the first figure. No impulse is needed; shorter deadlines require larger finite commands.
An open-loop control is prescribed as a function of time, possibly after calculation from an initial state and a dynamical model. It is executed without using observations of the actual current state to change the input. A simulated feedback control law can generate an open-loop waveform, but the resulting laboratory control does not automatically correct errors in the actual state or model.
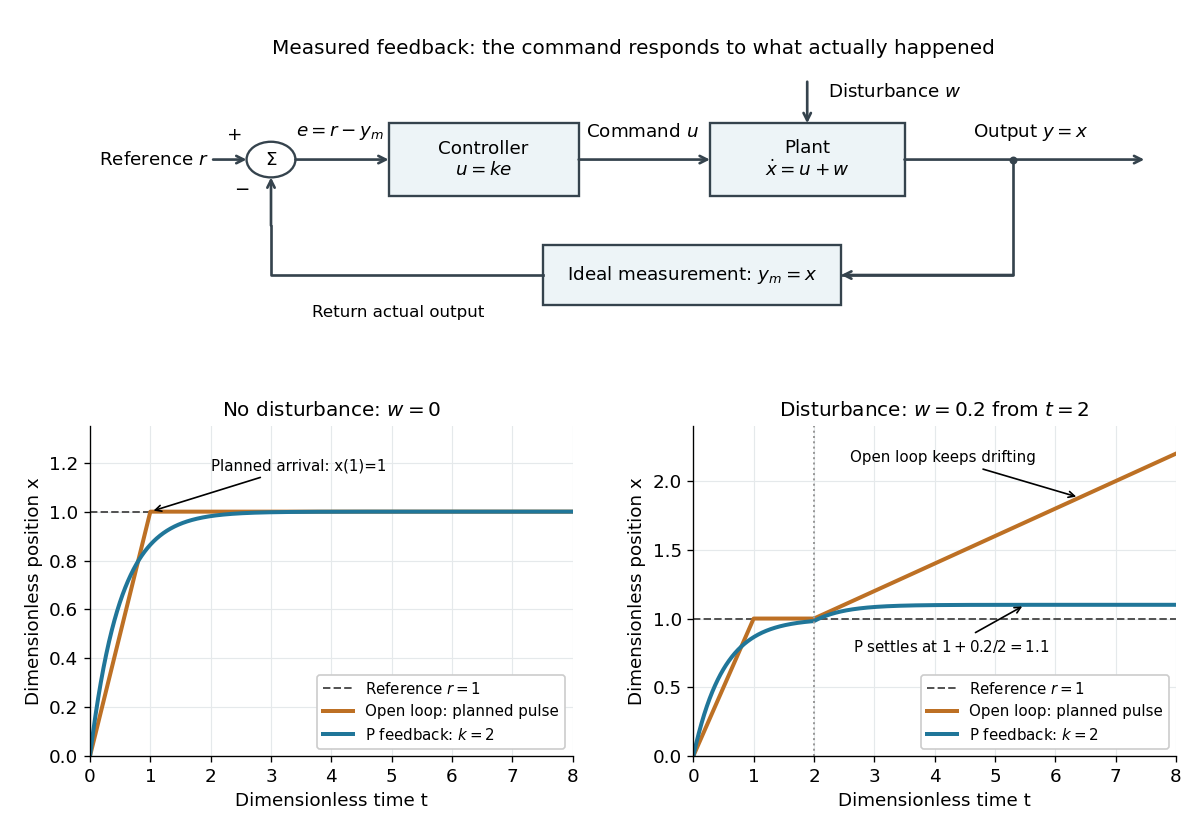
For the ideal controlled plant with , plan the control inputIntegration gives , so the planned command reaches the reference signal at . If an unplanned constant control disturbance begins at , the same open-loop control gives for : and . Knowing the nominal response did not provide a way to correct the actual plant output.
Quantum control chooses externally adjustable interactions to steer a quantum state or implement a desired unitary operator. Its achievable transformations depend on the Hamiltonian or Lindblad equation, the available control inputs, and physical constraints such as bandwidth and amplitude. Quantum optimal control optimizes performance within those constraints.
Individual quantum control of spins by exploiting different resonance frequencies. A sufficiently narrow-band radio frequency pulse can predominantly affect one resonance when the separation is large compared with the excitation bandwidth and coupling effects are accounted for. Equal resonance frequencies remove this frequency-based distinction. Whether individual gates remain possible then depends on other available interactions, spatial resolution, or differences in control coupling; frequency equality alone is not a universal impossibility theorem.
Let be the SWAP gate. If the drift Hamiltonian operator and every allowed control Hamiltonian operator commute with , every reachable time-evolution operator also commutes with . Indeed, satisfies the same initial-value Schrödinger equation as and starts at , so uniqueness gives . Yet . An individual Pauli Z gate is consequently unavailable within that symmetric control model. Equal nuclear resonances, isotropic exchange interaction, and identical coupling to a common homogeneous radio frequency field provide an example. An added interaction that breaks this symmetry can remove the obstruction.
For , , and an individually applied Pauli Z gate , conjugation gives . The paired Pauli operators commute with one another, soTwo equal free-evolution intervals, each of duration , therefore cancel exchange while retaining the Ising coupling. This spin echo is exact for instantaneous ideal gates; a finite pulse requires accounting for the interaction during the pulse. A simultaneous Pauli Z gate on each spin commutes with and cannot perform the same cancellation. The physical availability of the individual gate is a separate quantum control requirement.
On a connected transition chain, independently selected resonant pulses realize embedded two-level rotations with tunable angle and phase. Eliminate target amplitudes from one end of the chain using complex Givens rotations, and invert those rotations to prepare the target from a basis state. The pulse angles come from amplitude ratios and the phases from relative complex arguments. Spectator components are unchanged by each embedded rotation. Work in the interaction picture and compensate the known drift phases at the chosen final time when the target is specified in the laboratory frame.
An Ising coupling generates with in units . It is entangling precisely when is not an integer multiple of . A rotation on one qubit reverses its sign, permitting an ideal echo to cancel an always-on coupling.
A rotation about the x-axis on one qubit conjugates to its negative. With ideal instantaneous pulses, two equal free-evolution intervals separated by this pulse and its inverse cancel an Ising coupling exactly. Finite-duration pulses require accounting for the coupling during the pulses; the error is small only when times the pulse duration is small, or when the control is explicitly designed to compensate it.
In coherent quantum feedback, a quantum controller interacts with the controlled system without first converting the control signal into a classical measurement record. Optical feedback through a beam splitter is one example. The input-output interconnection must preserve the physical quantum dynamics, including noise and commutation relations; a classical state-feedback formula does not automatically define a valid quantum controller.
The rotating-wave approximation to a weak quadrature coupling of a cavity mode to a broadband field retains photon-exchange terms and removes counter-rotating pair creation and annihilation. Flat coupling around resonance produces the displayed interaction in units . Its short-time propagator is generated by ; the Gaussian quantum noise Ito table supplies the quadratic drift correction. The resulting passive cavity has the passive cavity input-output transfer function.
For a broadband bosonic input with , disjoint field increments commute and . An adapted system operator commutes with the next incoming increment. Noise increments scale as , so quadratic products contribute to first-order stochastic evolution.
For a zero-mean Gaussian bosonic input, completes the displayed table, with and . The vacuum has ; an unsqueezed thermal input has . Products with and higher differentials vanish in the first-order Ito equation. The difference between the first two products preserves the bosonic commutator.
For and , zero-initial-data Laplace transforms give the displayed transfer function. For its pole is in the open left half-plane, while and its zero lies in the right half-plane. Passing through in this plant's frequency plot is not evidence of an unstable open cavity: a Nyquist stability criterion needs an explicitly specified feedback return ratio.
With and , real and , eliminate the internal fields to obtain , where and . The internal output transfer is ; the external output transfer is . The loop is asymptotically stable in this nondegenerate range. At the cavity mode is undamped and decoupled; at the instantaneous algebraic feedback connection is singular.
Design Lindblad operators and a Quantum Hamiltonian so that desired density operators are stationary and unwanted perturbations decay. A dissipative interaction can change the spectrum and purity of a density operator, reaching targets unavailable to purely coherent Hamiltonian engineering. The engineered stationary state must be physical, and uniqueness alone must be distinguished from an explicit proof of asymptotic convergence.
Hamiltonian engineering designs accessible interactions or their effective time average to implement desired quantum states or unitary operators. The available control inputs, Quantum Hamiltonian generators and laboratory constraints determine which transformations can actually be achieved. Model-based open-loop control computes a waveform before running it; adaptive experiments instead evaluate its performance on the physical system.
Such a quantum state remains an eigenstate of for every control input. Its projector commutes with all available generators, so its population is conserved. This obstructs full-space pure-state controllability even when the orthogonal bright subspace can be controlled. An instantaneous dark state of a slowly varying Quantum Hamiltonian instead supports adiabatic quantum control if a spectral gap and slowness condition are maintained.
Fast prescribed pulses change the frame in which the system evolves during successive intervals. To leading order over a short control cycle, the effective Quantum Hamiltonian is the duration-weighted mean of these conjugated generators. The Baker--Campbell--Hausdorff formula supplies commutator corrections. Symmetrizing the cycle can cancel unwanted interactions or retain a desired one. The approximation requires control cycles short compared with the relevant dynamical timescales and a suitable account of finite pulse duration.
Design a slowly varying Quantum Hamiltonian path whose relevant initial eigenstate connects to a desired final eigenstate. Under the gap and slowness hypotheses of the quantum adiabatic theorem, the state follows that instantaneous eigenstate up to phase. The path, spectral gap and duration all matter; a level crossing or excessive speed can spoil the intended state transfer.
For a resonant three-level chain with couplings , the zero-energy dark state of a driven Hamiltonian is . Turning on the target-to-intermediate coupling first and sweeping from zero to infinity rotates this state from to . The other eigenvalues are , so controls nonadiabatic leakage. Ideally the intermediate state remains unoccupied, suppressing spontaneous-emission loss. The gap must not close while the dark state is rotating.
A near-resonant drive selects a transition and, in an appropriate rotating frame and rotating-wave approximation, controls a two-level effective Quantum Hamiltonian. If with fixed axis, then . Pulse area fixes the rotation angle; drive phase chooses a transverse axis. Selectivity and neglect of rapidly oscillating terms require the appropriate detuning and drive-strength regime.
For a fixed dimensionless Hermitian operator driven by , all instantaneous generators commute. The exact unitary operator is , so the area, rather than the detailed envelope, fixes the rotation. For , it is . This convention uses the Quantum Hamiltonian coefficient directly; a convention with instead has .
For a Hermitian operator satisfying , its squared operator is the projector onto the active eigenvalue- subspace. All remaining states have eigenvalue zero. Separate even and odd powers in the matrix exponential to obtain the displayed rotation on the active subspace and the identity on its spectator subspace. Thus an embedded two-level coupling need not square to the full Hilbert-space identity.
For and , the Hilbert-Schmidt distance gives . The choice yields . Decrease alone does not prove convergence: orthogonal pure eigenstates of a diagonal give zero input for a transverse Pauli control even though their distance remains nonzero. Such a law can be simulated to produce an open-loop control.
For , with both states evolving under the same drift and only receiving , cyclicity of the trace cancels the drift terms and gives the displayed identity. The scalar is real because is Hermitian. Choosing , , makes . This is nonincrease, not by itself convergence to the target: additional invariant-set and reachability conditions are needed.
Take , , and . The overlap is , but , so the Hilbert-Schmidt Lyapunov feedback identity gives . A target overlap and the derivative of that overlap along the control direction are different quantities.
Feedback control selects a control input using observations of the actual controlled plant. In a tracking loop, compare the reference signal with the measured output to form the tracking error , then let the controller change . The control input changes the plant output, which is measured again: that return path closes the loop. A controller can use earlier observations as well as the latest one. [ref]
https://www.fbswiki.org/wiki/index.php/Feedback_Principles. Åström and Murray, Feedback Systems, Chapter 2: Feedback Principles
For the ideal controlled plant, proportional control initially commands . As approaches , the command shrinks. When a positive control disturbance pushes above , the tracking error becomes negative and the control input pushes back. The result is a bounded offset rather than the continuing drift of open-loop control. Integral action can remove that offset by remembering past tracking errors.
A control selected from the observed current state, rather than specified only as a function of the initial state and time. For and stage cost , the infinite-horizon feedback gives and total cost . The finite-horizon Bellman coefficients satisfy , and increase to two, proving optimality.
A reference signal specifies the desired physical plant output as a function of time. A fixed reference signal is often called a setpoint; a changing reference signal describes a trajectory to follow. A reference signal is a goal, whereas the control input is the command chosen to achieve that goal. [ref]
https://jckantor.github.io/cbe30338-book/notebooks/03.06-Proportional-Integral-Control.html. Jeffrey Kantor, Practical Proportional and Proportional-Integral Control, nomenclature and sign conventions
Asking for a temperature of does not specify a heater command of : dimensional analysis distinguishes the units of these quantities. The reference signal and the measured output must describe the same quantity in the same coordinates before their difference can define a tracking error. An unconverted sensor readout cannot be subtracted directly from a desired temperature.
For example, let be temperature rise above a fixed ambient baseline , and write the desired temperature as . A Heaviside step function gives for , with before the change: the target rise becomes at once, although a physical controlled plant generally cannot jump at once. A ramp reference signal instead asks the temperature rise to increase at a fixed rate . If and , the first reference signal asks for a lasting one-degree rise; the second asks for a one-degree rise at and a two-degree rise at . Here degree Celsius differences are also kelvin differences. A target that grows forever is useful for analytical tests but eventually exceeds a real heater's range.
To make the distinction between a goal and a command concrete, the examples in steady-state tracking error use the first-order low-pass filter as a new controlled plant, rather than the accumulating controlled plant used in the earlier feedback demonstration:The time constant has units of time, has units of plant output per control input, and the additive control disturbance has the units of . This is an equivalent output offset, not the rate-like in . A heater interpretation uses in degree Celsius differences and in percentage points of heater command, with in degrees per percentage point; the control input is a command, not a direct measurement of delivered power. With exact measurement, holding requires . Thus even a constant reference signal can require a persistent nonzero control input. The numerical model below is deliberately synthetic and has no fitted laboratory parameters.
A ramp reference signal changes at a constant rate from onward. Its derivative is for . A ramp reference signal tests whether a controller can keep following a moving goal, rather than merely reaching a fixed one; a finite steady-state tracking error can coexist with an unbounded reference signal.
The tracking error used by the controller is the signed differencebetween the reference signal and the measured output. A positive tracking error means the readout is below the desired value; a negative tracking error means it is above. With exact measurement , and give . For a positive-response controlled plant, positive feedback gain in proportional control then reduces the plant output. The sign of the controller must also account for the sign of the controlled plant's response: a positive command that reduces the plant output requires a different sign choice. Kantor uses the opposite tracking error convention, , together with a minus sign in his controller; translating both signs gives the convention here. [ref]
Distinguish the controller's tracking error from the physical plant output discrepancy . If the readout has constant sensor bias , thenAll four quantities have the same units under dimensional analysis; a sensor bias is expressed in those units too. A readout that is too high by can make when the physical temperature is below the goal. Integral action integrates the tracking error it receives; it cannot infer this missing calibration information from that tracking error alone. Thermometer calibration against an independent reference addresses a different problem from tuning a feedback gain.
A motivating apparatus/model comparison is Park, Martin, Kelly and Hedengren's temperature-control laboratory: two TIP31C heaters with attached TMP36GZ sensors and heat sinks, an Arduino, a power supply, and a USB-connected computer. The readout converts sensor voltage to temperature; software records that measured output while specifying heater commands from to . For the single-heater test, one command changes in steps and the other heater stays off. Parameters are fitted to one run, then a different command sequence tests predictions without feeding measured temperatures into the simulation. The authors observe that their richer thermal model predicts the response better than the approximation with a single time constant and a delayed control input, especially after command changes. The real sensor has its own thermal lag. They also repeat the same command profile at different ambient temperatures and find changes in the response, motivating ambient-condition reporting. This experiment measures a command-to-readout response, not independently the exact heater temperature or delivered power. [ref]
https://www.researchgate.net/publication/338614896_Benchmark_Temperature_Microcontroller_for_Process_Dynamics_and_Control. Park, Martin, Kelly and Hedengren, Benchmark Temperature Microcontroller for Process Dynamics and Control, sections 2 and 3, Figures 3, 6 and 7: author-uploaded full text
The lesson for tracking error is to record three traces during a tracking test: the reference signal, the measured output, and the applied control input. Their first difference is the tracking error; a model prediction minus a readout is instead a model discrepancy. In a proposed comparison of proportional control and proportional-integral control, keep the initial temperature, ambient conditions, heater limits, and target changes fixed; run the second heater separately as a known control disturbance. Independent thermometer calibration is needed to assess physical accuracy. These are suggested controls, not additional experiments claimed for the paper. A sensor's lag, measurement noise, actuator saturation, and changed ambient conditions can all invalidate conclusions drawn from the ideal first-order model.
The steady-state tracking error iswhen this finite limit exists. A finite steady-state tracking error does not require the reference signal, the plant output, or the control input to become constant: all can grow while their difference settles. If the tracking error grows without bound or keeps oscillating, report that behavior rather than assigning a finite steady-state tracking error. Eventual accuracy and asymptotic stability are different questions.
For the first-order low-pass filter introduced in reference signal, assume exact measurement, constant control disturbance , and no actuator saturation or feedback delay. Under proportional control with , a constant reference signal givesThe decaying homogeneous solution has rate , so this equilibrium point is approached from any finite initial condition. A nonzero tracking error is needed to maintain the control input that balances the model's tendency to relax toward . This differs from the accumulating controlled plant , for which proportional control already tracks a constant reference signal exactly when . The presence or absence of a step offset depends on both the controlled plant and the controller.
For a ramp reference signal , the same proportional control givesIts long-time particular solution grows with slope when . Thus the controlled plant and homogeneous closed-loop response are stable, but the tracking error has no finite steady-state tracking error. A changing goal requires a different performance test from a fixed destination.
Now use proportional-integral control , , with . For the same controlled plant, differentiate the error equation on intervals where the inputs are smooth:The characteristic polynomial has both roots of a polynomial in the open left half-plane: real roots have negative sum and positive product, and a nonreal complex conjugate pair has negative real part. This proves decay of the homogeneous error for this model. It does not prove stability of an arbitrary controlled plant controlled by positive gains. At a reference jump, use the original ordinary differential equations to set the new initial conditions, rather than treating the reference as smooth at that jump.
With a constant reference signal and constant control disturbance, proportional-integral control therefore gives . At its equilibrium point, , , and . The stored integral maintains the required command while the current tracking error vanishes. For a ramp reference signal, however, the forcing above is , andThe tracking error settles even though the accumulated integral and the required control input grow. This finite offset is the error needed to keep increasing that command. For with , the forcing is and even this proportional-integral control leaves a tracking error growing with slope . Integral action is therefore a precise mechanism for selected input classes, not a promise of perfect tracking for every reference signal. [ref]
https://www.fbswiki.org/wiki/index.php/PID_Control. Åström and Murray, Feedback Systems, Chapter 11: integral action and actuator limits
Here are completely explicit synthetic examples with , , and no sensor bias. Choose , per percentage point, percentage point per degree, and percentage points per degree-second. Thus is dimensionless, and . In the following formulas, denotes the numerical time in seconds and denote numerical temperature rises in degrees. For the unit-step reference signal , proportional control and proportional-integral control respectively giveFor the ramp reference signal , the corresponding solutions areThe control inputs here are numerical heater-command percentage points. Substitution into and into the controller equations checks these solutions without invoking an unverified limiting rule. The proportional control step offset is degrees; the proportional-integral control step offset is zero. The proportional control ramp error grows; the proportional-integral control ramp offset is degrees, exactly .
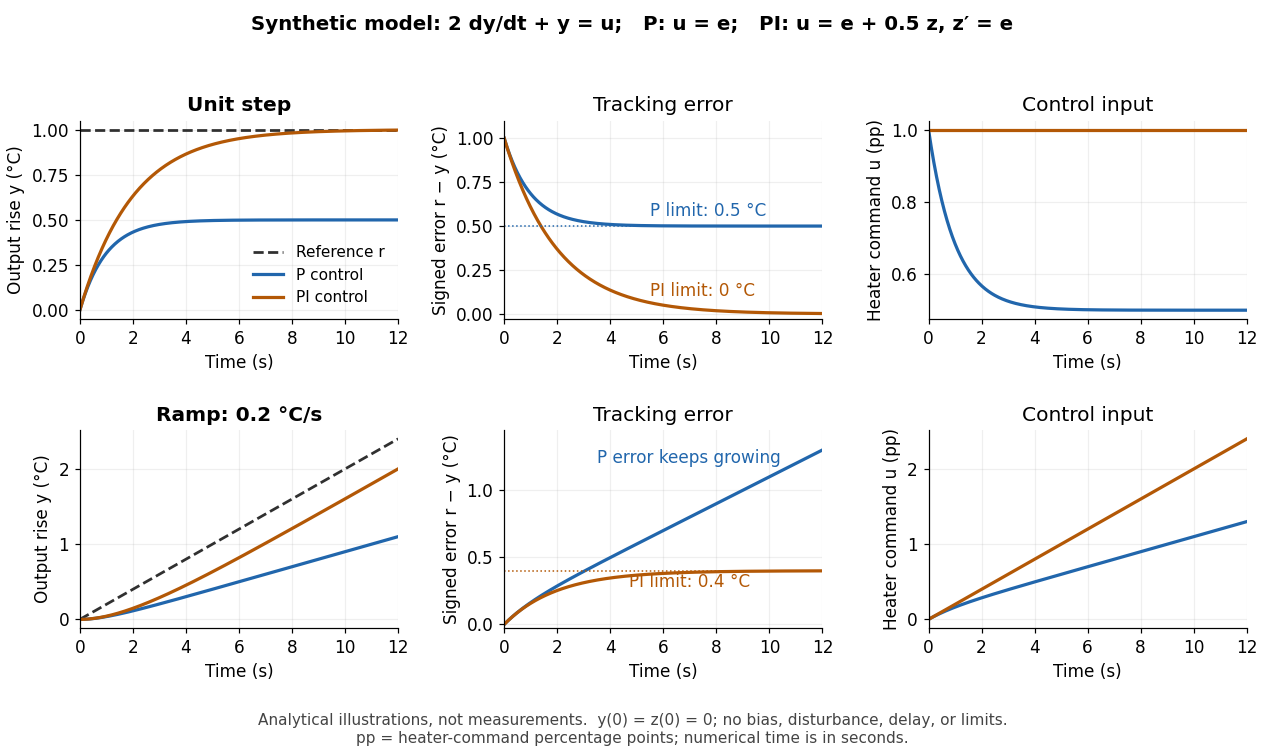
Synthetic step and ramp tracking of one stable first-order low-pass filter
. Original analytical model curves, not measurements or fits to the temperature laboratory. Columns compare plant output with reference signal, signed tracking error, and control input; rows use a unit step and a ramp of degrees per second. Both designs have decaying homogeneous responses. Proportional-integral control removes the step offset but leaves the ramp offset degrees; proportional control has an increasing ramp error. Heater-command percentage points and output degrees use separate axes. Details.The conclusions have specific limits. With constant sensor bias , stable proportional-integral control for a feasible constant reference signal drives the measured tracking error to zero but leaves the physical discrepancy . Under proportional control, the measured offset instead becomes . If actuator saturation prevents the required control input, zero step offset is not achievable by these formulas. A changing control disturbance contributes to the error equation, while feedback delay can change stability; neither is covered by the constant-disturbance result. These restrictions are what make steady-state tracking error useful: it identifies the input, measurement convention, and model for which an accuracy claim is actually justified.
Proportional control chooses a control input proportional to the current tracking error. For the ideal controlled plant and constant reference signal , its ordinary differential equation is . With and initial condition , the exact response isFor , and , this gives and . To verify the formula, substitute it into the ordinary differential equation and check the initial condition; its decaying exponential function explains the approach to the goal.
With a constant control disturbance, setting gives the equilibrium point and steady-state tracking error . For , doubling the feedback gain from to reduces the offset from to . This improvement is a statement about the ideal model: it neglects feedback delay and measurement noise, so it does not establish that arbitrarily large feedback gains are safe. [ref]
https://www.fbswiki.org/wiki/index.php/Introduction. Åström and Murray, Chapter 1: feedback benefits and drawbacks
In the first diagram's switched control disturbance experiment, and from give, for ,Thus and . At the equilibrium point, the controller supplies to cancel the control disturbance. Proportional control needs a nonzero tracking error to produce that persistent correction.
Integral action adds memory of the tracking error to a controller: . A persistent tracking error keeps changing , so an equilibrium point with constant must have . The accumulated value can remain nonzero after the tracking error has vanished, maintaining the control input needed to cancel a constant control disturbance. Convergence still requires a stable feedback control design. [ref]
Proportional-integral control is the proportional and integral part of a PID controller, with the derivative term omitted. Proportional-integral control combines proportional control with integral action. For the ideal controlled plant, a constant reference signal, exact measurement and a constant control disturbance, the ordinary differential equations giveThe characteristic polynomial is . Positive and imply asymptotic stability of the equilibrium point: real roots of a polynomial have negative sum and positive product, hence are both negative; a nonreal complex conjugate pair has real part . This is a short stability check for this ideal controlled plant, rather than a rule for every dynamical system.
At the equilibrium point, , , and . For and , the stored value supplies even though the tracking error is zero. This separates the eventual accuracy from the transient response: integral action cancels the lasting offset but can make the plant output pass beyond the goal. The authors discuss practical limits on integral action in Åström and Murray, Feedback Systems, Chapter 11.
For , , and , the characteristic polynomial is . The initial conditions are and , givingThe tracking error changes sign at . Since , the largest plant output occurs at and is , about above the reference signal.
For a separate comparison, start the control disturbance at . For , write . The exact responses areThe proportional control response tends to , while the proportional-integral control response returns to . At , the values are approximately and . The added term in the proportional-integral control response eventually vanishes, exposing how memory removes a constant control disturbance's lasting effect.
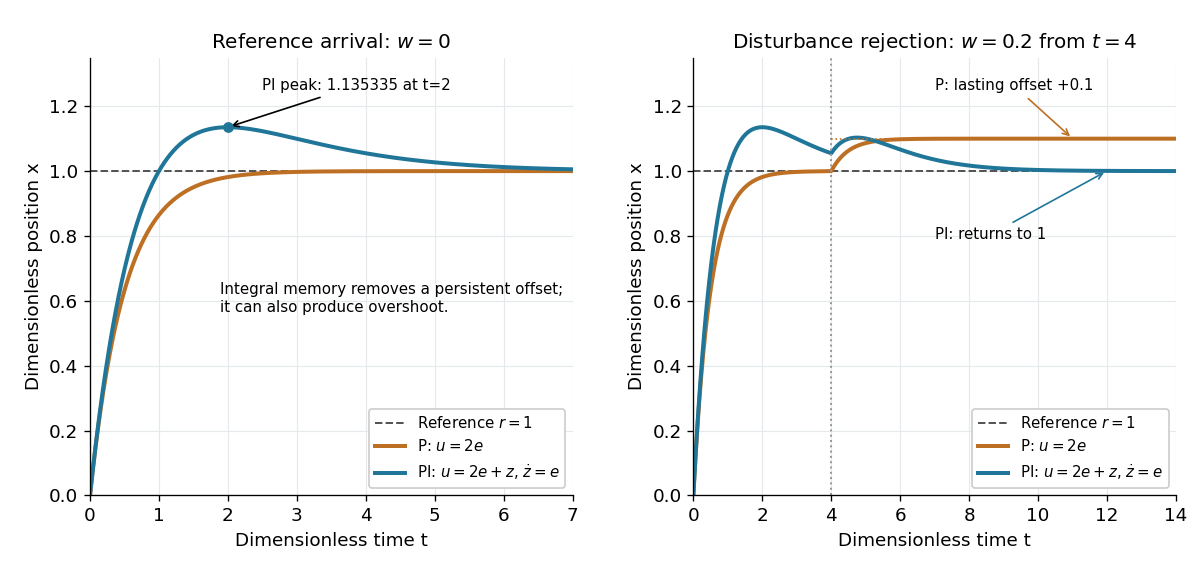
Proportional control and integral action: arrival and disturbance rejection
. Left: the ideal controlled plant has reference signal and no control disturbance; proportional-integral control reaches a peak at . Right: a control disturbance begins at ; proportional control settles at , while proportional-integral control returns to . The generator uses the classical fourth-order Runge-Kutta method with step , splits the computation at , and checks both full responses and the stored memory against their exact formulas. All coordinates are dimensionless quantities. Details.A feedback delay means a controller reacts to an earlier plant output. An accurate measurement can still be stale: when the plant output has already crossed the reference signal, a controller using the earlier value may continue pushing it away from the target. In a pure constant-delay model, with . This isolates timing from measurement noise; it does not describe every sampling or communication mechanism. [ref]
https://stevefrank.org/control/controlBook.pdf#page=99. Steven A. Frank, Control Theory Tutorial, section 13.4: delayed feedback of an integrator
For the ideal scalar controlled plant , a zero reference signal, no control disturbance, and proportional control with constant feedback gain , the equations areWith , this is an ordinary differential equation with exponential decay . With , it is a delay differential equation, requiring an initial history of delayed feedback. The delay stability of proportional integrator control depends on the product : even this simple controlled plant loses asymptotic stability at .
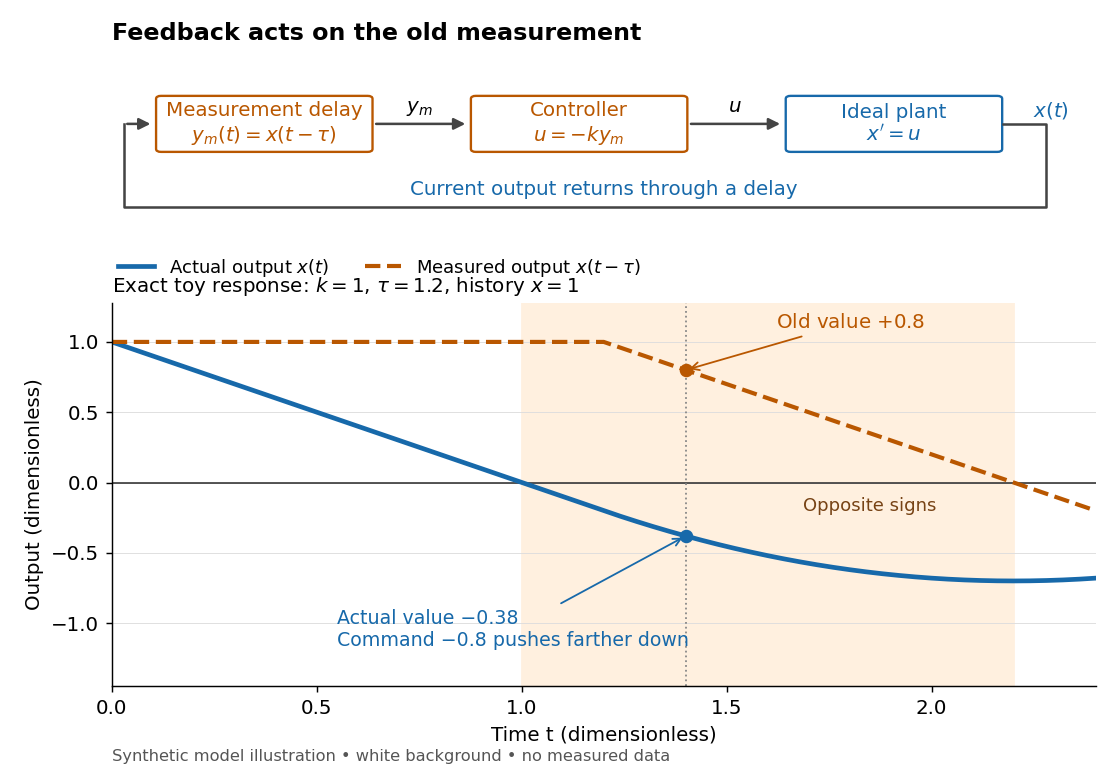
For positive feedback delay , an initial condition at a single instant is insufficient. Prescribe a continuous function throughout : for , the derivative depends on . A right derivative at is understood; the earlier history need not itself obey the subsequent control law. Once this first interval is computed, it supplies the delayed values for the next interval. This successive integration is the method of steps for a delay differential equation. [ref]
https://math1um.github.io/Teaching/cain-reynolds-odes.pdf#page=174. John W. Cain and Angela M. Reynolds, Ordinary and Partial Differential Equations, sections 6.1 and 6.2: history and the method of steps
For the constant initial history of delayed feedback , direct integration givesFor , , the plant output crosses zero at , while its measured output remains positive until . At , the delayed command therefore increases the magnitude of the actual deviation. This short exact calculation explains the first diagram without relying on a numerical approximation.
For the constant-coefficient model with and , the zero equilibrium point is asymptotically stable if and only if . For positive , perturbations are measured by the supremum norm of the initial history of delayed feedback; in the stable regime, every continuous history produces a solution tending to zero. At equality, nondecaying sinusoids prevent asymptotic stability. For , growing oscillatory solutions exist. These statements concern this ideal linear time-invariant system, rather than an arbitrary controlled plant. The corresponding linear equation and its threshold are developed in Cain and Reynolds, section 6.4, pages 174–177.
Substitute the exponential function , allowing a complex number . The characteristic equation isFor positive feedback delay this is not a characteristic polynomial: it has infinitely many roots. A root's real part determines growth or decay of its exponential mode, and its imaginary part determines the angular frequency. To find the first boundary, set with and use Euler's formula:The smallest positive crossing is and . Thus at the complex conjugate roots are . In fact, with the matching initial history of delayed feedback,solves the delay differential equation exactly: a quarter-cycle feedback delay turns the past displacement into precisely the current derivative. Its cycle lasts . The amplitude is arbitrary; this linear model does not select a finite-amplitude oscillation.
The roots cross toward growth as feedback delay increases. Differentiating the characteristic equation at fixed givesThis calculation identifies the direction of the first destabilization. The full threshold also requires ruling out earlier unstable roots: if with and , the characteristic equation implies and , hence . A real nonnegative root is impossible because there. This supplies the geometric reason the threshold is a quarter-cycle rather than an arbitrary fitting constant.
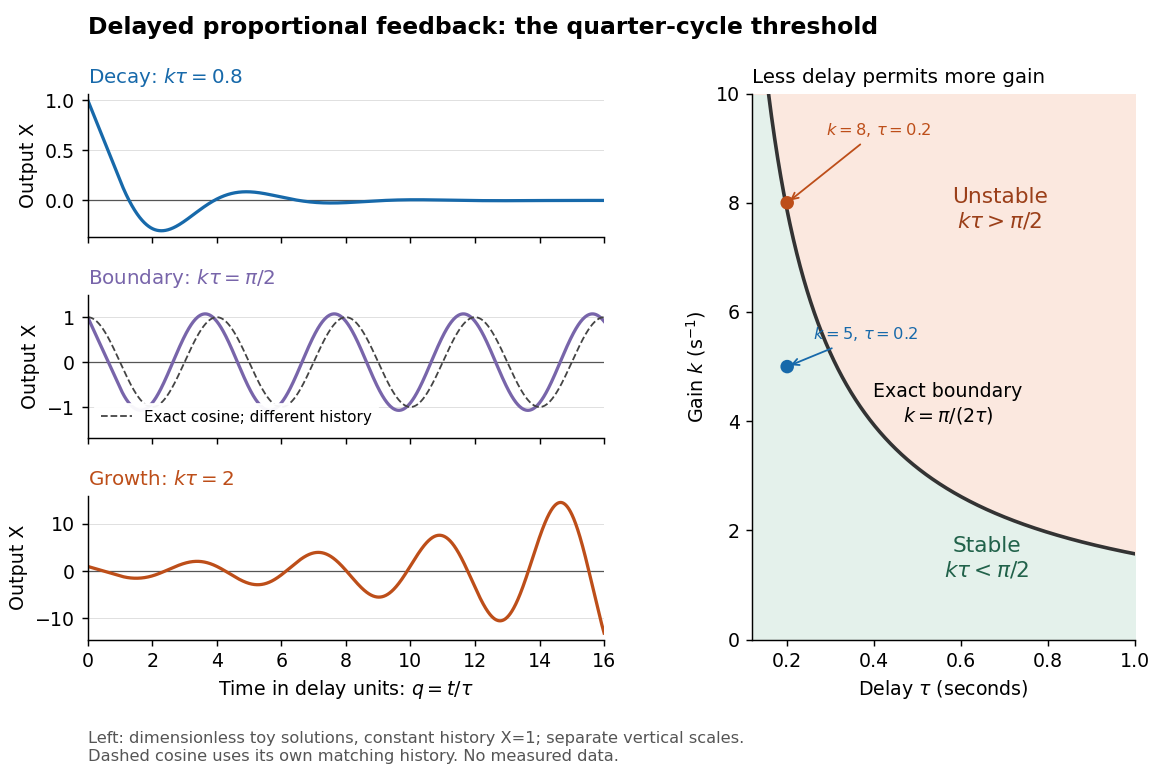
Feedback delay separates decay, persistent oscillation, and growth
. Left: numerical solutions with the same constant initial history of delayed feedback on , plotted against for , , and . The middle trajectory includes a transient because this history is not a pure sinusoid; the dashed curve is a separate exact solution with history . Each row has its own vertical scale. Right: the exact boundary for positive feedback gain and feedback delay. Toy responses are not measured data. The generator uses the classical fourth-order Runge-Kutta method with linear interpolation of delayed values and , checked against a separately evaluated exact finite sum and two coarser steps. Details.The tradeoff is concrete. Without feedback delay, increasing shortens the exponential decay time constant . With known , the same proportional control must satisfy . For , the threshold is : is stable and is unstable. A design close to the boundary leaves little room for additional feedback delay; reducing or reducing measurement latency increases that room. The zero-delay time constant is only a comparison scale, not the decay time of the delayed response. Frank discusses the gain–delay compromise in Control Theory Tutorial, section 13.4 and figure 13.3.
Can feedback delay change correction timing even when the physical task stays the same? Susilaradeya and colleagues tested this in a human tracking experiment. Participants pressed with both index fingers against fixed force sensors; the two forces controlled a screen cursor along two diagonal axes. A target moved in slow circular motion, usually at rotations per second. The researchers sampled the forces at samples per second and inserted an additional delay of , , , , or milliseconds before displaying the cursor. Each trial lasted seconds; the trials included per delay, in pseudorandom order. [ref]
https://pmc.ncbi.nlm.nih.gov/articles/PMC6453565/. Susilaradeya et al., Extrinsic and intrinsic dynamics in movement intermittency (2019), figure 1 and human task methods
The readout was fluctuation in cursor angular velocity, analyzed by Fourier transforms over approximately seconds from the middle of each trial. The principal peak was around hertz without added delay, around hertz with milliseconds, and around hertz with milliseconds. Thus changing observation timing changed the timing of corrective motion. [ref]
https://pmc.ncbi.nlm.nih.gov/articles/PMC6453565/. Susilaradeya et al., results: submovement frequencies are affected by feedback delays
This is an empirical motivation for taking stale observations seriously. Human feedback control includes prediction and other dynamics; these observations do not measure in the ideal integrator model or test its boundary.Measurement-based quantum feedback adapts a control input from a measurement record or conditional quantum state estimate. A measurement contributes backaction and generally stochastic dynamics. Exact instantaneous expectation values cannot be read from a single system without these effects. A feedback law derived for deterministic closed-system evolution therefore needs a new conditional dynamical analysis before being applied as measurement feedback.
An observed dissipative channel combined with direct feedback can create a modified Lindblad operator and a compensating Quantum Hamiltonian. Choosing those parameters can make a prescribed pure state stationary and globally attractive. At exceptional parameter values, the dissipator can instead leave an entire family of states stationary, so algebraic target stationarity does not establish stabilization. Checking the Affine Bloch equation and its transverse eigenvalues distinguishes these possibilities.
A chosen input to a dynamical system, commonly written in the state equation . An optimal control problem specifies both the admissible input set and any information or regularity constraints on the choice.
Choice of a control input to minimize an objective subject to differential equations for a state and constraints on the control, state or terminal time. Necessary conditions such as the Pontryagin maximum principle require regularity hypotheses and do not by themselves prove global optimality.
For bank dynamics and utility , substituting the terminal balance separates the concave optimization pointwise and gives the displayed control for . Put and . Its terminal balance is , so the unique positive multiplier achieving zero terminal wealth is . The same control solves the problem with no terminal reward and constraint , by the supporting-line inequality for logarithms.
For and with independent unit-variance normal noises, the equilibrium prediction-error variance is . Orthogonality to the next innovation gives the filtering gain . Minimizing the quadratic average cost gives a control Riccati coefficient satisfying , so and . Completing the control square yields minimal cost . The one-step observation delay is essential to the value of .
Quantum optimal control minimizes a state-transfer, observable, or gate error together with resource costs, subject to a controlled Schrödinger equation or Lindblad equation. Forward propagation of the state and backward propagation of a costate compute the gradient efficiently. The optimum depends on the admissible time-dependent fields and laboratory constraints.
For a real quantum optimal control objective , first variation gives the state equation, the adjoint equation, , and . The adjoint is taken for the Hilbert-Schmidt inner product. With dissipation it is essential to use , not silently the same generator as the forward state. These are necessary stationarity equations; they do not establish global optimality.
For and , enforce the state equation with . Variation gives the same Schrödinger equation for the costate, propagated backward from . Control variation gives the displayed real gradient. Forward state propagation, backward costate propagation, and a constrained gradient update form direct-adjoint looping. These are necessary stationarity equations, not a guarantee of a global optimum.
The Cauchy-Schwarz inequality for the Hilbert-Schmidt inner product gives for -dimensional unitary operators. Equality holds exactly when . When absolute gate phase matters, use the phase-sensitive Hilbert-Schmidt distance instead.
Parametrize a reproducible pulse by a finite vector and evaluate its objective experimentally on freshly prepared systems. Repeatedly update the pulse from measured objective values or finite-difference derivatives, including penalties for resources. This is closed-loop control across experimental runs, even when each pulse is open-loop control within a run. It reduces reliance on an inaccurate dynamical model but still requires preparation reproducibility, sufficient measurement statistics and stability of the experimental conditions.
Gradient ascent pulse engineering parametrizes each control by time-slice amplitudes and optimizes a differentiable quantum-control objective. Forward products of slice unitary operators and backward adjoint propagation give derivatives with respect to every amplitude. For , the exact derivative is . Updating all slice amplitudes along these derivatives is gradient ascent for a fidelity, or gradient descent for its negative.
For wealth dynamics and utility , with and , the unconstrained interior control equations do not give the maximum. Put . At positive shadow price , maximization over leaves a function of proportional to , up to constants. It is convex and hence maximal at or . The optimal controls work with zero consumption first, then cease work and consume at . The switch occurs where this consumption reaches ; the full discounted budget fixes and the switch time. The decreasing-consumption interior stationary candidate violates the Hamiltonian maximization condition.
A stochastic control problem chooses an admissible control input using information available in a filtration to optimize an expected objective for a random dynamical system. Dynamic programming often characterizes its value function through a Hamilton-Jacobi-Bellman equation.
A controlled Markov process has transition probabilities or rates depending on its current state and the chosen control action. A Markov policy selects an action from the current state and possibly the time. Once such a policy is fixed, the induced state evolution is a Markov process. For general history-dependent controls, the state alone need not remain Markov. A dynamic programming operator optimizes over the available actions at each state.
A Markov decision process specifies states, admissible actions, action-dependent transition probabilities and rewards. A policy chooses actions from observed information; a time-homogeneous problem uses transition and reward rules independent of the date. A Bellman equation optimizes current reward plus the conditional value of subsequent decisions. For nonnegative rewards, finite-horizon values increase as the horizon grows, while identification of their limit with the infinite-horizon value requires an approximation argument for admissible policies.
Estimating the expected return under a specified control policy. It is distinct from improving or optimizing that policy. A Bellman expectation equation describes the fixed-policy value, whereas a Bellman optimality equation compares admissible actions.
Policy iteration alternates evaluation of a fixed decision policy with improvement of its actions using the resulting value function. A stable policy satisfies the Bellman equation when each chosen action attains the required optimum.
In singular stochastic control, a control is a finite-variation process rather than only a rate integrated against time. Its increments can have atoms or a part singular with respect to time. The Hamilton-Jacobi-Bellman equation becomes a variational inequality with a constraint on directional derivatives of the value function.
Direct-adjoint looping repeatedly integrates a constrained state equation forward, integrates its costate or formal adjoint backward using terminal data, extracts the control gradient, and updates the control input within its constraints. It gives a practical route to local optimization but does not by itself prove a global minimum.
For a differentiable objective on an admissible real Hilbert space , with , stationarity on the sphere in a normed vector space of fixed kinetic energy means that the projected gradient is normal to the sphere in a normed vector space. Thus for a real Lagrange multiplier. It follows by testing all tangent variations orthogonal to . The multiplier need not be positive; second-order conditions are still needed for a local minimum.
A control input taking only extreme admissible values except possibly on a switching or singular set. If the Hamiltonian of an optimal-control problem is affine in a scalar control , a nonzero coefficient selects or ; a zero coefficient does not determine the control.
An adjoint variable enforcing the state dynamics in optimal control. In the normal minimization convention it satisfies for the Hamiltonian of an optimal-control problem, with terminal conditions determined by the endpoint constraints.
In a normal minimization convention for optimal control, the running cost and dynamics define . The multiplier is a costate; this Hamiltonian is a device for variational necessary conditions rather than necessarily a physical energy.
For a regular finite-horizon optimal control problem, an optimal trajectory admits nontrivial multipliers and a costate obeying adjoint equations, together with pointwise optimization of the Hamiltonian of an optimal-control problem. In the normal minimization convention , the conditions are , and minimization of over admissible controls; endpoint and state constraints change the terminal conditions. Abnormal extremals use a zero cost multiplier and must not be silently excluded.
For a closed planar path with , and , the signed area satisfies times the usual oriented area. Periodic Wirtinger and Cauchy-Schwarz inequalities give . Thus terminal requires cost at least . A clockwise circular path traversed once at constant speed attains equality, proving the global minimum rather than merely a stationary Pontryagin extremal.
For energy remaining , , , running cost and terminal cost , the normal maximizing Hamiltonian is , where the constant costate defines . Hence full power is chosen below the threshold and zero power above it. Free completion time on an active terminal arc gives . Global optimality still requires a comparison of feasible completion times; the maximum principle is only a necessary condition.
For a smooth normal optimal control problem with freely variable terminal time, fixed terminal state independent of that time and terminal cost , the optimized Hamiltonian of an optimal-control problem at completion satisfies . It follows by varying the terminal time in the augmented objective; restrictions on terminal time or a moving endpoint introduce additional terms or inequalities.
State estimation infers an unobserved state of a dynamical system from its observations and a model of its evolution. An observed position can help estimate an unobserved velocity; repeated noisy observations can help distinguish changes in the state from measurement noise. The result should describe both an estimate and its uncertainty. A Kalman filter does this exactly for a linear Gaussian state-space model, maintaining a conditional expectation and conditional covariance.
The time at which information is available matters. Causal state filtering estimates the present state from observations available now. State prediction estimates a future state from those same observations. Later observations can improve an estimate of a past state, but that is a different information set from the one a live controller had. Kalman explicitly distinguishes these estimation tasks in A New Approach to Linear Filtering and Prediction Problems (1960), section Optimal Estimates.
Causal state filtering estimates the current state of a dynamical system from observations up to the current time. Under quadratic loss, the conditional expectation is an optimal estimate. A Kalman filter obtains this estimate recursively for a linear Gaussian state-space model, without using future observations.
State prediction estimates a future state of a dynamical system using observations already available. A state-space model supplies the transition law. Unlike causal state filtering at the next time, the prediction has not yet incorporated that next observation; a Kalman prediction step therefore includes uncertainty from new process noise.
Articles were limited to the first 100 out of 126 total.
Articles by others on the same topic

Control theory is an interdisciplinary branch of engineering and mathematics that deals with the behavior of dynamic systems. It focuses on the design and implementation of controllers that manage the system's behavior to achieve desired objectives. Control theory is used in various applications, including aerospace, automotive, robotics, manufacturing, and process control. At its core, control theory strives to develop mathematical models of systems and to analyze their behavior over time.



This basically adds one more ingredient to partial differential equations: a function that we can select.
And then the question becomes: if this function has such and such limitation, can we make the solution of the differential equation have such and such property?
Control theory also takes into consideration possible discretization of the domain, which allows using numerical methods to solve partial differential equations, as well as digital, rather than analogue control methods.