Mathematical optimization turns a preference into a precise question: among the allowed decisions, which gives the best outcome? A model separates the objective function, which measures quality, from the optimization constraints, which determine the feasible set. This language unifies finding a cheap plan for a transportation problem, efficient scheduling, or an accurate model in linear regression. The separation is useful because changing a preference and changing what is possible are different modeling decisions. See Boyd and Vandenberghe, introductory optimization models.
For an objective function , a maximization problem asks for a feasible point satisfying for every ; a minimization problem reverses the inequality. This is a global extremum. A local maximum or local minimum compares only nearby feasible points, so finding one does not settle the global question.
Consider allocating ten units between two complementary inputs:The budget constraint forces a tradeoff: an extra unit of costs a unit of . The best allocation is , with objective function value . Without the budget constraint, gives : there is no global maximum. Constrained optimization can therefore have a finite answer even when the corresponding problem with fewer optimization constraints does not. Its beauty is that geometry, calculus, and an arithmetic-geometric mean inequality can certify the same answer.
The initial table of content was limited to the first level because it is larger than 1000 articles. There are 1447 articles in total. Expand a branch to load its children.
A penalty method incorporates constraint violation into the objective with a parameter controlling its cost. For an equality constraint , the quadratic penalty method adds a multiple of ; a power penalty uses higher even powers. The penalty can allow infeasible iterates while encouraging feasibility as the cost grows. This differs from a logarithmic barrier, whose domain itself excludes the constraint boundary and exterior. Existence of a penalized stationary point, convergence of its constraint violation and convergence of the primal points are separate questions.
For an equality-constrained optimization problem, an even integer makes this a nonnegative penalty for constraint violation. Its derivative is , with the power applied coordinatewise. The case is the quadratic penalty. Reducing increases the cost of infeasibility; it does not itself ensure that computed stationary points or minimizers stay bounded.
At a stationary point of the power penalty, define the displayed multiplier estimates. Its stationarity equation becomes . If and these multipliers are bounded, then each . Along any convergent primal subsequence, a further multiplier subsequence converges and yields equality-constrained first-order KKT conditions at the limit. This is a statement about finite cluster points: bounded multipliers alone do not prove convergence or boundedness of the primal iterates.
For smooth constraints , minimizeapproximately in , then update the nonnegative Lagrange multipliers by the displayed projected rule. Equality constraints instead contribute and use the unprojected update . The construction combines Lagrangian duality with a quadratic penalty method.
For an inequality, the exact identity is . Its unshifted negative part satisfies . On a violated constraint, accurate new multipliers therefore give violation of the order of times the multiplier error. This can achieve high feasibility accuracy without a vanishingly small , reducing condition number difficulties. The negative-part qualification is essential if an iterate approaches a binding constraint from the feasible side.
For constraints , , minimize the displayed merit function for progressively smaller , where . Increasing the quadratic penalty discourages constraint violation. In a violated inequality, differentiation gives the multiplier estimate ; an inactive inequality has estimate zero. Thus obtaining small violations by this method alone typically requires a very small , which may cause a large condition number in the inner minimization.
A merit function is a scalar objective function used by an iterative constrained algorithm to balance objective reduction and feasibility. It permits a line search or other acceptance test even when the original objective function alone is insufficient to judge progress. Quadratic penalty methods and the augmented Lagrangian method give two constructions with different treatments of multiplier information.
Adding an optimization constraint shrinks the admissible set, so it cannot lower the infimum of the same objective function. Every value attained on the smaller set was already available on the larger set. If both minima exist and the larger problem has a unique minimizer absent from the smaller set, the inequality is strict. This compares beam energies for free, pinned, and clamped endpoints without evaluating the energy integrals.
If a real-valued function has a zero in the feasible region, then , with equality precisely on that zero set. The minimum can therefore occur along a curve or a higher-dimensional set rather than at isolated critical points. To maximize it on a compact feasible region, maximize : both the largest and the smallest values of must be considered, since a large negative value also has a large square.
The metric k-center problem chooses at most centers from a finite metric space to minimize the largest distance from a point to its nearest center. For , exactly centers gives the same optimum: extra centers never increase the radius. The restriction that centers belong to matters; allowing centers anywhere in an ambient metric space is a different problem.
The basic packing argument is short. If a radius- solution uses centers, its closed balls cover . Two points assigned to the same center have distance at most by the triangle inequality. Thus points with pairwise distances greater than certify that no radius- solution exists. Greedily selecting a new center only outside all existing radius- closed balls therefore uses at most centers whenever a radius- solution exists, and its final covering radius is at most . The farthest-first traversal achieves the same approximation ratio without knowing .
Starting with an arbitrary point in a finite metric space, repeatedly select a point maximizing its distance to the selected set. Maintain each point's distance to its nearest selected center; each new center updates all those distances, giving distance evaluations for centers.
For the metric k-center problem, let be the final covering radius and add a point realizing to the selected centers. Every pair among these points has distance at least : at each selection the current maximum distance is at least its final value. If the optimum radius is , two of these points belong to the same optimal radius- closed ball, so the triangle inequality gives . The case is already optimal. This proves a factor-two approximation algorithm.
The set of minimizers of an objective:It is a set of inputs, whereas the minimum is an objective value. The argmin can be empty if an infimum is not attained, a singleton, or a larger set.
If is strictly increasing on the range of , then if and only if . Quantifying over every proves that and have the same argmin, whether or not a minimum is attained. Squaring therefore preserves the argmin of a nonnegative objective, while squaring a signed objective need not preserve its argmin.
A line search chooses a positive step size along a search vector , updating to . For a differentiable function , a descent direction makes sufficiently short steps decrease the objective function; an Armijo condition quantifies the decrease, while the Wolfe conditions also prevent accepting an unnecessarily short step.
Suppose is bounded below on its initial level set, continuously differentiable with a Lipschitz gradient nearby, and each descent direction uses a step satisfying fixed Wolfe conditions. If , the displayed series converges. In particular a uniform positive lower bound on these cosines gives .
For a gradient Lipschitz constant , the curvature condition gives . Sufficient decrease then gives . Summing and using the lower bound on proves the assertion.
A search direction is the nonzero vector used in the displayed optimization update. In a line search with positive step size, its orientation matters: a descent direction has negative directional derivative of the objective function. Minimization over a full line instead permits either sign of .
A line search that finds a global minimizer along the chosen ray, provided one exists. For a negative gradient direction, its decrease in the objective function is at least that of any admissible fixed step size. The cost of solving this one-dimensional minimization problem must be included when comparing computation time.
Target: vector-space.bigb, under Vector subspace.A vector is a descent direction for a differentiable function at if its directional derivative is negative. The first-order expansion then gives for sufficiently small positive . The negative gradient is a descent direction whenever the gradient is nonzero.
For a nonzero gradient, this unit direction minimizes the directional derivative among Euclidean unit directions. The Cauchy-Schwarz inequality gives , with equality for the displayed direction. The steepest descent method usually uses the equivalent unnormalized direction and chooses a separate step length. A different choice of norm can change the steepest direction.
For and a descent direction , the Armijo condition asks for a decrease at least a fixed fraction of the decrease predicted by the first-order Taylor expansion. Put . Differentiability gives for all sufficiently small positive . Thus the condition is satisfiable without a second derivative.
Start with a trial step size and repeatedly replace by , with , until the Armijo condition holds. For a differentiable function and a descent direction, the short-step argument in the Armijo condition proves finite termination. This alone does not enforce the curvature part of the Wolfe conditions.
For a continuously differentiable function, a descent direction and , the Wolfe conditions require both the Armijo condition andThis second inequality is the weak curvature condition: the slope must have become less negative. The strong variant instead requires . The weak version already guarantees a positive curvature pair for the Quasi-Newton secant equation.
Suppose is continuously differentiable, is a descent direction, and is bounded below for . A positive step size satisfying the weak Wolfe conditions exists. To prove this, put , , and . The Armijo condition proof shows just to the right of zero. Boundedness below gives . Consequently there is a first positive zero , with on . By the mean value theorem, some satisfiesAt , gives the Armijo condition, and the displayed derivative gives the weak Wolfe conditions.
Run a local optimization method from multiple initial points and compare the feasible solutions it returns. This can explore different attraction regions, but a finite set of starts does not generally certify a global minimum.
Optimization of an objective given as a ratio, such as area divided by perimeter. When the denominator is positive, a trial ratio can be tested by maximizing numerator minus times denominator.
For maximizing with , repeatedly maximize and update to the ratio at the selected maximizer. If the maximum difference is zero, is the optimal ratio. Exact convergence claims require the relevant existence and regularity assumptions.
A constraint qualification is a regularity hypothesis on optimization constraints that guarantees a specified optimality or duality conclusion. For the necessity of Karush-Kuhn-Tucker conditions, an appropriate constraint qualification ensures that a local minimum admits suitable Lagrange multipliers; linear independence of the gradients of equality optimization constraints and active constraints is one sufficient hypothesis in KKT regularity at a local minimum.[ref]
Lecture 7: Lagrange Multipliers and KKT Conditions. Lecture 7, §L7.1.3, Theorem L7.3, printed p. 4: independent active gradients
Slater's condition provides a different constraint qualification for convex optimization, yielding strong duality and dual attainment.[ref]Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §5.2.3, printed pp. 226–227: Slater's condition, strong duality and dual attainment
At a feasible point for smooth , , the equality gradients must be independent and there must be a direction with and for every active inequality. It supplies a first-order direction strictly into all active inequality constraints while respecting the equality tangent space. This constraint qualification ensures the usual Karush-Kuhn-Tucker conditions are necessary for local optimality. For a strictly convex quadratic inequality restricted to an affine equality space, it holds at every feasible point exactly when a strictly feasible point exists; moving from a boundary point toward a strictly feasible point supplies the required direction.
For smooth equality constraints and inequality constraints , this condition requires linear independence of all equality gradients and active inequality gradients at the feasible point. It ensures existence of Lagrange multipliers at a local optimum and uniqueness of their values for a fixed objective gradient. It implies the Mangasarian–Fromovitz constraint qualification by solving the independent gradient equations with zero equality derivatives and positive active inequality derivatives.
Scheduling assigns jobs to processing resources and orders their execution subject to resource and precedence requirements. Objectives include completion time, lateness and throughput. In single-machine sequencing with all jobs mandatory, the total processing time is constant, but order-dependent setups can still change completion time. With parallel machines, machine allocation and sequencing jointly determine the parallel-machine makespan with sequence-dependent setups.
For single-machine jobs all available at time zero, order by nondecreasing deadline. Keep a tentative on-time list. Whenever appending a job makes its completion exceed its deadline, delete a job of largest processing time from that list and place it on a rejected list. Append all rejected jobs at the end. This minimizes the number of late jobs: at the first missed deadline at least one job of that prefix must be rejected, and rejecting a longest one frees at least as much processing time as any alternative. The exchange argument applies recursively to the remaining prefixes. The algorithm needs no ordering of the rejected jobs to determine the minimum count.
The time at which all work in a scheduling instance has finished, equivalently the largest completion time measured from a common start. For divisible job sizes and positive machine speeds , when each machine's completion time is its total assigned size divided by its speed, the minimum makespan is . The lower bound follows from total processing capacity; assigning the fraction of each job to machine attains it.
On one server with all jobs initially available, nonnegative fixed durations and no sequence-dependent setup, a nondecreasing-duration order minimizes the sum of completion times. Swapping adjacent durations reduces their combined contribution by and changes no later completion time, because their total duration is unchanged. Repeated adjacent exchanges remove every inversion. The sum of pre-service waiting times has the same optimum, differing by the fixed total duration.
Partition jobs between machines and choose an ordering on each machine. Machine has load equal to its processing times, initial setup and internal changeovers; the completion time of all jobs is the maximum of these loads. Minimize a variable subject to for every machine. Branch and bound can combine machine-assignment decisions with route bounds; heuristic moves relocate jobs between machines, swap jobs, and reorder blocks. Minimizing the sum of route costs alone does not generally minimize the makespan.
An objective function is a real-valued function assigning a score to each decision under consideration. An optimization problem seeks a feasible solution maximizing or minimizing this score. The optimizing decision and its score are different objects: in the budget constraint example, the decision is and the optimal value is .
Choosing an objective function expresses what matters. With and , maximizing makes every feasible point equally good; maximizing selects ; maximizing rewards balance. If are side lengths, is a rectangle's area, and the budget constraint fixes its perimeter at . The same mathematics then says that a square encloses the largest area among these rectangles.
For the product objective function, the positive level sets are hyperbolas. Each collects decisions with identical scores. The highest attainable level set touches the feasible set at ; higher ones miss it entirely.
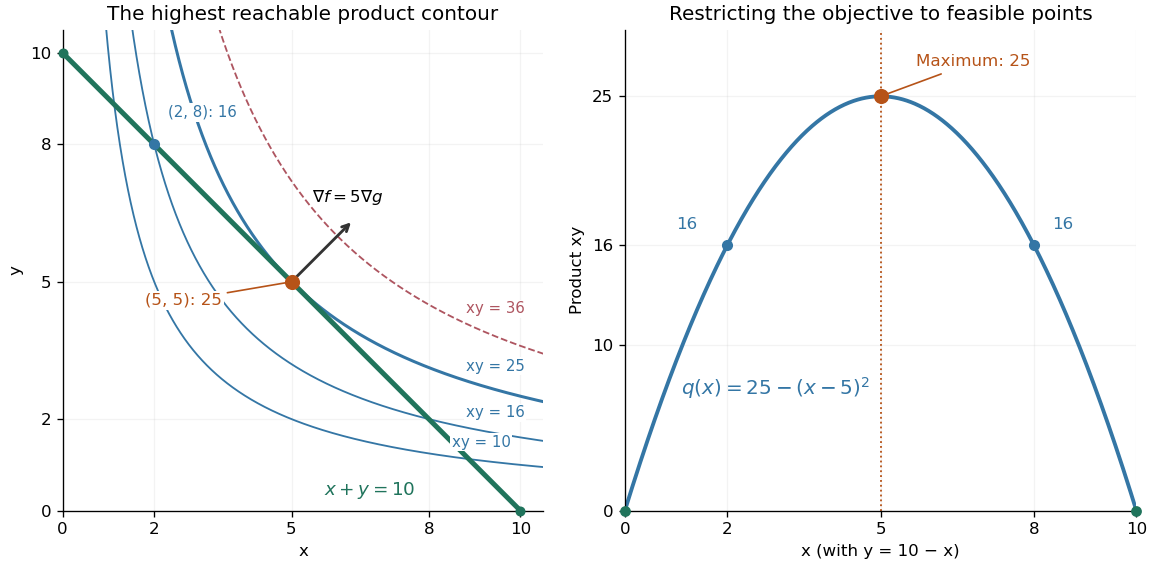
The product is neither a convex function nor a concave function on the positive quadrant: along it is , while along it is . Yet its restriction to this feasible set is a strictly concave function. Thus the geometry of the allowed decisions can make an otherwise nonconcave maximization problem tractable. Replacing by always converts a maximization problem into an equivalent minimization problem.
// Target: mathematical-optimization.bigb
Project scheduling asks how quickly a collection of dependent activities can finish. Adding their durations usually overestimates the answer, because independent activities can run together; taking only the longest single activity usually underestimates it, because some activities must wait. The critical path method identifies the chain of dependencies that determines the finish time. Its simplest model assumes known, fixed durations, unlimited parallel processing, and precedence requirements saying that each predecessor must finish before its successor starts. These are the assumptions of the basic model in Hendrickson, Project Management for Construction, §10.2.
Represent each activity by a vertex of a finite Directed acyclic graph; an edge means that activity waits for activity . Activity runs without interruption for duration , starting at . The optimization constraints and project finish time areThe objective function is to minimize . All durations and start times use the same time unit, and the project starts at time zero. The Directed acyclic graph assumption allows a topological order in which every predecessor is processed first.
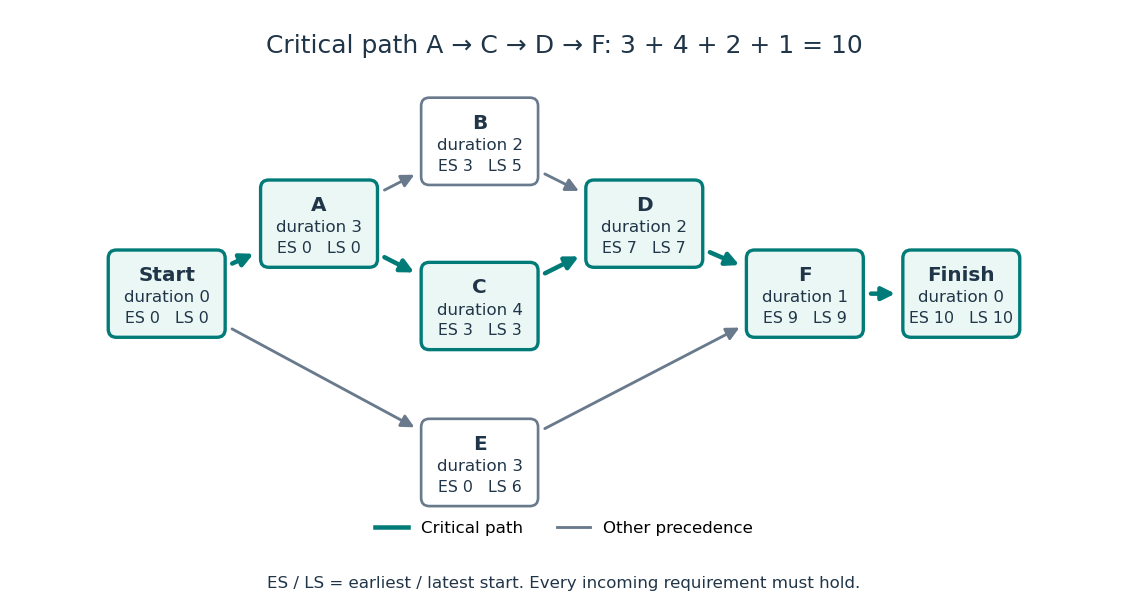
Consider this small, abstract project:
Activities A and E may start together. After A finishes, B and C may run together, but D must wait for both. F must similarly wait for both D and E: a merge means all incoming requirements must hold. This activity-as-vertex convention keeps durations on the activities and uses arrows only to express precedence.
Unlimited parallel processing is essential to the equality between the longest graph path duration and the optimal finish time. For example, two independent chains, each containing two activities of duration 3, have longest graph path duration 6. Two processors can finish both chains in 6, but one processor needs 12 because all four activities must run sequentially. Thus with limited resources the longest graph path still gives a lower bound, but it need not be achievable. Such resource requirements belong to the broader subject of scheduling.
// Target: mathematical-optimization.bigb
The critical path method calculates an earliest schedule, a latest schedule for a chosen finish time, and each activity's task float. A critical path is a start-to-finish graph path whose total duration is greatest. There can be several such graph paths, and every one constrains completion. In the six-activity project scheduling example, the critical graph path is A-C-D-F, of duration .
Add a zero-duration source before every initial activity and a zero-duration sink after every terminal activity. Give each edge weight , including zero weight on edges leaving . This produces a weighted graph in which a graph path's weight counts every activity on it exactly once. The possible source-to-sink graph paths in our example, omitting the dummy endpoints, are A-B-D-F with weight 8, A-C-D-F with weight 10, and E-F with weight 4.
Every feasible schedule must accommodate each of these sequential chains. Consequently,This bound applies to all source-to-sink graph paths, not just the one we happen to inspect. The critical path method attains the bound by setting each activity's earliest start to the maximum of its predecessors' earliest finish times:Evaluate this recurrence in a topological order, obtained by topological sorting. Each satisfies every incoming optimization constraint, so these times form a feasible solution. The same recurrence calculates the greatest weight of a graph path from to ; hence the feasible finish matches the lower bound. This is dynamic programming on a Directed acyclic graph, rather than an enumeration of all graph paths. See Paul Johnson, Scheduling and longest paths, longest-path algorithm. The linear programming formulation and its certificate are developed in project scheduling duality and unit-flow certificate for project duration.
For our project scheduling example, , , and the two merges giveF finishes at 10. All six activities are completed, even though E is absent from the critical graph path. Recording which predecessor attains each maximum lets us trace a critical graph path backward from the sink; retaining tied choices exposes multiple critical graph paths.
Now fix the project start at zero and the finish at . The latest starts come from a backward pass in reverse topological order:Every activity must finish by the earliest of its successors' latest starts, explaining the minimum here. This gives , , , , , and . These latest times themselves form a feasible solution finishing at 10. The backward calculation depends on the chosen finish time; a later deadline would give different latest times and task floats. The forward and backward passes are described in Olivier de Weck, MIT ESD.36 Lecture 2, slides 22–29.
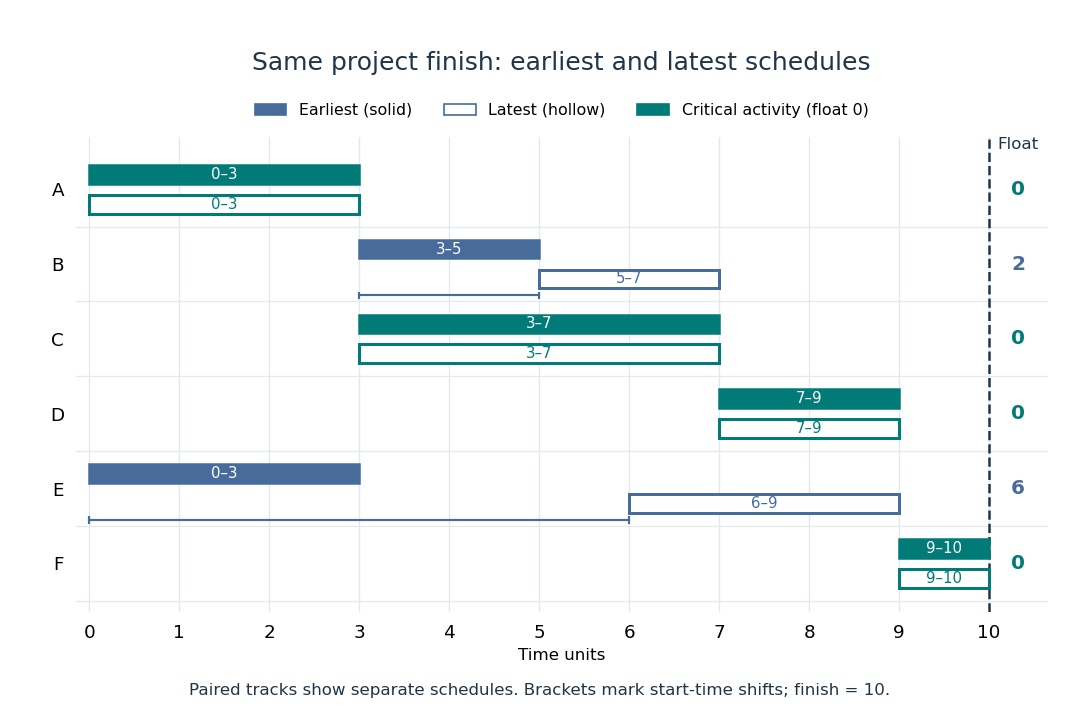
Earliest solid and latest hollow activity bars for the critical path method, with task floats of 2 for B and 6 for E
. Details. Changing a duration can change which graph paths are critical. If B's duration becomes 4, A-B-D-F and A-C-D-F both take 10: there are two critical graph paths. Shortening C alone then cannot reduce the finish time, because the chain through B still takes 10. If B's duration instead becomes 5, the earliest starts of D and F become 8 and 10, and the finish becomes 11. A-B-D-F is now the unique critical graph path; C has task float 1 relative to that new optimal finish. These calculations show why the critical path method is useful for understanding where a duration change matters, even in a project containing many parallel activities.
Task float, also called total float or task slack, measures an activity's available start-time delay relative to its earliest start, while allowing a feasible schedule that meets the fixed project finish. For earliest start , latest start , and fixed duration , it isIn the six-activity project scheduling example with start zero and finish 10, B has task float 2 and E has task float 6. B can move from the interval to , and E from to , without changing D's or F's earliest starts. A, C, D, and F have zero task float. With the finish fixed to the optimal duration and the basic critical path method assumptions, zero task float identifies exactly the activities lying on at least one critical graph path. See Hendrickson, §10.4, Activity Float and Schedules.
Task float is not generally an independent allowance that can be spent separately on every activity. For a small example, let two duration-1 activities X then Y form one chain, running in parallel with a separate duration-4 activity. The optimal finish is 4. X has earliest/latest starts 0/2 and Y has earliest/latest starts 1/3, so each has task float 2. Delaying X to 2 forces Y to start at 3, using Y's allowance too. Choosing X at its latest start 2 and Y at its earliest start 1 violates precedence, although both chosen times lie inside their individual ranges. The optimization constraints still couple the decisions. Here B and E can both use their full task floats together because they lie on separate branches; that freedom must be checked from the Directed acyclic graph.
// Target: mathematical-optimization.bigb
On the augmented precedence graph, the linear programming problemhas dual , with a unit source-to-sink flow. Equivalently, the dual is the negative of the optimal uncapacitated minimum-cost flow value with arc costs . The flow selects a longest path, while the time variables provide a matching weak duality bound.
// Target: mathematical-optimization.bigb
A feasible timetable with finish time and a unit flow carried on a precedence path of total duration certify optimality. Summing the inequalities along that path proves every schedule needs at least , while the timetable attains it.
// Target: computer-science.bigb
Maxima and minima are extrema of a real-valued function. A global maximum of on its domain is a point with for every ; a global minimum reverses the inequality. A local extremum requires the inequality only in a neighbourhood of the point within . In constrained optimization, is the feasible set, so an extremum is tested relative to the constraints rather than in every ambient direction. Thus a constrained local maximum or local minimum can occur at a boundary point without being an interior critical point.
A local extremum of a real-valued function is either a local maximum or a local minimum, with comparisons restricted to a neighbourhood in its domain. A differentiable interior local extremum is a stationary point, but the converse can fail, as at zero shows.
For positive constants , a Cobb–Douglas production function describes output in terms of capital and labour . It is homogeneous of degree . Under with , its unique nonnegative-input optimum is and , obtained by maximizing the strictly concave logarithm along the budget line. The optimized output has derivative , equal to its budget Lagrange multiplier. When , the unconstrained Lagrangian supremum over the positive orthant is infinite for every finite multiplier, despite the finite constrained optimum; the global dual representation must not be presumed in this case.
Heuristic optimization seeks useful feasible solutions without necessarily providing a universal approximation ratio or a polynomial worst-case guarantee. Examples are local search, simulated annealing and tabu search. A claimed approximation algorithm needs a separate proved performance guarantee.
Tabu search keeps a short-term memory of recently reversed moves or visited attributes and prohibits them temporarily, reducing cycling in local search. It can select the best admissible neighbor even when that neighbor worsens the objective; an aspiration rule permits a tabu move when it improves the best known solution. For allocations, transfers and exchanges maintain feasibility and recent reverse transfers can be tabu.
Simulated annealing accepts worse feasible solutions to escape a local minimum. Minimize an objective function , analogous to energy. Effective temperature has the same units as , absorbing the Boltzmann constant; it controls exploration, rather than a material's thermodynamic temperature.[ref]
Optimization by Simulated Annealing by Scott Kirkpatrick and others. Printed pp. 672–673: effective temperature and cost as energy
Given current feasible point , draw from a proposal distribution . For a symmetric proposal distribution, , use the Metropolis–Hastings acceptance probabilityAccept with this conditional probability; on rejection retain . Every downhill or equal-cost proposal is accepted. Draw a fresh uniform random variable on and accept if . The off-diagonal transition probability includes proposing .[ref]
Optimization by Simulated Annealing by Scott Kirkpatrick and others. Printed p. 672: acceptance rule and rejected proposals
For a maximization problem with objective function , set : every improving proposed neighbor is accepted, and a worsening move of loss has conditional probability of acceptance, under the same symmetry assumption. Likelihood-power annealing uses precisely this sign convention for a log-likelihood. Retain the best feasible solution seen, since the current state can worsen even after a global minimum has been visited.
If the proposal distribution is asymmetric, use the full Metropolis–Hastings acceptance probability, for ,A missing reverse proposal gives zero acceptance. Even a downhill proposal need not be accepted with probability one in this case. Choosing uniformly among a variable number of neighbors is generally asymmetric: and give the correction , where is vertex degree.[ref]
The useful idea is to separate exploring from insisting on improvement: an uphill move can open a route to a better feasible solution. Its usefulness depends on the proposal distribution, the scale of the objective function, and the cooling schedule for simulated annealing. Finite practical schedules carry no general guarantee of finding a global minimum.
To maximize a log-likelihood, use energy and Boltzmann distribution proportional to at temperature . Reversing this sign favors likelihood minima and can make the probability density function nonnormalizable. For Poisson observations with total and sample size , with respect to the normalized probability density function isIts mean is and variance , so it concentrates at the maximum-likelihood estimate as . Cooling of equilibrium laws and convergence of a particular changing-temperature chain are different statements; the latter requires mixing or a direct chain argument.
For independent binomial distribution observations with fixed trial count and total successes , the likelihood-power probability density function relative to is . Its normalized law is the displayed beta distribution. Its mean tends to and its variance tends to zero as , including endpoint maxima. Energy for maximizing a log-likelihood is its negative; the opposite sign reverses the optimization.
Let and . With Lebesgue base measure for , the likelihood-power law has conditionalsThe joint law is proper for , since its marginal is inverse-gamma distribution with shape and scale . There is also a direct convergence proof for successive Gibbs sampling updates with deterministic and . Update from , then from . Inverse-gamma distribution moments and conditional normal moments giveThe coefficients of the preceding moments are bounded by and , so these moments stay bounded from a finite deterministic initial variance. Letting gives and . Also . Thus the iterates converge in mean square to the normal maximum-likelihood estimate.
Consider the chosen finite minimization problemOnly adjacent integers are neighbors. At each interior state propose left or right with probability each; at an endpoint propose its sole neighbor with probability and itself with probability . This proposal distribution is symmetric, including at the endpoints. The local minimum at is relative to these allowed moves; is the unique global minimum.
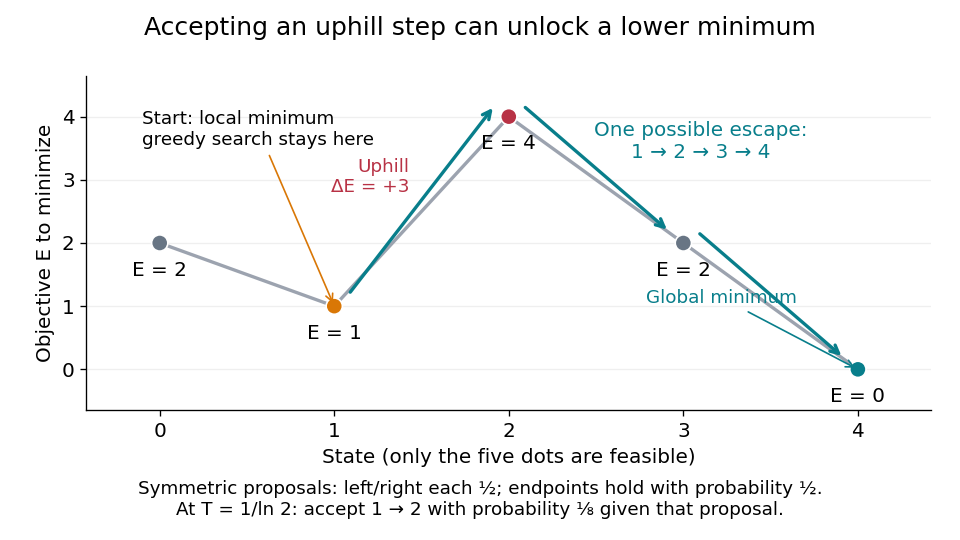
At , improving-only local search rejects both neighbors because and exceed . For simulated annealing, choose , using the natural logarithm. Conditional on proposing from , the acceptance probability isThe one-step transition probability is instead . Both subsequent rightward proposals are downhill, so the conditional probability of the precise next three states being , given and fixed , isThis is one possible escape route, not the probability of eventually reaching . Rejections, excursions toward , and repeated attempts give many other sample paths. The calculation establishes possibility, without claiming a general performance advantage from a selected sample path.
For comparison, halving makes the uphill acceptance probability ; doubling it makes that probability . Cooling makes it harder to leave this local minimum, even though the stationary distribution increasingly favors the global minimum. That tension is the central scheduling problem.
On a finite state space with finite objective function values, the fixed- target is a Boltzmann distribution:The partition function normalizes the weights but cancels from the Metropolis–Hastings acceptance probability. A short detailed balance proof explains the target. With symmetric and ,Summing over gives , so this is a stationary distribution. On a finite state space, a connected graph of positive symmetric proposals makes the accepted Markov chain an irreducible Markov chain. Convergence from any starting state additionally requires an aperiodic Markov chain; one positive self-transition suffices under irreducibility. Replacing by ensures this. For asymmetric , require connectivity through bidirectional proposals: one-way proposals are rejected.[ref]
In the five-state barrier example for simulated annealing, gives exact Boltzmann weights . Multiplying by givesFor the uphill edge, detailed balance is visible numerically:Thus the global minimum has the largest individual stationary probability, , but is far from certain at this positive . At the exact stationary distribution is .
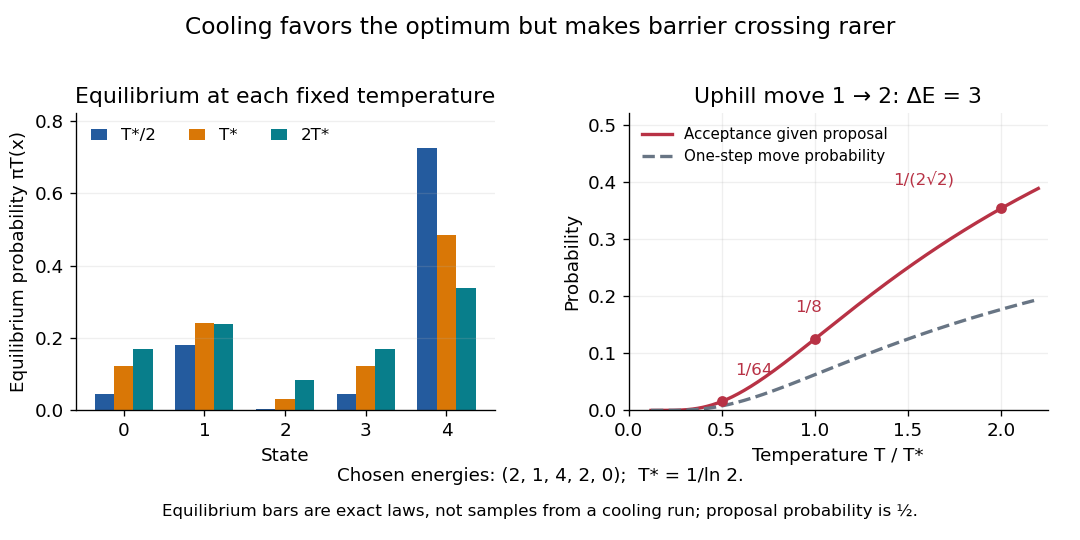
Lower temperature concentrates equilibrium weights while suppressing uphill acceptance
. Exact Boltzmann distributions for the chosen five-state objective function, and the uphill acceptance probability conditional on the proposal . The one-step transition probability is half that acceptance probability. The bars describe equilibrium at each fixed temperature, not the evolving probability distribution during cooling. Details.For any finite , let be the set of global minima and the smallest objective function value. Cancelling from numerator and denominator shows that each nonminimal state's weight tends to zero as , while every state in has equal weight. Therefore tends to the uniform distribution on . This is a statement about a family of equilibrium probability distributions; it does not prove that a cooling Markov chain follows that family.
A cooling schedule for simulated annealing specifies successive effective temperatures and how many proposals to attempt at each. For example, with , using the geometric sequence, can define stages of equal chosen length. Changing changes the transition matrix: if the state probability distribution is , then , which generally differs from . Time spent at one temperature must be compared with its mixing time before equilibrium intuition is justified.
In the five-state barrier example for simulated annealing, fixed gives a finite irreducible Markov chain, so is eventually visited with probability one. That unbounded-time statement gives no fixed finite deadline. Over any finite number of trials starting at , the probability of staying at throughout isEach factor is the rejection probability at . This is an explicit failure event even when every is positive: the best visited objective function value remains , above the global minimum value . More exploratory proposals can help cross a barrier; cooling before those moves occur can preserve a poor local minimum. Successful asymptotic schedules need additional analysis of the allowed moves and barriers.
Historically, Scott Kirkpatrick, Charles Daniel Gelatt Jr. and Mario P. Vecchi connected statistical mechanics with mathematical optimization in 1983. They adapted the Metropolis–Hastings algorithm to cooling searches with symmetric proposals and illustrated computer-design problems.[ref]
Optimization by Simulated Annealing by Scott Kirkpatrick and others. Printed pp. 672–673 and 675: Metropolis procedure, cooling schedule, logic partitioning
Local search repeatedly improves a feasible solution within a specified neighborhood until no improving move remains. For an allocation, neighbors can transfer an item or exchange items between bidders while preserving the partition. A local optimum need not be a global optimum; restarting from several initial solutions can explore different basins.
A local search method that retains one current candidate and repeatedly chooses an improving neighbor of its objective. For a conflict-minimization constraint satisfaction problem, a candidate can assign all variables within their constraint domains while violating some inter-variable constraints; the objective counts those violations. Zero conflicts certifies a solution, while a positive-conflict local minimum need not certify impossibility. Plateaus and local minima motivate sideways moves, randomized choices and restarting. Prescribed variables must remain fixed in every initialization and move.
A repair method for a constraint satisfaction problem: choose a currently conflicted, movable variable, and assign a permitted value minimizing its number of violated constraints with the other variables held fixed. Tie handling can permit sideways moves. For the queens completion problem, keep prescribed rows fixed, select a conflicted unfixed row, and choose a column minimizing attacks. Never interpret failure to improve as proof that no solution exists.
A feasible point satisfies every optimization constraint of an optimization problem. For the budget constraint example, the feasible set is exactlyIt is the line segment from to , a compact set and a convex set. The point is feasible, with product ; has a larger product but violates the budget constraint. Feasibility answers whether a decision is allowed; optimality asks whether any allowed decision is better. The extreme value theorem guarantees that this continuous objective function attains its maximum on this nonempty compact set.
Eliminating gives a one-variable objective function:By completing the square, , with equality exactly at . Alternatively its derivative is , which vanishes at ; the endpoint values are both zero. Completing the square proves global optimality directly, whereas the first-order optimality condition only identifies a candidate. It also quantifies the cost of imbalance: moving to with loses exactly units of product. The arithmetic-geometric mean inequality gives another short certificate: , with equality exactly when .
For a transportation problem with capacity inequalities, feasibility requires nonnegative shipments, row totals no greater than factory capacities and column totals equal to shop demands. Feasibility alone does not prove minimal cost: a matching transportation dual certificate with capacity inequalities provides an optimality proof. The feasible set can be empty, and a finite infimum need not be attained even when the set is nonempty.
The set of all feasible points of an optimization problem. It depends on the optimization constraints and the decision domain; the objective function ranks its members.
Think of three successive questions. Which decisions can be represented in the model? Which satisfy every optimization constraint? Which of those receive the best objective function value? For decisions in a domain , inequalities and equations define the feasible regionThe domain must be contained in the domain of a function for every function being evaluated; choosing integers rather than real numbers as decisions can also change the feasible set. Constraint satisfaction determines membership of . Minimizing an objective function then compares its members by , with optimal value . Changing the scores while keeping and the optimization constraints fixed leaves unchanged, provided the new objective function is defined throughout . These distinctions separate an allowed decision from a best decision.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §4.1.1, printed pp. 127–128: problem domain, feasible set, optimal value and attainment
For inequalities , the active constraints at a feasible point are those holding with equality. Inactive constraints remain strictly satisfied in a sufficiently small neighborhood and do not restrict first-order feasible velocities there. The active gradients determine the linearized tangent cone and appear in the linear independence constraint qualification. At a KKT point, inactive constraints have zero Lagrange multipliers by complementary slackness.
This cone records first-order limiting velocities of feasible points approaching . The defining limits are required to exist, and the point sequences must be feasible. A local minimizer of a differentiable function satisfies for every in the cone: expand to first order and divide by . A tangent direction need not itself generate an exactly feasible straight segment. Linearizing active constraints always gives a containing linearized tangent cone; equality requires a suitable constraint qualification.
For smooth inequalities , the displayed intersection of half-spaces contains the contingent tangent cone. This follows by differentiating each active feasibility inequality along a feasible tangent sequence. The linear independence constraint qualification, and more generally the Mangasarian–Fromovitz constraint qualification, ensure equality in the inequality-only setting. Without a qualification the inclusion can be strict: for , the feasible set is and its tangent cone is , while makes the linearized cone the whole real line.
Take the decision domain and minimize the objective functionEach inequality permits a closed half-space; their intersection is the filled triangle with vertices , and , including its edges. The feasible region is a compact set and a convex set. The point is a feasible point, but its objective function value will not be best. Without the optimization constraints, the unique global minimum is at with value . That point is infeasible because .
The objective function is the squared Euclidean distance from . Its positive level sets are circles centered there. Expanding a circle from that center, the first contact with the feasible region is at , with objective function value . Thus the optimum is the Euclidean projection onto a convex set of the target . Squaring a nonnegative Euclidean distance preserves which point is nearest.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §8.1.1, printed p. 398: squared Euclidean projection onto a polyhedron and half-space projection formula
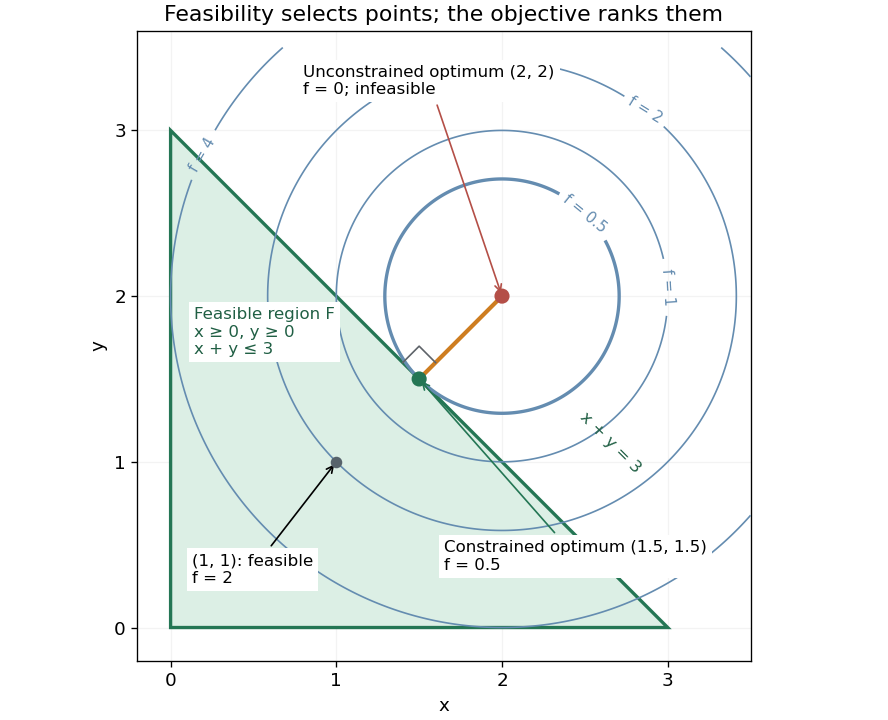
Feasible triangle with a squared-distance objective: the first attainable level set has value 0.5 at (1.5,1.5)
. Details. Here is a direct certificate, without relying on the picture. Put and . The objective function becomesEquality requires and , so the unique optimum is . At this point is an active constraint, while and are strict. An active constraint identifies a tight restriction at a specified point; it alone does not establish optimality. For example, has the same tight sum restriction but objective function value .
For a check using the Karush-Kuhn-Tucker conditions, write the inequalities as , , . Their Lagrange multipliers at the optimum are . The gradient equation isFeasibility, nonnegative Lagrange multipliers and complementary slackness also hold. With this strictly convex function and affine optimization constraints, the Karush-Kuhn-Tucker conditions certify the unique global minimum.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §5.5.3, printed pp. 243–244, equation (5.49) and sufficiency for convex problems
Keep the feasible triangle with a squared-distance objective, but add the equation . An equality requires an exact relation, whereas an inequality allows a range. Here the equality selects a line, and intersecting that line with the original feasible region leaves just the line segment from to :The lower bound comes from ; the upper bound comes from . This is a nonempty closed set even though it has empty interior in the plane. An equality can reduce the dimension of the allowed decisions without making the feasible region empty.
The old optimum violates the added equality. On the surviving line segment, the objective function isThe derivative shows that the unique global minimum is at , giving and value . The nearest point on the entire equality line would be , at with value , but it violates . Both the equality and the original inequalities must hold simultaneously.
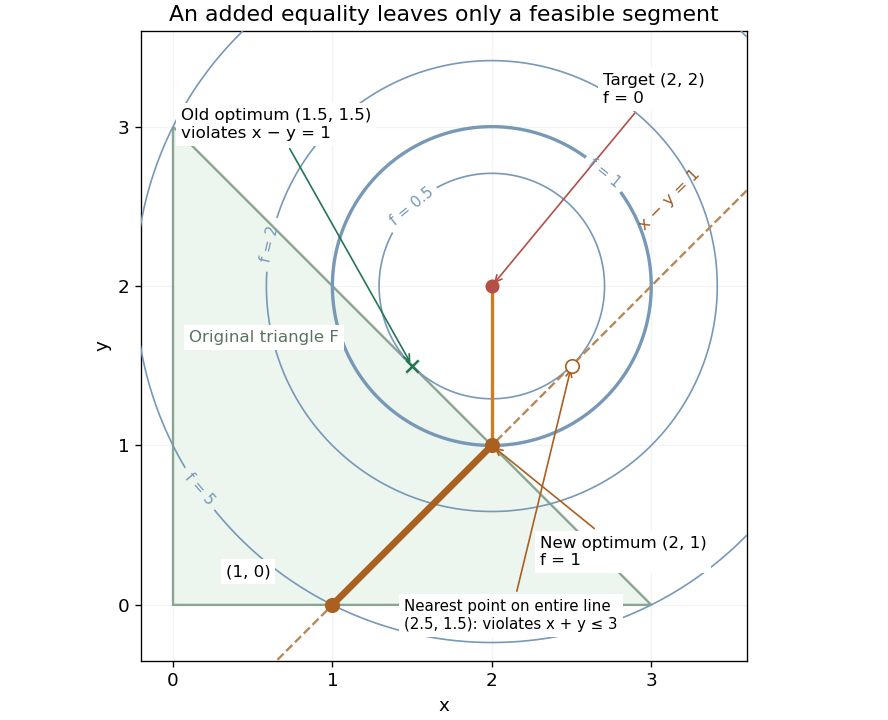
Equality slice of a feasible triangle: the allowed line segment ends at the optimum (2,1), while the nearest point on the entire line is infeasible
. Details. Use and to fix the multiplier sign convention in the optimization Lagrangian ; the Lagrange multipliers of and are again zero. At , Karush-Kuhn-Tucker conditions hold with and :The Lagrange multiplier of an equality has no nonnegativity restriction. For an independent global certificate, completing the square gives . On the feasible set, and , so , with equality exactly at .
Adding an optimization constraint removes possibilities: if it permits a set , the new feasible region is . It can leave unchanged when all its members already satisfy the added restriction. For a fixed objective function, restricting the feasible set cannot lower a minimization problem's infimum. In the equality slice of a feasible triangle, it raises the attained value from to .
Instead add to the feasible triangle with a squared-distance objective. No point can have both and . The resulting feasible set is the empty set, so there is no feasible point and no optimizing decision. Under the extended-value convention for a minimization problem, its infimum is .[ref]
A nonempty feasible set can also lack an optimizing decision. With domain , minimize subject to the strict inequality . The feasible region is an open set. Its infimum is , approached by the feasible points , but is excluded. Every feasible point is beaten by , so no minimum is attained. Replacing by includes the missing optimum. Open feasible regions do not always prevent attainment: minimizing on the same open set attains value at . A useful sufficient condition is instead the extreme value theorem: a continuous objective function on a nonempty compact set attains its minimum.
A nonlinear programming problem minimizes an objective over finitely many real variables subject to constraints, with at least one objective or constraint nonlinear. Parametrizing the pulse amplitudes in quantum optimal control produces such a problem. Gradient descent and related local methods exploit differentiability, but a local stationary point need not be a global optimum without additional convexity or other structure.
A perturbation function encodes a family of objectives and constraints indexed by a perturbation , with the original problem at . Extended-real values encode constraints. Its marginal measures the optimal value's response to perturbation; jointly convex data give convex perturbation duality.
A constraint imposed with a specified probability when data or demands are random. Distributional assumptions can turn it into a deterministic condition on decision variables. The choice of strict versus non-strict event matters when the distribution has atoms, as in the deterministic boundary in an upper-tail chance constraint.
A deterministic demand has probability one of meeting or exceeding its mean. Thus replacing a positive-variance Gaussian chance constraint by its naive zero-variance limit with a non-strict capacity inequality loses the boundary condition. The example , , satisfies for finite , but violates the chance requirement.
For with and , is equivalent to the displayed chance constraint, because the standard normal distribution function is continuous and strictly increasing. The coefficient is a standard normal quantile, which can be negative. If , equality is an atom and the exact condition becomes instead.
For a feasible set and a vector field , a variational inequality asks for satisfying the displayed inequality for every feasible . If is convex and is the gradient of a differentiable convex function, it is the necessary and sufficient first-order condition for minimizing that function. It also describes Wardrop equilibria when no scalar objective has the route-cost vector as its gradient.
Let be a convex set in a real Banach space, and let be a strongly monotone operator. If both satisfy the displayed variational inequality, testing with and respectively and adding yields . Strong monotonicity gives , hence . This proves uniqueness whenever a solution exists.
At an interior local extremum of a differentiable function, its gradient is zero: restricting the function to every line through the point shows that all directional derivatives vanish. This is only a necessary condition in general. For a strictly concave function, an interior stationary point is the unique global maximizer on its convex domain. Constrained or boundary optima instead need conditions adapted to their feasible directions.
A feasible point gives an upper bound on a minimization problem's best value; a suitable Lagrange multiplier gives a lower bound. Lagrangian duality searches for the strongest bound obtainable this way. Matching bounds certify a global minimum.
Let be a nonempty decision domain on which the objective function and the constraint functions are finite. Write the primal problem and its optimization Lagrangian asThe inequality Lagrange multipliers obey ; the equality Lagrange multipliers are unrestricted real numbers. Define the Lagrange dual function and dual optimal value byThe inner infimum keeps , but releases the displayed optimization constraints. It can be , giving an uninformative lower bound. A different domain changes the bound.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §§5.1.1–5.1.3, printed pp. 215–216: domain, Lagrangian, dual function and lower bounds
Here is the entire weak duality argument. For any feasible point and allowable Lagrange multipliers,The first inequality is the definition of an infimum; the second uses and . Taking the infimum over feasible , then the supremum over allowable Lagrange multipliers, gives . No convexity is used.
The Lagrange dual function is a concave function, since each fixed decision makes an affine function of the Lagrange multipliers.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §5.1.2, printed p. 216: pointwise infimum of affine functions
Explicitly, write and choose two points where is finite. For and every ,Taking the infimum over proves the defining concavity inequality. Thus even a difficult primal problem supplies a dual with useful geometry, although evaluating can itself be difficult.For finite optimal values, strong duality means , or zero duality gap. It need not imply dual attainment. For convex optimization, Slater's condition is a sufficient constraint qualification for both when is finite.[ref]
Convex Optimization by Stephen Boyd and Lieven Vandenberghe. §§5.2.2–5.2.3, printed pp. 225–227: gap, strong duality and Slater dual attainment
The Strong Lagrangian property requires an actual finite Lagrange multiplier achieving equality. Convex perturbation duality interprets such a bound as a supporting slope of the perturbed value function.For a maximization problem, every feasible point's finite objective is bounded above by every valid Lagrangian relaxation value. If a sequence of nonnegative multipliers makes those upper bounds tend to minus infinity, no feasible point can exist. Thus a minimization Lagrangian dual problem unbounded below certifies primal infeasibility. Finite dual value alone does not certify primal feasibility.
Choose the one-variable quadratic programWithout the optimization constraint, the global minimum is at . On the feasible set , write with : then . Hence is the unique primal optimizer and .
For any , completing the square in the optimization Lagrangian givesThe inner minimization problem is over all real numbers, so its unique optimizer is . ThereforeThe best lower bound is , attained at . At , the inner optimizer is , which is infeasible for the primal problem; nevertheless is a valid lower bound. At , the inner optimizer is , which is feasible, but is weaker than . Feasibility of an inner optimizer alone does not make the bound exact.
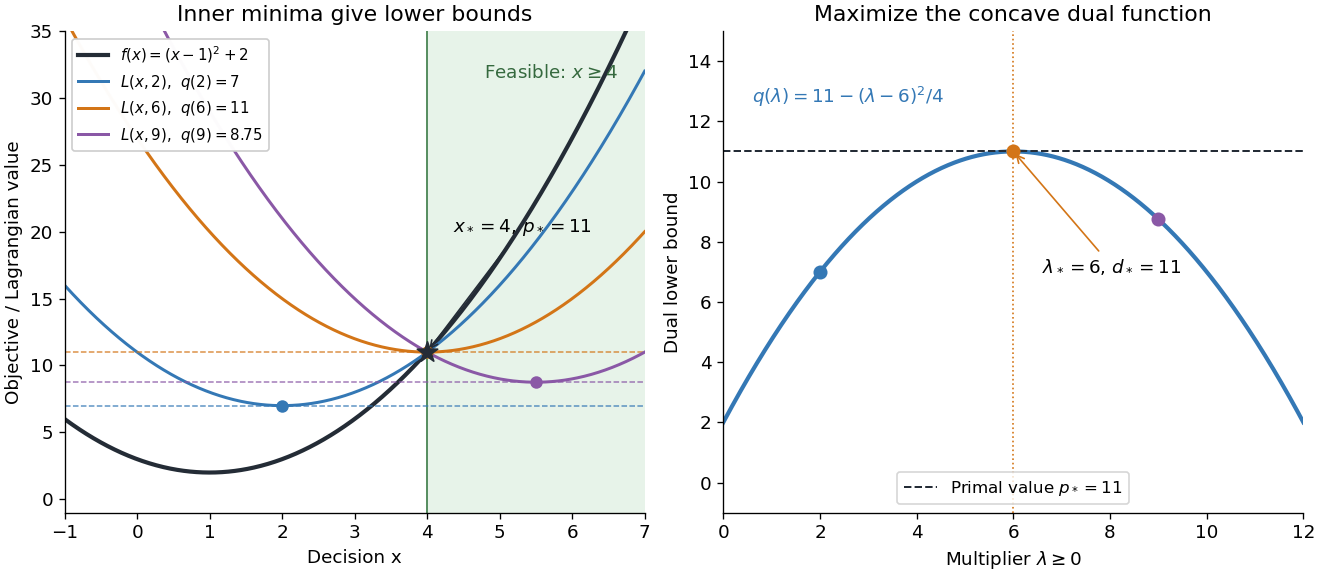
At , the Karush-Kuhn-Tucker conditions reduce toThe last equality is complementary slackness. The strongest certificate is visible without solving another optimization problem: , so every feasible point satisfiesThe same Lagrange multiplier simultaneously makes the inner optimizer feasible and removes the slack between and . This is a convex KKT optimality certificate; also verifies Slater's condition.
The domain in the inner infimum is essential. If one mistakenly keeps when computing , the restricted minimum becomes , whereas the actual Lagrange dual function has value . Constraints deliberately retained in are allowed in a Lagrangian relaxation, but that is a different choice of which restrictions to dualize.
A nonconvex primal problem can have a positive duality gap even when both optima are attained. Choose the finite set , the objective function values , , , and the equality optimization constraint . The only feasible point is , so .
With unrestricted equality Lagrange multiplier , the three possible optimization Lagrangian values and their minimum areThe concave Lagrange dual function has unique maximizer , with . Thus the duality gap is . At the optimal Lagrange multiplier, both inner minimizers and violate the equality; the dual optimum does not recover a primal optimizer.
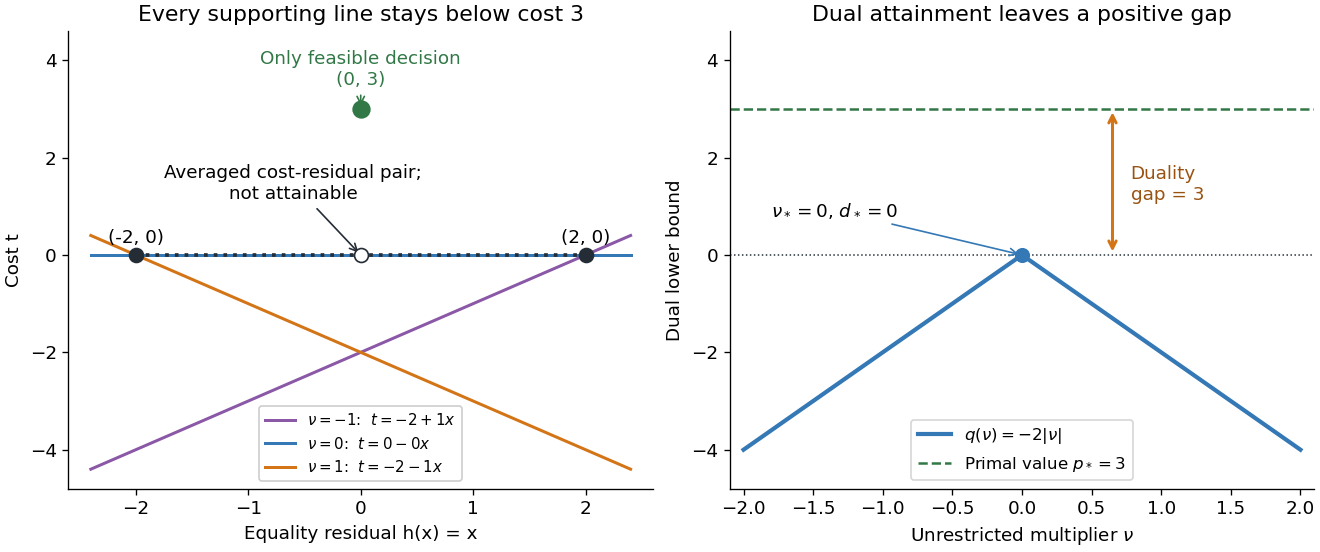
Why can no slope close the gap? Any affine function lying below the two endpoint costs obeys and . Adding gives , so its value at residual zero cannot reach the feasible cost . A convex combination of the endpoint cost-residual pairs with equal weights has residual zero and average cost zero. This averaged pair is unattainable: the actual decision costs . This geometry explains precisely what the dual bounds fail to distinguish. Nonconvexity does not force a positive duality gap: changing only to makes both optimal values zero on the same nonconvex domain.
Consider an objective function that is a quadratic polynomial, with a singular optimization constraint:Its only feasible point is , giving . For , completing the square yieldsEvery finite Lagrange multiplier gives , but as . Thus : strong duality holds, and the primal optimum is attained, yet dual attainment fails. The inner minimizers approach without ever becoming feasible at finite .
Both the objective function and the constraint function are convex functions. However, Slater's condition fails because is impossible. At the optimum, stationarity would require , which no finite Lagrange multiplier satisfies. Compare KKT regularity at a local minimum: a zero gradient of an active constraint can prevent a multiplier certificate. This example has zero duality gap without the Strong Lagrangian property.
For a finite constrained optimum value and optimization Lagrangian , the strong Lagrangian property means that some finite Lagrange multiplier attains the dual lower bound exactly: . It includes dual attainment, but need not include primal attainment. It is equivalent to a non-vertical supporting hyperplane of a value function: a supporting slope gives , hence ; weak duality gives the opposite inequality. Conversely the infimum identity bounds every below by ; taking the infimum over gives the supporting inequality. No convexity assumption is needed for this equivalence.
The original mathematical optimization problem relative to a chosen Lagrangian dual problem. In convex perturbation duality, its objective is and its value is . Strong duality concerns optimal values; primal attainment additionally requires an actual minimizing point.
A maximization problem seeks a feasible point with largest objective value. Its supremum can fail to be attained or be infinite. Negating the objective gives a minimization problem. A global extremum of an optimization Lagrangian can certify a feasible optimum by the Lagrangian sufficiency theorem.
A minimization problem seeks a feasible point with smallest objective value. Its infimum can be finite without being attained, or equal to when unbounded below. Negating the objective converts it to a maximization problem.
A parametric optimization problem has objective or constraints depending on input data. Its optimizer set is a solution map of a parametric optimization problem. Sensitivity analysis asks how this map changes as the data vary.
The solution map sends a data parameter to the set of minimizers of the associated objective, . Existence, uniqueness and local stability are distinct questions. Strong convexity gives uniqueness when a minimizer exists; the Aubin property gives a perturbation bound.
Variational analysis studies optimization, perturbation stability and generalized differentiation through functions, sets and set-valued mappings. Convex analysis is a foundational special case; limiting normal constructions also handle nonconvex geometry.
Normal cones describe generalized supporting directions to sets. For a convex set, the normal condition is for every in the set. For nonconvex sets, the Fréchet normal cone and the limiting normal cone distinguish local regular support from limits of such supports.
The limiting normal cone consists of limits of vectors from the Fréchet normal cone with in . It need not be convex. Including normals from nearby graph pieces is essential to the Mordukhovich criterion.
A vector is a regular normal at when . At an isolated point all vectors satisfy this condition. It is the local first-order supporting cone.
Set-valued analysis studies relations whose output at one input is a set. Solution maps, subdifferentials and generalized normal mappings are important examples. Graph geometry provides definitions of continuity, local stability and differentiation.
A mapping assigns a subset to each . Empty and multiple values are allowed. The graph of a set-valued mapping records the relation as a subset of .
A set-valued mapping is upper hemicontinuous at when every open set containing also contains for all nearby . With values in a fixed compact space, a closed graph of a set-valued mapping implies upper hemicontinuity: a violating sequence has a convergent subsequence of outputs whose limit lies in the limiting value.
Near in a graph, this property requires neighborhoods and a finite such that for all . Nearby solutions can be matched under nearby perturbations with linear displacement control. Single-valued maps reduce to local Lipschitz continuity.
In finite dimensions, if the graph is locally closed at , the Aubin property holds exactly when . Thus no nonzero horizontal vector in the limiting normal cone may occur. The exact local Lipschitz modulus is the outer norm of this coderivative.
The graph is . Local graph normals encode the Mordukhovich coderivative and hence the Aubin property. Graph closedness is a local hypothesis in the sensitivity criterion.
The limiting coderivative is . The negative sign on the output dual is essential. For a smooth single-valued function it gives the transpose Jacobian acting on .
An outcome is Pareto efficient when no feasible alternative weakly improves every agent's utility and strictly improves at least one. For strict preference orders over distinct alternatives, an outcome unanimously ranked below another is inefficient. Onto strategyproof social choice functions on an unrestricted domain are Pareto efficient: rank-raising monotonicity and unanimity rule out selecting a unanimously dominated alternative.
A feasible change weakly increasing every participant's utility and strictly increasing at least one. An assignment is Pareto optimal exactly when no Pareto improvement exists. This comparison permits coordinated changes by several participants; it is different from a profitable unilateral deviation used to test a Nash equilibrium.
Two strictly positive nonproportional utility gradients admit a transfer direction with and . Choose with ; strict Cauchy-Schwarz inequality makes this interval nonempty. Small opposite transfers in this direction strictly improve both differentiable utilities. Absence of such trades therefore forces positive proportionality of all gradients in an unconstrained allocation space.
The Pareto frontier consists of feasible payoff vectors that no other feasible vector weakly improves in every coordinate and strictly improves in at least one. A Nash bargaining solution with positive gains lies on this frontier, because increasing either gain without decreasing the other raises its Nash product.
An approximation algorithm efficiently returns a feasible solution with a proved performance guarantee relative to the optimum. The guarantee must specify whether the problem is a maximization or minimization problem.
For a nonnegative counting quantity , an FPRAS is a randomized algorithm with the displayed guarantee, running in time polynomial in encoded input length, and . The usual constant-success definition is equivalent by independent repetition and a median. This counting notion differs from a deterministic fully polynomial-time approximation scheme for optimization.
For every , such a scheme returns a feasible solution within relative error and runs in time polynomial in the encoded instance size and in . Dependence polynomial only for each fixed epsilon is the weaker polynomial-time approximation-scheme requirement.
Articles were limited to the first 100 out of 1447 total.
Articles by others on the same topic



Mathematical optimization is a branch of mathematics that deals with finding the best solution (or optimal solution) from a set of possible choices. It involves selecting the best element from a set of available alternatives based on certain criteria defined by a mathematical objective function, subject to constraints. Here are some key components of mathematical optimization: 1. **Objective Function**: This is the function that needs to be maximized or minimized.