A real-valued random variable is a measurable function from a probability space to the real numbers with their Borel sigma-algebra. More general targets give random elements. For every Borel set , measurability ensures that is an event, so the question "does the observed value lie in ?" has a defined probability.
The function is fixed; its input outcome is uncertain. This separates what we measure from how the uncertainty is modeled. A probability distribution is the resulting pushforward measure, . A cumulative distribution function, probability mass function, or probability density function describes that measure in an appropriate setting. The random variable and its probability distribution are different objects: the former also retains its relationship to other measurements on the same sample space.
For two independent uniform dice, let record their results and define and . The 36 ordered pairs are equally likely, but the resulting probability mass functions differ:For the sum, count the diagonal of the outcome grid having total . For the maximum, subtract the pairs with both results below from the pairs with both results at most . These examples show how a deterministic function transforms a simple input probability distribution into a nonuniform output one.
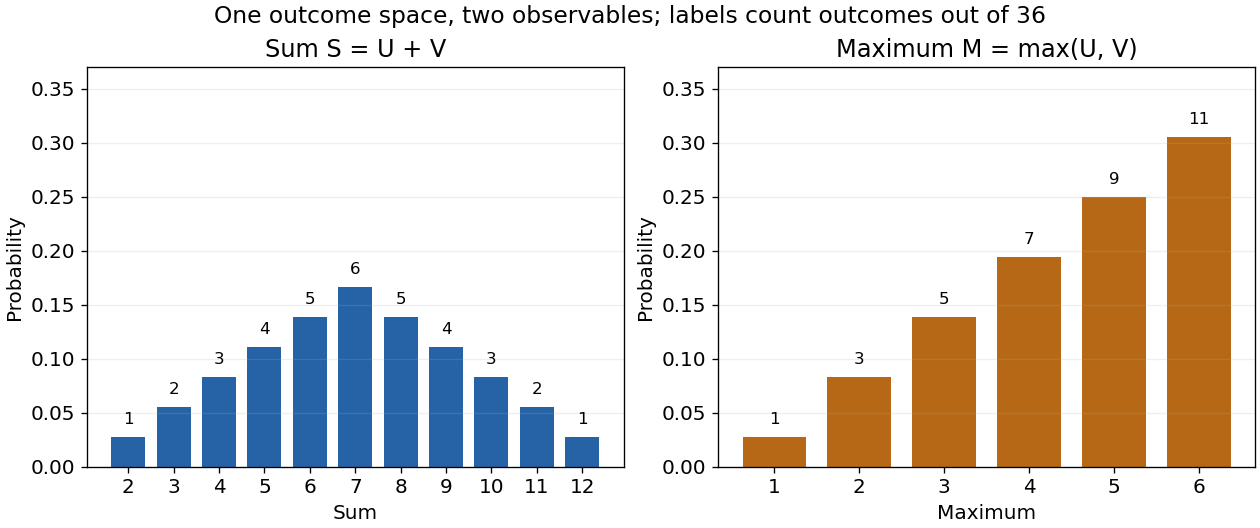

The corresponding expected values are and . The first follows immediately from linearity of expectation; the second follows from . Neither number must be an attainable result. An expected value describes an average under the probability measure, not a prediction that the next observation will equal it.
The distinction between a random variable and its probability distribution matters for dependence. and have the same discrete uniform distribution and are independent random variables. and a second copy of also have that same marginal probability distribution, but they always agree. Their joint probability distribution is concentrated on the diagonal; the marginals alone cannot say which relationship holds. This is why a model for several measurements must specify their joint law or an appropriate independence assumption.
Indicator random variables turn events into numbers: equals one on and zero elsewhere, and . This connects event counting with expected value and variance, and lets tools for random variables answer questions about probabilities. More complicated functions of observations can describe totals, waiting times, or estimation errors using the same framework.
A random variable whose cumulative distribution function is continuous, equivalently whose probability distribution assigns zero probability to every singleton. In elementary applications, one usually additionally assumes a probability density function; that stronger property means its law is an absolutely continuous probability distribution. A continuous cumulative distribution function alone need not admit a probability density function.
A random variable with a probability density function , so its cumulative distribution function is . Equivalently, its law is an absolutely continuous probability distribution. In particular, the probability of every singleton is zero.
A constant random variable takes the same fixed real number at every outcome in its sample space. Its probability distribution puts mass one at . An almost surely constant random variable may differ on an event of probability zero, while having the same probability distribution.
A random element is a measurable function from a probability space to a measurable space . Its law is the pushforward measure for . Real-valued random variables and vector-valued random variables are examples; a stochastic sample path can also be a random element when its path-space sigma-algebra is specified. For a Polish space , the usual choice is its Borel sigma-algebra. A large deviation principle concerns the laws of a family of such random elements.
Two random variables are statistically dependent when their joint probability distribution differs from the product of their marginal probability distributions. Equivalently, some events determined by the two variables violate the product rule that defines independence. Nonzero covariance implies statistical dependence when the moments exist, but zero covariance does not in general imply independence.
A random sum has a random number of summands, usually with a nonnegative integer-valued random variable. The empty sum is zero. The dependence between and the summands must be stated; independent summands do not by themselves imply independence from .
Retain each of objects independently with probability , independently of the nonnegative integer-valued random variable . The retained count has the displayed conditional binomial distribution. The probability generating function of an independent random sum gives . If has finite variance, the law of total expectation and law of total variance giveThe first term is the average conditional variance of the independent retention decisions; the second is the variance in their conditional expected value.
Use the zero-based geometric distribution, with for and . After binomial thinning with retention probability , the retained count is again zero-based geometrically distributed, with the displayed success probability. Indeed, writing , its probability generating function isFor this includes the degenerate success parameter and retained count zero.
For independent identically distributed summands, independent also of the count , conditioning on gives . The law of total expectation gives the composition of the count's probability generating function with the summand's moment-generating function. This identity is valid as an extended nonnegative expectation; finiteness near zero requires additional exponential-integrability assumptions.
A random variable is discrete when some finite or countable set has . Its probability mass function is ; these nonnegative masses sum to one. An event determined by the value has probability . Values outside may still occur on a zero-probability event without changing this definition.
Countable support need not consist of integers: a random variable constantly equal to is discrete. Integer-indexed tail-sum formulas therefore require a separate integer-valued hypothesis. For the dice sum in random variable, the expected value is and the variance is ; the same answer follows by adding the variances of its independent summands.
A random variable whose values lie in the integers with probability one. Its probability mass function is for . If it is nonnegative, its probability generating function is wherever this expectation is finite.
A random vector is a random variable whose values are vectors or, equivalently, an ordered tuple of scalar random variables on one probability space.
The mean vector of an integrable random vector is its coordinatewise expected value: . Integrability of every coordinate makes this a finite vector.
For an isotropic three-dimensional random vector, its direction is uniform on the sphere and independent of its length. Projection onto a fixed plane gives . The solid-angle averages are and . This proves the two formulas whenever the corresponding moments exist. The mean-length factor and root-mean-square factor are different. Both are independent of the radial distribution, so projection preserves a polymer's chain-length scaling exponent.
For discrete random variables , their joint probability mass function assigns a probability to each possible ordered pair. Its entries are nonnegative and sum to one. Marginalization gives the probability mass functions and . In a table with rows indexed by and columns by , these are the row and column totals. The joint probability distribution records how the coordinates occur together, while the marginal distributions describe each separately.
A Hilbert-space-valued random variable is a measurable map into a Hilbert space. It is square-integrable when , in which case its mean is defined by the Bochner integral.
For a square-integrable centered Hilbert-space-valued random variable , its covariance operator isIt is a positive self-adjoint trace-class operator, and .
When a covariance operator on a function space is an integral operator, its covariance kernel satisfies . For a centered process, whenever point evaluation is meaningful.
The covariance kernel of standard Brownian motion on is . Its integral operator has eigenfunctions and eigenvalues .
For a complete orthonormal basis of , the Parseval identity for a Hilbertian basis identifies the sum of the feature products with . The Cauchy-Schwarz inequality gives absolute convergence.
The covariance kernel of a standard Brownian bridge on is . Its integral operator has eigenfunctions and eigenvalues for .
For observations and a chosen center , the empirical covariance operator is . Its expectation equals the population covariance plus the rank-one operator formed from the centering error.
A pooled covariance operator averages the within-group empirical covariance operators from several samples that are assumed to share one population covariance. Centering within each group prevents differences between group means from contaminating the covariance estimate.
A random element of a Hilbert space is Gaussian when every continuous linear functional of has a normal distribution. Its mean and covariance operator determine its distribution.
Random variables are independent when, for every choice of Borel sets ,The requirement covers all these events, not only one selected combination of values. Equivalently, the generated sigma-algebras are independent sigma-algebras, or the joint probability distribution is the product measure of the marginal distributions. For an infinite family, the same condition must hold for every finite subfamily. For random elements, replace Borel sets by measurable sets in their specified target spaces.
For discrete random variables, checking every entry of the joint probability mass function is enough:Summing this identity over the desired sets proves the event formulation. For general real-valued random variables, checking point probabilities alone can say nothing: a pair with no point masses has even when . The all-set definition avoids that trap. See Gautam Iyer, Conditional Probability and Independence, definitions 12, 16 and 18 and proposition 19, with the continuous case treated in his [ref].
For a concrete comparison, let be independent fair bits: each has a Bernoulli distribution with parameter . Their joint probability mass function, with rows and columns , isAll four entries equal the product of the corresponding row and column totals, . For example, : learning one bit leaves the other one's probability distribution unchanged.
Now keep a fair but set . The same marginal distributions give the same product table, yet the actual joint probability mass function isHere differs from , and . Thus matching marginal distributions does not establish independence. Grinstead and Snell formulate the discrete product criterion in Introduction to Probability, section 4.1, definition 4.4, printed page 143.
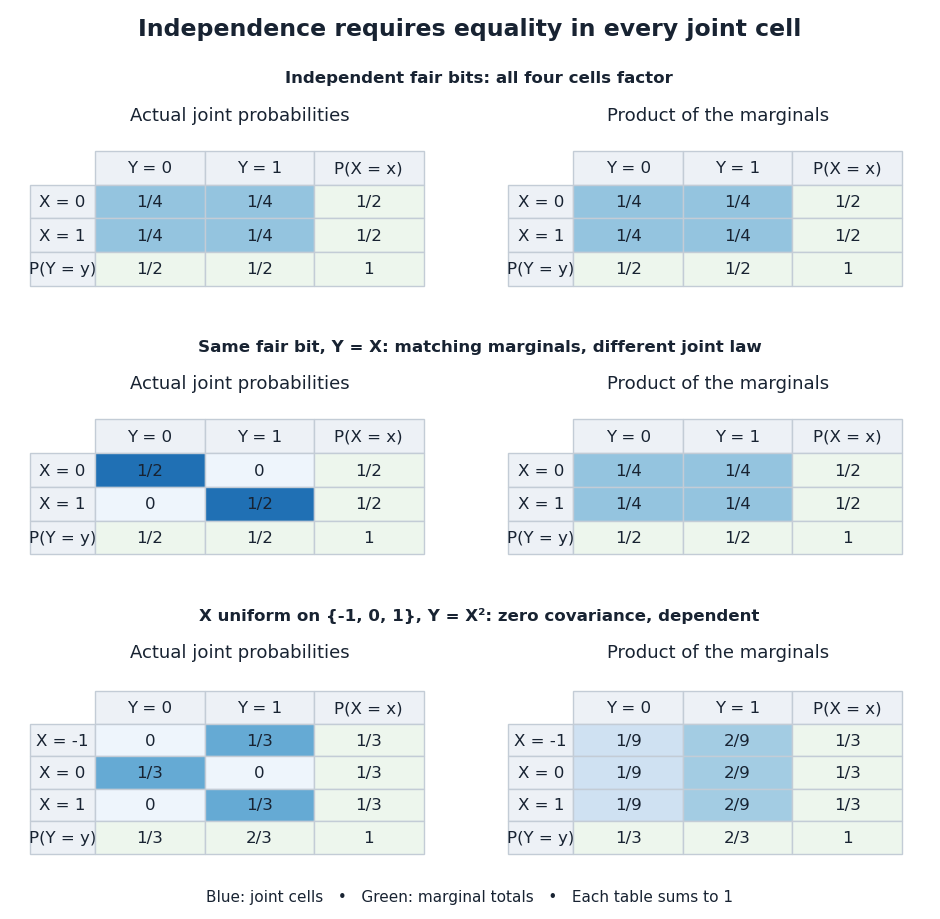
Independence compares every joint probability with the product of the marginals
. Each row compares an actual joint probability mass function with its product of marginal distributions. Marginal totals are shown at the right and bottom of every table; each whole table sums to one. The last example has zero covariance but a visibly different joint table. Details.
Independence is stronger than zero covariance. For square-integrable independent random variables, , so they are uncorrelated random variables. The converse fails: take with a discrete uniform distribution on and . Direct calculation givesNevertheless, is a nonconstant function determined by . The event is exactly the event , so , whereas . The positive and negative contributions to the covariance cancel without erasing the statistical dependence.
The usefulness of independence is that a large joint probability distribution can be assembled from small pieces. For fair independent bits, each of the patterns has probability . Products also simplify expected values, and vanishing cross covariances simplify the variance of a sum. Separate measurable functions of independent random variables remain independent: each output event is already an input event, so the defining product rule still applies. These are consequences of a model's independence assumption; whether the assumption describes actual observations is a question for statistical inference.
Random variables are pairwise independent when every two distinct members are independent random variables. Each pair's joint probability distribution must factor for all its events; examining only a pair's covariance is insufficient. Full independence implies pairwise independence by taking the other sets in the definition to be the whole target spaces. The reverse implication fails once there are three or more variables.
Pairwise independence is enough to add variances: for a finite family of square-integrable pairwise independent random variables,because all cross covariances vanish in the variance of a sum. Thus pairwise independence can support calculations about the size of fluctuations while failing to determine the full joint probability distribution. The following example makes that distinction visible.
Let be independent fair bits, and let be their exclusive or: precisely when . The four possible triples are , each with probability . Each coordinate is a fair bit. Writing out all eight patterns givesEvery pair has all four cells with probability :For , the four allowed triples project to ; for they project to . Each projection lists each pair exactly once, proving pairwise independence. But differs from the product , so the three are not independent random variables. Indeed, any two determine the third. A single coordinate reveals nothing about another, while two coordinates together reveal it completely.
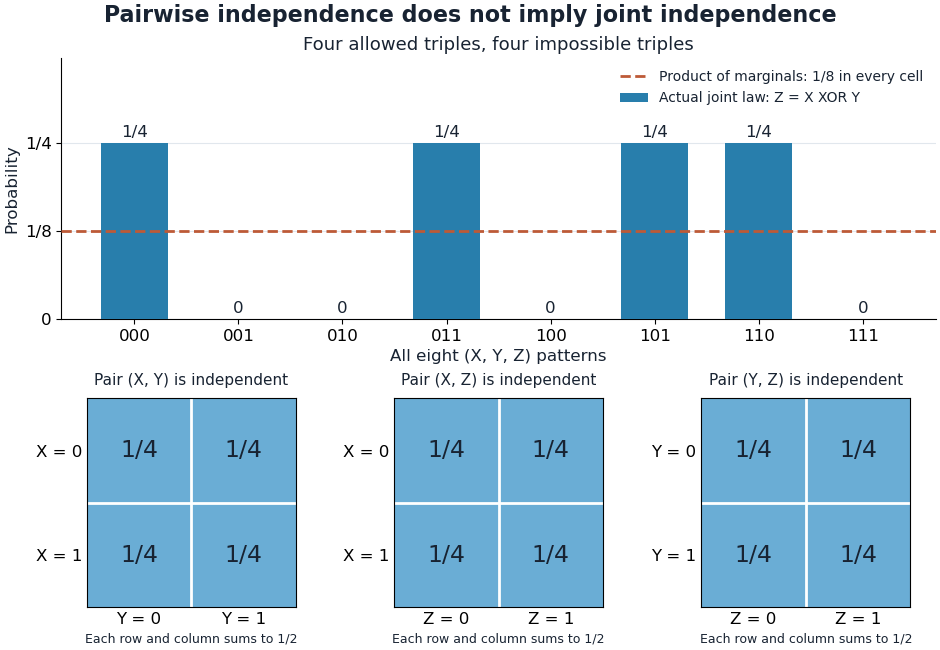
The XOR example hides joint dependence from every pairwise probability table
. The bars show all eight triple patterns against the reference for three independent fair bits. Below, all three pairwise joint probability mass functions have four equal cells of . Details.
The exclusive or example is the complementary-bit version of the two-toss exercise in Grinstead and Snell, Introduction to Probability, section 4.1, exercise 7, printed page 151. It is a compact reason to check the full product rule whenever a calculation uses three-way or higher events.
Random variables and are conditionally independent given when, for every pair of Borel sets , the following identity holds almost surely:Here conditional probabilities are conditional expectations of the corresponding indicator random variables given the sigma-algebra generated by . This defines the condition even when . In terms of regular conditional distributions, the conditional joint law is the product of the conditional marginal distributions for almost every conditioning value.
For discrete random variables, at every with , the condition becomesWhere , this is equivalent to . Once is known, observing provides no further information about .[ref]
Information Theory I — Scene Setting and Statistical Applications (Lecture 9). Information Theory I — Scene Setting and Statistical Applications, Lecture 9, section Conditional independence and conditional mutual information: conditional factorization and predictive irrelevance
For a worked example, suppose a latent variable chooses between two environments with . Given , take to be independent and identically distributed with a Bernoulli distribution of parameter , where and . Think of two separate trials run under the same quiet or active environment. Their conditional joint probability mass functions, with rows and columns , areEach is exactly the product of its own conditional marginal distributions: for , and for . Thus are conditionally independent given .
If the environment is unobserved, the law of total probability averages the two tables:Both unconditional marginal distributions are fair, but . The law of total expectation gives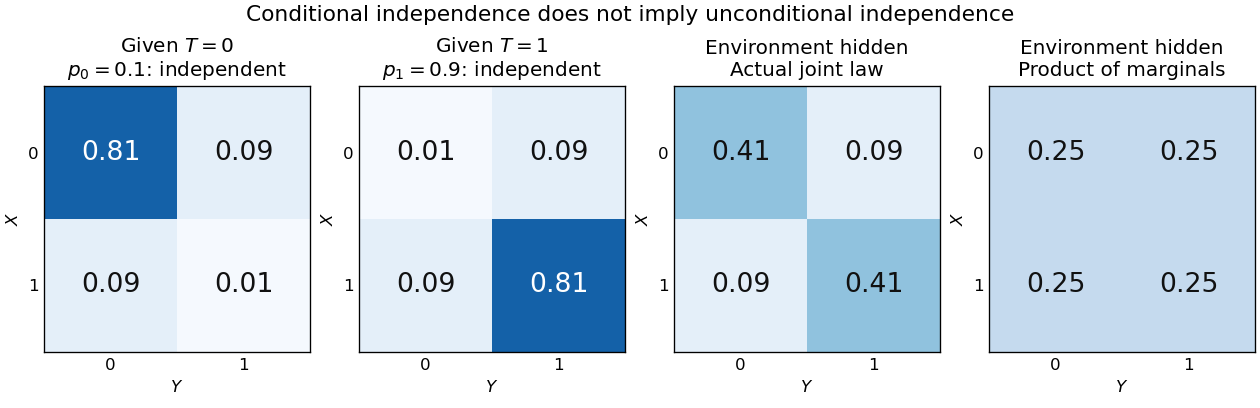
Figure 1.
An unobserved shared environment creates statistical dependence between conditionally independent trials
. The first two tables show independent Bernoulli trials at conditional success probabilities and . Averaging them with equal weights gives the third table. The fourth table is the product of the resulting unconditional marginal distributions, which differs from the actual joint table. These are stipulated model probabilities, not observed frequencies. Details.
Observing makes the active environment more plausible, so it raises to . Knowing the actual environment removes this source of statistical dependence. The covariance induced by a shared latent variable lemma explains the calculation without listing all the outcomes.
This is why conditional independence is useful in statistical modelling: a model can multiply simple conditional laws and then average over a shared latent variable. The resulting observations can remain statistically dependent. Conditional independence graphs organize such information relations; their interpretation as causes requires additional assumptions from causal inference. Conditioning describes the information available to an observer. It does not, by itself, describe what would happen if an experimenter changed a variable.
Return to pairwise independence does not imply joint independence, where are independent fair bits and is their exclusive or. Given , only and remain, each with conditional probability . Given , only and remain, again each with conditional probability . Consequently,The conditional marginal distributions are still fair, so their product has four entries in either case. The actual tables differ: given , and given . Thus unconditional independence need not survive conditioning. Observing whether two bits agree restricts their possible combinations; no physical interaction between the original trials is required to produce that information constraint.
Let be independent random variables, each with a Bernoulli distribution of parameter , and put . Unconditionally, the four ordered pairs each have probability . On the event , only and remain, each with conditional probability . ThusKnowing that exactly one trial succeeded makes observing one outcome informative about the other. This violates conditional independence given , even though the original random variables are independent. Given or , both variables are constant random variables and are conditionally independent there; that does not repair the failure at , an event of positive probability.
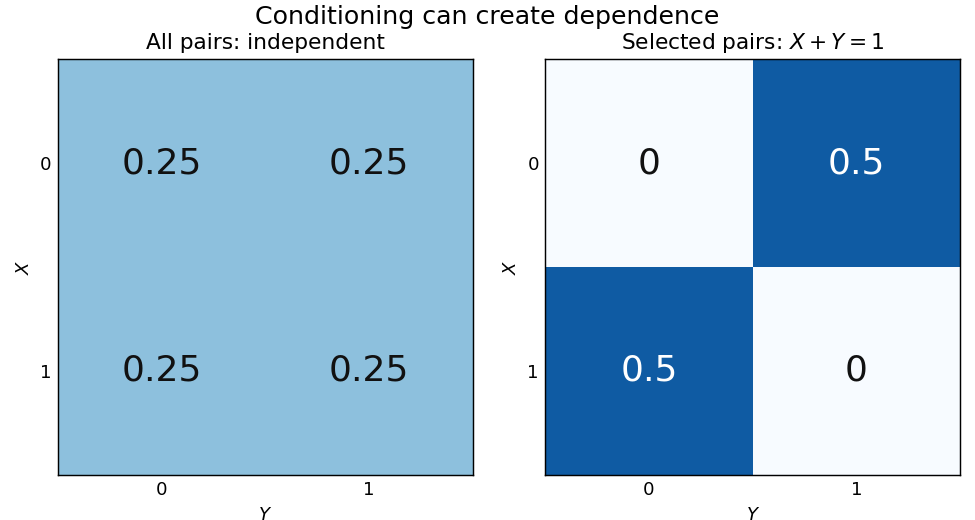
Selecting pairs with exactly one success makes independent trials dependent
. Left: four equally probable outcomes of independent fair Bernoulli trials. The selection retains exactly two pairs. Right: their conditional joint table has zero mass on the diagonal and off it. Within this selected model the conditional covariance is ; the two conditional marginal distributions remain fair. Details.
The conditional covariance here is . Both conditional variances are , so the conditional correlation coefficient is : within the selected group, . These conclusions follow from restricting a finite sample space, without positing any physical interaction between the trials.
This example and the shared-environment example establish both logical directions: independent random variables need not be conditionally independent, and conditionally independent variables need not be independent. When is represented as the joint result of two inputs in a causal directed acyclic graph, conditioning on it has the collider structure associated with collider bias. A probability calculation by itself establishes a dependence relation, not a physical causal mechanism or an intervention.
For a random vector indexed by vertices , its conditional independence graph is the undirected graph with absent exactly when . In a nonsingular multivariate normal distribution, its edges are the nonzero off-diagonal entries of the precision matrix.
Fit the conditional law of each variable given all others and use its predictor support to estimate its neighbours. In a Gaussian graphical model, this is linear regression with coefficients given by conditional regression coefficients from a Gaussian precision matrix. The Nodewise Lasso supplies sparse fits; the OR rule for nodewise graph selection and AND rule for nodewise graph selection combine possibly disagreeing directional supports into an undirected graph.
Minimizing the squared error over each free regression intercept gives the displayed formula. Substitution replaces all data columns by centred columns. The regression intercept is generally not the marginal mean of the response when predictor means are nonzero; the distinction matters in conditional regression coefficients from a Gaussian precision matrix.
The intersection rule retains an edge only when both directions of nodewise regression select it. It is more conservative than the OR rule for nodewise graph selection; the distinction matters because separate finite-sample fits can disagree.
The union rule retains an edge whenever either of the two nodewise regression fits selects the other variable. It is more inclusive than the AND rule for nodewise graph selection and makes an undirected edge decision from potentially asymmetric estimated neighbourhoods.
For a nondegenerate multivariate normal distribution, the conditional independence graph is read from zeros in its precision matrix. Conditional independence of two components given all others is equivalent to a zero cross term in their conditional Gaussian quadratic density, hence to . It does not generally correspond to a zero in the covariance matrix.
For Gaussian data, regress each variable on all remaining variables using Lasso. Nonzero coefficients estimate its neighbours in the conditional independence graph. Symmetrize the separate regressions using either the union or the intersection of their selected directed neighbourhoods.
If D-separation and conditional independence are equivalent for a Directed acyclic graph, its moral graph is its conditional independence graph. After conditioning on all other vertices, an active path can only be a direct edge or a two-edge collider through a common child: two adjacent interior vertices cannot both be colliders. These are exactly the moral edges.
The contraction axiom says thatIt follows directly by multiplying the corresponding conditional-density factorizations.
The decomposition axiom says that implies both and . It follows by marginalizing the joint conditional distribution over the discarded variable.
To test , regress and on and average the products of their residuals. Dividing the scaled average by its empirical second moment produces the generalized covariance measure statistic. Small mean-square nuisance-regression errors and a product-rate condition make it asymptotically pivotal.
If the numerator of the generalized covariance measure statistic obeys a central limit theorem with variance and its empirical residual-product second moment converges in probability to the same positive quantity, the Slutsky theorem makes the studentized statistic converge in distribution to .
If are independent centered square-integrable random variables in a Hilbert space, then for , and hence
An independent and identically distributed sequence combines two conditions: its members are independent random variables, and every member has the same probability distribution. For a finite sequence with common law , this means that for all measurable sets ,For an infinite sequence, require this condition for every finite collection of distinct indices. Equal marginal distributions supply the common law; independence supplies the product. Neither condition supplies the other. Grinstead and Snell call the combination an independent trials process.[ref]
Introduction to Probability by Charles M. Grinstead and J. Laurie Snell. §4.1, Definitions 4.4–4.5, printed pp. 143–144: mutual independence and a common distribution
Choose a Bernoulli distribution with success probability . Four independent draws produce all sixteen binary patterns with probability each. If instead for one fair Bernoulli random variable , every member still has that same Bernoulli distribution, but only patterns
0000 and 1111 occur. Conversely, independently drawn Bernoulli random variables with success probabilities have a product joint probability distribution but unequal marginal distributions.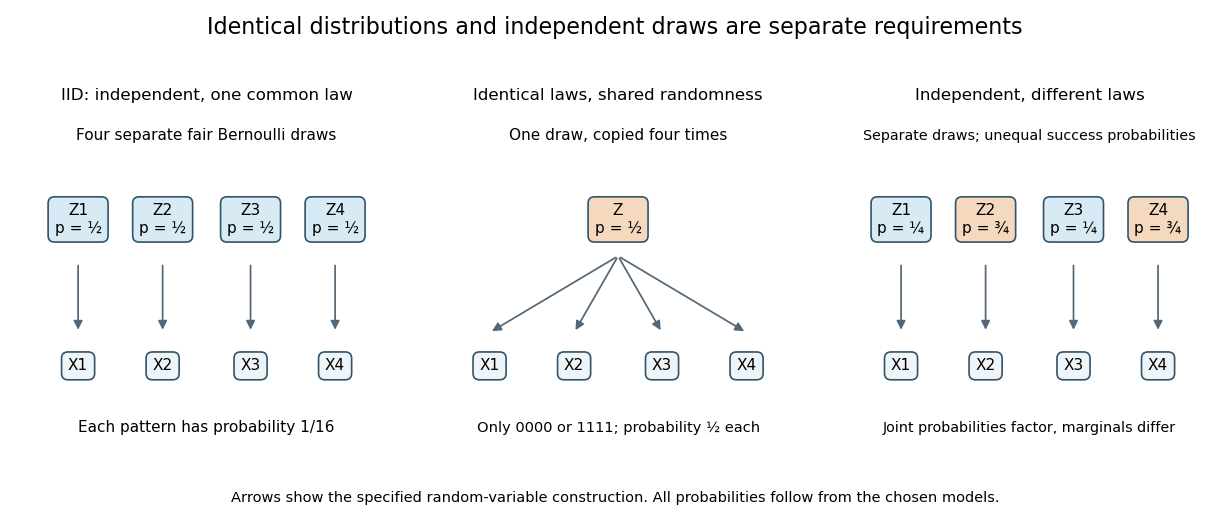
IID sampling combines a common distribution with separate independent draws
. Original constructions of four Bernoulli random variables. Separate arrows in the first and third panels represent explicitly independent source draws; the middle panel copies one shared draw. Dependence and marginal laws are specified by the chosen models. Details.
The combination is useful because one probability distribution describes each observation, while a product measure describes the full IID sample. In particular, an IID sample of finite-variance, real-valued observations has a predictable sample mean: its expected value stays at the population expected value, while its variance of a sample mean decreases as . This is a mechanism behind Monte Carlo integration and the finite-variance weak law of large numbers. Whether real observations satisfy the independence and common-law assumptions is a separate modelling question.
For independent and identically distributed Bernoulli random variables with success probability , the sum has a binomial distribution. Every length- pattern with successes has probability , and the binomial coefficient counts its possible success positions. ThereforeThe usual endpoint convention includes and as deterministic cases. For and , the five probability masses are divided by . The sample mean takes values , with variance and standard deviation . At , its variance is and its standard deviation is .
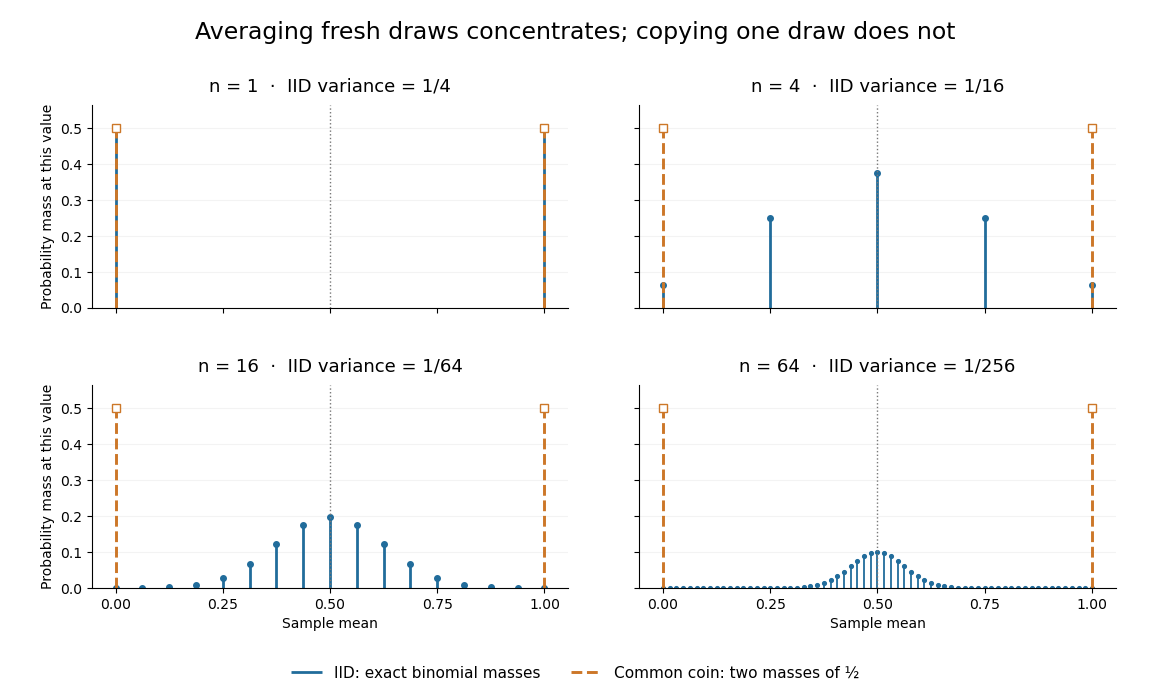
Exact sample-mean distributions distinguish fresh IID draws from a copied common coin
. Original exact binomial distribution probabilities for sample sizes . Blue marks give the mass at each possible mean under independent fair draws. Orange marks give the masses for the same fair draw copied times: at zero and at one for every . These are discrete probability masses, not density values or measured histograms. Details.
In the copied-coin model, for every , so the sample mean is exactly , however large is. Its expected value is and its variance is , matching each observation's marginal variance. The off-diagonal covariances in the variance of a sum explain the difference:For an IID sample, those off-diagonal terms are zero. Repeating the same random input therefore does not create the reduction in fluctuations obtained from fresh independent draws. The general common-plus-individual structure is described by compound-symmetry covariance.
The IID sample property places no integrability condition on its common probability distribution. An IID sample with the standard Cauchy distribution has no finite expected value or variance. The Cauchy sample mean stability result shows that its averages keep that same Cauchy distribution for every sample size. Thus increasing need not concentrate an IID sample around a population mean that does not exist. The finite-variance bound below applies only when its hypotheses hold.
Draw two different labels uniformly from using sampling without replacement. Each position has a uniform distribution on a finite set, but . Two independent random variables with those same marginal distributions would match with probability . Equal marginal laws therefore do not make this sample an IID sample. Mark some of those four labels as successes. Their count in the two draws has a hypergeometric distribution; independent Bernoulli trials with a common success probability give a binomial distribution.
A measurable function applied to a random variable defines a new random variable . Its probability distribution is the pushforward measure under .
Articles by others on the same topic
There are currently no matching articles.