Number theory studies integers, their divisibility, and the patterns created by prime numbers. Its questions often have short statements but rigid answers: which integers divide a given one, when does an equation have integer solutions, and when can arithmetic with congruence classes be reversed? The Euclidean algorithm and modular multiplicative inverses connect these questions through explicit calculations.
For example, and . Their shared prime factors give greatest common divisor . The Euclidean algorithm reaches that answer without finding either complete prime factorization. It also produces , an instance of Bézout's identity. This relation certifies every common divisor at once and solves an associated linear Diophantine equation.
Modular arithmetic retains only remainders, but the lost information can be surprisingly controlled. Multiplication by modulo is a permutation of all residue classes, because has modular inverse . Multiplication by modulo collapses fifteen residue classes to three. Thus an apparently small change in the modulus changes whether a calculation can be reversed. The Chinese remainder theorem explains another kind of compression: remainders modulo coprime integers can be combined into one remainder modulo their product.
Simple restrictions help reveal the structure without telling the whole story. Every prime number greater than three is congruent to or modulo : the other four residue classes force divisibility by or . The converse fails because and lie in those classes but are composite numbers. Necessary conditions are useful filters, not substitutes for primality testing.
The subject's appeal lies partly in this tension: prime factorization gives a clean description of every positive integer, while identifying factors and predicting their distribution lead to substantial further questions. Analytic number theory uses tools from analysis to study global patterns, and algebraic number theory extends arithmetic into number fields. Applications include cryptography and error-correcting codes; MIT's discrete applied mathematics course develops modular structures for both purposes. [ref]
https://ocw.mit.edu/courses/18-200-principles-of-discrete-applied-mathematics-spring-2024/mit18_200_s24_lec15.pdf. Ankur Moitra, MIT 18.200, Modular Arithmetic and Elementary Algebra, 2024, introduction
Euclid's Elements already gives a greatest-common-measure construction in Book VII, Proposition 2, and the argument that a finite list cannot exhaust the prime numbers in Book IX, Proposition 20. These are documented ancient treatments, rather than evidence that all of number theory began with one author. [ref]
https://mathcs.clarku.edu/~djoyce/java/elements/bookVII/propVII2.html. Euclid, Elements VII.2, translated text hosted by David Joyce
[ref]https://mathcs.clarku.edu/~djoyce/java/elements/bookIX/propIX20.html. Euclid, Elements IX.20, translated text hosted by David Joyce
Geometry of numbers uses the geometry of lattices in real vector spaces to study arithmetic questions. A full-rank lattice has covolume , the volume of a fundamental parallelotope. Geometric size can force a region to contain a nonzero lattice point.
Minkowski convex body theorem states that a centrally symmetric convex measurable body of volume greater than contains a nonzero point of . The symmetry and convexity let two lattice-congruent points in produce a difference in .
For , a centered disk of radius has area , so the theorem guarantees a nonzero integer point when . This sufficient bound need not be the exact first radius where a point occurs: the unit coordinate vectors already have length one. Such estimates connect shortest-vector problems with ideal classes, Diophantine approximation and arithmetic volume bounds.
Computational number theory studies algorithms for arithmetic objects, including integers, finite fields, polynomials and algebraic number fields. Typical tasks are greatest-common-divisor computation, modular inversion, primality testing and integer factorization. The output may be an answer together with a certificate that can be checked independently.
For example, the extended Euclidean algorithm finds , certifying that the inverse of seven modulo twenty-six is fifteen. Modular exponentiation by repeated squaring computes with a number of modular multiplications proportional to the bit length of , instead of multiplying copies.
Input size is measured in bits, not by the numerical magnitude alone. An integer near has roughly bits, so an algorithm using time proportional to that integer can be exponential in its input length. Primality testing and complete factorization are distinct tasks; solving the former does not automatically supply the latter.
Transcendental number theory studies numbers that satisfy no nonzero polynomial equation with integer coefficients, and stronger independence properties among numbers and special-function values. The distinction is algebraic: is irrational but algebraic because it satisfies .
A useful example is the Liouville constant . Truncating after terms gives a rational with andFor any fixed algebraic degree, these approximations eventually contradict the rational-approximation lower bound in Liouville approximation theorem. Thus exceptionally good approximation can certify transcendence.
Other results, such as the six exponentials theorem, constrain collections of exponential values using linear independence of their inputs. Proving each number irrational is weaker than proving it transcendental, and proving separate transcendence is weaker than proving algebraic independence of a collection.
The Liouville constant is the real numberIts decimal ones occur at factorial positions . The growing gaps make exceptionally well approximated by rational numbers. If is the truncation after terms, with , thenThe strict lower bound shows the truncations never equal .
For any fixed degree of an algebraic number , these errors eventually fall below every positive constant times . The Liouville approximation theorem forbids this for an irrational algebraic number of degree . A rational number is also impossible, since distinct fractions satisfy . Hence is a transcendental number. The construction turns deliberately sparse decimal digits into a proof of transcendence.
The six exponentials theorem states that if are complex numbers linearly independent over , and are also linearly independent over , then at least one of the six numbersis a transcendental number. It does not require the inputs themselves to be algebraic. Both independence hypotheses are essential.[ref]
Linear Independence of Logarithms of Algebraic Numbers by Michel Waldschmidt. Chapter1, Theorem1.7
For an application, suppose a real makes all algebraic. If were irrational, choose and . The logarithms are rationally independent: clearing denominators and exponentiating would otherwise give a nontrivial integer relation , contradicting unique prime factorization. All six outputs would be algebraic, a contradiction. Hence must be rational.
With only two independent , the analogous assertion is the four exponentials conjecture, not this theorem.
A sum of two squares representation of a nonnegative integer is an equality with integers . For example, has two representations even before changing signs or interchanging the two terms.
Counting conventions matter. If ordered pairs and signs are distinguished, the representation generates eight pairs, whereas generates only four and only one. Every perfect square is zero or one modulo four, so an integer congruent to three modulo four is impossible. That quick obstruction is insufficient by itself: also has no representation. The exact prime factorization criterion is the sum of two squares theorem.
The four exponentials conjecture asserts that if are complex numbers linearly independent over , and are likewise linearly independent over , then at least one of the four numbers is a transcendental number.
Both independence hypotheses are essential to the statement. It is a problem in transcendental number theory, asking how a two-by-two array of products constrains exponentiation. The analogous statement with two independent and three independent is the six exponentials theorem; that stronger supply of inputs is known to force at least one transcendental output. The four-number assertion is a conjecture, not a consequence of checking individual exponentials.
A pronic number is for a nonnegative integer , the product of two consecutive integers. The sequence begins . Arranging points in a rectangle with side lengths and explains the product, while shows that each is twice a triangular number.
There is an exact recognition test: a nonnegative integer is a pronic number if and only if is an perfect square. Indeed, ; conversely an integer square equal to has an odd positive square root , recovering . For , the test gives and .
A cube-full number is a positive integer whose every occurring prime factor has prime exponent at least three. Equivalently, if a prime number divides , then divides . Examples are , and . The number fails because its factor three occurs only twice. The number is included, since it has no prime factors violating the condition.
Every cube-full number is a powerful number, but the converse fails: is powerful without being cube-full. Being cube-full also differs from being a perfect cube; the exponents need only be at least three, rather than multiples of three. Thus is cube-full but not a perfect cube.
For , let count the integer quadruples with , counting order, signs, and zeros. Jacobi's four-square theorem givesThe right side is positive, so this also implies that every positive integer is a sum of four squares.
For , the formula gives eight representations: choose the position of . For , it gives , matching the six choices of two nonzero positions and four sign choices. Specifying the counting convention matters: unordered nonnegative representations have a different count.
The base-ten Kaprekar routine takes a fixed-width digit string, sorts its digits into descending and ascending order, and subtracts the second integer from the first. Leading zeros are retained so the next step uses the same width.
For four digits, . The next step returns , a Kaprekar constant. Equal-digit inputs instead reach zero. Since there are finitely many fixed-width strings, every orbit eventually reaches a fixed point or a cycle. This finite-state observation does not by itself prove which attractor occurs.
A Kaprekar constant is a nonzero fixed point of a specified Kaprekar routine, with the base and digit width held fixed. In base ten with four digits, is one because ; with three digits, is one because .
Leading zeros must be retained during iteration. The familiar four-digit attraction result applies to inputs with at least two distinct digits; strings such as go to zero. Other widths or bases can have different fixed points and cycles, so the phrase does not identify a base-independent numerical constant.
The arithmetic derivative on positive integers is specified by for each prime number and the product rule . These conditions force . For a prime factorization they giveRepeated use of the product rule proves necessity. Conversely, the fundamental theorem of arithmetic makes this formula well-defined, and the addition of prime exponents under multiplication verifies the product rule. Thus it proves existence as well as uniqueness.[ref]
How to Differentiate a Number by Victor Ufnarovski and Bo Åhlander. §1, Theorem 1, printed p. 2: factorization formula, uniqueness and verification of the Leibniz rule
For example, . Despite its name, the arithmetic derivative does not preserve addition: , whereas . Its analogy with an ordinary derivative preserves the product rule while sacrificing the usual sum rule.
A Harshad number in base is a positive integer divisible by its base-p digit sum in that base. In base ten, is a Harshad number because divides . It is strong when the quotient by its base-p digit sum is prime, and right-truncatable when every nonempty prefix is a Harshad number.
For positive integers having greatest common divisor one, the Frobenius number is the largest integer not expressible as with nonnegative integer coefficients . A coin interpretation allows unlimited copies of denominations , rather than a fixed number of coins.
For denominations and , the value is . The next four values are representable: , , and . Repeatedly adding then covers every larger integer. The two-generator Frobenius theorem proves the formula for two coprime denominations.
The hypotheses exclude two different degeneracies. If all denominations have a common divisor greater than one, infinitely many positive amounts are impossible, so no largest impossible amount exists. If denomination one is present, every nonnegative integer is possible; the usual positive-gap problem disappears. Some conventions assign the latter case the value .
First, cannot equal with nonnegative integers . Reducing modulo gives ; coprimality forces to be a positive multiple of . Hence , a contradiction.
Now take any integer . Multiplication by permutes the residue classes modulo , so choose with . The difference is a multiple of and satisfies . It is therefore nonnegative, giving and . This proves both the largest gap and representability of every greater integer.
A positive integer such that every positive integer at most is a sum of distinct divisors of . For example, is practical because its divisors represent every value from through .
A positive integer that is both the sum and the product of one multiset of positive integers. For factors at least with product , sum , and count , appending ones gives without changing the product. For , the example with ones proves that the smallest product-sum value is at most .
Integer factorization seeks the prime factorization of a positive integer . For , this means identifying its prime factors and their multiplicities; one has the empty prime factorization. Finding one proper divisor is useful progress, but need not finish the job: factor and further until all factors are prime numbers.
For example, is a semiprime, whereas has three prime factors. Primality testing asks whether a proposed integer is prime; it need not return a factor when the answer is no. Trial division is a direct factoring method: try division by small prime numbers until a divisor is found. More elaborate methods obtain a proper divisor through a greatest common divisor of with a specially constructed integer.
The beautiful trick in congruence of squares is that two integers with equal squares modulo can reveal different factors through their sum and difference. In the worked example, gives and . Computing those greatest common divisors uses the Euclidean algorithm; it does not require trying every potential factor. A factor base supplies a systematic way to construct useful equal-square relations. [ref]
https://crypto.stanford.edu/pbc/notes/crypto/factoring.html. Ben Lynn, Factoring and Discrete Logarithms: congruent squares and the linear-algebra step
.This connection is useful in cryptography because recovering the factors of an RSA cryptosystem modulus defeats the factoring assumption behind its construction. That application concerns large, carefully chosen inputs; the small examples here explain the arithmetic mechanism and are not benchmarks or estimates of present cryptographic security.
The elliptic-curve factorization method searches for a nontrivial divisor of a composite integer by doing elliptic curve arithmetic modulo . Hendrik W. Lenstra's method replaces the multiplicative group in Pollard's p-1 algorithm with a group whose order varies as the curve varies. For an unknown prime divisor , a curve for which the order of the chosen point has only small prime factors can make a suitably chosen multiple of that point vanish modulo without vanishing modulo every prime divisor of .[ref]
In affine-coordinate arithmetic, trying to invert a denominator modulo can fail. Computing the greatest common divisor then yields a factor if . A full gcd of is inconclusive; another curve or point may be needed. Implementations can accumulate this information with projective coordinates rather than attempting an inversion at every step.
For a small worked example, take , the curve , and . Its discriminant is coprime to . The usual addition formulas give and modulo . Adding these to form calls for inversion of . Since , the failed division exposes a prime divisor. This elementary example illustrates the mechanism; the method's practical advantage is its dependence on the size of the factor sought, rather than only on the size of .
For an integer to be factored, John Pollard's method chooses an integer coprime to and an exponent divisible by many small prime powers. Compute by modular exponentiation and the Euclidean algorithm. If , it is a proper divisor. If a prime divisor of has , Fermat's little theorem ensures ; success requires some other prime divisor not to divide . Common choices are and . The method exploits a smooth , rather than a small divisor itself.
A general-purpose classical integer factorization algorithm combining polynomial relations, arithmetic in number fields and sparse linear algebra to construct congruent squares modulo the input. Its familiar general-input complexity estimate is heuristic and subexponential in the input's value, roughly for input bits. This is not polynomial in the bit length. Special input structure, small factors and preprocessing can make other algorithms preferable.
An ordered factorization of a positive integer is an ordered list of factors greater than one whose product is . For example, , , and are the three ordered factorizations of . Taking successive partial products gives a bijection with strictly increasing divisor chains from to .
An integer factorization algorithm that iterates a simple map such as and searches for a nontrivial greatest common divisor of and the difference of two iterates. A collision modulo an unknown prime factor can reveal that factor before a collision modulo . A cycle detection schedule such as Floyd's cycle-finding algorithm limits the number of stored iterates. Unsuccessful choices of seed or map can be retried.
The Brent variant of Pollard rho finds factors of a composite integer by iterating a map such as . A collision modulo an unknown prime factor can be detected through . Brent's variant organizes comparisons in blocks whose lengths double, reducing the work of cycle detection compared with comparing two iterates at every step.[ref]
An improved Monte Carlo factorization algorithm by Richard P. Brent. §§3–4, cycle finding and factorization
It can also batch differences: compute their product modulo and take one greatest common divisor per block. If that gcd is , retry the saved differences individually to recover a proper factor, or restart with a different orbit. The commonly used square-root-of-factor runtime estimate is heuristic and depends on treating the orbit modulo that factor like a random map.
A factor base is a finite set of small prime numbers over which selected auxiliary integers are completely factored. Some methods also record a sign coordinate for , which is not a prime number. A positive integer supported entirely on the chosen factor base gives an exponent vector; reducing that vector modulo two records which prime exponents are odd integers. The product is a square of a number precisely when every prime exponent is an even integer.
For the original toy , use factor base and the two relationsThe residues have exponent vectors and in the order . Adding the two vectors modulo two gives , so multiplying the residues gives . Consequentlyand and . Neither individual residue was a square; combining the relations made all exponents even.
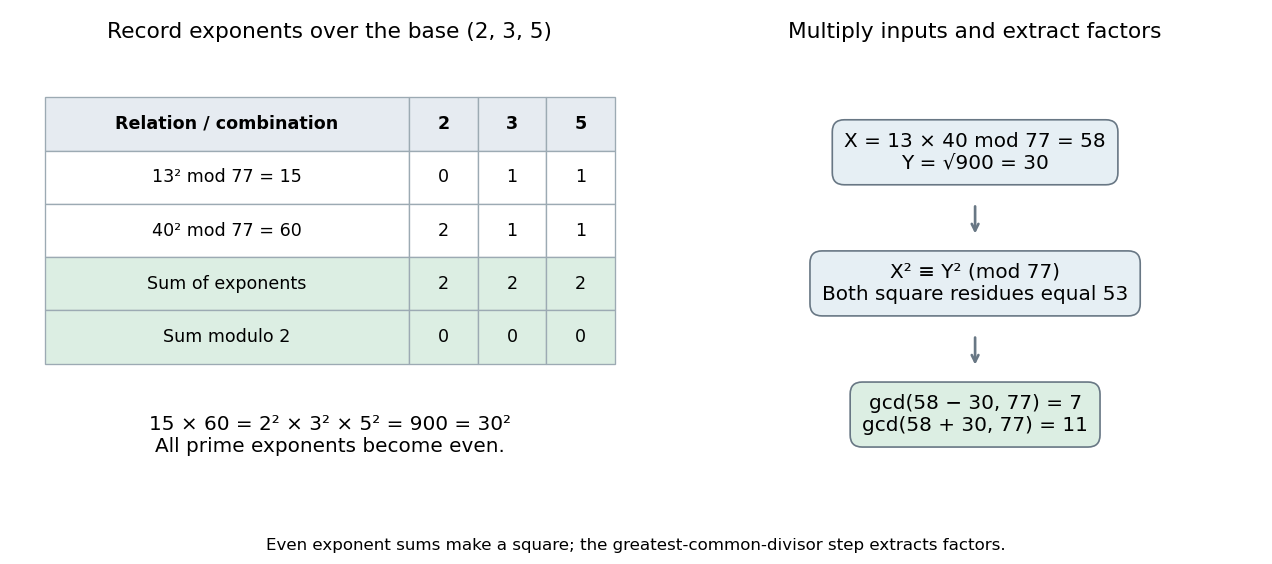
In a larger collection, choose relations with positive residues . If a nonempty selection has an even sum in every exponent coordinate, setThen . Finding such a selection is a linear dependence problem over the finite field : the indicator vector of the chosen relations belongs to the kernel of a linear map given by the parity matrix. This is why a problem about prime factors recruits linear algebra. The final congruence of squares may still be trivial, so another selection can be needed. [ref]
https://crypto.stanford.edu/pbc/notes/crypto/factoring.html. Ben Lynn, Factoring and Discrete Logarithms, Dixon's Algorithm: exponent matrix and kernel
.There is a tradeoff: a small factor base gives a smaller parity matrix, but fewer auxiliary integers factor completely over it. A larger factor base accepts more relations but makes the linear algebra larger. Negative auxiliary values need an additional sign coordinate, and a selected product needs even sign parity as well as even prime exponents. Pomerance's account explains this balance and the historical development of combining smooth relations; the toy example omits algorithm-specific sieving and running-time claims. [ref]
https://math.dartmouth.edu/~carlp/PDF/paper109.pdf. Carl Pomerance, A Tale of Two Sieves (1996), pp. 1475–1476: exponent parity, factor bases and signs
.Relative to an ordered factor base , a positive integer has exponent vector . Multiplication of such integers adds their exponent vectors. Reducing every coordinate modulo two gives the parity vector used to find congruences of squares. The ordering and any sign coordinate must be used consistently across all rows.
For positive integers and a prime , their prime-exponent difference is , where is the exponent in prime factorization. This is the exponent of in the positive rational number , and it may be negative.
For and , the differences are at and at , giving . The quotient is an integer exactly when every difference is nonnegative. It is a rational th power exactly when every difference is divisible by , making exponent differences useful for perfect-power and divisibility tests.
The odd part of a positive integer is the unique odd positive integer obtained by repeatedly dividing by two. The process terminates because the positive integers decrease. If with odd, then would make even and would make even; hence and . Two positive integers have the same odd part exactly when their ratio is an integral power of two. The odd positive integers therefore give representatives for the resulting equivalence classes.
A congruence of squares says that two integers have the same square modulo a positive integer . Factoring their difference of squares givesA useful integer factorization results when or is a proper divisor of . Divisibility of a product does not generally force divisibility of either factor by all of : different prime factors of can divide different parts of that product.
For , . ThereforeThus . The prime seven divides the difference, while eleven divides the sum. These computations already give a complete prime factorization because seven and eleven are prime numbers.
The Chinese remainder theorem explains the hidden sign choices. The four congruence classes solving have representatives . Modulo seven each is or ; modulo eleven each is or . Two independent sign choices produce four roots. The inputs thirteen and twenty agree modulo seven and disagree by sign modulo eleven, allowing their sum and difference to separate the two prime factors.
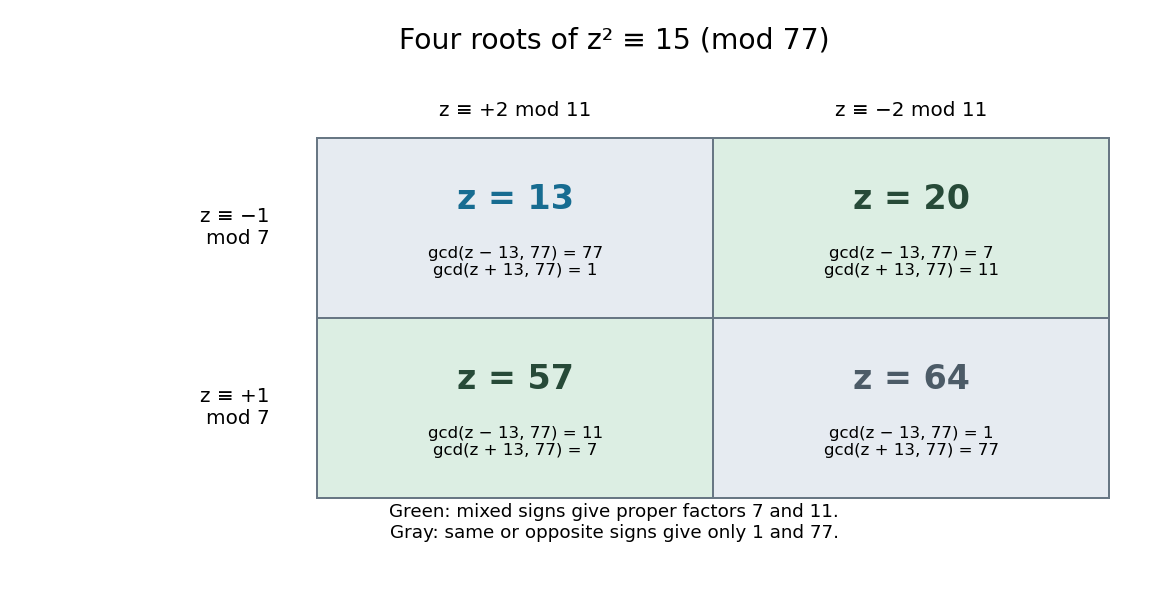
For distinct odd prime numbers , and , a solution with and modulo yields both proper factors by the two greatest common divisors. For a general composite integer, a proper divisor need not itself be prime; further factoring can remain. If or in the coprime case, the two calculations return and one instead. A factor base helps generate relations, but does not ensure every resulting relation is useful.
For historical context, Pomerance describes Kraitchik's 1920s enhancement of the difference-of-squares approach associated with Fermat: seek a difference that is a multiple of , rather than exactly . His account also notes antecedents in Gauss and Seelhoff, so this is not an attribution of the whole idea to a single inventor. [ref]
https://math.dartmouth.edu/~carlp/PDF/paper109.pdf. Carl Pomerance, A Tale of Two Sieves (1996), pp. 1474–1475: difference-of-squares and congruent squares
.For an odd integer , a nontrivial square root of unity modulo is a residue with and . Then both and are proper divisors. For , works: , , and .
A congruence of squares with converts to this form by , using a modular multiplicative inverse. In the example, , so . It yields and . Nontriviality requires mixed sign choices across prime factors, which an odd prime number modulus cannot provide.
The Erdős-Turán inequality bounds how unevenly finitely many points fill the half-open interval by measuring finitely many Fourier modes. For define their normalized star discrepancy byThere is a universal constant such that, for every positive integer ,The finite-point form follows from the corresponding probability measure inequality by placing mass at each point of the unit circle represented by .[ref]
One more proof of the Erdős-Turán inequality, and an error estimate in Wigner's law by Ohad N. Feldheim and Sasha Sodin. Proposition 1, equation (1), printed p. 1; rescale the circle coordinate by and use the empirical probability measure
The cutoff trades an approximation error against the measured exponential sums. If each fixed nonzero Fourier mode tends to zero as grows, take the limit superior first with fixed, then let grow. This gives , the quantitative route to equidistribution.
For the grid with , every displayed exponential sum vanishes for by the finite geometric series. Choosing yields ; direct counting gives the sharper exact value .
A Fermat number is the positive integer , indexed by a nonnegative integer . The first five are , all prime numbers; the next is the composite number . This family offers a compact lesson in number theory: a very persuasive finite pattern can fail, while an exact divisibility relation settles a gigantic case with little computation.
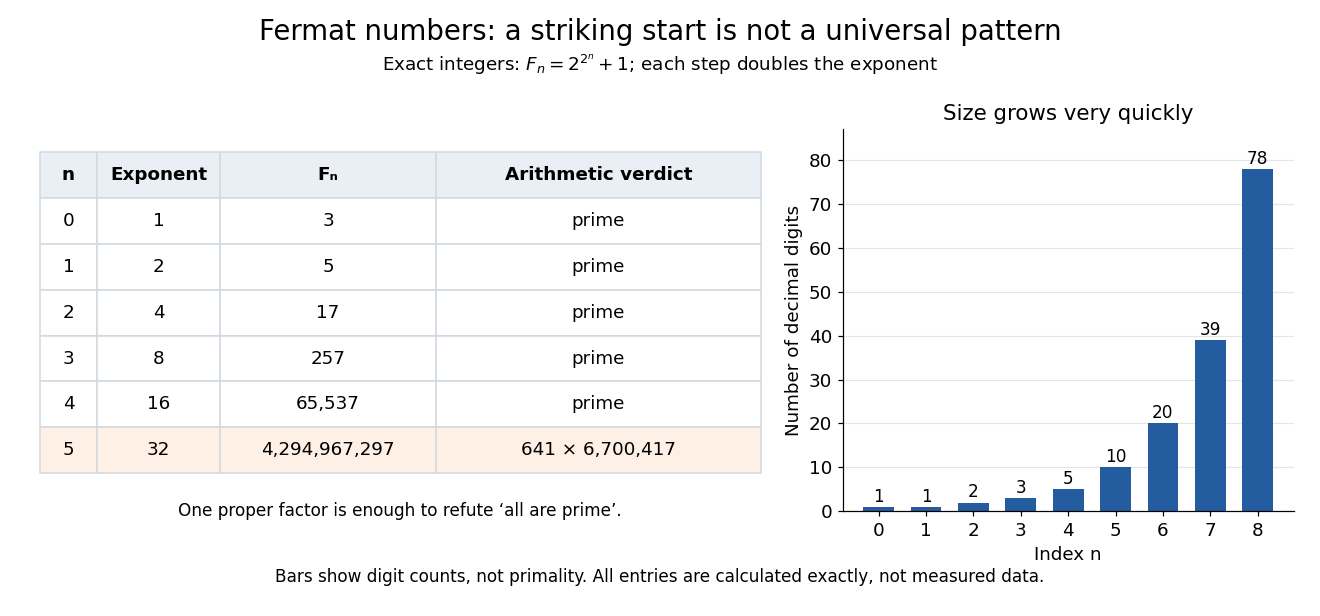
Exact Fermat numbers: five initial primes, a composite sixth term, and rapidly increasing decimal lengths
. Details. Why does the exponent itself have the form ? Suppose is a positive integer with an odd integer factor . The polynomial factorization shows that is a proper divisor of . Consequently, if is a prime number, must be a power of two. That is a necessary condition, rather than a promise that the surviving candidates are prime.
The Fermat number product identity makes distinct Fermat numbers coprime integers. Thus every term has a prime factor absent from all earlier terms, whether or not that term is itself a prime number. This gives an explicit route to infinitely many different prime numbers, without establishing that infinitely many terms of this particular sequence are prime. Meanwhile the prime divisor of a Fermat number criterion filters possible factors through a small multiplicative order calculation.
The family also links arithmetic to Euclidean geometry: a constructible regular polygon can have a number of sides equal to a power of two times a product of distinct Fermat primes. The Gauss-Wantzel theorem gives the precise criterion. For instance, and qualify, but does not. The word "distinct" matters. Carl Pomerance describes this connection in Primality testing: then and now by Carl Pomerance (slide 18).
Historically, Leonhard Euler records Pierre de Fermat's proposed primality pattern, then refutes it by finding the factor of . His paper was presented in 1732 and published in 1738; those are different events, not competing dates for one publication.[ref]
Observations on a certain theorem of Fermat and on others concerning prime numbers by Leonhard Euler. pp. 1–2 and the publication note
A short modern check needs only two representations of :In modular arithmetic these give and . Substitution yields , so . This verifies the factor directly; it does not claim to reconstruct Euler's search process.
For each positive integer , the product of the preceding Fermat numbers is two less than the next:For example, . The identity telescopes by repeated difference of squares: . Its usefulness is that a huge integer product exposes a tiny difference, two, from the next term.
If , a common divisor of and divides both , by the Fermat number product identity, and . It therefore divides two. Both Fermat numbers are odd integers, so their greatest common divisor is one. Each term's prime factors are consequently different from the prime factors of every other term.
For a prime number , the exact criterion iswhere must be different from two and is the multiplicative order of two modulo . If , then : the order divides but not , so it is exactly . Conversely, that order makes a square root of unity different from one in the prime field ; it must be , because has no other roots in a field.
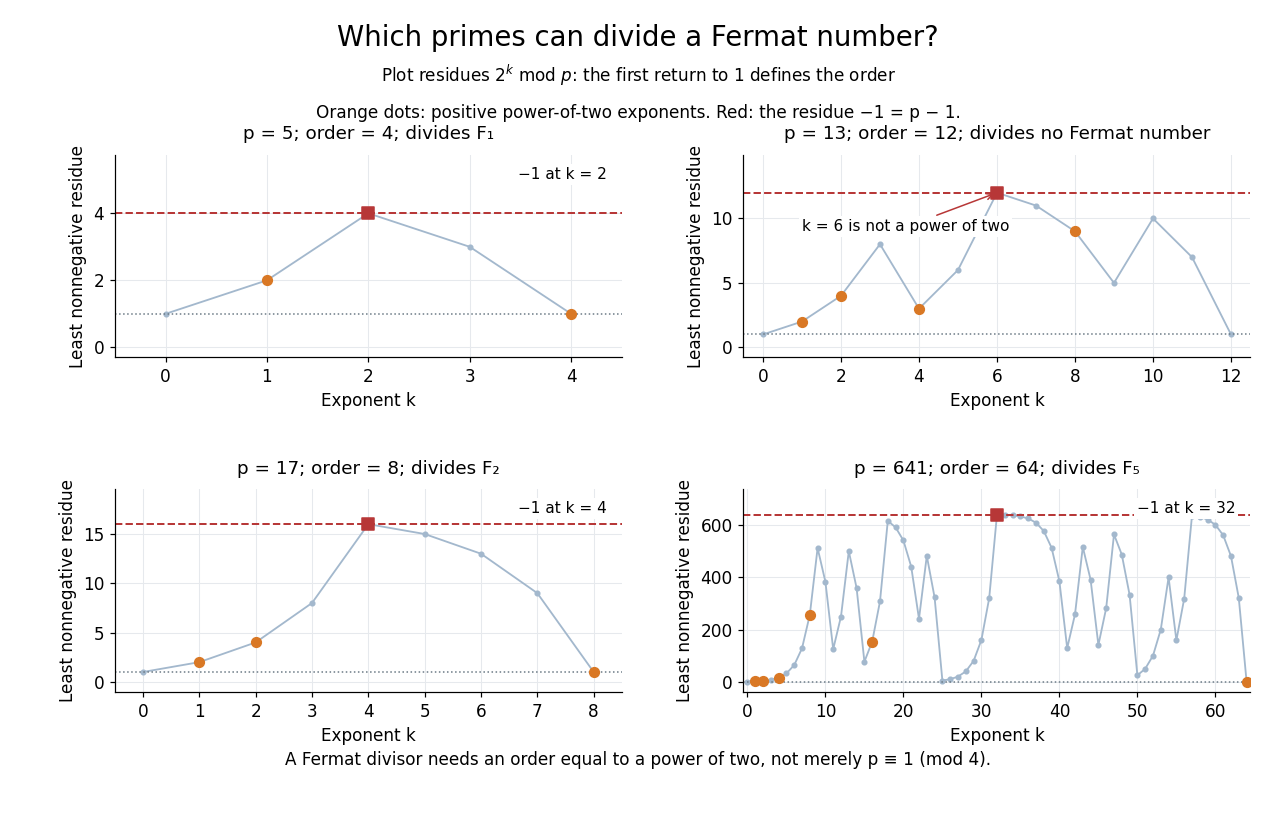
Exact modular powers distinguish Fermat divisors from the prime thirteen, whose multiplicative order is twelve
. Details. For example, modulo seventeen the powers of two are . Their first return to one occurs after eight steps. The half-way value is , proving that . Likewise, identifies as a prime factor of . These are statements about divisibility, not evidence that the entire Fermat number is prime.
The multiplicative order always divides , by Fermat's little theorem, so . In particular, for every prime divisor of a Fermat number is one modulo four. That weaker modular congruence is insufficient: thirteen is one modulo four, but , which is not a power of two. It divides no Fermat number at any index. The exact order criterion explains the whole family, instead of testing finitely many terms.
For , the first order bound already gives . The second supplementary law for quadratic reciprocity says that two is then a quadratic residue modulo . Euler's criterion gives , so its multiplicative order divides . Thus , further reducing the candidate factors. At , meets this bound. The restriction matters: has factor five, which is not one modulo eight.
The Bernoulli numbers are a sequence of rational numbers that turns integer power sums into exact polynomials. The same numbers describe corrections when a discrete summation is compared with an integral. For example, the sum of squares is : the leading term is an integral, while the last two terms repair the difference between area and sampled values.
We use throughout. The defining exponential generating function isHere is the exponential function and is a factorial; in particular, the coefficient of is , rather than . At the quotient has limiting value one. The identity can be read algebraically as a formal power series, or as a convergent series for .[ref]
NIST Digital Library of Mathematical Functions. Karl Dilcher, Chapter 24, §24.2(i), equation 24.2.1: defining generating function and convergence domain
To compute the numbers, multiply by and compare coefficients. The resulting recurrence relation, with binomial coefficients, isThus , , and give , , and . Continuing givesThe recurrence relation agrees with equation 24.5.3 after replacing its index by .[ref]
NIST Digital Library of Mathematical Functions. Karl Dilcher, Chapter 24, §24.5(i), equation 24.5.3; first values also in Table 24.2.1
Why do so many values vanish? Put . Direct substitution gives , so is an even function. Its odd power series coefficients vanish: for every positive integer . The exception matters. The alternative convention obtained from has and exactly the same other values. A formula copied between conventions must also retain its summation endpoints.
Historically, integer power sums were studied before the modern Bernoulli number notation. A historical study examines formulas published in 1631 and distinguishes those separate formulas from encoding all exponents using one sequence of constants. This is a useful motivation for the generating function, without assigning all discovery to a single moment. [ref]
Johann Faulhaber and sums of powers by Donald E. Knuth. Donald E. Knuth, Johann Faulhaber and sums of powers, 1992 preprint, pp. 2 and 14: the 1631 power-sum formulas and the uniform Bernoulli-number formula
For , the von Staudt-Clausen theorem statesConsequently the positive denominator of the Bernoulli number in lowest terms is exactly the squarefree product of the primes satisfying . This gives its denominator without computing its numerator.[ref]
For , the relevant primes are . Their reciprocals sum to , and , so the displayed expression is . The theorem concerns even positive indices; is handled separately. It explains the recurring small prime factors in denominators of formulas for sums of powers.
The Bernoulli polynomials extend the Bernoulli numbers by inserting the exponential function into their exponential generating function:For example, , , , and .[ref]
NIST Digital Library of Mathematical Functions. Karl Dilcher, Chapter 24, equations 24.2.3–24.2.5 and Table 24.2.2
Their crucial property is a finite difference identity:Indeed, subtracting the two exponential generating functions cancels and leaves . Thus plays for discrete summation the role that plays for integration: taking a unit finite difference recovers .[ref]
The periodic Bernoulli function is the periodic extension of the Bernoulli polynomial, where is the fractional part. It has period one. For example, .
For , its Fourier expansion isThe series is absolutely convergent. For the same formula holds away from the integers and describes a sawtooth. At an integer the symmetric Fourier value is zero, whereas the literal fractional-part convention gives ; endpoint conventions must therefore be distinguished.[ref]
Periodic Bernoulli functions occur in the remainder of the Euler-Maclaurin formula, connecting errors in discrete summation with periodic oscillation between successive integers.
An integer power sum adds a fixed nonnegative integer power of consecutive integers. Let be a nonnegative integer and a nonnegative integer. For , use the constant polynomial , including at zero, so . Summing the Bernoulli polynomial finite difference identity makes the intermediate terms cancel and givesThe sum is empty when . For the endpoints , the formula valid also at is insteadFor , , and this becomes the standard positive-endpoint formula. The exception at is essential: .[ref]
For , adding to changes the contribution from to . Equivalently,where only differs from our Bernoulli numbers. A quick endpoint check is : the sums over and are and , respectively. The latter is a triangular number.
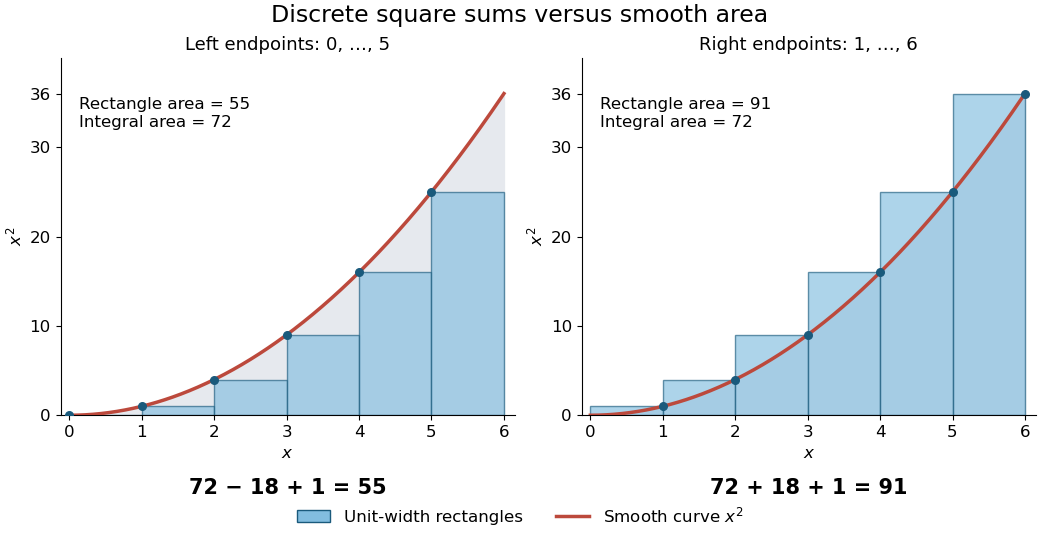
For a concrete comparison, take on . The integral is , whereas the unit-width left and right Riemann sums are and . The exact integer power sum formula givesThe endpoint choice explains the opposite signs of the correction. The remaining correction is one in both cases.
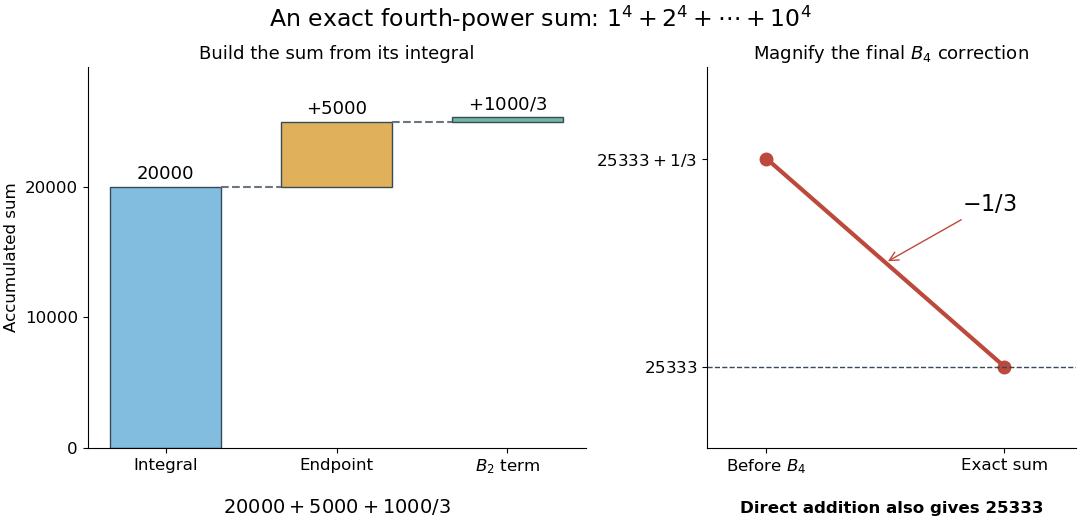
The same method is useful far beyond squares of numbers. Substituting , , and into the integer power sum formula gives the exact fourth-power resultAt , this isThus a finite polynomial calculation replaces ten additions, or a million additions if is a million. Although the individual corrections can be rational numbers, the result is the exact integer sum.
There is also a useful numerical integration interpretation. The average of the left and right Riemann sums is the composite trapezoidal rule. For , the endpoint corrections cancel but its value is , one above the true integral. Subtracting the correction makes this particular polynomial example exact. For , the two interior corrections above can be written and . These are exact identities for these polynomials; extending such corrections to general functions requires a separate error analysis.
The defining generating function of the Bernoulli numbers, with , gives this identity of formal Laurent series by . Therefore is regular and odd. Integrating it gives the even formal logarithm of . Its even derivatives of order at zero are , while the odd derivatives vanish. This computes the cyclotomic higher logarithmic derivatives of symmetric cyclotomic units without introducing a spurious linear term.
The Euler evaluation of even zeta values turns a family of series into exact expressions using Bernoulli numbers, factorials and powers of . For every positive integer ,Here is the Riemann zeta function, defined by its convergent series at these arguments, and the Bernoulli number convention is . The alternating sign combines with the sign of to give a positive sum.[ref]
Substituting , and givesThe first identity answers the Basel problem. It is surprising because the original series only mentions reciprocal squares of integers, while its exact sum involves the circle constant . The cotangent partial-fraction expansion supplies a connection between the two: trigonometric functions encode equally spaced integer poles, whose expansion brings the reciprocal powers into view.
For an original numerical comparison, the first ten terms give , while . The omitted positive terms still contribute approximately . For fourth powers, the ten-term partial sum is approximately , only below . Both are convergent series, but the second approaches its limit much faster.
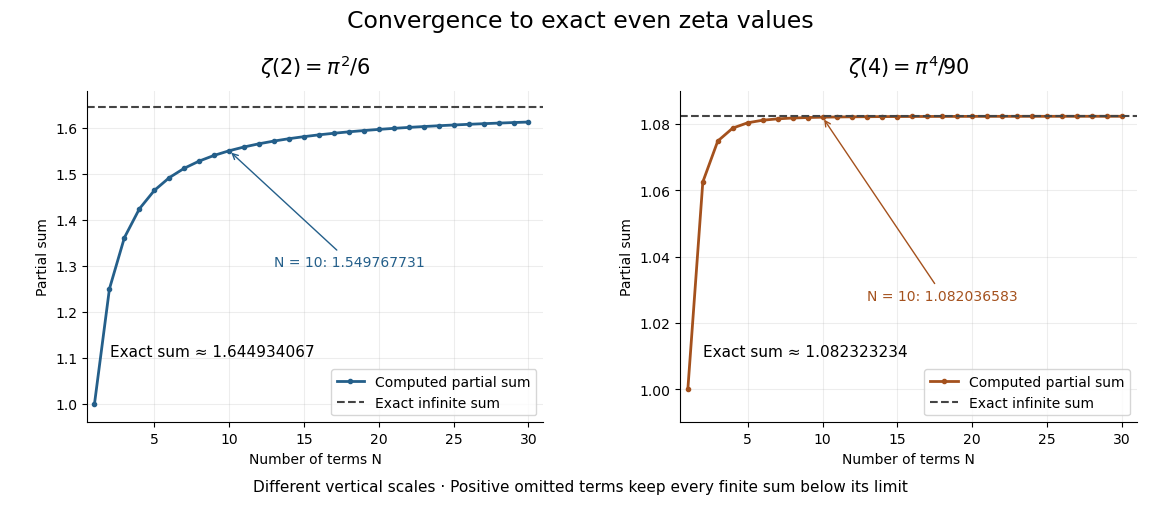
Exact evaluation is useful beyond obtaining more digits. It supplies an independent check on a numerical summation, exposes how Bernoulli numbers organize infinitely many identities, and makes the remaining series truncation error measurable without knowing any omitted terms individually. The even integer condition is essential to this formula: putting into it is not a way to evaluate , since the required Bernoulli number index and factorial expression here are indexed by positive integers.
Historically, Leonhard Euler announced reciprocal-square and reciprocal-fourth-power evaluations in §2 of On the sums of series of reciprocals by Leonhard Euler. That paper was presented on 5 December 1735 and published in 1740, as the English translation's first-page note records. His §§3–8 develop a route through the sine power series and relationships between roots and coefficients. The cotangent calculation below is a concise modern presentation of the connection.[ref]
On the sums of series of reciprocals by Leonhard Euler. English translation, p. 1, §2 and publication note; pp. 3–4, §§3–8: sine series, roots and coefficients
For a real exponent and a positive integer , the series truncation error in the defining Riemann zeta function series isThe integral comparison for the positive decreasing function gives the explicit boundsOn each unit interval, the area under lies between its endpoint heights. Summing from the first omitted term gives the lower integral from to infinity and the upper integral from to infinity. This uses positivity and monotonicity, not an assumption that the last computed term equals the remaining error.
At , the bounds are , whereas . The errors above fit both intervals. Merely looking at the eleventh term would give for squares, far smaller than the actual remaining .
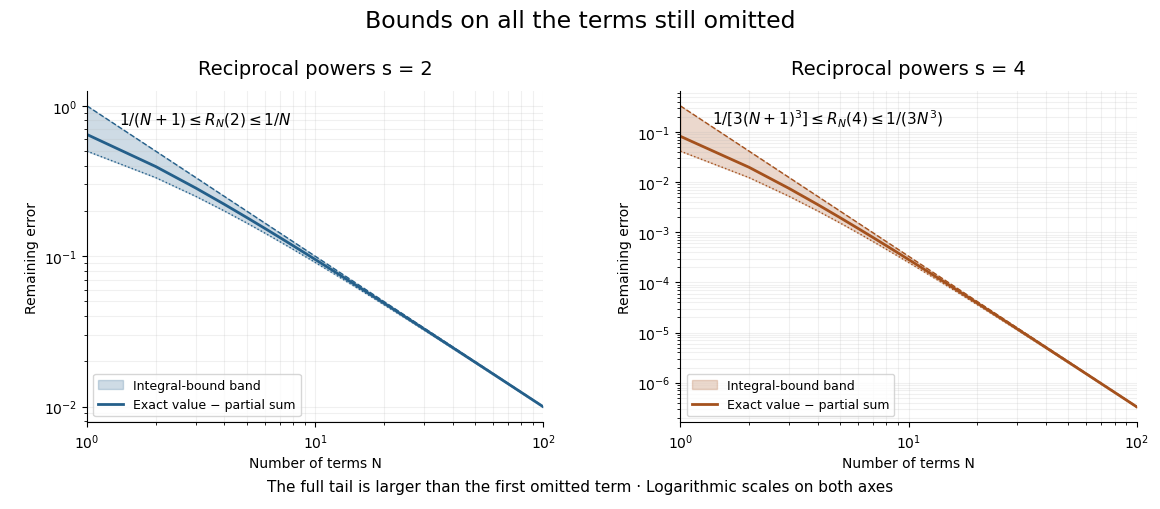
For a chosen absolute error target , the sufficient condition is , rounded upward to an integer. Thus requires by this bound for squares but only for fourth powers. This is a guarantee from an upper bound, not a claim that those are the smallest successful term counts.
The cotangent partial-fraction expansion gives, on ,The Bernoulli number generating function gives the same Laurent series in another form:The term cancels the separate ; the higher odd Bernoulli numbers vanish. Comparing Laurent coefficients therefore gives , which is the stated real formula because . The cotangent partial-fraction expansion justifies the convergent expansion before the coefficient comparison; a finite plot of partial sums alone would not prove the infinite identity.
Let be a primitive Dirichlet character of conductor of a Dirichlet character . Its generalized Bernoulli numbers are the coefficients of the exponential generating functionComparing this with the Bernoulli polynomial generating function gives the finite formulaThe formula makes the definition computable using finitely many ordinary Bernoulli polynomials.[ref]
NIST Digital Library of Mathematical Functions. §24.16(ii), equation 24.16.10: primitive character, conductor and defining generating function; the finite formula follows by substituting ft into equation 24.2.3
The convention at the trivial character deserves attention. For conductor , the generating function is , so , whereas the ordinary Bernoulli number convention in this article is . All other coefficients agree. For the nontrivial character modulo , with , and zero values at even inputs, the finite formula gives .[ref]
NIST Digital Library of Mathematical Functions. §24.16(ii), equation 24.16.12 and the character modulo 4 immediately preceding it
These character-weighted coefficients encode special values of Dirichlet L-functions at nonpositive integers and occur in Kubota-Leopoldt p-adic L-functions. They let the arithmetic carried by a Dirichlet character enter the same generating function framework as ordinary Bernoulli numbers.
A real number is normal in an integer base when every finite word of digits occurs in its positional notation with the same limiting digit block frequency as every other word of the same length. Write its fractional part as in base , using the expansion that is not eventually all digits when two expansions are possible. For every length and every word , the requirement isOccurrences overlap: the word occurs twice in . There are possible words of length , so is the equal share for each. In a decimal representation, this means frequency for each digit, for each pair, and for each triple, continuing through every finite length. The definition agrees with that used by Copeland and Erdős in their work on explicit normal numbers. [ref]
https://users.renyi.hu/~p_erdos/1946-01.pdf. Arthur H. Copeland and Paul Erdős, Note on Normal Numbers, 1946, opening definition
The appeal is that a precise, deterministic real number can have the same limiting digit block frequencies as repeated draws from a uniform distribution on a finite set, with independence between draws. Champernowne constant is an explicit example. Normality is useful for studying digit distribution, but balanced digits alone establish only a simply normal number, and a finite sample cannot establish any of these infinite limits.
Émile Borel introduced normal numbers and established their prevalence in his 1909 paper applying probability to number theory; the stronger all-base statement is discussed under absolutely normal number. [ref]
https://doi.org/10.1007/BF03019651. Émile Borel, Les probabilités dénombrables et leurs applications arithmétiques, Rendiconti del Circolo Matematico di Palermo 27, 247–271, 1909
For a finite prefix of digits in positional notation, the digit block frequency of a length- word is its number of overlapping occurrences divided by , the number of available starting positions. All such digit block frequencies sum to one. The infinite limit used for a normal number can instead divide counts by : the factor tends to one for fixed .
For the six binary digits , the single-digit counts are three zeros and three ones. Its five adjacent pairs are , givingThis example explains both the overlapping convention and the end correction in a finite sample. The corresponding infinite binary expansion has pair frequencies , rather than the four values required of a normal number in base two.
A real number is simply normal in base if each individual digit in its positional notation has limiting digit block frequency . This is the length-one part of the definition of a normal number. It places no equal-frequency requirement on longer words.
For example, is a simply normal number in base two: each binary digit has frequency . But and never occur, and and each have frequency . Thus is not a normal number in base two. Even a sequence that looks more complicated, such as the deterministic Thue–Morse sequence, must be tested against the actual digit block frequency definition; visual complexity is no substitute for it.
The decimal representation makes the same point in base ten. Every digit has frequency , yet the only adjacent pairs areEach has limiting digit block frequency ; the other ninety pairs have frequency zero. A normal number in base ten requires for every one of the hundred pairs. This rational number is a simply normal number in base ten, but it is not a normal number in that base.
Form Champernowne constant by using concatenation to join the decimal representations of the positive integers after the decimal point. Champernowne proved in 1933 that this particular real number is a normal number in base ten. The construction is striking because its rule is completely explicit, while all finite words have the prescribed limiting digit block frequencies. [ref]
https://doi.org/10.1112/jlms/s1-8.4.254. D. G. Champernowne, The Construction of Decimals Normal in the Scale of Ten, Journal of the London Mathematical Society 8, 254–260, 1933
Copeland and Erdős explicitly recall this result at the start of their own paper. [ref]https://users.renyi.hu/~p_erdos/1946-01.pdf. Copeland and Erdős, Note on Normal Numbers, 1946, first paragraph
The first digits of Champernowne constant have the following exact counts, in digit order :For the adjacent pairs fully inside that prefix, the words occur times respectively. Thus, for example, , which is about , rather than . The prefix ends partway through the decimal representation of ; the many leading ones in earlier positive integers help explain the visible imbalance.
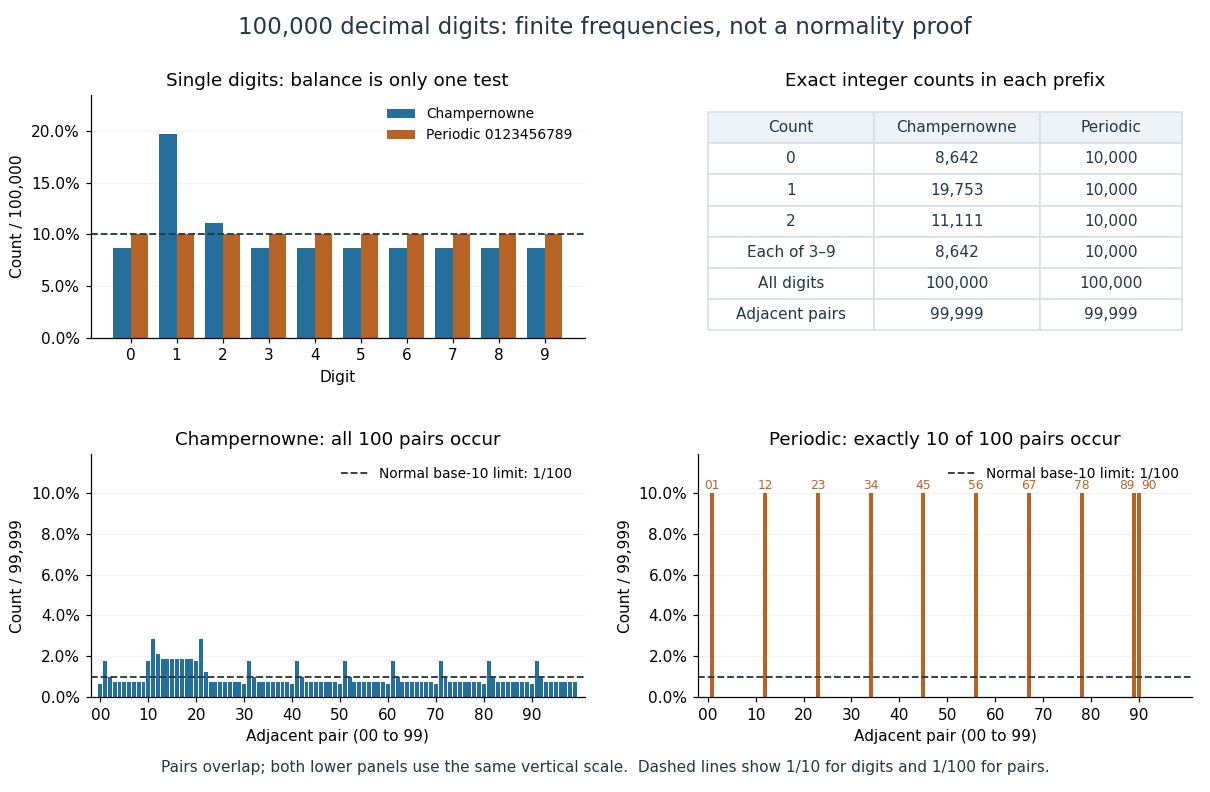
These are finite counts, not a proof of the normal number theorem: a finite prefix can be followed by an all-zero tail. The theorem for Champernowne constant concerns the infinite limit, and establishes base-ten normality, rather than absolute normality. Nor do computations prove normality for familiar constants: the normality of Pi and Euler's number remains unproved, as discussed by Bailey and Borwein. [ref]
https://www.davidhbailey.com/dhbpapers/normal-pseudo.pdf. David H. Bailey and Jonathan M. Borwein, Normal Numbers and Pseudorandom Generators, author manuscript, 2011, introduction
A real number is a normal number in base exactly when its iterates under the integer multiplication map on the circle, , form an equidistributed sequence. Braces denote the fractional part. Multiplication by shifts the positional notation one digit to the left:A length- word with base- integer value specifies the half-open interval , whose length is . Visiting that interval is exactly encountering that word at the next digit position. These digit intervals form arbitrarily fine grids, so their correct limiting visiting frequencies imply equidistribution on every interval. This converts a question about digits into one about a dynamical system. Bailey and Crandall develop this connection using equidistribution of the fractional parts of . [ref]
https://www.davidhbailey.com/dhbpapers/bcnormal.pdf. David H. Bailey and Richard E. Crandall, Random Generators and Normal Numbers, 2003 author manuscript, Section 2
In base ten the word corresponds to . For Champernowne constant, counting the visits for gives precisely the occurrences of in its first digits. For , the base-two integer multiplication map on the circle instead alternates between and ; it never visits , the interval for . This two-point orbit is not an equidistributed sequence.
An absolutely normal number is a normal number in every integer base . This requires every finite word in every such positional notation to have its appropriate limiting digit block frequency. Knowing base-ten normality alone does not establish absolute normality; the base is part of the statement.
Borel's 1909 result says that absolute normality holds almost everywhere for Lebesgue measure: within the exceptions form a Lebesgue null set. In particular, the set of absolutely normal numbers has Lebesgue measure one there. This is a statement about the size of an exceptional set, not a test for a specified constant. [ref]
https://doi.org/10.1007/BF03019651. Émile Borel, Les probabilités dénombrables et leurs applications arithmétiques, 1909
[ref]https://www.davidhbailey.com/dhbpapers/normal-pseudo.pdf. Bailey and Borwein, Normal Numbers and Pseudorandom Generators, 2011, introduction: simultaneous normality in all integer bases
A modern route uses the Birkhoff ergodic theorem and ergodicity of integer multiplication on the circle. For each fixed base and digit interval, the time proportion equals its Lebesgue measure almost everywhere. The bases and finite words form countable sets, so a countable intersection of these measure-one sets still has Lebesgue measure one. For an absolutely normal number, the word therefore has frequency in base two, in base three, and in base ten. The same symbols represent different intervals in different bases.
For a set of nonnegative integers, its natural density is the limiting proportion of the first nonnegative integers that belong to :provided this limit exists. Write for the counting function. The numerator is a finite cardinality; the denominator is exactly , including zero. Every existing natural density lies between zero and one.
For the even nonnegative integers , there are elements below and below . Thus using the ceiling function, and . For the square numbers , the exact count for isThe floor function counts the allowed indices , and the extra one counts zero. At , the square numbers below ten are , so the proportion is ; at , it is . The count grows like the square root of , while the denominator grows like .
The prime numbers also have natural density zero. If is their set, the Prime number theorem gives , hence . The Prime number theorem is a substantial result about the count, rather than a consequence of the fact that there are infinitely many prime numbers. [ref]
https://math.mit.edu/classes/18.785/2025/LectureNotes16.pdf. Andrew V. Sutherland, MIT 18.785 lecture 16, Riemann's zeta function and the prime number theorem, 2025
Why use natural density when cardinality already measures size? The even nonnegative integers, the square numbers, and the prime numbers all have the same countably infinite cardinality, yet their proportions among large initial integer intervals differ. Natural density distinguishes frequent membership from sparse membership. Equivalently, under a uniform distribution on a finite set of possible nonnegative integers, is the probability of landing in . A set without natural density shows why this limiting proportion need not exist.
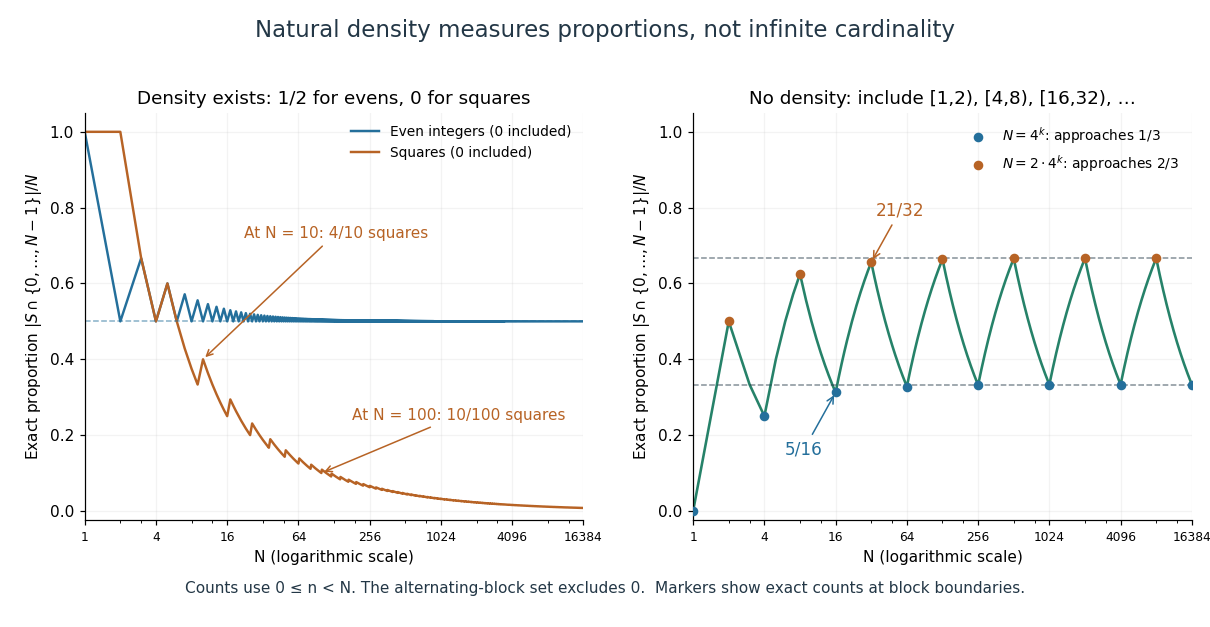
Include the positive integers in , and exclude the intervening integer intervals and zero. Equivalently, include for . Each included block is large enough to raise the running proportion; the following excluded block lowers it again.
With , the exact boundary counts follow from a geometric series:The first sum is empty at . Dividing by the corresponding boundary, rather than using one denominator for both, givesFor example, , whereas , yielding proportions and . For , the exact count is ; for it stays . Hence the proportion increases through each included block and decreases through each excluded block. These boundary subsequences give the actual limit inferior and limit superior:Since these differ, has no natural density. Its upper asymptotic density still records its largest limiting proportion.
For a subset of the positive integers, its upper asymptotic density isThe limit superior keeps the largest limiting proportion even when the running proportions oscillate. Because they lie in , this limit superior always exists in . If natural density exists, upper asymptotic density equals it.
The convention here uses , while natural density above uses . Replacing one interval by the other changes a count by at most one, so the proportions differ by at most and have the same limit superior. For the set without natural density above, the count in is six rather than five, because is included and zero is absent. Nevertheless its upper asymptotic density is exactly . The even positive integers have upper asymptotic density and the prime numbers have upper asymptotic density zero.
The useful feature is that a large proportion along arbitrarily large initial integer intervals already supplies structure. The Szemerédi theorem says that positive upper asymptotic density forces arithmetic progressions of every finite length, with positive common difference, even without an existing natural density. Szemerédi's 1975 paper resolved this general finite-length problem; it makes density a bridge from counting to additive structure. [ref]
https://doi.org/10.4064/aa-27-1-199-245. Endre Szemerédi, On sets of integers containing k elements in arithmetic progression, Acta Arithmetica 27, 199–245, 1975
An increasing sequence of integers has full density when its range has natural density one. Convergence in density of a sequence means that, for each fixed tolerance, the exceptional indices have natural density zero.
Every nonnegative integer is a sum of squares with four terms, with zero terms allowed. Precisely, for every integer , there exist nonnegative integers such thatAllowing arbitrary integer roots gives the same statement: changing a root to its absolute value leaves the resulting square number unchanged. Four is a uniform upper bound on the number of nonzero terms, rather than a demand for four positive terms. Repeated square numbers are allowed. Conrad states the positive case and explicitly explains the role of zero terms; follows by taking all four roots zero. [ref]
https://kconrad.math.uconn.edu/blurbs/ugradnumthy/descent.pdf. Keith Conrad, Proofs by Descent, Section 6, opening paragraph and Theorem 6.6
The small cases make the convention visible:In particular, could not be a sum of squares with four strictly positive roots, since each term would be at least one. Geometrically, a square of integer side length has area : the theorem says that any nonnegative whole-number total area can be split into at most four such square areas. It does not assert that those squares tile one larger square or a prescribed rectangle.
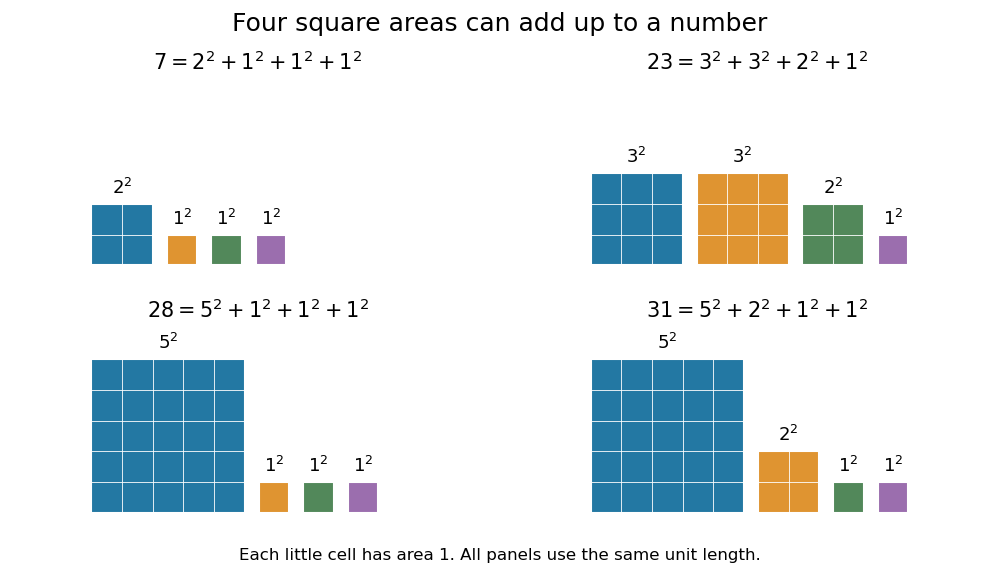
Why does the fourth term matter? Two square numbers do not suffice for : in modular arithmetic, a square number has remainder zero or one modulo four, so their sum cannot be three modulo four. The sum of two squares theorem gives a complete criterion for the positive integers representable with two terms. Even three terms leave gaps. A square number has remainder or modulo eight; adding three of these, with repetition allowed, never gives seven modulo eight. Thus cannot be sums of three square numbers, although Lagrange's four-square theorem represents all of them with four. This also proves that the bound four cannot be reduced to three.
The modulo-eight obstruction is not the only way that three terms can fail. For example, needs four: if three square numbers added to , their remainders modulo four would force all three roots even. Dividing by four would then express as a sum of three square numbers, contradicting the preceding calculation. These short checks explain the examples without requiring a full classification of sums of three square numbers.
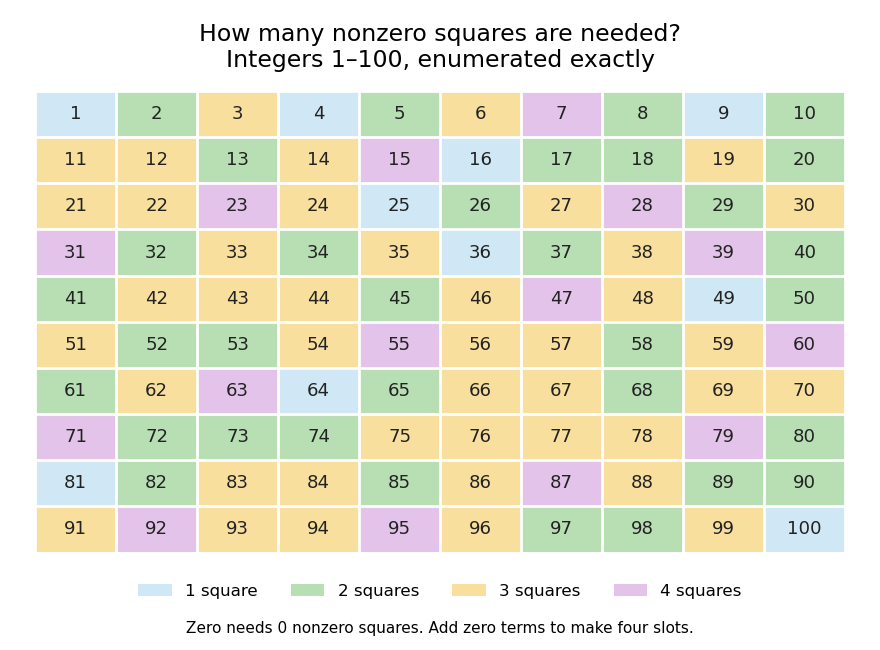
The practical benefit of Lagrange's four-square theorem is an existence guarantee for a family of Diophantine equations: for every nonnegative integer , the displayed equation has an integer solution. It does not specify a unique solution. For instance, . To find a representation by a finite search, enumerate and test the sum. The floor function supplies a finite bound because no single term can exceed , and sorting roots removes duplicate orderings without discarding any possible sum. The theorem guarantees that the search succeeds.
A greedy algorithm that repeatedly subtracts the largest available square number need not find four terms: for it chooses , while uses four. The appeal of the theorem is this gap between local choices and a global promise: individual square numbers become farther apart, and two or three terms leave arithmetic obstructions, yet four terms cover every nonnegative integer.
For historical orientation, Conrad dates Lagrange's four-square theorem to and identifies the memoir as Démonstration d'un théorème d'arithmétique: it appeared in the Berlin Academy's volume for the year , published in , pages –. Keeping the volume year and publication year distinct avoids an apparent conflict between dates. [ref]
https://kconrad.math.uconn.edu/blurbs/ugradnumthy/descent.pdf. Keith Conrad, Proofs by Descent, Theorem 6.6 and reference 11
Analytic number theory uses real analysis and complex analysis to study integers, primes, and arithmetic functions. It encodes discrete counting problems in sums, integrals, and Dirichlet series, then extracts information from convergence, oscillation, and singularities.
For example, the Euler product links the Riemann zeta function with all primes. Its logarithmic derivative has coefficients given by the Von Mangoldt function, turning prime counting into an analytic problem. The Prime number theorem is a central outcome: . The method is useful because analytic transformations can control an enormous discrete sum without enumerating every term.
An automorphic form is a function with arithmetic symmetries, together with analytic regularity and growth conditions. In a classical example, a modular form of integer weight on the modular group is a holomorphic function on the upper half-plane satisfyingand a holomorphy condition at the cusp. The transformation rule expresses compatibility with a group action, rather than ordinary periodicity alone: translation gives , while inversion gives .
The broader theory also permits nonholomorphic forms and groups beyond . In the adelic formulation for , automorphic forms are smooth, arithmetically invariant functions satisfying moderate growth and finiteness conditions under compact-group translations and central differential operators. The classical modular forms embed in this larger space. This connects number theory with representation theory and harmonic analysis.[ref]
The constant term of an automorphic form is its average along the periodic or unipotent direction associated with a cusp. In the basic period-one upper-half-plane setting,It is the zeroth coefficient of the Fourier series in . Despite the name, it may depend on . For a cusp width , use the normalized average after moving the chosen cusp to infinity.[ref]
Modular Functions and Modular Forms by James S. Milne. sections 2 and 4, cusp coordinates and Fourier expansions
For a weight-zero Maass form with and , periodicity makes the averaged -derivative term vanish. ThusIf and , the solutions are . At , the repeated root gives . A constant Fourier mode need not therefore be a constant function on the upper half-plane.
For the constant automorphic function , the constant term is one and . A Maass cusp form instead has identically zero constant term at every cusp. The condition concerns the whole coefficient function, rather than merely its value at one height.
For a finite-index subgroup of , a cusp is a -equivalence class of rational boundary points, including infinity:Geometrically it describes a noncompact end of the quotient of the upper half-plane. Adding these classes compactifies the corresponding modular curve. The added points describe boundary data of the quotient.[ref]
Modular Functions and Modular Forms by James S. Milne. section 2, cusps and the compactification of a finite-index quotient
The full modular group has one cusp: a reduced rational number is the image of infinity under a matrix with determinant one. In contrast, has inequivalent cusps represented by infinity and zero. A matrix sending infinity to zero must have , hence and odd , so it cannot belong to .
At infinity the cusp width is the least positive for which belongs to the effective stabilizer. The local coordinate tends to zero as . Filling in adds one point. At other cusps one first changes coordinates by a matrix carrying infinity to the chosen rational boundary point. Growth and constant term of an automorphic form conditions must be checked at each inequivalent cusp.
In the weight-zero convention, a Maass form for a discrete subgroup is a smooth function on the upper half-plane, invariant under , satisfying a hyperbolic Laplacian eigenvalue equation and specified growth conditions at the cusps:Additional conditions specify a cuspidal or square-integrable class. The sign of is a convention and must be stated.[ref]
Shifted polyharmonic Maass forms for PSL(2,Z) by Nickolas Andersen and others. Introduction, depth-one eigenfunction conditions; the paper uses its own Laplacian sign convention
The constant function is an invariant eigenfunction with and moderate growth, but is not cuspidal: its average along a horizontal period is nonzero. A Maass cusp form has zero such constant term at each cusp. The eigenfunction condition allows nonholomorphic automorphic forms, connecting arithmetic symmetries with spectral geometry.
A shifted polyharmonic Maass form is a smooth automorphic function that satisfies a generalized eigenfunction equation for a hyperbolic Laplacian. In weight zero, choose the convention and requirefor an integer , together with automorphy and the specified growth conditions at each cusp. Moderate growth means at most polynomial growth in cusp coordinates. The weight- version replaces by the corresponding Weight-k hyperbolic Laplacian and uses the weight- transformation law.[ref]
Shifted polyharmonic Maass forms for PSL(2,Z) by Nickolas Andersen and others. Introduction, equations 1.1–1.2 and growth hypothesis
The least possible is the exact depth. For this is an ordinary eigenfunction condition; higher depth allows a chain of generalized eigenfunctions. It is not merely an equation with a different eigenvalue. The cited paper uses the opposite Laplacian sign, so its eigenvalue parameter is the negative of the one used here.
For an illuminating construction, let a nonholomorphic Eisenstein series satisfy . At a regular value , differentiate in . The function obeysThe first right-hand side is nonzero, so this gives depth two. Parameter differentiation introduces a generalized eigenfunction while preserving automorphy.[ref]
In the integer-depth convention, a polyharmonic Maass form is a smooth automorphic function annihilated by a positive integer power of its weight-appropriate hyperbolic Laplacian, with specified growth at the cusps. In weight zero, using , the equation is . It is the zero-shift case of a shifted polyharmonic Maass form. Exact depth is the least such integer . Some refined conventions also use half-integer depths, so the convention must be stated.[ref]
Polyharmonic Maass forms for PSL(2,Z) by Jeffrey C. Lagarias and Robert C. Rhoades. Introduction and harmonic-depth convention
A global depth-two example comes from the finite part of a completed nonholomorphic Eisenstein series. Near , writewhere is a nonzero constant and . Comparing constant Laurent coefficients gives , hence but . The finite part is automorphic and has moderate growth.[ref]
This demonstrates why higher depth is substantive: the space contains functions that are not harmonic but become harmonic after one application of the Laplacian. Merely solving a local differential equation is insufficient; automorphy and cusp growth remain part of the definition.
A Maass cusp form is a nonzero Maass form with vanishing constant term of an automorphic form at every cusp. For weight zero on the modular group , it is a smooth, -invariant function on the upper half-plane, square-integrable on a fundamental domain with measure , satisfyingThe integral condition describes the cusp at infinity; other groups require the corresponding condition in coordinates at each cusp.[ref]
Rigorous computation of Maass cusp forms of squarefree level by Andrei Seymour-Howell. Section 2.1, definition specialized to level one and stated Laplacian sign
Translation invariance gives a Fourier series. When , its decaying modes have the formwhere is a Modified Bessel function of the second kind. The absent term expresses cuspidality. The Fourier coefficients must also satisfy the full automorphic symmetry.[ref]
Rigorous computation of Maass cusp forms of squarefree level by Andrei Seymour-Howell. Section 2.4, even and odd Fourier expansions, rewritten in complex exponential notation
The constant function is a useful test: it satisfies the symmetry and has eigenvalue zero, but its horizontal average is , so it is not a Maass cusp form. The extra condition isolates oscillating eigenfunctions connecting arithmetic symmetry with spectral geometry.
A smooth automorphic form is an automorphic form whose archimedean variables are infinitely differentiable, without necessarily being holomorphic. Conventions differ over whether compact-group finiteness is included or one takes a larger smooth representation space. In the classical finite-vector convention on , one asks for left invariance under an arithmetic subgroup , moderate growth, finite-dimensional span under right translations by , and finiteness under the centre of the universal enveloping algebra.[ref]
Classical Modular Forms as Automorphic Forms by Matthew Emerton. Definition 5.1 and section 7, general forms versus holomorphic forms
The constant function on is an example: it is smooth, bounded, -invariant and annihilated by positive-order invariant differentiation. More interesting examples come from Maass forms, whose Laplacian eigenfunction condition replaces holomorphy. Smoothness is therefore a regularity requirement, not a claim that the Cauchy-Riemann equations hold.
The circle method represents a weighted additive count as an integral of products of exponential sums against a character. Near rationals with small denominator, major arcs produce a structured main term involving a singular series and an archimedean singular integral. Away from those rationals, minor arcs require cancellation bounds. The partition and approximation estimates depend on the problem; a formal integral alone is not a positivity proof.
Every sufficiently large odd integer is a sum of three primes, with repetitions allowed. The weighted count is asymptotic to . Siegel–Walfisz theorem controls the major arcs, and Type I/II estimates for the prime exponential sum make the minor arcs negligible. Removing prime-power contributions gives genuine prime representations. This is the sufficiently-large theorem, not by itself a proof for every small odd integer.
A singular series assembles the local congruence densities in an additive counting asymptotic. For three prime summands it is , with Ramanujan sum . Its Euler product vanishes for even and has a uniform positive lower bound for odd . Different additive problems have different local factors, so this is a specific instance rather than a universal formula.
Minor arcs are the complement of the specified major arcs. They contribute an error only when a suitable pointwise or mean-value cancellation estimate is proved; their name does not imply that their measure is small.
In a circle-method problem of scale , major arcs are neighborhoods of reduced rational points with small denominator, where the relevant exponential sum is approximated using distribution in residue classes. For the three-prime problem one may take and , with suitably fixed .
An L-function is an arithmetic function given initially by a Dirichlet series and often an Euler product, with analytic continuation and a functional equation in important cases. Dirichlet L-functions and L-functions of cusp forms are basic examples; p-adic L-functions interpolate suitably modified special values.
The Hasse–Weil zeta function of an algebraic variety over a number field is assembled from local point-counting factors at finite places. At a good place with residue field of size , the factor is , where . Defining all bad-place factors requires a specified integral model or convention. The zeta function of an elliptic curve over a finite field is a local factor, rather than this global product.
For an elliptic curve over a number field, its Hasse-Weil L-function is the product of the local factors determined by its Tate module. At a good finite place, the factor is , with . At a bad place use the inertia-invariant subspace and an auxiliary prime different from the residue characteristic. For a CM elliptic curve with all endomorphisms defined over the base, this factors as the product of the two conjugate Hecke L-functions.
The L-function of a Hecke character is initially the displayed Euler product over prime ideals away from its conductor. The equivalent Dirichlet series sums over integral ideals prime to the conductor. For a CM elliptic curve with its endomorphisms defined over the base, its Hasse-Weil L-function factors into the two conjugate Hecke L-functions.
A p-adic L-function is a -adic analytic function or measure interpolating suitably adjusted special values of an L-function. The Kubota-Leopoldt p-adic L-function is the basic example attached to a Dirichlet character.
For an even Dirichlet character , the Kubota-Leopoldt function interpolates generalized Bernoulli values with the relevant Euler factor and Teichmüller character adjustment. If , it can be encoded by an integral power series. For , the -ramified convention is . The trivial character requires separate treatment of the pole.
On , this element of the total quotient ring of the Iwasawa algebra becomes an integral measure after multiplication by every difference . Its even moments interpolate the displayed Euler-corrected zeta values. Its trivial-character component has a pole, so the pseudomeasure itself must not be treated as an element of the integral group algebra. Multiplication by the augmentation ideal removes the pole.
There is an absolute finite exponent bounding the least prime in any reduced arithmetic progression by a constant times . The multiplicative large sieve inequality is one of the tools in proofs of this theorem.
A sum of character values over a set. Arithmetic cancellation, rather than the termwise absolute-value bound, is the useful feature. A Gauss sum of a Dirichlet character is a weighted example, and the Pólya–Vinogradov inequality bounds interval sums.
For a primitive nonprincipal Dirichlet character modulo , finite Fourier inversion theorem and the primitive Gauss magnitude give this bound uniformly in the interval. Bound the exponential sums by and sum the resulting harmonic series. The general Gauss identity follows from the prime-power identity by the Chinese remainder theorem.
A prime sum is a summation indexed by prime numbers, for example . The indexing restriction distinguishes it from a sum over all positive integers.
For every there is such that, for ,Here is the Chebyshev function in an arithmetic progression and is the Euler totient function. Partial summation gives the corresponding result for the prime-counting function and the offset logarithmic integral function. The theorem controls the total error over many moduli; it need not give the same bound for each individual modulus.
Let . For , the Brun–Titchmarsh theorem and Cauchy-Schwarz inequality giveWrite each summand as , then use .
A finite sum of complex exponentials, such as with , is an exponential sum. Cancellation in an exponential sum between its terms can make it much smaller than the sum of their absolute values.
Taking a finite difference lowers the degree of a polynomial phase. For , expand by shifts and apply the Cauchy-Schwarz inequality to those shift sums. This gives , where enforces that lie in . Although individual terms can be complex, the entire sum is real and nonnegative because it equals a sum of squares. For , the phase is .
For a real degree- polynomial with leading coefficient , , and coprime integers satisfying , the displayed bound applies to its exponential sum over . Repeated Weyl differencing reduces the phase to slope . A geometric-sum estimate, the subpower bound for the divisor function and the reciprocal fractional-part sum near a rational complete the estimate. The arbitrary positive exponent absorbs divisor bounds and logarithms.
If and with , the displayed estimate holds. Twice applying Weyl differencing bounds by . Group by and use the subpower bound for the divisor function. The reciprocal fractional-part sum near a rational bounds the resulting sum by . Take fourth roots, absorbing logarithms into when ; for larger the trivial bound suffices. Leiden lecture notes, Section 7.2 develop this cubic differencing estimate.
For and every , the displayed estimate bounds a mean value of a polynomial exponential sum. For cubes its eighth-moment bound is . It complements pointwise Weyl differencing estimates: a ninth moment over a region is bounded by its supremum there times this eighth moment. Leiden lecture notes, Section 8.1 give the cubic formulation.
Write and . Character orthogonality gives . For , fix the difference . If , there are choices for the two equal pairs. If , any solution has ; fixing this divisor gives a quadratic equation for , hence at most two choices. The subpower bound for the divisor function yields .
The twice-differenced inequality in Weyl differencing reads , with counting triples for which and all four shifted arguments are in . Thus , and for : the product divides , and the remaining equation determines . The Fourier coefficients of are nonnegative counts, with and . Multiply the inequality by and integrate. It follows that , after choosing the divisor-bound exponents small enough.
For in the finite field , put . The multiplicative group of a finite field is cyclic, and character orthogonality expresses the number of th roots of as . The trivial character contributes , cancelling the term. Each of the remaining Gauss sums of Dirichlet characters has modulus , by the prime-field character Gauss sum identity. Consequently .
For , character orthogonality counts representations of by . Its zero-frequency term is . The power Gauss sum over a prime field bounds the other terms in total by , strictly less than when . Every residue class therefore has a representation.
A quadratic exponential sum has a polynomial phase of degree two. Its multiplicative derivative at lag has the linear phase up to a constant factor. This degree reduction lets the Van der Corput inequality for finite scalar sequences reduce its size to estimates for finite geometric series.
For coprime integers with and , expand the squared quadratic exponential sum by its difference . The exponential geometric sum bound gives . In each block of length at most , the rotations are separated by at least : the reduced denominator of is at least , and the approximation error between two block points is at most . The separated reciprocal-distance sum bounds each block by . There are blocks, giving the displayed inequality. For bounded the trivial estimate supplies the same conclusion.
By orthogonality of integer Fourier modes, this integral counts pairs of -tuples with the same first power sums. Diagonal pairs give . There are possible moment vectors; the Cauchy-Schwarz inequality gives . Upper bounds measure how much arithmetic coincidence remains beyond these necessary contributions, and enter the Vinogradov mean-value method for a bilinear exponential sum.
Expand moments of the inner sum and group equal power-sum differences. Their multiplicities are bounded by through the Cauchy-Schwarz inequality. Two applications of the Holder inequality yield a bound for containing and a product of short geometric-sum bounds over the moment differences. Thus a sharp mean-value estimate combines with rational approximation or spacing of the coefficients to prove cancellation. When all coefficients are integers, , so mean-value estimates alone cannot force cancellation.
Translating an integer interval by changes a sum of unit-modulus terms by at most . Averaging gives the displayed formula. For , , expand to degree . Its remainder is at most . This reduces the logarithmic exponential sum to bilinear polynomial sums while keeping explicit boundary and approximation errors.
For a real phase with continuous monotone derivative and , the sum-integral discrepancy has the displayed uniform bound. Periodization and the Dirichlet-Jordan convergence theorem express it as symmetric nonzero Fourier modes. Integration by parts gives endpoint terms and reciprocal-derivative variations. Monotonicity bounds their total variation by . Pairing the leading endpoint terms reduces them to the uniformly bounded sine series. The exclusion of integer nonzero frequencies is essential.
Articles were limited to the first 100 out of 991 total.
Articles by others on the same topic

Number theory is a branch of mathematics that deals with the properties and relationships of numbers, particularly integers. It is one of the oldest areas of mathematics and has a rich historical background, dating back to ancient civilizations. Number theory explores various topics, including: 1. **Prime Numbers**: The study of prime numbers (integers greater than 1 that have no positive divisors other than 1 and themselves) and their distribution.



