An expected value is the probability-weighted arithmetic mean of a real-valued random variable. On a probability space , its general definition is the Lebesgue integralwhere is the probability distribution of . For an integrable random variable, this is a finite real number. With a probability mass function , use ; with a probability density function , use . These are two ways of computing the same weighted average, rather than different definitions for different experiments.
For example, suppose takes the values with probabilities . ThenThe most likely outcome is , and is not a possible outcome at all. The expected value summarizes all outcomes and their weights; it need not predict the result of one trial. Geometrically, placing masses equal to the probability masses at the outcome positions gives a center of mass at , since . This balance-point interpretation also explains the connection to a weighted arithmetic mean. [ref].
For the dimensionless random variable with probability density function on , the expected value is . Integrating the probability density function itself gives one; to compute the expected value, multiply by the outcome first. [ref]
https://ocw.mit.edu/courses/18-05-introduction-to-probability-and-statistics-spring-2022/mit18_05_s22_class06-prep-a.pdf. Orloff and Bloom, expectation for continuous random variables
.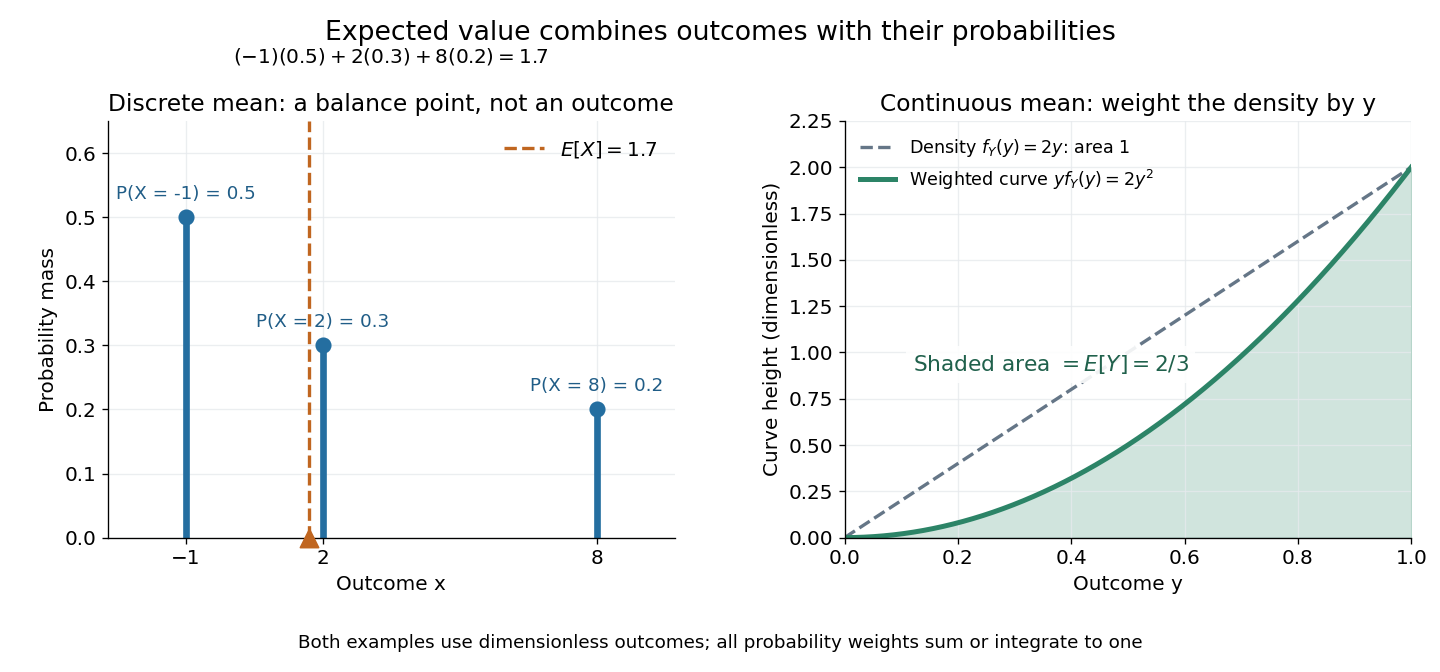
Expected value balances probability masses, or integrates outcomes weighted by a probability density function
. The left panel's dashed line marks , even though the only possible outcomes are . In the right panel, the shaded area under is ; the area under the dashed probability density function is one. Both examples use dimensionless outcomes. Details.Why is this useful? Linearity of expectation lets us compute an average total by adding average contributions, even for dependent random variables. And for independent and identically distributed integrable random variables, the strong law of large numbers says their sample mean approaches their common expected value almost surely. The theorem supplies the link to repeated observations; the weighted-average definition itself does not promise that any particular finite run will be close to the expected value.
There is a useful historical connection to valuing uncertain rewards. In his 1657 De ratiociniis in ludo aleae, Christiaan Huygens assigns the value to equally likely rewards , and when they have equally likely chances. These are the finite weighted-average formulas for expected value. His opening discussion asks how to divide the stakes when a game stops before completion, connecting probability to a concrete question about an unfinished contest. [ref]
https://math.dartmouth.edu/~doyle/docs/huygens/huygens.pdf. Huygens, De ratiociniis in ludo aleae, 1657; reprint of the 1714 English translation, introduction and Propositions I–III
.The expected value of a numerical characteristic under the target population's probability distribution, when it exists. A sample mean estimates this fixed statistical parameter from observed data; it is not itself the population value.
The law of the unconscious statistician computes the expected value of a measurable function of a random variable directly from the original probability distribution. If is an integrable random variable, thenUse for a probability mass function, or for a probability density function. There is no need to derive the probability distribution of first. The identity is the integration rule for a pushforward measure, and also holds with an infinite value when is nonnegative. [ref]
https://ocw.mit.edu/courses/res-6-012-introduction-to-probability-spring-2018/pages/part-i-the-fundamentals/. Tsitsiklis, Introduction to Probability, Lecture 5: the expected value rule
.For taking with probabilities , choosing gives . Its variance is therefore . Squaring the expected value would instead give , because squaring does not commute with averaging.
For a bounded possibly nonmeasurable real function on a probability space, its outer expectation is the infimum of expected values of measurable majorants. Its inner expectation is . They agree with the usual expected value for measurable . This permits function-space convergence in distribution for an empirical distribution process whose paths are not Borel-measurable in a nonseparable norm topology: both expectations of each bounded continuous test functional must approach its ordinary expectation under the tight measurable limiting law.
For independent integrable variables, . Tonelli theorem first gives ; then Fubini's theorem factors the signed joint integral.
A mean-zero function has expectation zero with respect to the specified probability measure. On a finite set with uniform measure this means . A balanced subset indicator is an example. In Fourier analysis on a finite group, this is equivalent to vanishing of the component at the trivial representation.
A real or complex random variable is integrable when . This is integrability with respect to its probability measure, and ensures that its expected value is finite. A bounded random variable is always an integrable random variable; so is the example taking , for which .
For a real random variable, put and , its positive part and negative part. Each has a nonnegative Lebesgue integral, possibly infinite. The expression is defined when at least one of these two expected values is finite; if both are infinite, the expected value is undefined. Integrability makes both finite. A nonnegative random variable can have expected value , even though it is not an integrable random variable.
The standard Cauchy distribution is a useful warning. With its probability density function , the positive contribution is , which tends to infinity; the negative contribution has the same magnitude. Integrating symmetrically over gives zero for each , but this cancellation does not define an expected value. The Cauchy sample mean has an unchanged distribution, showing why the integrability hypothesis in the strong law of large numbers matters.
For an integrable random variable, conditional expectation preserves integrability, and linearity of expectation can safely combine finite averages without forming .
Let have standard normal distribution, let be an integer and let . A finite expected value of requires absolute integrability, which reduces to finiteness ofFor it is finite exactly when . For every it is finite exactly when : the higher power dominates the negative quadratic when , and for the integrand is bounded by . In the finite cases the signed expected value is zero by symmetry. Otherwise each signed part has infinite integral; a formal symmetric cancellation is only a Cauchy principal value.
More generally, a moment is an integral weighted by a power of a coordinate against a measure or density; raw, central, and standardized moments are distinguished by the coordinate and normalization used.
The fourth moment is . Its finiteness is equivalent to square integrability of . For centered variables, dividing it by the squared variance gives kurtosis.
A probability distribution is moment-determinate if its moments uniquely specify it among probability distributions. A moment-generating function finite in a neighbourhood of zero is a sufficient condition. The standard normal distribution is moment-determinate.
Skewness is the standardized third central moment of a probability distribution. A symmetric distribution with finite third moment has zero skewness. Cosmology also uses the reduced skewness , which differs from the standardized skewness by a factor of .
The variance measures the mean squared distance of a random variable from its expected value. For a real square-integrable random variable ,The square prevents positive and negative deviations from cancelling. It also gives the variance squared units: if measures a length in metres, its variance has units of square metres. Its nonnegative square root is the standard deviation, which has the same units as .
For example, let take , and with equal probabilities. Its expected value is zero, but its variance is , and its standard deviation is . The constant random variable zero has the same expected value and zero variance: a mean alone does not describe the spread. The variance is zero exactly when almost surely.
The variance is useful because squared deviations interact neatly with linear combinations. The covariance supplies the cross terms when combining different random variables, and a covariance matrix organizes those terms for many variables. The characterization of variance as the minimum mean squared error of a constant also explains why the expected value is the best constant prediction under squared error.
For independent identically distributed random vectors with finite second absolute moments, expand . Their independence makes , proving the identity. The right side is the sum of the coordinate variances. Applied to the displacement in an optimal transport plan, it separates motion of the barycenter of a measure from relative particle motion.
For a finite population with arithmetic mean , its variance is . It averages squared deviations over the whole population.
For a nonnegative count with positive mean, the Fano factor compares its variance to its mean. A Poisson distribution has factor one. Correlated production bursts or weak restoring feedback can give factors larger than one even at large molecular copy number.
// Target: mathematical-biology.bigb
For a square-integrable real random variable ,Thus the unique best constant predictor is , and the minimum mean squared error is .
The conditional variance measures the remaining squared uncertainty after specified information has been used to form a conditional mean. For a real square-integrable random variable and a sub-sigma-algebra , let . ThenIt is a -measurable random variable, nonnegative almost surely, rather than necessarily a single number. With the information , its value is the variance in the group identified by . Its expected value is the mean squared error of predicting by its conditional mean.[ref]
In the exact mixture distribution in law of total expectation, group contains around mean two, and group contains around mean eight. Both groups have conditional variance four because their deviations from their own means are with equal probabilities. Therefore . Meanwhile, the two group means have variance . The law of total variance givesDirect calculation gives and , checking the decomposition.
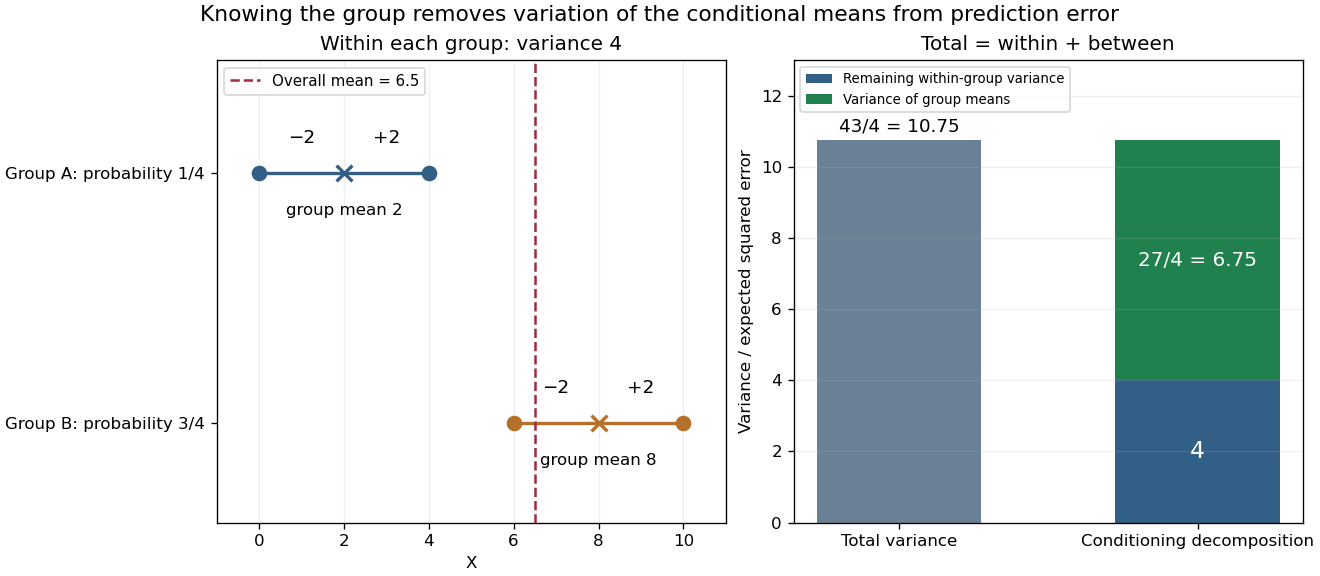
For any square-integrable -measurable predictor , the error identity isThe cross term vanishes because . Thus using the conditional mean minimizes mean squared error, while conditional variance quantifies what this information still cannot predict. This is the orthogonal projection interpretation in L2 space.[ref]
For square-integrable and nested information , let and . The predictor is also -measurable, so the conditional variance error identity givesMore information cannot increase the average best squared prediction error. Equality holds exactly when the two conditional means agree almost surely; additional information can change the conditional distribution without changing its mean.
This is an averaged statement. Take with equal probabilities, and learn only whether is zero. The unconditional variance is . In the nonzero group, the conditional variance is , which is larger; in the zero group it is zero. Their weighted average remains . Both groups have conditional mean zero, so the extra information has not improved squared-error prediction, even though it has revealed whether the outcome is extreme or central. An individual group's conditional variance need not decrease.
For independent random variables with , writeThen . Hence converges in exactly when the scalar Cesàro means converge.
Let each be uniform on , with arbitrary dependence. For centered unit-norm , putThenPartition into equal intervals and test normalized differences of two interval indicators. Averaging over the two intervals reduces the claim to for their occupancy counts, and then let .
The covariance measures the average product of two centered deviations. For real square-integrable random variables and ,Deviations with the same sign contribute positively; deviations with opposite signs contribute negatively. Their magnitudes and probabilities determine the net result. Taking recovers the variance. The definitions and algebraic properties are presented in Orloff and Bloom, MIT 18.05, Covariance and Correlation, sections 2–2.1.
For a worked example, let be independent random variables, each equally likely to be , or , and put . All nine pairs have probability . The expected values are zero, while linearity of covariance and the vanishing covariance of independent random variables giveThe shared term makes large accompany large on average. Replacing by reverses the covariance to without changing either variance.
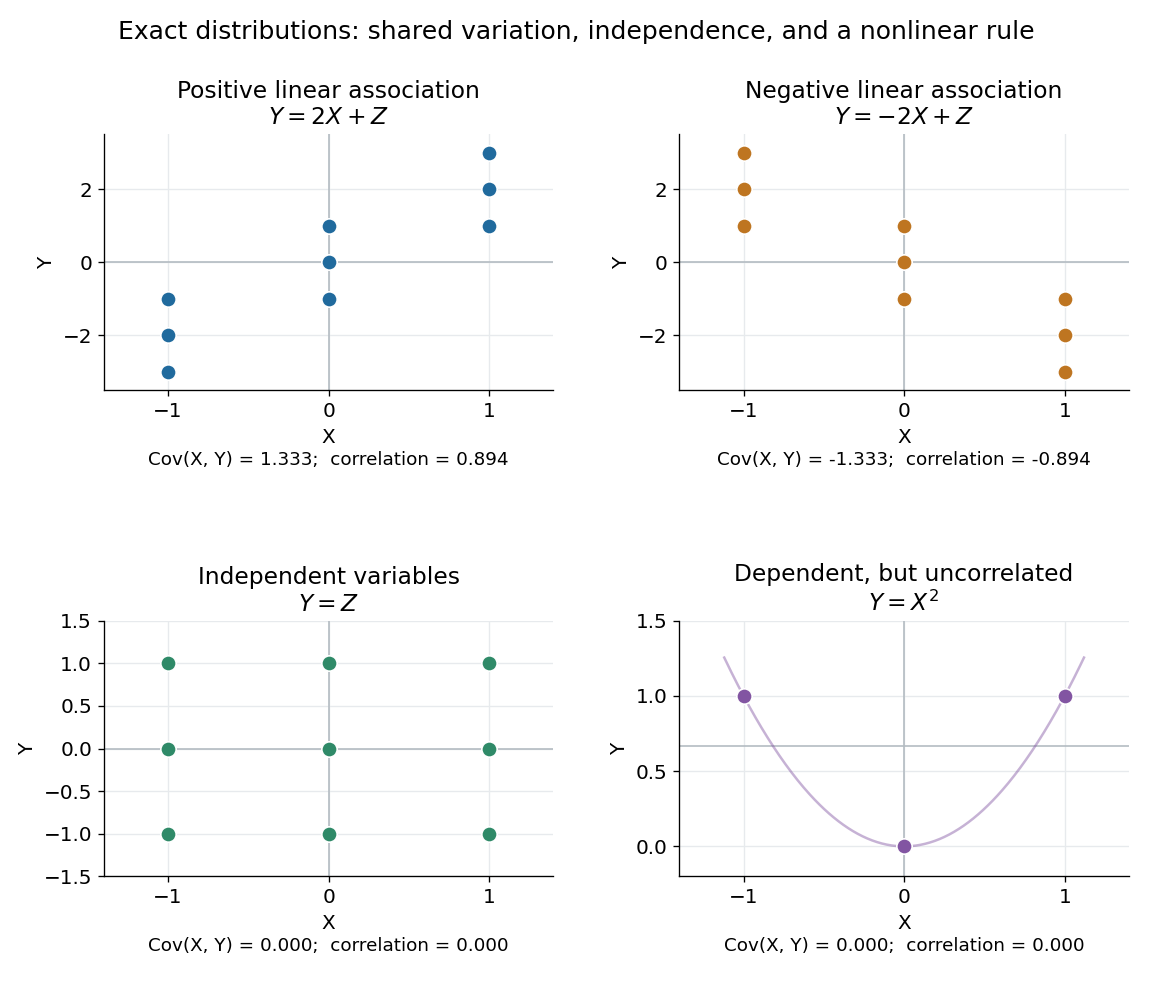
Positive, negative, independent, and nonlinear relationships have different covariance behavior
. In the first three panels, and independently take , and with equal probabilities; each point has probability . In the last panel, , and the three marked outcomes each have probability . The thin curve shows that quadratic function. Its zero covariance leaves strong nonlinear statistical dependence visible. Details.The covariance is useful whenever deviations are added or subtracted. Expanding the square givesFor the worked model, these are and . Positive covariance increases variation in the sum while reducing variation in the difference: the same shared fluctuation reinforces one combination and partly cancels in the other. The identity applies beyond independent random variables.
The size of a covariance depends on the measurement scale. For constants , linearity of covariance gives . Adding offsets has no effect; rescaling either measurement rescales the covariance. The Pearson correlation coefficient divides by both standard deviations to describe the standardized linear relationship.
For mutually independent square-integrable random variables , factor the joint moment as , then subtract the product of the two means. This proves the formula. Sharing one factor can therefore produce nonzero covariance even when all original factors are independent. Products of disjoint groups of independent factors are themselves independent random variables.
For square-integrable random variables, expand and into their conditional expectations and their centered conditional residuals. The cross terms vanish by the law of total expectation, giving the displayed covariance decomposition. Conditional independence can therefore coexist with positive unconditional covariance from a shared latent variable.
If is nondegenerate, is strictly increasing and the relevant products are integrable, an independent copy gives . The integrand is positive exactly when , so the covariance is strictly positive. The same argument applies within each conditional law and yields a positive terminal stock hedge for an attainable increasing payoff.
For square-integrable random variables, . It is a -measurable random variable. Replacing by its conditional expectation given a larger sigma-field leaves this covariance unchanged when is measurable with respect to that larger sigma-field. This observation underlies recovery of a martingale-transform integrand by conditional covariance.
For paired observations , the sample correlation coefficient isIt is the normalized inner product of the centered data vectors, or the sample covariance divided by the product of the corresponding sample standard deviations. The choice of divisor or cancels when used consistently in all three quantities. It is undefined if either centered data vector is zero, which occurs when that variable is constant in the observed statistical sample.
For and , both sample means are . The sum of centered products is , and each sum of centered squares is , hence the sample correlation coefficient is . This is a summary of these four observed pairs; it is not automatically the population Pearson correlation coefficient. Philip Stark, Computing the correlation coefficient explains the centered and standardized calculation.
A sample correlation matrix rescales a sample covariance matrix to unit diagonal, for variables with positive sample variance. Its off-diagonal entries are sample correlation coefficients. Strong correlations between predictors can indicate multicollinearity, but pairwise correlations alone do not exclude higher-order linear dependence.
For square-integrable complex random variables, the Hermitian covariance is . Its diagonal is nonnegative and equals . The conjugation distinguishes it from the pseudo-covariance.
For a centered complex random variable , the pseudo-covariance is . Together with it determines the real covariance matrix: , , and .
For independent standard normal random variables , define the displayed errors for . Each has mean zero and variance one. Nonadjacent errors depend on disjoint sets of independent variables. Adjacent covariances vanish because their product contains an independent centered factor. Thus their covariance matrix is .
They are nevertheless dependent: the Gaussian fourth moment gives , and hence . Constant variance and zero pairwise covariance can conceal dependence in magnitudes. This is useful when interpreting a residual plot in linear regression.
For two Bernoulli random variables with joint probabilities in the order , their covariance is . Zero covariance fixes the probability to the product of its marginals; subtracting this from each marginal fixes all three remaining joint probabilities to their products. Thus uncorrelated random variables taking only zero and one are independent, including degenerate marginals. The implication is special to this two-point setting and fails for general distributions.
For a real random vector with finite second moments, its covariance matrix collects all pairwise covariances:The diagonal entries are variances. The covariance matrix is a symmetric matrix and a positive semidefinite matrix, because for every real vector ,Thus one matrix describes the variance of every linear combination of the coordinates. It is a positive-definite matrix exactly when no nonzero linear combination is constant almost surely. A deterministic linear relation produces a zero eigenvalue.
For example,has unit coordinate variances, covariance , and eigenvalues and . Its unit eigenvectors and describe directions of greatest and least projected variance. For a unit vector , direct multiplication gives : the variation in the sum direction is nine times that in the difference direction.
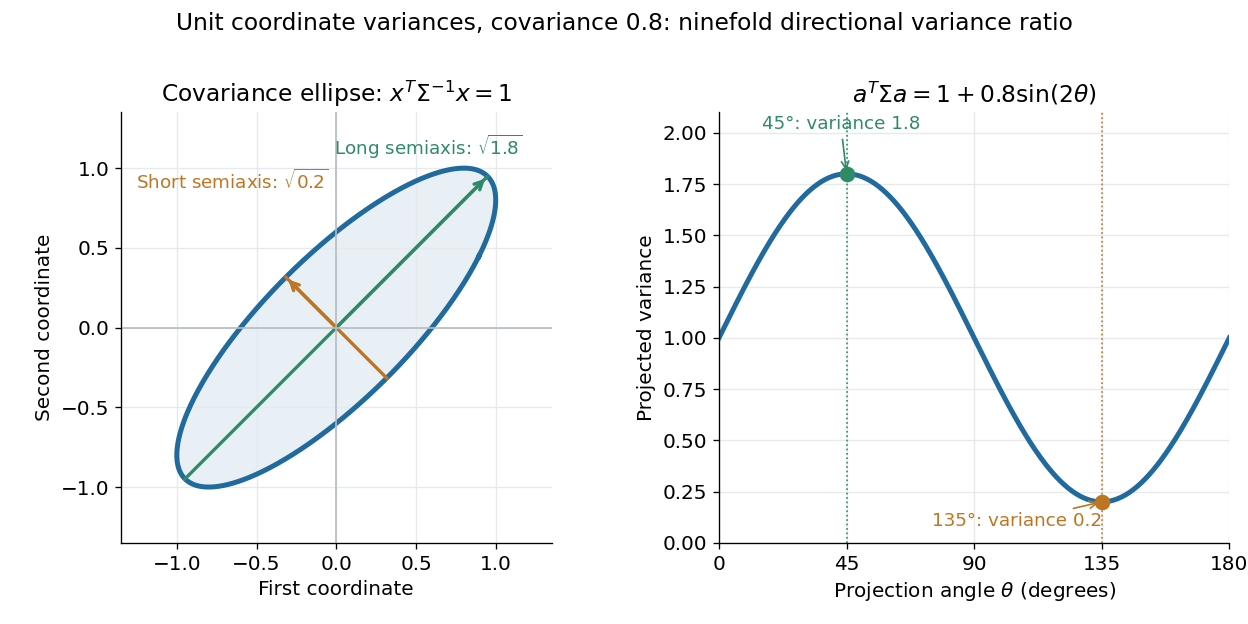
The spectral theorem supplies an orthonormal basis of these directions. This connects covariance matrices to principal component analysis: its leading eigenvector identifies the unit-direction projection with the largest variance. For a linear transformation , the transformed random vector has covariance matrix , so uncertainties propagate through a linear model by matrix multiplication.
For a two-dimensional positive-definite covariance matrix , the centered covariance ellipse is the image of the unit circle under its positive definite square root of a matrix. Equivalently, it satisfies . Its semi-major and semi-minor axes have lengths given by the square roots of the larger and smaller eigenvalues, along the corresponding eigenvectors. The ellipse encodes a second-moment geometry; a probability-coverage interpretation needs additional information about the probability distribution and the chosen scale.
For a random vector with covariance and positive coordinate variances, let . Its correlation matrix is the covariance of , so it is positive semidefinite with unit diagonal. Each entry is the correlation of the corresponding pair of variables. In particular , explaining why an eigenvalue in correlation-based principal component analysis represents that eigenvalue divided by of the total variance. The empirical version is the sample correlation matrix.
This unit-variance covariance matrix has eigenvalue on the constant-vector direction and eigenvalue on its orthogonal complement. It is positive semidefinite exactly when . For positive , the first population principal component is the normalized sum of the centered variables.
For a positive-definite covariance matrix, this is Euclidean distance after whitening. It accounts for both scales and correlations and is invariant under consistent nonsingular linear changes of coordinates. Estimating the covariance can be unstable with small samples, and a singular covariance requires restricting to a nonsingular subspace rather than claiming an ordinary metric on the full space.
A compound-symmetry covariance matrix has a common diagonal entry and a common off-diagonal entry: . For a group of size , its within-group eigenvalue is and its constant-direction eigenvalue is . Thus and characterize positive semidefiniteness. When , an independent shared random intercept plus individual noise realizes this covariance. A group mean has variance ; a difference of two disjoint subgroup means within the same group cancels .
For a unit vector and , a rank-one covariance spike is the covariance matrix . Its eigenvalue is in the direction and one on the orthogonal complement. It arises by adding an independent scalar normal distribution signal to a standard Gaussian random vector.
The sample mean and covariance estimate the first two moments of a random vector from repeated observations.
The uncentered empirical second-moment matrix averages the outer products of the observations. Its expected value is . It is an unbiased estimator of the covariance matrix when the population expected value is known to be zero. It differs from a sample covariance matrix centered at the sample mean.
For independent samples of sizes from populations with means and finite variances , the difference of their sample means has expected value and variance . This uses independence between and within the samples. With dependent samples, a covariance term is required instead.
Partition a sample into two disjoint groups with fixed positive sizes , and let . The overall sample mean is the weighted meanSubtracting gives the displayed identity. The subgroup and overall sample means share observations, so they are not independent. If the two disjoint groups are sampled independently, thenThus treating the subgroup and the combined sample as two independent samples uses the wrong standard error. Equality of the subgroup and overall population means is equivalent to equality of subgroup and complement means when both groups have positive weight, but the sampling distribution must respect the shared observations.
For independent and identically distributed observations with finite positive variance, the central limit theorem, consistency of the sample variance and Slutsky's theorem give . Under an independent normal distribution sample it instead has the exact finite-sample Student t-distribution with degrees of freedom, as described by the studentized normal sample mean. The asymptotic statement does not require normal individual observations.
For observations , the sample covariance matrix is , or the same sum divided by under the unbiased convention.
If and , then . In particular full column rank of raw does not ensure a nonsingular centered sample covariance matrix. When is singular, its Gaussian precision profile likelihood has no finite maximizer: increase precision along a nonzero null vector.
For paired scalar observations , their sample covariance is , or the same sum divided by under the unbiased convention. It is an off-diagonal entry of the sample covariance matrix of the paired vectors.
The effective rank measures the total variance of a covariance matrix relative to its largest directional variance.
For independent centered Gaussian vectors with covariance and uncentered sample covariance , with probability at least ,
The precision matrix is the inverse of a nonsingular covariance matrix. For a multivariate normal distribution, a zero off-diagonal precision entry encodes conditional independence of the corresponding coordinates given all remaining coordinates.
For a nonsingular multivariate normal distribution with precision matrix , fixing all coordinates except leaves a density proportional to after completing the square. Thus its conditional variance is the reciprocal diagonal precision entry. This is conditioning on every other coordinate, not the marginal variance .
In a Gaussian graphical model, regressing component on the others gives the displayed coefficients, residual variance and intercept . Opposite directions have identical zero patterns and signs because is symmetric with positive diagonal, but generally unequal coefficient magnitudes.
For independent multivariate normal observations with unknown mean and nonsingular covariance, profiling the mean at its sample value gives negative log-likelihood proportional to over . The sample covariance matrix uses divisor . Its minimizer exists exactly when , and is then .
If a positive-definite matrix is the precision matrix of a multivariate normal distribution, draw independent and solve . Then has covariance . This avoids forming the inverse and exploits a banded Cholesky decomposition when is banded.
The constrained minimization estimator minimizes subject toIts constraints and objective separate by columns. Feasibility of the true precision matrix and elementary matrix-norm inequalities yield entrywise error bounds under an entrywise covariance-estimation bound.
The graphical Lasso estimates a sparse precision matrix by minimizing a Gaussian negative log-likelihood plus an entrywise penalty.
For a Graphical Lasso solution with inverse , the unique minimizer of , , is . The inverse identity gives , and the off-diagonal Graphical-Lasso Karush-Kuhn-Tucker conditions become the column Lasso conditions because the corresponding signs are opposite.
For objective , the KKT conditions are with .
The Pearson correlation coefficient is the covariance divided by the product of the standard deviations. For real random variables with finite, strictly positive variances,It is the expected value of the product of the two centered variables after dividing each by its standard deviation. The Cauchy-Schwarz inequality gives . This removes measurement units, while retaining the direction and strength of the linear relationship. Constant random variables have zero standard deviation, so their Pearson correlation coefficient is undefined.
For the covariance model , with independently uniform on , the calculation givesThe positive correlation is less than one because the independent term introduces extra variation. For the correlation is . Both examples appear in the covariance diagram.
For nonzero real , the correlation of and is . Positive rescaling and added offsets therefore leave the correlation unchanged; reversing one scale reverses its sign. Equality means that one random variable is an affine function of the other almost surely, with a nonzero slope of the corresponding sign. This is the equality condition in the Cauchy-Schwarz inequality, and includes perfect positive correlation.
Zero correlation says that the centered variables are orthogonal in their square-integrable inner product. It permits nonlinear statistical dependence, as the example in uncorrelated random variables demonstrates. More generally, a correlation is a statement about a joint probability distribution; identifying effects of interventions is the separate task of causal inference. This distinction keeps an observed association from being mistaken for a demonstrated mechanism.
An early source for standardized association is Francis Galton's 1888 paper “Co-relations and their Measurement, chiefly from Anthropometric Data”. He compared stature and forearm measurements and changed each measurement to units of its own variability so the two regression directions could be compared. His scale used probable error, so it should not be identified word for word with the modern standard deviation formula above. [ref]
https://galton.org/essays/1880-1889/galton-1888-co-relations-royal-soc/galton_corr.html. Galton's original paper, Proceedings of the Royal Society 45, 135–145
.The correlation coefficient computed under a conditional distribution, using its conditional covariance and positive conditional variances. It can depend on the observed conditioning value. For a multivariate normal distribution, conditioning on other coordinates gives the corresponding partial correlation.
The partial correlation is the correlation of residuals after linearly projecting each of two variables on the conditioning variables and an intercept. With nonsingular covariance matrix, subtracting the two least-squares predictors gives residual covariance and residual variances . Dividing gives the displayed formula. For a multivariate normal distribution, it is also the conditional correlation, independent of the conditioning value; this equality need not hold for general distributions.
For square-integrable variables of positive variance, correlation one is equivalent to with . The squared norm of the difference between the two standardized centered variables is , proving the equivalence. For uncentered variables the relationship can have a nonzero intercept; it need not be proportionality.
For two strictly positive zero-rate stock martingales with bounded volatilities and the same initial value, proportional terminal prices must be equal because their expectations coincide. Conditional expectation then makes the whole paths equal. Comparing their stochastic integrals by the Itô isometry gives equality of the volatility coefficients almost everywhere in time and probability. Perfect positive correlation alone does not provide the required proportionality.
The stocks and start at one, are true square-integrable zero-rate martingales, and have perfect positive correlation at each positive time. Their bounded multiplicative volatilities are and , which differ throughout. The additive intercept is what allows the same correlation but different stochastic-exponential coefficients.
Responses observed on the same process or individual at different times may have nonzero correlation coefficients. Such serial correlation can arise from a shared random effect or from history-dependent conditional means. A scalar dispersion parameter adjustment alone does not represent this temporal dependence.
The intraclass correlation coefficient measures the correlation between observations in the same group. In a random-intercept model with group variance and individual variance , it is .
An indicator random variable is the indicator function of an event in a probability space: is one when occurs and zero otherwise. It has a Bernoulli distribution with parameter , so and . Even an event described without numbers becomes a numerical random variable in this way.
For a finite collection of events, their indicator random variables add up to the number that occur. Linearity of expectation therefore turns an average count into a sum of probabilities, without requiring independence. The fixed point count of a uniform random permutation provides an example where the indicators are dependent random variables.
The tail-sum formula expresses an expected value as the area under a survival function. For every nonnegative random variable ,This Lebesgue integral and the expected value may both be ; a probability density function is unnecessary. For a random variable taking values in the nonnegative integers, the corresponding sum isThe events and coincide because takes integer values. Thus the strict sum starts at zero, while the inclusive sum starts at one.[ref]
Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist. Expected Value, §2 Additional Properties, Right Distribution Function: nonnegative tail integral and integer-valued tail sums
For an original example, let the probability mass function of beIts expected value computed directly is . The strict tail probabilities at thresholds are : their sum is again . There is no probability mass at two, yet the event still has probability . The survival function has heights on the successive intervals ; each interval has length one, so its integral is the same sum.
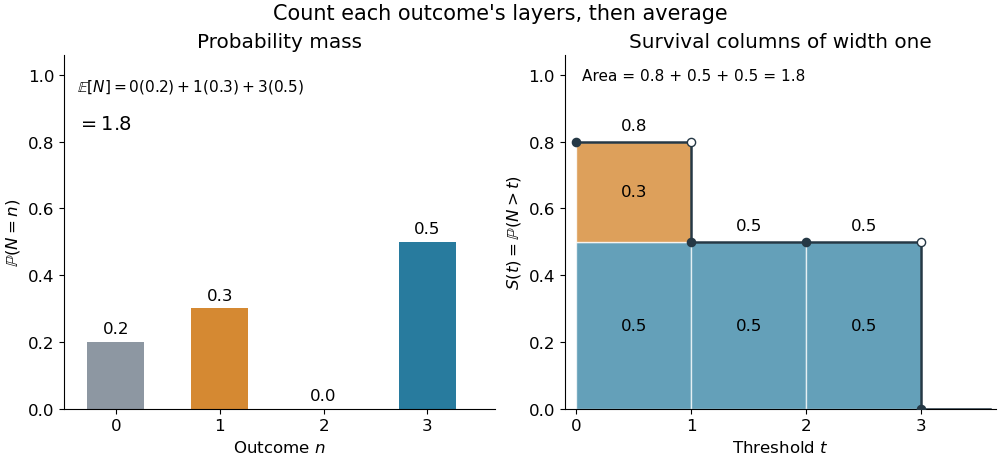
The same expected value from probability masses and survival columns
. The exact constructed probability mass function assigns to . The contribution appears in one survival column, while the contribution appears in three. Filled endpoints give the strict survival function at its jumps; open endpoints show the preceding height. The shaded area is . Details.The indexing matters numerically. Starting the inclusive sum at zero adds , giving for this example. Starting the strict sum at one omits , giving . For a general nonnegative random variable, replacing with inside the integral is harmless: the difference is , nonzero at only a countable set of thresholds. For each positive integer , at most thresholds can have probability mass at least ; their countable union contains all thresholds with positive probability mass and has Lebesgue measure zero. This reasoning concerns an integral, not equality of the two survival function conventions at every point.
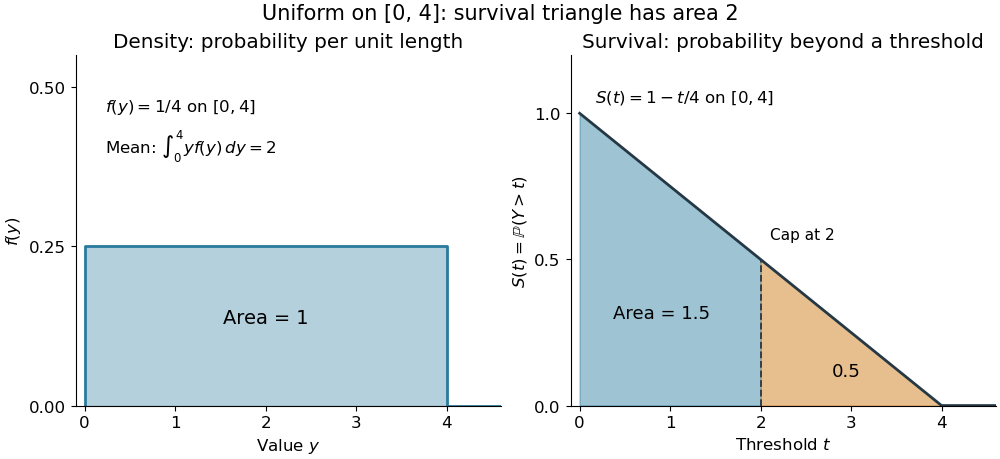
For a continuous original example, take the uniform distribution on the interval . Its survival function is for and zero for . The area is a triangle of base four and height one:Directly integrating against the probability density function gives the same expected value, . The integral of the probability density function alone is one; it is the survival function whose area is the expected value.
The proof counts layers of each outcome. For a realized value , the indicator function equals one over an interval of length , soTonelli theorem permits the interchange because the indicator function is nonnegative; no finite expected value is assumed. Similarly, an outcome contributes one indicator random variable for each of the events that occur:Again Tonelli theorem applies to the nonnegative sum, or equivalently the monotone convergence theorem applies to its partial sums. This exchanges counting layers within each outcome with averaging across outcomes. The existing integer-valued hypothesis in the tail-sum formula explains what changes when the values are not integers; the tail integral formula for moments weights the layers to obtain higher moments.
For an integrable random variable that can have either sign, apply the nonnegative formula separately to its positive part and negative part :Integrability makes both integrals finite. More generally the difference defines an extended expected value when at least one is finite; if both are infinite, subtraction does not define an expected value.[ref]
Random: Probability, Mathematical Statistics, Stochastic Processes by Kyle Siegrist. Expected Value, §2 Additional Properties, A General Definition: positive and negative parts and the condition on their expectations
Tail probabilities are often easier to measure or bound than a whole probability density function. For a device's survival time, the survival function records the probability of still operating at each threshold; its integral gives the mean operating time. A finite observation window naturally gives the expected value of a capped nonnegative random variable. For a mathematical bound, for all implies . The tail-sum formula turns control of a whole family of events into control of an average.
For a nonnegative integer-valued variable, and the tail-sum formula gives . For arbitrary positive real values, that integer-indexed sum equals instead. Two independent constants equal to demonstrate that the product of such tail sums need not equal the tail sum of their product: the two sides are four and three.
For a nonnegative random variable and a fixed cap , the tail-sum formula givesBelow the cap, the events and coincide; at and above the cap, the former event is empty. For the second identity, the positive part exceeds precisely when . Thus the two integrals divide the area under the survival function, just as divides each outcome. The capped expected value is always finite, while the excess expected value may be infinite.
For the uniform distribution on the interval and cap , the capped expected value is and the excess expected value is . Directly averaging the capped values also gives . Capping therefore measures a different average from the uncapped expected value two, even when both are finite.
For integrable random variables on the same probability space and fixed real numbers , linearity of expectation statesThe random variables can be dependent random variables. The formula follows by the linearity of integration; a finite linear combination of integrable random variables remains integrable. For example, if takes with probabilities , then and are dependent random variables, yet .
An especially useful application counts how many events occur. Put , an indicator random variable, and . Since , we get . There is no need to compute the whole probability distribution of , or to assume independence. For a uniform random permutation of objects, each object stays fixed with probability , so the fixed point count of a uniform random permutation has expected value one for every . [ref]
https://ocw.mit.edu/courses/6-042j-mathematics-for-computer-science-spring-2015/mit6_042js15_textbook.pdf. Lehman, Leighton and Meyer, Mathematics for Computer Science, §18.5: linearity and sums of indicators
.Linearity of expectation concerns addition and multiplication by fixed scalars. Products instead satisfy under the hypotheses of expectation of a product of independent random variables. For the example above, , whereas . Applying a nonlinear function before averaging can therefore change the answer substantially; use the law of the unconscious statistician to compute that average.
In independent trials with category probabilities , let count the distinct categories observed. Write it as the sum of indicator random variables for the categories' appearances. Category is absent with probability , so linearity of expectation gives the displayed formula. The appearance indicators need not be independent. For equally likely categories the expression becomes ; uneven probabilities can substantially delay observation of rare categories.
If random variables satisfy , then converges absolutely almost surely, is integrable, and its expected value equals . Indeed, the monotone convergence theorem gives , so that nonnegative sum is finite almost surely. It dominates every finite partial sum in absolute value; the dominated convergence theorem then justifies passing the limit through the expected value. No independence is required.
For example, if for a fixed and , the geometric series bound proves the hypothesis directly. This is useful when repeated observations are multiplied by geometrically shrinking distances or weights.
Let be an IID sample of real-valued random variables with finite expected value and finite variance , where . Its sample mean satisfiesLinearity of expectation gives the first identity. The variance of a sum and vanishing cross covariances give ; scaling by scales the variance by . Pairwise independent random variables with the same expected value and variance suffice for these identities, even without full independence. Grinstead and Snell state the corresponding finite-variance independent-trials result.[ref]
The standard deviation of the sample mean is . Four times as many observations halve this scale; they do not divide it by four. In the fair Bernoulli distribution example, , so sample sizes and give standard deviations and , respectively. The common-coin averaging example shows why merely repeating observations with a common marginal law does not justify this calculation.
Chebyshev's inequality turns the variance identity into a probability bound: for ,This proves convergence in probability of the sample mean to in this finite-variance setting, a form of the weak law of large numbers. It is an upper bound, so values above one convey no improvement over the universal probability bound one. Cauchy sample mean stability lies outside these hypotheses.
For a nonnegative random variable, pointwise, including when . Tonelli's theorem permits taking expectation under the integral and proves the formula in the extended nonnegative reals. This relates finiteness of a Brownian exit time expectation to integrability of its survival probability.
If for and , then . Indeed the tail integral formula for moments gives ; split at . Clipping at one improves the constant compared with integrating the exponential bound alone.



